The Economics of Agent Optimization: How AI agent governance controls cost and proves ROI

This blog post is the fourth and final installment of The Economics of Agent Optimization, which shares the strategies, capabilities, and proof points that can help you optimize agent costs and run AI as a managed investment system on Microsoft Foundry. The first post set out the three decisions that systems rest on, the second post took the request at runtime, and the third post took the workflow over time. This post takes the decision that never stops running: governing the spend.

AI agents are moving from isolated pilots into an enterprise estate. They work across teams, connect to data and tools, and make decisions with varying degrees of autonomy. For IT leaders, that creates a broader operating question: how do you govern a agentic system that can grow and act faster than traditional applications?

AI agent governance starts with knowing which agents exist, who owns them, what they can access, and which policies apply. It is often discussed in terms of security, compliance, and lifecycle management. It is also fundamental to cost optimization. Without consistent governance, each team makes its own choices about models, tools, capacity, and limits—and small inefficiencies multiply across every agent and every turn.

Good governance makes consumption visible, attributable, and bounded. IT needs to see which agents and teams are driving usage. Finance needs budgets and cost allocation it can trust, without discovering an unexpected increase after the invoice closes. Developers need controls that can respond at the speed agents run.

That last requirement exposes an important distinction. Traditional cost management tools can track spending and alert on actual or forecasted costs, but they typically operate on billing data rather than in the request path. An agent caught in a retry loop does not wait for the next budget evaluation.

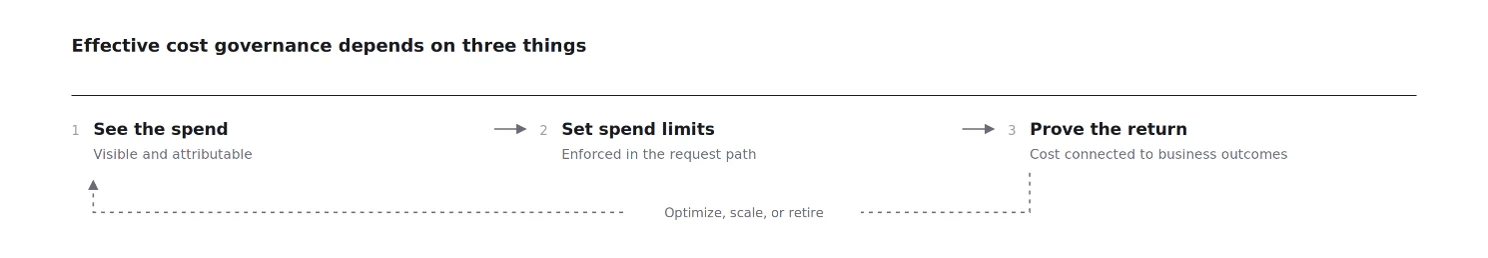
A budget alert is a smoke detector. An agent also needs a circuit breaker. Effective cost governance therefore depends on three things: seeing the spend, bounding it, and proving the return.

See the spend where it starts

AI costs become difficult to manage when they arrive as one aggregate number. One deployment may serve several agents; one agent may use several models and tools; and one outcome may require many turns. By the time that appears on an invoice, the business context has disappeared.

Cost management capabilities in Foundry brings that context closer to the systems creating it. Teams can see estimated costs across projects, inspect cost and token usage for individual agents, and monitor model costs. These estimates support operating decisions; Microsoft Cost Management and invoiced charges remain the system of record for financial reconciliation.

Foundry also supports project-level cost attribution. Every Foundry project is automatically associated with a project tag on its underlying usage. FinOps teams can filter Cost Analysis by that tag to allocate spending to the business unit, team, or workload that incurred it. This capability is currently in preview for models sold by Microsoft Azure, including Azure OpenAI.

At the gateway, Azure API Management’s AI Gateway can emit token metrics by API, product, user, subscription, gateway, and backend. Tracing in Foundry captures tool usage, retries, latency, token consumption, and costs for an agent run.

Together, observability signals explain not only how much an agent consumed, but why:

Traces reveal model calls, tool invocations, retries, latency, and token usage.

Monitoring surfaces production trends and anomalies.

Evaluations measure quality, safety, groundedness, and task completion. Run continuously, they give teams evidence to test whether a smaller model still meets their quality bar rather than defaulting to the largest one. Safety evaluators can also flag issues such as prompt injection, sensitive data leakage, and harmful content before they reach production, where remediation can be costly.

Viewed together, these signals help teams understand whether rising costs are driven by customer demand, inefficient agent behavior, quality regressions, or architectural issues.

That context turns cost data into actionable governance. Before teams can set limits or measure ROI, they need to understand how agents behave in production.

Set spend limits at every layer

Visibility tells you where the money went. Limits determine whether it can keep going. There are three layers to the control system, each working at a different scope and speed:

1. Enforce limits in Foundry

With AI Gateway configured, Foundry Control Plane can enforce tokens-per-minute rate limits and total token quotas for model deployments at the project scope. A request that exceeds the rate limit receives a 429 Too Many Requests response. A caller that exhausts its token quota receives a 403 Forbidden response.

Unlike a cost alert, enforcement happens in the request path. Teams can contain one project’s consumption before it monopolizes shared capacity and establish different boundaries for different projects. Quotas can operate over hourly, daily, weekly, monthly, or yearly periods. Teams can configure the Azure API Management-backed gateway and manage its token limits through Foundry Control Plane.

2. Apply policy across models and providers

For controls spanning projects or model providers, the llm-token-limit policy limits consumption per key using a rate, a cumulative quota, or both. The key can represent a subscription, application, team, customer, workload identity, or another business boundary.

AI Gateway applies the same governance model across OpenAI-compatible APIs, the Anthropic Messages API, as well as MCP servers and agent-to-agent APIs. Backend load balancing can prioritize provisioned capacity before spilling over to pay-as-you-go deployments, while circuit breakers can temporarily stop sending requests to a failing or throttled backend.

Like any distributed limit, these controls have boundaries. Counters are maintained independently at each gateway, and concurrent requests can create a small temporary overage because final token consumption is known only after responses return. The goal is to replace unbounded consumption with a predictable operating boundary.

3. Use financial budgets for accountability and escalation

Microsoft Cost Management budgets serve a different purpose from token limits. They use Azure billing data, including actual prices, credits, and purchasing commitments, to give finance and IT an authoritative view of what the organization has spent and is forecast to spend.

Teams can set budget thresholds and notify owners when actual or forecasted costs approach them. They can also connect a budget to an Azure Monitor action group, which can invoke a customer-designed workflow such as opening a ticket, notifying an operations team, or starting a Logic App or automation runbook. Cost anomaly detection provides another warning when spending departs from its historical pattern.

These are valuable accountability and escalation tools, but they are not instant spending caps. They respond to billing data after consumption occurs. Token limits operate earlier, in the path of each model request, where they can reject new calls after a rate limit or quota is reached. Organizations need both: token limits to contain consumption as agents run, and financial budgets to keep owners accountable and prevent finance from being surprised.

Today, these two layers use different units. The platform enforces consumption in tokens, while finance plans and allocates investment in dollars. Because token prices vary by model and offer, a token quota does not translate into one stable dollar amount.

We are actively working to close that gap with future capabilities in Microsoft Foundry and the AI Gateway in Azure API Management that bring dollar-denominated budgets, finer-grained attribution, and policy-driven controls closer to where agents run.

Measure the value the agent creates

Putting a ceiling on consumption solves only half of the governance problem.

While cost controls can help organizations manage spending, they do not answer a more important question: is the agent delivering enough business value to justify that investment?

The least expensive agent is not necessarily the best investment. An agent that costs more but resolves substantially more cases may deserve additional capacity. An inexpensive agent that rarely completes its task may not. Governance therefore needs a second unit alongside tokens and dollars: business outcomes.

This is ultimately an ROI problem. Organizations want to understand whether their agents are creating more value than they cost. However, connecting business outcomes to the underlying cost of running an agent can be difficult.

ROI for agents in Foundry, currently in private preview, helps organizations connect agent costs to business outcomes. Teams define the outcomes they want to track, such as successful task completion, customer satisfaction, or case deflection. They then assign a business value to those outcomes and define how success should be measured. Foundry tracks which outcomes an agent achieves, and the model and tool costs incurred along the way, calculating:

Value generated: The total value attributed to successful business outcomes.

Total cost: The model and tool costs incurred to achieve those outcomes.

Net value: The value remaining after costs are subtracted.

ROI: The return generated relative to the investment required.

The dashboard shows daily trends and separates models from tool costs. Teams can compare agent versions using average value per conversation, pass rate, and improvement percentage. That makes optimization decisions defensible in business terms: not merely “the new version uses fewer tokens,” but “the new version produces more net value.”

The ROI feature also connects the business view to engineering evidence. Teams can inspect the lowest-ROI conversations and traces to find an oversized model, repetitive tool calls, or a workflow consuming tokens without producing meaningful outcomes. Because ROI is connected to observability data, teams can move directly from a business metric to the traces, evaluations, and operational signals that explain what is driving cost, quality, and business outcomes.

A low-ROI trace can point to a request that should be routed differently, context that should be removed, or an agent configuration that should be optimized. The same telemetry used to improve quality and efficiency can now help organizations answer the question the business ultimately asks: is this agent worth what it costs?

Run AI as one managed investment system

Together, the four posts in this series describe one optimization system operating at three speeds. At runtime, model routing, deployment choices, and caching right-size each request. Over days and weeks, context engineering, memory, tools, and agent optimization improve the workflow. Continuously, governance attributes consumption, enforces limits, and measures whether the portfolio is creating value.

The same evidence connects every layer, and answers different questions:

Traces show what an agent did on a run, exposing expensive requests and inefficient context.

Evaluations show whether the output was good, protecting quality as configurations change.

Cost attribution shows where the money went, pointing to the project, agent, or model to intervene on.

ROI shows whether the work was worth it, telling leaders whether to optimize an agent, give it more capacity, or retire it.

Cost is only one part of a much bigger governance story, and it helps to be clear about who owns which part.

Foundry is built for developers creating agents. It’s where developers build, test, and optimize, and Foundry Control Plane gives them an operating view of everything they’ve shipped, from cost trends and anomalies to token usage and lifecycle controls, with Azure Policy, Microsoft Defender, and Microsoft Purview woven in so compliance and security aren’t an afterthought.

Microsoft Agent 365 is built for the people responsible for the entire enterprise estate. IT administrators and security teams use it to discover, inventory, secure, and manage every agent in the tenant, whether it came out of Foundry, Microsoft 365, or a partner platform, and to extend the same identity, access, and data protections to agents that they already apply to people.

The FinOps capabilities we’ve covered in this series live on the Foundry side of that line, giving developers and platform teams the levers to keep spend predictable, while IT and security govern the estate around them in Agent 365.

Agent optimization isn’t about driving the cost of every request to zero. It’s about running agents with the same discipline you’d apply to any other serious investment, and that is what Foundry is built for: helping developers build and manage agents that are efficient by design, contained as they scale, and accountable for the value they create.

Get started

If you’re governing agents today, start by making their consumption visible and attributable. Identify which agents and teams are driving usage, apply request-time limits to contain unexpected consumption, and pair those controls with financial budgets and alerts. Then connect cost to business outcomes so you can decide which agents to optimize, scale, or retire.

Enforce token limits for model deployments in Microsoft Foundry.

Plan, monitor, and allocate AI costs in Microsoft Foundry costs.

Create budgets and alerts in Cost Management.

Explore AI Gateway governance capabilities in Azure API Management.

Learn about observability and ROI for agents in Foundry.

Microsoft Foundry

The enterprise AI platform to build, ground, and govern AI apps and agents at scale.

Start managing agents

Did you miss these posts in The Economics of Agent Optimization series?

AI cost management: From AI pilots to measurable ROI

AI cost optimization: How to lower AI spend

AI agent optimization: How context engineering lowers AI costs

The post The Economics of Agent Optimization: How AI agent governance controls cost and proves ROI appeared first on Microsoft Azure Blog.
Quelle: Azure
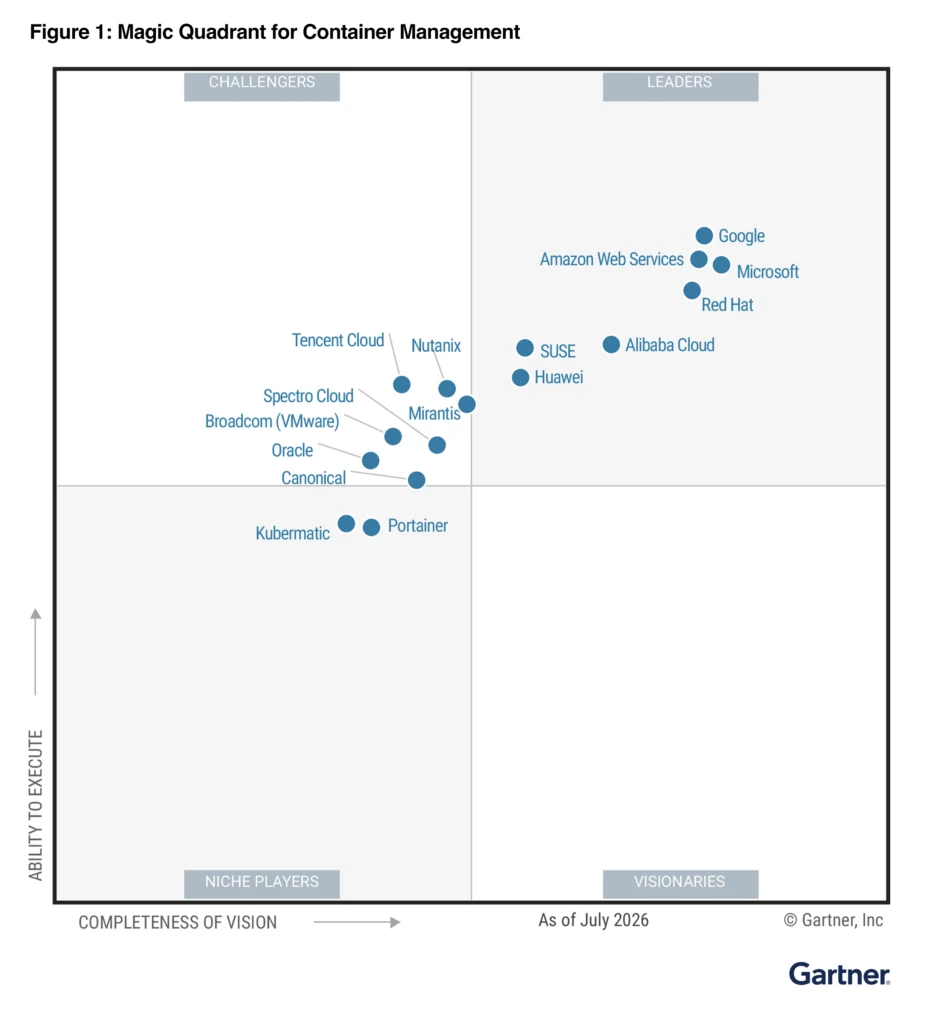
Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management

I am pleased to share that Microsoft has been named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management, positioned furthest to the right on Completeness of Vision. We believe this recognition reflects our ability to help customers modernize existing applications and embrace AI workloads without adding operational complexity.

Furthermore, this recognition comes at a moment when container platforms are being asked to support a far broader range of workloads, operating models, and deployment environments than many organizations ever anticipated.

Read the Gartner® Magic Quadrant™ Report

When we started working on Kubernetes over a decade ago, the problem was narrow: democratize distributed systems so that reliable services were easier to build. We were careful to describe workloads in terms of what they needed instead of where they should go, mostly because we wanted the scheduler to have room to make good decisions. That turned out to matter more than we expected, because it meant the system never had strong opinions about what the workloads actually were.

AI has reshaped the requirements for container management. While Kubernetes has proved well suited for AI workloads, the bigger shift is that applications and AI now need to run closer to data and users, and increasingly inside specific sovereign and regulatory boundaries. Organizations now need more than container orchestration; they need a platform that provides a consistent operating model across cloud, edge, and hybrid deployments while adapting to new requirements without needing applications to be rebuilt. This vision underpins Microsoft’s container portfolio, spanning Azure Kubernetes Service (AKS), Azure Container Apps, Azure Arc, and Azure Kubernetes Fleet Manager..

Run AI on the platform you already operate

Across customer deployments, we’ve seen it settle into two distinct architectural models. In the first, a platform team owns a persistent serving layer, GPU scheduling, model lifecycle, and the compliance boundary around the system. Once volume is high and predictable, organizations increasingly want AI infrastructure to behave like any other platform capability: application teams consume it, while platform teams retain control over how it is operated and governed. On AKS, open-source tooling such as the AI toolchain operator helps automate model deployment and GPU provisioning, while AKS holding CNCF AI Conformance certification gives customers confidence that the ecosystem around their applications remains compatible as it evolves.

In the second model, an application or agent invokes inference when needed, runs generated code, and releases capacity when the work finishes. This model places a premium on elasticity and isolation. Capacity needs to appear quickly, be removed when it’s no longer needed, and safely contain workloads whose behavior isn’t always predictable in advance. Azure Container Apps is designed around that operating model, with serverless GPUs for on-demand inference, and hardware-isolated sandboxes for agent hosting that preserve state between interactions.

Almost every enterprise we work with needs both, and I’d argue the interesting engineering problem is making the boundary between them easy to cross: the same image, the same identity and network controls, the same policy, whichever side a team lands on. Platform teams want the control the first model gives them for the models the business depends on. Application teams and agent frameworks want the second, and they often want it without learning Kubernetes.

Keep one operating model as the estate spreads out

Once inference follows the data, the estate stops being centralized. Clusters accumulate across regions, in datacenters, at sites, and in environments where connectivity is intermittent or prohibited outright, often because sovereignty rules require the workload and its data to stay inside a jurisdiction. The resulting failures are usually coordination failures rather than single-cluster failures: configuration drift between locations, upgrades landing unevenly, and policy being applied in one environment but not another. Hybrid strategies can often fail when teams treat coordination problems as isolated cluster issues instead of platform problems.

We know that AI needs to spread from cloud to edge. To address that, we’ve built AKS Everywhere to enable a consistent, Azure-built and secured Kubernetes platform from cloud to edge. Going even broader, with Azure Arc for Kubernetes we extend a common identity, policy, and observability model across CNCF-conformant Kubernetes environments, including clusters in other clouds. With many clusters comes cluster sprawl, and Azure Kubernetes Fleet Manager addresses the coordination problem that emerges as estates grow, helping organizations manage upgrades, workload placement, and policy consistently across fleets.

Holding all of that together depends on AKS staying close to upstream Kubernetes, and we’ve kept it there deliberately. There’s no proprietary fork, and open-source is at the core of our strategy. Microsoft is the second-largest contributor to CNCF projects overall and the largest among cloud providers for the past three years. That work is what keeps the API you build against stable no matter where the workload lands, and why the ecosystem around your cluster looks the same inside Azure and outside it.

Hold operations steady as the estate grows

Cluster counts often grow faster than operations teams do, and most organizations feel that pain before they have a plan for it.

Some of the answer is better defaults. AKS Automatic applies operational practices derived from Microsoft’s experience running Kubernetes at scale, while preserving the flexibility of the Kubernetes API.

The larger shift, however, is agentic operations. I expect this area to change more than any other over the next few years. Azure SRE Agent and the AKS MCP Server help operators move from alert to diagnosis to remediation using the same permissions and controls they already use today. The goal isn’t to replace operators; it’s to reduce the amount of routine investigation that still consumes too much operational time.

A platform built to absorb new requirements has more surface area than one built for a single scenario, and that demands more judgment from the people running it. Our job is to keep pulling that complexity into the platform, and the work is not finished.

Customer momentum

These examples highlight how customers are applying Azure’s container portfolio across AI, business-critical applications, and hybrid environments.

Wayve trains its autonomous driving models on petabytes of video and sensor data, using AKS to pull thousands of GPUs into what amounts to a single elastic training system.

AT&T built Ask AT&T with AKS as the orchestration core for its containerized agents, and every agent clears legal, security, and finance review before it reaches production.

Replit‘s agent takes a plain-language description, writes the application, and deploys it as a Container App inside the customer’s own Azure environment, where it picks up that customer’s network and compliance controls from the first deployment onward. Roughly three-quarters of their enterprise users don’t write code for a living.

SimCorp moved the investment management platform behind many of the world’s largest asset managers from virtual machines onto AKS, driven by the need for identity, logging, and security policy to apply identically for every client in every jurisdiction, and to be auditable when someone asks.

Emirates Global Aluminium runs about two-thirds of its estate in Azure and a third on-premises at its own sites, with image and video analytics running next to the plant floor and applications moving between the two without being re-engineered.

A training cluster spanning thousands of GPUs has very little in common with a regulated multi-tenant SaaS platform or with analytics running beside a smelter. What connects them is that each one eventually needed something its original architecture wasn’t built for.

Azure Kubernetes Service gives us the control and cost efficiency we need. We can scale GPU resources based on call volume and test new models without touching production.
Brian Sutliffe, Vice President of Engineering, CallRevu

Being named a Leader in this Magic Quadrant is an honor for us, and it solidifies clear expectations for our work ahead. At the end of the day, only the team running a workload can decide where it belongs, and the answer will vary across an estate. The platform’s role is to let that answer change without forcing the team to redesign the application or adopt a second operating model. I also want to personally thank all of Azure Cloud Native since this recognition reflects a lot of hard work by many people throughout Microsoft and Azure.

You can read a complimentary copy of the 2026 Gartner® Magic Quadrant™ for Container Management here.

Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management

Read the report

Gartner ® Magic Quadrant™ for Container Management, Dennis Smith, Tony Iams, Wataru Katsurashima, Lucas Albuquerque, 2 September 2026

Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.

Gartner and Magic Quadrant are trademarks of Gartner, Inc., and/or its affiliates.

This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request here.

The post Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management appeared first on Microsoft Azure Blog.
Quelle: Azure
Beyond the benchmark: How an adaptive approach drives scientific discovery

For research and development (R&D) organizations, the promise of agentic AI is not a better one-time answer. It is a new way to explore complex scientific and engineering problems: pursuing multiple hypotheses, validating them against evidence, learning from what does not work, and adapting their approach as new information becomes available.

This unique nature of the agentic discovery process has been a core area of research for Microsoft, and a design principle for Microsoft Discovery, our platform for organizations embracing Frontier R&D.

Learn how Microsoft Discovery explores science

Measuring adaptive AI for scientific discovery

A new benchmark result shows how that opportunity is becoming real. On Agent’s Last Exam, a demanding evaluation of long-running, tool-using professional tasks, Microsoft Discovery Engine with CLIO (Cognitive Loop via In-Situ Optimization) achieved higher scores than the other agentic harnesses evaluated across three scientific domains: 61.6% in health and medicine, 75.2% in physical sciences, and 64.6% in life sciences.

This result builds on Microsoft’s core research into what makes agentic discovery distinctive. CLIO enables independent reasoning paths to explore a problem, compare and share learning, and resolve the strongest trajectory into a single evidence-backed result. The system can determine when to keep exploring, change strategy, use a different model, or bring a domain expert into the loop.

The CLIO benchmark blog post describes this adaptive reasoning approach in depth. More broadly, this core innovation for scientific discovery, powered by agentic AI, is available to R&D organizations in every industry and the scientific community with Microsoft Discovery not only as a research breakthrough, but as a foundation for real R&D work.

Explore Microsoft Discovery

Why scientific discovery requires adaptive reasoning

Many of the hardest scientific and engineering challenges do not have a clearly defined workflow or a known answer. A researcher may need to navigate incomplete evidence, competing objectives, specialized tools, and changing constraints. A materials team may be balancing performance, safety, cost, and manufacturability. A life sciences team may need to connect literature, proprietary data, models, and experimental evidence before deciding what to validate next. An engineering team may need to search a vast design space without sacrificing physical fidelity or traceability.

In these settings, a single model response is not enough. Practitioners need systems that can reason over time, preserve evidence, challenge assumptions, and work within the tools, data, governance, and review processes their experts already use. Just as importantly, they need to understand how a conclusion was reached and where human judgment should enter the process.

Microsoft Discovery was designed as an enterprise platform for agentic R&D, combining the scientific mindset of hypothesis, experimentation, and refinement with the engineering rigor of problem decomposition, structured execution, and reproducibility. CLIO strengthens that foundation with a more adaptive reasoning loop and a diverse model ecosystem, while allowing researchers to use a diverse model ecosystem and multiple reasoning paths.

Try Microsoft Discovery app

From benchmarks to real-world impact

The greater opportunity extends beyond benchmark rankings into real research environments. Discovery Engine with CLIO has already supported work that discovered a novel organic redox flow battery. The same approach has potential across design simulation (like for silicon chips), formulation and process optimization (for example in manufacturing and CPG), materials and molecular discovery (which can drive sustainability and drug discovery), and lab automation, areas where organizations need to shorten research cycles, without sacrificing rigor or traceability.

Agentic discovery does not replace scientists and engineers. It expands what they can explore, helps them learn faster from evidence, and gives them a more systematic and transparent way to move from an idea toward an outcome that experts can evaluate and validate.

Realizing the enormous opportunity to redefine R&D requires a platform built for the tools, data, governance, and review processes researchers already use. Microsoft Discovery was designed with that need in mind: to bring agentic discovery to researchers and scientists in R&D organizations across every industry and throughout the scientific community.

We are still early in this journey, but this benchmark milestone demonstrates what becomes possible when AI is built for the way discovery actually happens: iteratively, collaboratively, and adaptively. I look forward to seeing what organizations, researchers, and partners discover next.

Adaptive AI for scientific discovery

Learn how Microsoft Discovery uses adaptive, agentic approaches to explore complex scientific and engineering challenges, helping R&D teams accelerate innovation and uncover new possibilities.

Read the blog

The post Beyond the benchmark: How an adaptive approach drives scientific discovery appeared first on Microsoft Azure Blog.
Quelle: Azure
GPT-6 Astra: Frontier intelligence for work, now generally available in Microsoft Foundry

The next era of enterprise AI will not be defined by chat experiences. It will be defined by how well a model can work for and with you. GPT-6 Astra, OpenAI’s newest frontier model, is now generally available for all customers in Microsoft Foundry. It is designed to help organizations make decisions for complex work and execute across the applications and systems where your business operates.

We are investing to make it easier for customers to use advanced technology like Astra. AI initiatives often slow down on identity, networking, governance, data handling, evaluation, and compliance. Microsoft Foundry brings these fundamentals together in Azure, helping teams move from experimentation to production with speed and trust.

Turn open-ended goals into action

Astra is built to take an open-ended challenge, reason through it in multiple steps, create a plan, and produce a polished result. It can weigh trade-offs, incorporate new direction as work progresses, and use tools across applications and systems. 

For enterprises, this shifts AI from conversational assistance toward delivering more substantial units of work:

Deliberate planning and decision support. Astra can break a challenge into steps, evaluate options, communicate its recommendation, and identify the next actions for review.

Polished, purposeful output. Astra can apply context, templates, and quality standards throughout a workflow, helping produce documents, spreadsheets, presentations, and analyses that are ready for review.

Execution across applications. With advanced tool use and computer use, Astra can interact with software on a person’s behalf, move between apps, and complete multi-step tasks with appropriate human oversight.

At Replit, our mission is making useful intelligence accessible to everyone. GPT-6 Astra available through Microsoft Foundry unlocks a new level of agentic capability that goes beyond code generation to active software creation and more. We’re excited about the opportunities created for developers and entrepreneurs to build more ambitious applications with an intelligent software-building partner.
—Luis Hector Chavez, CTO, Replit

Computer use across applications

Astra’s computer-use capabilities are designed to work across familiar applications, including workflows without dedicated APIs. It can interpret on-screen information and interact with approved interfaces to support tasks such as updating records, navigating development tools, testing software, and assembling results into reports. OpenAI reports state-of-the-art results on selected computer-use evaluations; performance varies by task, tools, configuration, and safeguards.

Capability this direct demands containment. Content displayed in an application may be incomplete, misleading, or designed to influence an agent’s behavior. Foundry helps customers define access, approvals, and monitoring, and design workflows with scoped credentials, approved resources, human checkpoints for consequential actions, and activity records aligned to their risk requirements.

Enterprise scenarios we’re seeing

Software engineering: Astra can reproduce complex bugs, investigate likely causes, propose fixes, and prepare changes for developer testing and review.

Business intelligence: Astra can build and refine dashboards in Power BI, helping analysts compare data, identify trade-offs, and prepare insights to share.

Professional work: Astra can produce documents, spreadsheets, and presentations that follow existing templates and business standards, creating polished artifacts for expert review.

Application workflows: Astra can support tasks such as updating customer records, processing forms, testing websites, and working through approved interfaces where dedicated APIs are limited. 

Enterprise controls for agentic work

OpenAI describes Astra as its most aligned model to date and plans to publish supporting alignment, safety, and computer-use evaluations in its supporting launch materials. Foundry complements that model-level work with enterprise security, safety, and compliance capabilities, including Microsoft Entra identity and access management, encryption in transit and at rest, private networking options, role-based access controls, content filtering, safety evaluations, monitoring, and governance tools.

Prompts and outputs are not used to train the models. These capabilities help customers configure safeguards and maintain oversight, but do not eliminate risk or replace each organization’s responsibility to select and configure controls appropriate to its scenarios and regulatory obligations.

At Albertsons Companies, we believe the real advantage in frontier AI is the ability to evolve as quickly as the technology does, without compromising enterprise discipline. That means creating an environment where we can evaluate new capabilities, put the right ones to work quickly and maintain consistent security, governance and operational controls as we scale. Azure OpenAI on Microsoft Foundry helps us create that balance of speed and control, so our teams can stay focused on delivering meaningful outcomes for our customers, associates and the business.
—Anirban Nandi, VP, Data and AI, Albertsons Companies

Global scale with service level to match

GPT-6 Astra is available in Foundry models with Standard and Provisioned Throughput deployment options, in both Global and US Data Zone geographies. Standard provides pay-as-you-go flexibility for variable demand, while Provisioned Throughput provides dedicated model-processing capacity for workloads requiring consistent latency and guaranteed throughput. Customers can choose the right deployment based on workload requirements.

Astra is designed for token efficiency on complex work, helping customers manage consumption as they scale. Actual usage and costs will vary by workload and configuration.

GPT-6 Astra pricing*

Deployment Context Length Pricing (USD $/million tokens) Input Cached Input Cached Writes Output Standard Global Short context $10.00 $1.00 $12.50 $50.00 Long context $20.00 $2.00 $25.00 $75.00 Standard Data Zone (US) Short context $11.00 $1.10 $13.75 $55.00 Long context $22.00 $2.20 $27.50 $82.50 Provisioned Throughput pricing varies by deployment type. U.S. Data Zone Provisioned Throughput is priced at a 10% premium to Global Provisioned Throughput. For current rates and terms, see the Azure OpenAI pricing page.

Get started today

Explore the model: Try GPT-6 Astra in Foundry Models to see its advanced capabilities firsthand.

Build agentic workflows: Start with the Foundry Agent Service to bring cross-application task execution to your workflows.

Try GPT-6 Astra today

Explore the model and start building agentic workflows.

Learn more

The post GPT-6 Astra: Frontier intelligence for work, now generally available in Microsoft Foundry appeared first on Microsoft Azure Blog.
Quelle: Azure
How Microsoft’s Physical Security Engineering Team scaled hybrid operations with Azure Arc and Azure Virtual Desktop

When a physical security operator begins a shift supporting Microsoft’s global datacenter operations, they depend on a collection of applications and systems that help monitor access activity, review video feeds, investigate alerts, and coordinate physical security operations across a complex global environment. Those tools must be available, responsive, and reliable from the moment a shift begins.

As Azure datacenters expanded to support growing demand for cloud and AI services, maintaining that experience became increasingly important. Critical security systems were distributed across hundreds of locations worldwide, while the infrastructure supporting them spanned both on-premises and cloud environments. The challenge wasn’t responding to a specific incident or operational failure but ensuring that as Azure’s physical footprint continued to grow, the systems supporting those operations remained secure, manageable, observable, and consistent at a global scale.

See how Azure Arc unifies hybrid operations

Meeting that goal required more than simply keeping systems online. The team needed a way to manage infrastructure across hybrid environments, standardize operations, automate routine tasks, improve visibility into system health, and provide operators with consistent application experiences regardless of location. By combining Azure Arc, Azure Virtual Desktop, Azure Monitor, and other Azure management services, Microsoft built a more unified operational foundation designed to support the evolving needs of its global physical security environment.

Building a unified management layer across hybrid infrastructure

As Azure datacenters expanded, so did the infrastructure supporting their physical security operations. Critical systems were deployed close to the environments they served and operated within highly segmented networks designed to prioritize resiliency, security, compliance, and local autonomy. That architecture solved one challenge but created another.

The physical security organization was responsible for deploying and managing thousands of servers distributed across Microsoft’s global datacenter footprint in alignment with established protocols. While each deployment met baseline operational requirements, rapid growth and increasing scale made it increasingly difficult to guarantee consistency.

The team needed a way to bring these distributed systems under a common management framework without changing where the workloads ran or weakening the security boundaries that protected them.

Why Azure Arc

The objective wasn’t to move these workloads into Azure. Many of the systems supporting physical security operations needed to remain close to the environments they served and continue functioning independently when required by local operational or resiliency needs. Instead, the team was looking for a way to extend the operational benefits of Azure to on-premises infrastructure.

Azure Arc was designed to address exactly this type of challenge. At its core, Azure Arc extends Azure’s management and governance capabilities to servers and resources running outside Azure. Rather than treating on-premises systems as separate operational islands with their own tools and processes, Azure Arc allows organizations to manage those resources through Azure’s control plane. This makes it possible to apply, at scale, many of the same monitoring, policy, automation, security, and update-management workflows used in Azure to infrastructure running elsewhere.

For Microsoft’s physical security organization, Azure Arc made it possible to manage servers across its global datacenter footprint through a common operational model, regardless of where they were physically located.

More importantly, Azure Arc allowed the team to preserve the resiliency and security characteristics of their existing deployments while gaining centralized visibility, governance, and automation capabilities.

Establishing a consistent operational foundation

Once onboarded to Azure Arc, the team began extending familiar Azure management capabilities to infrastructure running outside Azure. Using Azure Update Manager, patching activities that had historically required significant coordination across distributed environments could be scheduled, tracked, and governed through a centralized framework. According to the team, this automation now saves thousands of hours annually while enabling a relatively small operations team to support a growing infrastructure footprint.

At the same time, Azure Policy, Guest Configuration, Azure Monitor, Azure Monitor Agent, and Log Analytics helped create a common framework for governance, compliance monitoring, and observability. The team could continuously assess critical security configurations, identify drift, monitor system health, and surface operational telemetry through centralized dashboards, alerts, and reporting workflows regardless of where infrastructure was deployed.

Security remained a primary consideration throughout the design. Managed Identities and Azure role-based access control (RBAC) helped reduce reliance on stored credentials while providing more granular control over access to operational resources. Azure Automation further reduced manual effort by standardizing remediation, maintenance, and configuration-management activities through reusable runbooks. Together, these capabilities helped establish a more consistent operating model across the environment while improving visibility, strengthening governance, and reducing the operational overhead associated with managing a globally distributed infrastructure.

Delivering a consistent operator experience with Azure Virtual Desktop

Unified management solved one part of the challenge. The next was ensuring that operators interacting with those systems received the same level of consistency, performance, and visibility.

The team’s objective extended beyond providing remote access. They needed a way to improve application performance, simplify lifecycle management, and gain better insight into the end-user experience. Azure Virtual Desktop provided a flexible platform for delivering applications closer to the infrastructure they depended on, while also enabling centralized image management and integration with Azure monitoring services. This allowed the team to maintain consistent host configurations, simplify updates, and incorporate user-session telemetry into existing operational workflows.

To improve the operator experience, the team relocated the application environment closer to the infrastructure it supported and delivered access through Azure Virtual Desktop sessions. The impact was immediate: application launch times improved by approximately 12x, helping operators access critical tools more quickly and consistently.

The team also adopted a centralized image-management strategy and automated host refresh process. Instead of maintaining individual systems over time, hosts could be rebuilt from approved images and deployed consistently across the environment. This approach accelerated release cycles by ~6x, reduced configuration drift, and allowed updates that once required weeks or months of coordination to be completed in hours.

Equally important was the visibility Azure Virtual Desktop unlocked. By integrating Azure Virtual Desktop with Azure Monitor, Azure Monitor Agent, Log Analytics, and Azure Virtual Desktop Insights, the team gained access to telemetry on session health, round-trip time, bandwidth usage, and client-side application behavior. Engineers could better understand how applications performed from the operator’s perspective, identify trends earlier, and shift from reactive troubleshooting to a more proactive, data-informed approach.

Key lessons for managing hybrid environments at scale

As Azure’s global datacenter footprint continued to grow, Microsoft’s physical security organization needed a management and delivery model that could scale alongside it. By combining Azure Arc and Azure Virtual Desktop, the team established a more consistent approach to managing infrastructure, delivering applications, and monitoring operational health across a complex hybrid environment.

The result wasn’t a single breakthrough technology, but a unified operating model that improved visibility, reduced operational overhead, and helped ensure critical systems remained resilient, manageable, and ready to support future growth.

Learn more

Azure Arc

Azure Virtual Desktop

Azure Monitor

Bring consistency and control to hybrid operations

See how Azure Arc helps organizations extend Azure management and governance capabilities across distributed infrastructure, enabling centralized visibility, automation, compliance, and operational consistency without changing where workloads run.

Explore Azure Arc

The post How Microsoft’s Physical Security Engineering Team scaled hybrid operations with Azure Arc and Azure Virtual Desktop appeared first on Microsoft Azure Blog.
Quelle: Azure
GPT-6 Astra: Frontier intelligence for work, now available in Microsoft Foundry

The next era of enterprise AI will not be defined by chat experiences. It will be defined by how well a model can work for and with you. GPT-6 Astra, OpenAI’s newest frontier model, begins rolling out today through the Microsoft Foundry Limited Access Program, with availability expanding to participating customers over the coming days. It is designed to help organizations make decisions for complex work and execute across the applications and systems where your business operates.

We are investing to make it easier for customers to use advanced technology like Astra. AI initiatives often slow down on identity, networking, governance, data handling, evaluation, and compliance. Microsoft Foundry brings these fundamentals together in Azure, helping teams move from experimentation to production with speed and trust.

Turn open-ended goals into action

Astra is built to take an open-ended challenge, reason through it in multiple steps, create a plan, and produce a polished result. It can weigh trade-offs, incorporate new direction as work progresses, and use tools across applications and systems. 

For enterprises, this shifts AI from conversational assistance toward delivering more substantial units of work:

Deliberate planning and decision support. Astra can break a challenge into steps, evaluate options, communicate its recommendation, and identify the next actions for review.

Polished, purposeful output. Astra can apply context, templates, and quality standards throughout a workflow, helping produce documents, spreadsheets, presentations, and analyses that are ready for review.

Execution across applications. With advanced tool use and computer use, Astra can interact with software on a person’s behalf, move between apps, and complete multi-step tasks with appropriate human oversight.

At Replit, our mission is making useful intelligence accessible to everyone. GPT-6 Astra available through Microsoft Foundry unlocks a new level of agentic capability that goes beyond code generation to active software creation and more. We’re excited about the opportunities created for developers and entrepreneurs to build more ambitious applications with an intelligent software-building partner.
—Luis Hector Chavez, CTO, Replit

Computer use across applications

Astra’s computer-use capabilities are designed to work across familiar applications, including workflows without dedicated APIs. It can interpret on-screen information and interact with approved interfaces to support tasks such as updating records, navigating development tools, testing software, and assembling results into reports. OpenAI reports state-of-the-art results on selected computer-use evaluations; performance varies by task, tools, configuration, and safeguards.

Capability this direct demands containment. Content displayed in an application may be incomplete, misleading, or designed to influence an agent’s behavior. Foundry helps customers define access, approvals, and monitoring, and design workflows with scoped credentials, approved resources, human checkpoints for consequential actions, and activity records aligned to their risk requirements.

Enterprise scenarios we’re seeing

Software engineering: Astra can reproduce complex bugs, investigate likely causes, propose fixes, and prepare changes for developer testing and review.

Business intelligence: Astra can build and refine dashboards in Power BI, helping analysts compare data, identify trade-offs, and prepare insights to share.

Professional work: Astra can produce documents, spreadsheets, and presentations that follow existing templates and business standards, creating polished artifacts for expert review.

Application workflows: Astra can support tasks such as updating customer records, processing forms, testing websites, and working through approved interfaces where dedicated APIs are limited. 

Enterprise controls for agentic work

OpenAI describes Astra as its most aligned model to date and plans to publish supporting alignment, safety, and computer-use evaluations in its supporting launch materials. Foundry complements that model-level work with enterprise security, safety, and compliance capabilities, including Microsoft Entra identity and access management, encryption in transit and at rest, private networking options, role-based access controls, content filtering, safety evaluations, monitoring, and governance tools.

Prompts and outputs are not used to train the models. These capabilities help customers configure safeguards and maintain oversight, but do not eliminate risk or replace each organization’s responsibility to select and configure controls appropriate to its scenarios and regulatory obligations.

At Albertsons Companies, we believe the real advantage in frontier AI is the ability to evolve as quickly as the technology does, without compromising enterprise discipline. That means creating an environment where we can evaluate new capabilities, put the right ones to work quickly and maintain consistent security, governance and operational controls as we scale. Azure OpenAI on Microsoft Foundry helps us create that balance of speed and control, so our teams can stay focused on delivering meaningful outcomes for our customers, associates and the business.
—Anirban Nandi, VP, Data and AI, Albertsons Companies

Global scale with service level to match

GPT-6 Astra will be available through Standard deployments including Global and U.S. Data Zone. Customers can choose the right deployment based on workload requirements.

This consumption-based model lets teams begin building without committing to reserved capacity. Astra is also designed for token efficiency on complex work, helping customers manage consumption as they scale. Actual usage and costs will vary by workload and configuration.

GPT-6 Astra pricing

DeploymentPricing (USD $/million tokens)InputCached InputCached WritesOutputStandard Global (Short context)$10.00$1.00$12.50$50.00Standard Global (Long context)$20.00$2.00$25.00$75.00Standard Data Zone (US) (Short context)$11.00$1.10$13.75$55.00Standard Data Zone (US) (Long context)$22.00$2.20$27.50$82.50

Get started today

Explore the model: Try GPT-6 Astra in Foundry Models to see its advanced capabilities firsthand.

Build agentic workflows: Start with the Foundry Agent Service to bring cross-application task execution to your workflows.

Try GPT-6 Astra today

Explore the model and start building agentic workflows.

Learn more

The post GPT-6 Astra: Frontier intelligence for work, now available in Microsoft Foundry appeared first on Microsoft Azure Blog.
Quelle: Azure

Enterprise AI transformation relies on the end-to-end platform: Azure was built for this moment

Summary
The recognition for Microsoft over the past couple of weeks comes down to models, infrastructure, data, applications, and developer tools working as one system when AI moves into production.

Enterprise AI is moving into production, and our customers are becoming multi-model. Organizations will use frontier models where capability matters, and smaller, specialized, and open-weight models where economics and finer controls matter. But the value does not come from any model in isolation. It comes from the system around it: infrastructure, data, applications, agents, security, and operations working together. That compounding value is what Microsoft Azure is built to deliver.

A system built from silicon to agent

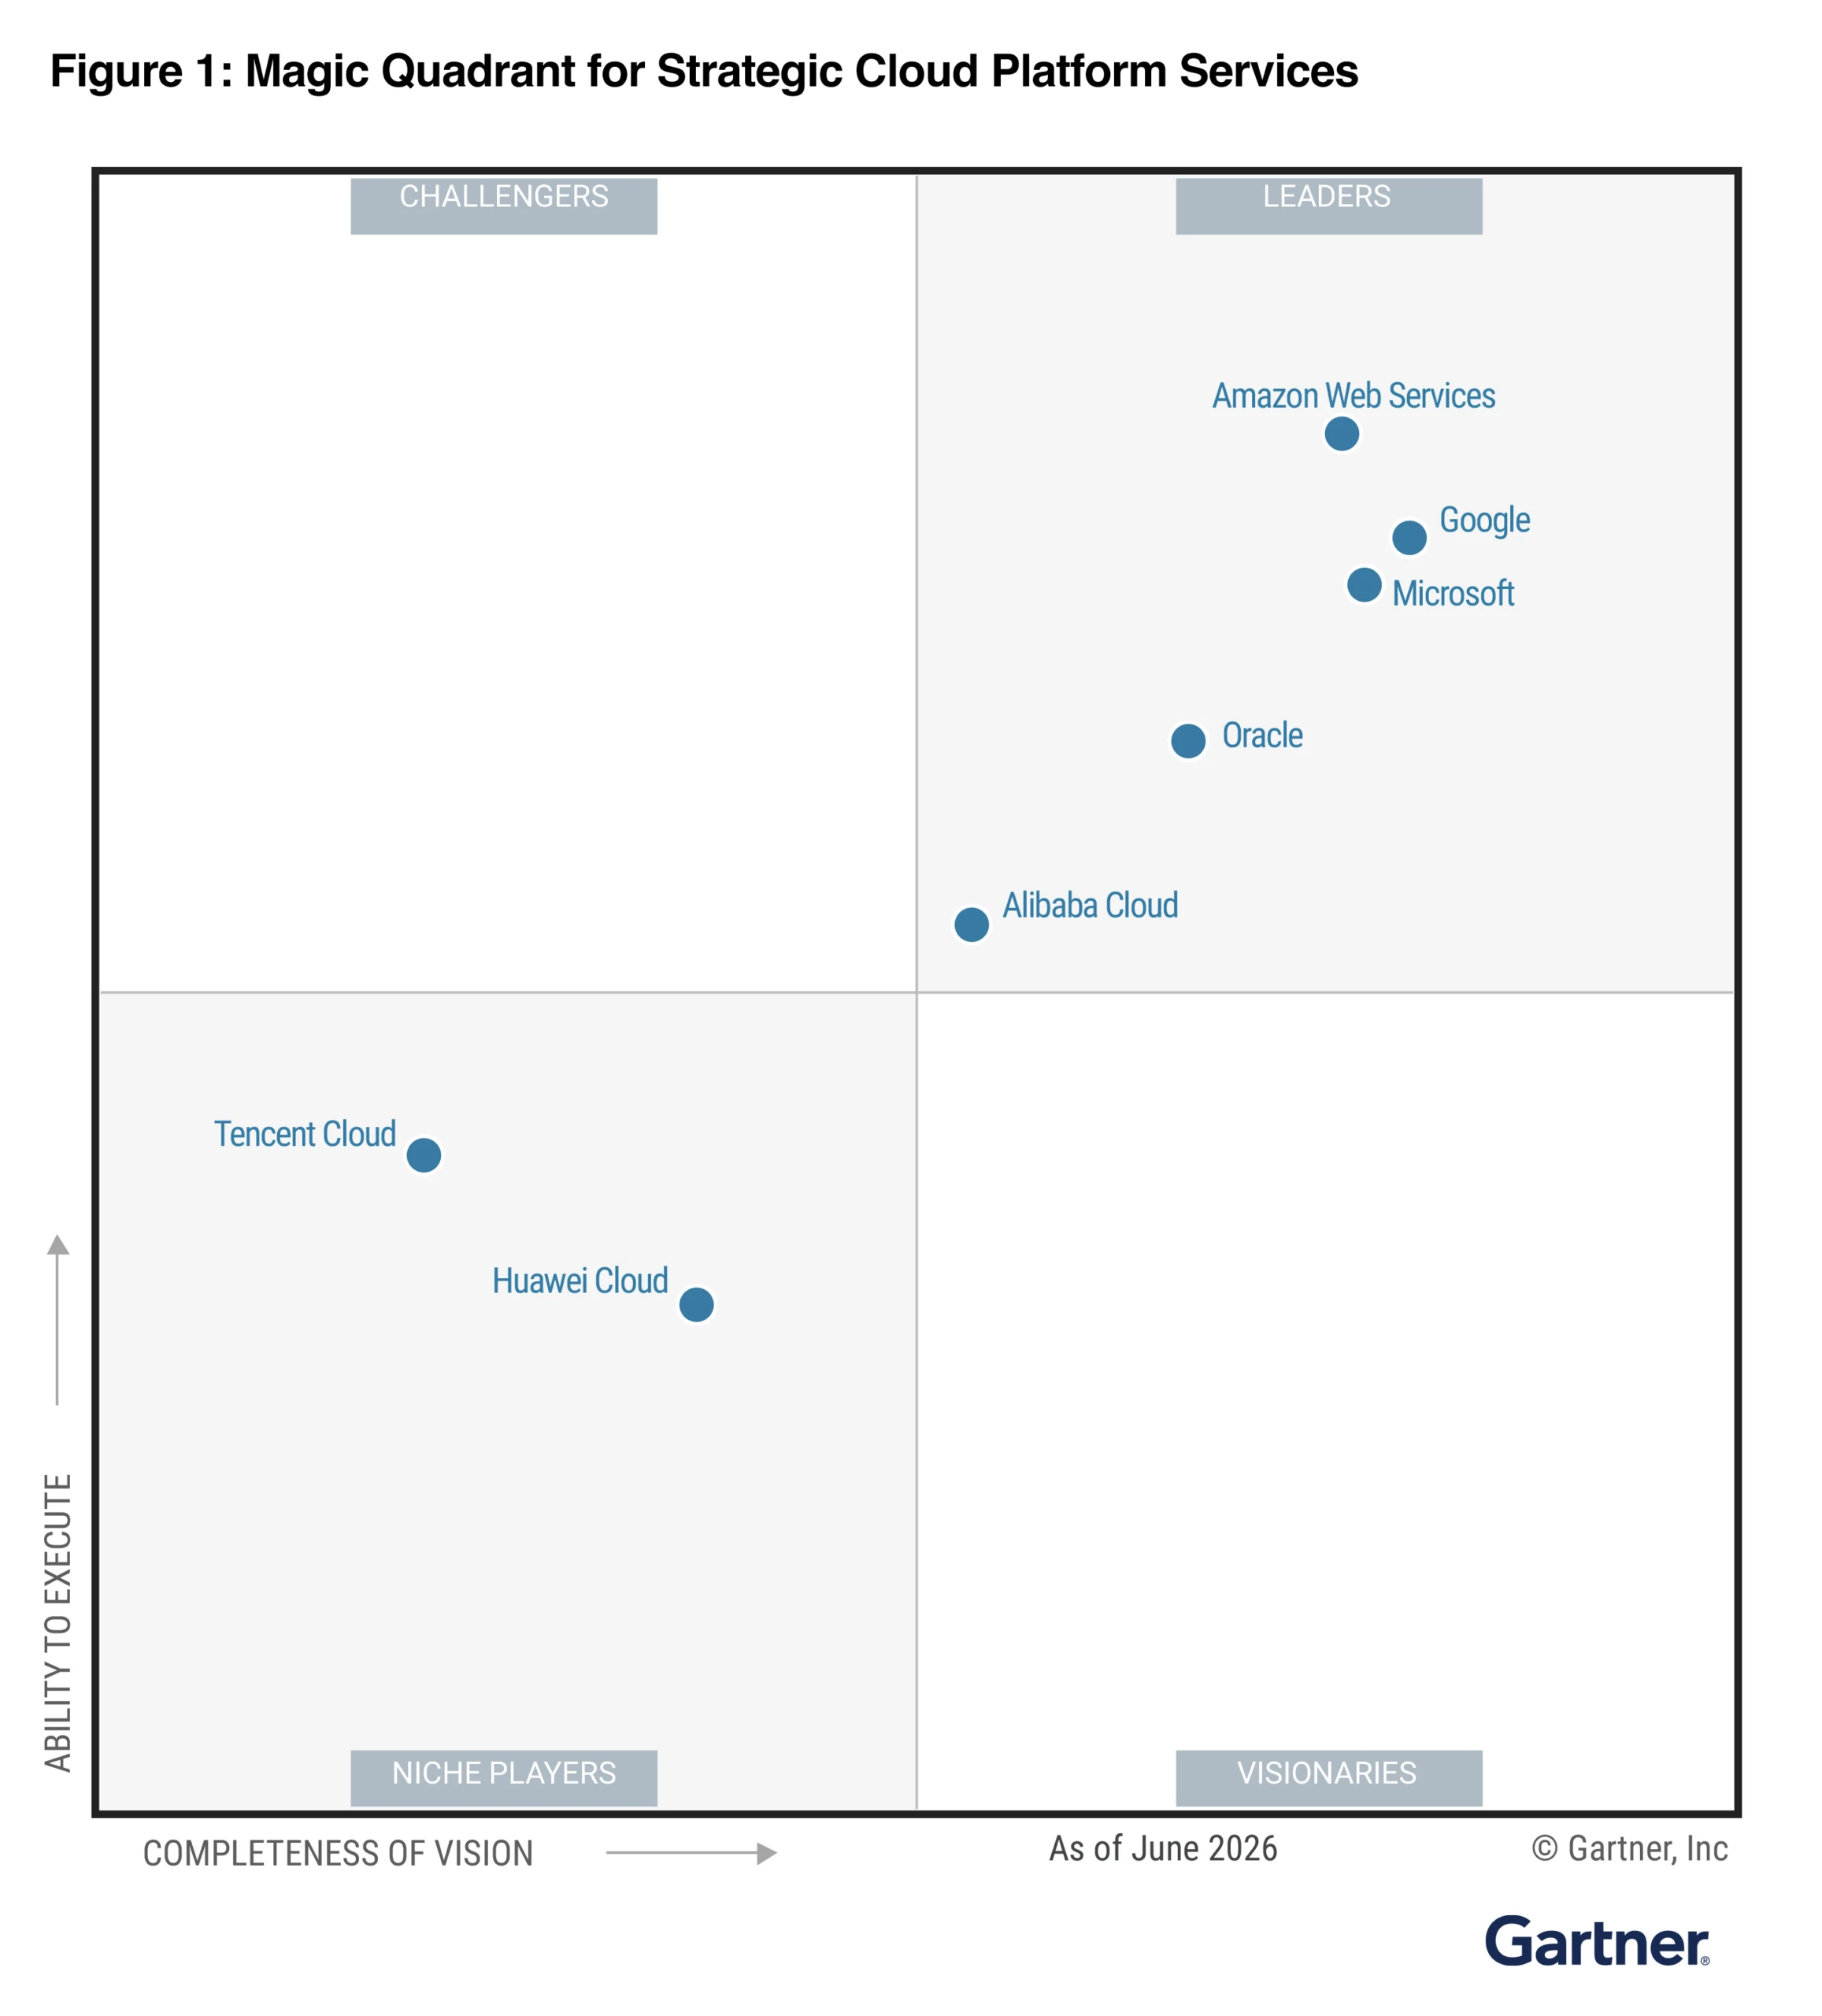
That integration extends into the infrastructure underneath the model. Customers want the flexibility to choose across models and infrastructure without having to stitch together and tune every layer themselves. Microsoft has drawn on decades of running mission-critical systems and operating some of the world’s most demanding AI services at global scale. We believe that breadth and integration across the platform, extending through developer tools and AI applications is a key reason why Microsoft has been named a Leader in both the 2026 Gartner® Magic Quadrant™ for Strategic Cloud Platform Services and The Forrester Wave™: Public Cloud Platforms, Q3 2026.

We appreciate the recognition. What matters more is that customers choosing a platform today are shaping their infrastructure for years, and that choice rests on system-level capability. A cloud platform now must do more than provide individual services. It must give customers choice across models and infrastructure while helping them build faster, run reliably, manage risk, control cost, and improve outcomes. For an enterprise building the next generation of AI applications, how the layers work together matters more than any single feature.

Discover trusted cloud solutions on Microsoft Azure

Microsoft’s Leader placement in the 2026 Gartner® Magic Quadrant™ for Strategic Cloud Platform Services follows Leader placements in the 2025, 2024, and 2023 editions. We believe that what matters for customers, is whether the platform can translate technology into real impact: better performance, greater cost efficiency, faster delivery, and the ability to scale critical systems with confidence.

Microsoft was also named a Leader in The Forrester Wave™: Public Cloud Platforms, Q3 2026. Forrester’s evaluation looks at both the strength of the current offering and the strategy behind it. This recognition provides another independent view of how Azure is evolving as customers move from isolated AI projects to production systems.

Forrester describes Microsoft’s direction as a vision of Azure as a single, vertically integrated system.

Choice without complexity

A multi-model strategy does not mean every model should run the same way. The platform must support those choices across heterogeneous compute while applying consistent security, identity, governance, reliability, and operations.

Microsoft Foundry is central to this approach. It gives developers broad model choice and the tools to evaluate, secure, monitor, and operate AI systems, with Azure infrastructure underneath. This is not about forcing every workload into one model. It is about using reducing the seams between layers so teams can make workload-specific choices while operating consistently across cloud, on-premises, edge, and third-party environments.

Data gives AI its business value

Model choice will keep changing, but the data and business context that make AI useful endure. Customers want to work with data where it already resides, without creating more copies or losing governance along the way. As Forrester puts it: “Models come and go; data has gravity.”

Microsoft Fabric brings analytics and data together, and Microsoft Purview applies governance across that estate. The Azure databases, including Azure SQL and Azure Cosmos DB, connect AI to current operational data. On top of that foundation, Microsoft IQ provides the unified enterprise intelligence layer, giving apps and agents consistent business context across work, data, and knowledge. Together, these capabilities let organizations change models without rebuilding the data, governance, and business context around every application.

UNC Health illustrates why that foundation matters. By modernizing its analytics, the organization is creating a governed data environment that supports care, operations, and research within the requirements of a highly regulated industry. It is the kind of foundation organizations need before AI can be applied responsibly at scale.

Modernization is the catalyst to AI

The applications running a business today contain years of business logic, data, and operating knowledge. They need a modern home where they can continue to support proven processes and connect to new AI experiences. Modernization is therefore part of the AI work, not a separate project. Customers need to decide workload by workload whether to move it, update it, use a managed service, expose it to agents through secure interfaces, or rebuild the parts where there is a clear business reason.

Levi Strauss & Co. shows how modernization and AI become part of the same journey. The company modernized its legacy infrastructure on Azure to build a more resilient foundation, then used Microsoft Foundry to introduce agents that simplify work and accelerate decision-making. A heritage company did not have to leave its existing business behind to adopt AI; it modernized that foundation and built forward from it.

Agents can help teams assess applications, plan upgrades, refactor code, test changes, and support migration while developers and IT teams retain control of architecture and business decisions. GitHub Copilot agentic modernization supports .NET and Java applications, and the work connects across the software lifecycle. This is where the analyst feedback is especially relevant: Gartner highlights Microsoft’s pragmatic approach to application modernization and its integrated, end-to-end software developer lifecycle, while the Forrester report notes our customers’ appreciation for Microsoft’s migration and modernization expertise. The goal is straightforward: help customers modernize the applications they already rely on and so they are ready for the next generation of AI.

Power every AI ambition

As customers run more AI in production, the platform must be more efficient, more reliable, and easier to operate. Customers need the freedom to choose the models and infrastructure that best fit each workload, while the platform reduces the complexity of bringing those choices together.

We’re proud to be recognized as a Leader by Gartner and Forrester, and even more excited by what these evaluations reflect about where the industry is heading. We believe the next generation of cloud will be defined by how well the platform brings infrastructure, data, models, applications, and developer tools together while preserving the choice customers need as each layer continues to evolve.

That’s the direction we’re building toward with Azure, and we’re excited to keep shaping what comes next alongside our customers and partners.

Review the 2026 Gartner® Magic Quadrant™ for Strategic Cloud Platform Services. Read the report.

Review The Forrester Wave™: Public Cloud Platforms, Q3 2026. Read the report.

Gartner® Magic Quadrant™ for Strategic Cloud Platform Services, 2026. By Alessandro Galimberti, Carolin Zhou, Douglas Toombs, Dennis Smith, Ed Anderson, Tobi Bet, Chuck Lawton, 1 September 2026.

Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.

Gartner and Magic Quadrant are trademarks of Gartner, Inc., and/or its affiliates.

This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request here.

Forrester does not endorse any company, product, brand, or service included in its research publications and does not advise any person to select the products or services of any company or brand based on the ratings included in such publications. Information is based on the best available resources. Opinions reflect judgment at the time and are subject to change. This report is part of a broader collection of Forrester resources, including interactive models, frameworks, tools, data, and access to analyst guidance. For more information, read about Forrester’s objectivity here.
The post Enterprise AI transformation relies on the end-to-end platform: Azure was built for this moment appeared first on Microsoft Azure Blog.
Quelle: Azure

The Economics of Agent Optimization: Context engineering for enterprise AI agents

This blog post is the third of a four-part series called The Economics of Agent Optimization, which shares the strategies, capabilities, and proof points to help you optimize agent costs and run AI as a managed investment system on Microsoft Foundry. The first post set out the three decisions that systems rest on. The second post took the request at runtime. This post takes the next one: making each agent cheaper over time as it learns what works.

Every agent has a mechanism that determines what its model sees on each turn. In many production systems, that choice was set during prototyping and never revisited, even though it often drives the largest share of operating cost and contributes to disappointing answers.

This is also the part of an agent that can improve on its own. The model remains as capable as when you selected it, and instructions change only when someone rewrites them. But what an agent knows, can access, and remembers, grows as it runs—making it the key to improving performance while lowering cost over time. Managing that process is called context engineering.

Why the context window sets what an agent costs

A model has no memory of its own. On each turn, its context window supplies everything it can use: instructions, available tools, retrieved documents, and conversation history. When the turn ends, that context disappears and must be sent again on the next one.

That cost is manageable for a chatbot answering one question. For an agent working across many turns toward one outcome, it is often the largest expense. Because the context window is paid for every turn, unnecessary content is billed repeatedly.

The less visible cost is quality. More context does not guarantee better answers: a relevant fact buried in 40 pages is harder to use, and a long tool list makes the wrong choice more likely. Each mistake adds more turns—and more cost—to recover.

That makes context worth a leader’s attention. Most cost reductions involve a tradeoff: a cheaper model may reduce quality, and shorter instructions may weaken an answer. By contrast, removing unnecessary context can lower costs without reducing quality, making it an easier optimization for teams to support.

What context engineering means in practice

That is what context engineering does: it decides what enters the context window on each turn, so the agent gets what this request needs rather than everything it might ever need. As a one-time choice, it is a design decision. Practiced continuously, it is how an agent improves, because every turn reveals what it actually used. Four questions cover the work, and teams usually take them in this order.

What should the agent know?

Many teams begin with broad searches that insert entire documents into the prompt. This approach is easy to build but costly to run, and it forces the model to find the one relevant detail amid everything else.

Foundry IQ replaces that with a managed knowledge layer. A knowledge base points at sources across Work IQ, Fabric IQ, Web IQ, Microsoft Azure Blob Storage, SharePoint, OneLake, and Azure SQL. When an agent submits a query, Foundry IQ decomposes it into subqueries, searches connected sources in parallel, semantically reranks the results, and returns grounded passages with citations. This narrows what enters the model’s context to the most relevant evidence while preserving traceability to the source.

Two features make this knowledge layer reusable across agents and governable at scale. A single knowledge base can serve multiple agents. Indexed sources can refresh incrementally on a configured indexer schedule, while remote sources are queried on demand. At query time, Foundry IQ can run under the caller’s Microsoft Entra identity, synchronize access-control lists for supported sources, and honor Microsoft Purview sensitivity labels, so the agent retrieves only content the caller is authorized to access.

Our internal evaluations showed that Foundry IQ knowledge bases improved evidence recall by up to 54% on the BrowseComp-Plus benchmark while reducing retrieval token costs by 34%. The gains came from agentic retrieval, semantic reranking, improved answer synthesis, and more efficient token use.

What should the agent be able to reach?

Tool overhead is easy to miss: adding one may take a single line of code, but its full description occupies the prompt. Every tool attached to an agent has that description sent to the model on every turn, needed or not, and enterprise agents pick up tools quickly as they connect to more systems.

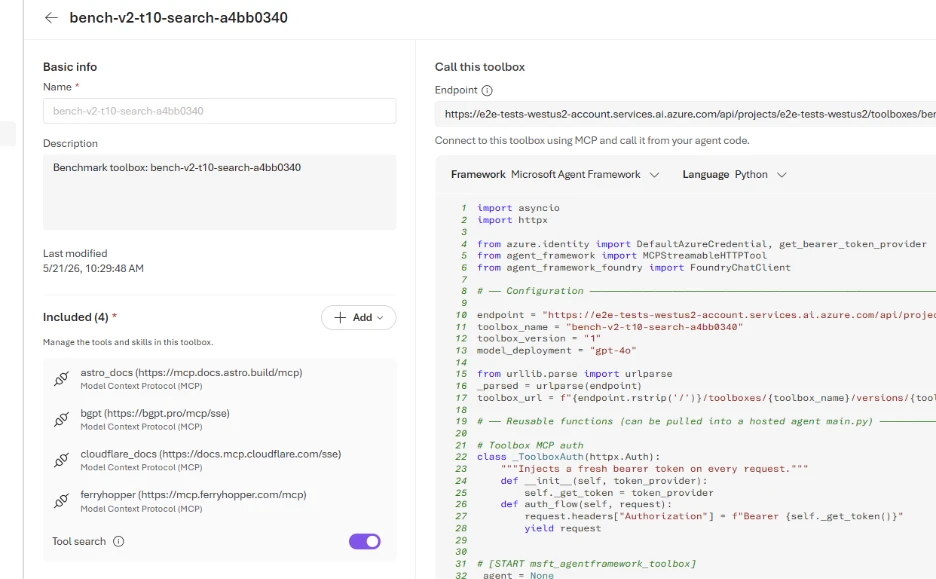
Toolboxes in Foundry give an agent one managed Model Context Protocol (MCP) endpoint for built-in tools like web search, code interpreter, and file search alongside custom MCP servers, OpenAPI 3.0 and 3.1 APIs, and A2A agents. Foundry manages authentication, access policies, and tool versions in one place, rather than configuring each integration separately for every agent. Once a new toolbox version is tested and promoted, connected agents can use it without code changes or redeployment.

Toolboxes organize your tools. The tool search capability inside Toolbox is what stops you paying for all of them. Instead of the full list, the model gets two things: a way to describe what it needs in plain language, and a way to call whatever comes back. The cost of the tool list stays flat, however large the toolbox grows. In internal benchmarking against a public, open-source tool-retrieval dataset, Toolboxes in Foundry reduced average input-token consumption around 97% for large tool libraries—directly lowering inference costs for customers building agents.1

Foundry also notices which tools each toolbox uses most and puts those within easy reach, so the common path gets faster and cheaper the longer the agent runs. Accuracy improves alongside cost, because a short, well-matched list means fewer wrong calls and fewer turns spent recovering.

How should the agent do the work?

Knowledge and tools cover what an agent can find and do. Neither covers how your company expects the work to be done: the escalation path a support agent follows; the checklist a code review applies. That guidance usually lives in the agent’s instructions. As a result, the same procedures may be copied across multiple agents and included in every request, even when they are not relevant.

A skill turns that guidance into a named, reusable procedure. Skills are stored centrally in Foundry and made available to agents through a toolbox. Instead of embedding a copy of the procedure in each agent, the toolbox references the centrally managed skill. When your organization improves a procedure, you can publish a new version and set it as the default. Every agent using that skill can then follow the updated procedure without code changes or redeployment. To minimize context usage, the agent initially sees only each skill’s name and short description. It loads the full instructions only when the skill is relevant. This makes it practical to offer a large library of detailed procedures without adding unnecessary content to every interaction.

What should the agent remember?

Agents need continuity, but they do not need to carry every detail from every interaction. Repeatedly sending an entire conversation to the model adds cost and consumes context, even when only a few details remain useful.

Memory in Foundry Agent Service helps agents retain important context without replaying entire conversations. It supports three types of memory:

Session memory for the current conversation.

User memory for preferences and facts that persist across sessions.

Procedural memory for learned workflows and task execution patterns.

This allows a returning customer to pick up where they left off, while enabling an agent to consistently follow proven processes without being re-instructed each time.

Together, these capabilities help an agent continue a customer interaction, personalize future responses, and improve how reliably it completes recurring tasks. Procedural memory complements centrally managed skills: a skill defines the organization’s approved procedure, while procedural memory helps an agent learn from its own task execution. In Microsoft’s evaluations, enabling procedural memory produced about a 5% improvement on STATE-Bench and Tau-Bench. Organizations can also control memory through user-level isolation, retention settings, and time-to-live policies that determine what is stored and when it expires.

Why context engineering becomes a system

Any team can assemble knowledge retrieval, tools, procedural guidance, and memory. The challenge is making them work together, under one set of permissions, and keeping them current as the organization changes.

Foundry brings these pieces into a single system. Knowledge, tools, skills, and memory can be managed through shared infrastructure rather than separate products, while permissions are enforced where data is retrieved, so agents inherit the access controls already applied to enterprise content. Foundry IQ extends that model across enterprise knowledge, business data, and organizational context, while remaining compatible with frameworks such as Microsoft Agent Framework, LangGraph, GitHub Copilot SDK, and Claude Agent SDK.

The result is that context improves without requiring agents to be rebuilt. Knowledge bases refresh as source systems change. Skills evolve as policies evolve. Memory accumulates what matters about users and successful workflows. Tool search adapts to the capabilities people actually use. Agent optimizer in Foundry Agent Service then closes the loop by analyzing agent behavior and generating improved instructions, skills, tool descriptions, and model configurations.

That is the larger goal of context engineering: not simply reducing prompt size or retrieval costs, but creating agents that improve with use. When the knowledge they draw from, the tools they discover, the procedures they follow, and the memories they retain all become better over time, an agent can become both more capable and more efficient without starting over.

Get started

If you’re building agents today, start by examining what enters the context window on every turn. Look at the documents being retrieved, the tools being exposed, the instructions being repeated, and the conversation history being carried forward. In many cases, improving those inputs has a larger impact on cost and quality than changing models.

Ground an agent in enterprise data with Foundry IQ: Connect a Foundry IQ knowledge base to an agent.

Give an agent one endpoint for its tools, and turn on tool search: Enable tool search in a toolbox.

Add memory so an agent carries context across sessions: Create and use memory in Foundry Agent Service.

Start building in Microsoft Foundry.

Microsoft Foundry

The enterprise AI platform to build, ground, and govern AI apps and agents at scale

Explore capabilities

Did you miss these posts in The Economics of Agent Optimization series?

AI cost management: From AI pilots to measurable ROI

AI cost optimization: How to lower AI spend

1 Command Line, Tool search: Finding the right tool at the right time, July 29, 2026.
The post The Economics of Agent Optimization: Context engineering for enterprise AI agents appeared first on Microsoft Azure Blog.
Quelle: Azure

Inside Microsoft’s marketing team: Scaling expertise with AI

Business leaders are facing a familiar challenge at an unfamiliar scale.

Every organization is being asked to move faster as markets change quickly, customer expectations continue to rise, and technology advances at a pace that can feel overwhelming. Teams are expected to deliver greater results, often with the same resources they had before.

AI is helping organizations meet those expectations. Some of the strongest examples I’ve seen revolve around scaling the judgment, strategy, and success measures that strong performers already set for themselves and their teams. AI agents apply that expertise consistently across a growing volume of work, helping them deliver more without sacrificing quality.

We’ve seen it firsthand on my team. As innovation cycles have accelerated, product launches have increased from a quarterly cadence to weekly—and sometimes even daily—events. Our teams are now supporting a growing volume of launches, up to 150% year over year.

To relieve the pressure, we’ve looked for places where AI can help teams at Microsoft find the right information faster, reduce repetitive coordination, and bring more consistency to work that depends on shared context. To do that, we used Microsoft Foundry, Microsoft’s platform for building and managing enterprise AI applications, to create agents grounded in business knowledge and embedded in the flow of work, helping our teams operate at greater scale while staying focused on the work where their expertise matters most.

Start building with Microsoft Foundry

Why context matters

One lesson became clear very quickly: AI is only as good as the data it has access to. General-purpose AI can generate content, but enterprise decisions depend on information spread across documents, workflows, business systems, communications, and institutional knowledge.

For us, Microsoft IQ helped connect that business context to our AI capabilities. Rather than asking employees to assemble information from multiple sources, agents could draw from the same knowledge people rely on every day to surface relevant information and support better decisions.

But IQ does more than ground AI in the right data. It helps connect the knowledge and workflows that shape how the business actually operates.

That shift changed the role AI could play. Instead of simply helping people find information, it could help teams work from a shared understanding of what’s happening across the business.

Learn how Microsoft IQ helps bring together people, data, knowledge, and workflows

Context alone wasn’t enough. The breakthrough wasn’t a single agent. It was creating a way for teams to build on what was already working.

As people shared successful agents and AI skills, expertise started becoming easier to reuse and scale. Ideas that began with one team could quickly create value for many others.

Microsoft Foundry became important because it allowed us to ground agents in organizational knowledge, connect them to existing workflows, and operationalize them beyond a single team.

In many ways, this reflects a broader lesson across AI adoption. As Jay Parikh recently wrote, “AI alone doesn’t transform a business. The system around it does.” The following examples show what that looked like inside our marketing organization:

const currentTheme =
localStorage.getItem(‘blogInABoxCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);

// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/1104726-MarThriveCustomerZero_tbmnl_en-us?wid=1280″,”title”:””,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1104726-MarThriveCustomerZero-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1104726-MarThriveCustomerZero-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1104726-MarThriveCustomerZero-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1104726-MarThriveCustomerZero-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/bloginabox/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F1104726-marthrivecustomerzero%2F1104726-MarThriveCustomerZero_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1104726-MarThriveCustomerZero_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1104726-MarThriveCustomerZero_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};

if (currentTheme) {
options.playButtonTheme = currentTheme;
}

document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6a9834893027f”, options);
});

Raising the quality bar at scale

As our Microsoft Foundry business grew, so did the volume of content we needed to create. Our team now reviews and publishes more than 200 blog posts each year, maintaining a consistent quality bar increasingly dependent on a small number of subject matter experts. Much of their time was spent applying the same review criteria over and over again.

Rather than reviewing every draft from scratch, one of our content leaders documented the rubric she uses to evaluate a strong blog and refined it until it reflected the standards our team expected.

Using Microsoft Foundry, we translated that expert-defined rubric into a repeatable workflow that could identify gaps and opportunities before content reached a human reviewer. The capability was integrated directly into the content creation process, bringing instant feedback to every drafted post and making expert-defined standards available to every content creator.

Review cycles that once required substantial manual effort can now be completed in minutes, resulting in higher satisfaction and over 2,000 estimated hours saved annually across the team. More importantly, the approach demonstrates a broader pattern organizations can apply in many domains: use AI to apply established criteria at scale so experts can focus their time where judgment, coaching, and experience create the most value.

What we automated is consistency, not judgment. Our team set the bar based on our expertise; the AI agent reviews every post against that bar.

Validating messaging before it reaches customers

As the pace of innovation accelerated, one question kept coming up: would our messaging resonate with the customers we were trying to reach?

At Microsoft, we aim to keep the customer at the center of everything we do. That led us to look for ways to evaluate messaging before it reached customers, using more than internal opinions alone.

We applied that approach through AI Messaging Assistant (AMA), which helps evaluate messaging and positioning against different audience perspectives before going to market. Instead of relying only on internal opinions, teams can pressure-test whether a message is clear, relevant, and actionable for the stakeholders they are trying to reach.

Using Microsoft Foundry, we grounded AMA with a virtual congress of personas based on real customer conversations and extended it with the expertise, product knowledge, messaging guidance, and business context our teams rely on every day. That made it possible to move from a one-off AI experiment to a repeatable workflow where teams could evaluate messaging against a shared understanding of audience needs rather than rebuilding that understanding for every review.

The broader pattern is using AI to pressure-test important decisions before they reach customers, partners, or employees.

Microsoft scales customer intelligence with AMA to speed decisions, deliver ROI

Keeping teams aligned as the pace accelerates

As launch activity accelerated across our business, keeping teams aligned became harder than creating the work itself. New announcements arrived daily. Priorities shifted quickly. Information was spread across planning backlogs, documentation, meetings, and operational systems. Our marketers were spending too much time assembling context and not enough time acting on it.

In response, we started by writing down how our marketing work actually gets done, turning an unwritten process into a clear specification. With that in hand, we could sort the work: which parts required a marketer’s judgment, which could be automated, and which could be delegated to AI.

Using agents built on Microsoft Foundry, we connected the systems our teams already rely on, including planning backlogs, documentation, meeting signals, and other operational sources. Rather than manually gathering updates from dozens of places, teams can work from a real-time view of key developments, upcoming launches, and changes that affect go-to-market plans.

This transformed alignment from a manual effort into a repeatable workflow. Instead of spending time assembling information, teams spend more time understanding what changed, why it matters, and what actions to take next.

The challenge was never a lack of expertise. It was coordinating that expertise across a rapidly changing environment.

The outcome is not merely faster communication. It is better organizational alignment. When teams operate from the same base, decisions happen faster, handoffs become smoother, and organizations can respond more quickly to change.

Scaling expertise, reducing friction

Across each of these examples, the goal wasn’t automation for its own sake. The goal was making expertise available wherever it could create value. Looking back, the lesson wasn’t that a single AI capability changed how we worked. It was that building the right system around those capabilities allowed expertise, context, and judgment to scale across the team.

Technology will continue to evolve. The pace of business will continue to accelerate. But the differentiator remains the same: People provide the judgment. People set the strategy. People define success. AI helps them scale it.

Microsoft Foundry

Foundry helps teams create agents grounded in enterprise knowledge, connected to the tools people use every day, and designed for production workflows.

Ready to build with Foundry?

The post Inside Microsoft’s marketing team: Scaling expertise with AI appeared first on Microsoft Azure Blog.
Quelle: Azure

Introducing Azure Multicloud Interconnect for AWS

As organizations accelerate AI adoption and modernize their digital estates, applications, data, and infrastructure increasingly span multiple cloud environments. Customers are choosing the best platform for each workload, leveraging unique capabilities across providers to drive innovation, resilience, and business agility.

Yet while multicloud strategies have become commonplace, networking between cloud environments remains complex. Establishing private connectivity often requires customers to manually stitch together services, coordinate provisioning across providers, manage multiple operational processes, and navigate fragmented support experiences. What should be a straightforward connectivity decision can take weeks or months to implement and manage.

Explore Azure Multicloud Interconnect

Today, Microsoft and Amazon Web Services (AWS) are taking an important step toward simplifying that experience.

Microsoft Azure and AWS are excited to collaborate on a multicloud networking solution that uses both AWS Interconnect – multicloud and Azure Multicloud Interconnect for network interoperability, enabling customers to establish a private, high-performance private connectivity between Microsoft Azure and AWS through a streamlined, cloud-native experience.

This collaboration is built using the Open API specifications for network interoperability. Azure Multicloud Interconnect helps remove much of the complexity traditionally associated with multicloud networking. Customers can provision connectivity through an integrated experience while benefiting from enterprise-grade performance, resiliency, security, and operational simplicity.

Simplifying multicloud connectivity

Until now, organizations connecting Azure and AWS environments required careful planning, physical connectivity, routing configuration, provisioning coordination, monitoring, and lifecycle management to assemble and maintain multiple components across providers.

Azure Multicloud Interconnect fundamentally changes this model. With Microsoft and AWS collaborating using the standardized Open API specification, customers can establish dedicated private connectivity through a simplified experience that abstracts the underlying complexity of multicloud networking. Rather than focusing on infrastructure management, organizations can focus on delivering applications, moving data, and accelerating business outcomes.

The result is a high-bandwidth, more predictable path to deploying multicloud architectures for mission-critical workloads.

Designed for the AI era

Training and inference workloads frequently require access to data distributed across environments. Enterprises are increasingly architecting applications that span cloud boundaries while maintaining performance, security, and compliance requirements.

Azure Multicloud Interconnect is designed to support these evolving requirements with high-capacity private connectivity that extends to Azure Private Link, providing an end-to-end private path between the clouds.

This combination of high-performance connectivity and operational simplicity enables customers to move faster as they build the next generation of AI-enabled applications and services.

As AI transforms every industry, customers need the freedom to place data, applications, and infrastructure wherever it delivers the greatest business value. Azure Multicloud Interconnect helps make that possible by providing resilient, high-performance, private connectivity between Azure and AWS through a simplified, cloud-native experience. Together, we are reducing the complexity of multicloud networking and giving customers the scale, reliability, and agility they need to power the next generation of AI and data-driven innovation.

Customers told us they wanted a better way to connect workloads spanning AWS and Azure, and the old ways of doing it were clunky. With AWS Interconnect-multicloud and Azure Multicloud Interconnect, we’re proving what’s possible when both sides commit to a high bar: MACsec security out of the box, four-nines availability, and scalability at the click of a button.
—Robert Kennedy, VP of Network Services at AWS

Advancing an open multicloud future

Azure Multicloud Interconnect represents more than a new connectivity offering—it is a step toward a more open and interconnected cloud ecosystem.

Looking ahead, we see the opportunity to extend this model beyond a single cloud-to-cloud relationship. The same open API specification can help enable broader interoperability across hyperscale cloud providers, creating a more consistent experience for customers operating in increasingly diverse multicloud environments.

Customers can deploy connectivity at speeds up to 100 Gbps from day one at general availability, helping meet the needs of high-bandwidth applications while providing the foundation for future growth. As demand increases, capacity can expand dynamically, enabling organizations to scale without disrupting operations or redesigning their network architecture.

Beyond hyperscalers, this approach has the potential to simplify connectivity with network service providers and telecommunications carriers. By adopting a common interoperability model, cloud providers and carriers can work together to streamline last-mile connectivity, accelerate provisioning, and reduce operational complexity across the end-to-end customer journey.

Our long-term vision is an open ecosystem where hyperscalers, network service providers, and telecommunications carriers use a common interoperability framework to establish and operate connectivity through standardized APIs. Customers should be able to provision trusted, high-performance connectivity between clouds, metro networks, and enterprise locations with the same simplicity and automation they expect from modern cloud services.

To learn more about how to implement multicloud networking on Azure, please visit the in-depth blog or visit the Microsoft Learn page to get started. To read the AWS announcement, please visit their blog.

Get started with Azure Multicloud Interconnect

Explore technical guidance for implementing private, high-performance connectivity between Azure and AWS.

Read the in-depth blog

The post Introducing Azure Multicloud Interconnect for AWS appeared first on Microsoft Azure Blog.
Quelle: Azure


