GPT-6 Astra, Sol, and Luna: For production agents in Microsoft Foundry

Today, we are expanding our GPT-6 series by welcoming GPT-6 Sol and GPT-6 Luna to our generally available lineup in Microsoft Foundry. Building on the exceptional customer momentum of GPT-5.6 Sol and GPT-6 Astra, this launch continues our work to deliver transformative capabilities in Microsoft Foundry that produce less noise and are more capable at completing full tasks with agents.

Explore GPT models in Foundry today

Astra brings advanced reasoning, software engineering and computer use to demanding work that requires both judgment and action. Azure customers report a step-change in capabilities, and strong cost-to-performance with the model using fewer, higher-value tokens to drive agents.

Completing the lineup, GPT-6 Sol is excellent for general-purpose use, while Luna brings efficient intelligence to high-volume data and preparatory work.

Put the right intelligence behind every agent

The right model for a job should be determined through evaluations: an agent handling a complex business decision and one routing routine requests have different needs. Microsoft recommends customers start with GPT-6 Astra for demanding work. For higher-volume workloads, GPT-6 Sol and Luna carry that progress forward, giving you a complementary choice built for production and scale.

GPT-6 Sol for production AI agents and complex workflows

GPT-6 Sol, and its proven predecessor—GPT-5.6 Sol—offer slightly more cost-effective intelligence with frontier efficiency. They support enterprise agents, coding and complex knowledge work, including reasoning across multiple steps, long-context analysis, and workflows that use tools. For teams evaluating their next production workload or migrating off a legacy model, Sol is a strong starting point.

GPT-6 Luna for efficient, high-volume AI workloads

GPT-6 Luna is Sol’s smaller, faster sibling, built for high-volume work. Use it for extraction, summarization, request routing, and routine customer interactions. Reserve deeper reasoning for the steps that need it, rather than applying the same model to every task.

As the GPT-6 lineup expands, the opportunity is not simply to choose a newer model, but to improve what your agents can accomplish while saving money. Customers should look beyond pricing per token and seek to understand cost per task, which is a better measure for understanding the ROI of AI.

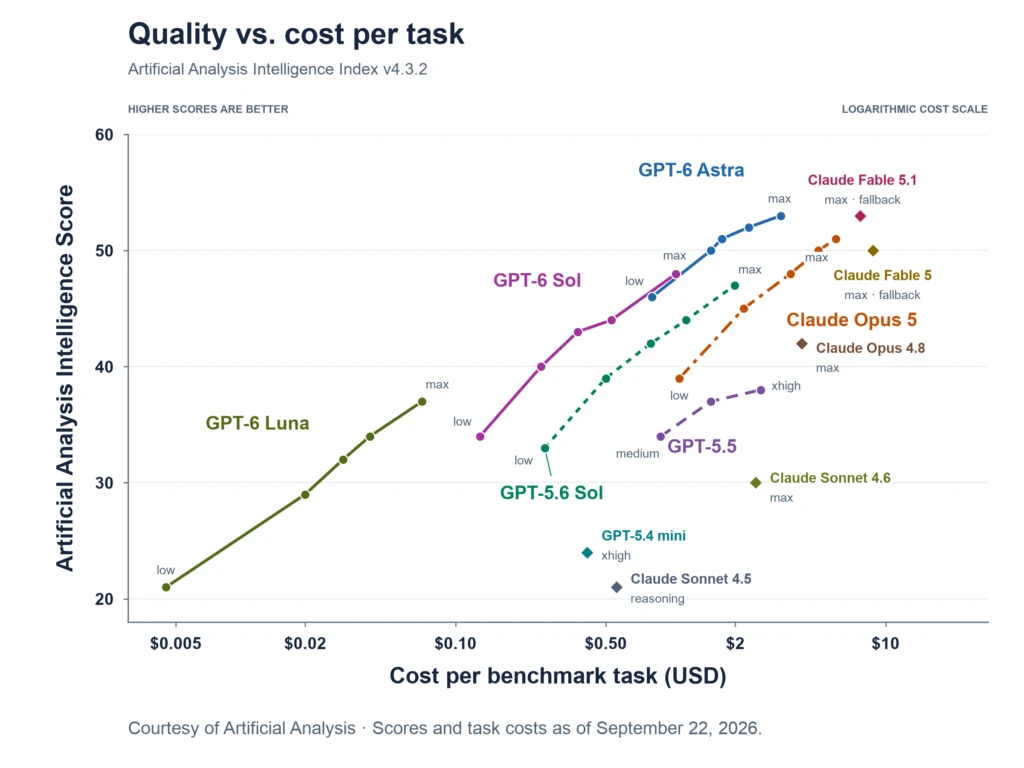
The accompanying chart illustrates why enterprise customers on Microsoft Foundry are switching to GPT-5.6 Sol and the latest GPT-6 offerings.

Foundry brings evaluation and monitoring together so teams can make those decisions with evidence. The real measure of that progress is what customers can do in production, which is why Foundry has always encouraged model choice and an open, interoperable stack.

The Foundry advantage, in customers’ words

Access to frontier models is only the starting point. Foundry pairs GPT-6 intelligence with the breadth of deployment options enterprise production demands. Today, Standard deployment is available for Astra, Sol and Luna across all 28 Global regions, and US and EU Data Zones; Provisioned Throughput for Astra and Sol across Global regions and US and EU Data Zones; and Priority Processing for Sol across Global regions and US Data Zones. The breadth and performance of Azure is why OpenAI continues to launch first on Azure, and why sophisticated customers like Manus choose Foundry.

Azure OpenAI models provide a core layer of intelligence powering Manus. Through Azure, we reliably integrate advanced models into our agentic workflows, enabling Manus to understand user intent, plan tasks, and execute complex work. Responsive Microsoft technical support and rapid access to new model capabilities help us iterate quickly and deliver a leading, reliable AI experience for our users.
—Tao Zhang, Co-Founder & Product Partner, Manus

For customers getting started with AI on Azure: choose Global for flexible, pay-per-token capacity, or supported Data Zone deployments for processing-location requirements. Priority Processing is a priority lane for responsive, pay-as-you-go experiences, with Provisioned Throughput providing reserved capacity and superior latency for critical production demand. Match the serving option to the workload, from interactive agents to high-throughput business processes.

That is the Foundry advantage: not just frontier intelligence, but the platform to put it to work. Teams can match each workload to the right model, deployment option, and controls, balancing capability, responsiveness, and cost as adoption grows. By bringing these choices together on Azure, Foundry helps customers focus on delivering business value, with the operational foundation to move from a promising agent to production at scale.

Our customers work in domains where getting an answer isn’t enough, it has to be the right answer, and it has to hold up to scrutiny. The latest Azure OpenAI frontier models reason through a problem in steps we can follow, which is what makes it viable for the research and compliance workflows our professionals depend on. Building on Microsoft Foundry lets us take those agentic workflows into production on infrastructure and services that already meet our governance, data residency, and security obligations.
—Brian Diffin, CTO of Wolters Kluwer Tax & Accounting

GPT-6 pricing and deployment options**

ModelDeploymentContext LengthPricing (USD $/million tokens)InputCached InputCached WritesOutputGPT-6 AstraGlobal StandardShort context$10.00$1.00$12.50$50.00Long context$20.00$2.00$25.00$75.00Data Zone Standard (US)Short context$11.00$1.10$13.75$55.00Long context$22.00$2.20$27.50$82.50Data Zone Standard (EU)Short context$12.00$1.20$15.00$60.00Long context$24.00$2.40$30.00$90.00GPT-6 SolGlobal StandardShort context$2.00$0.20$2.50$10.00Long context$4.00$0.40$5.00$15.00Data Zone Standard (US)Short context$2.20$0.22$2.75$11.00Long context$4.40$0.44$5.50$16.50Data Zone Standard (EU)Short context$2.40$0.24$3.00$12.00Long context$4.80$0.48$6.00$18.00GPT-6 LunaGlobal StandardShort context$0.10$0.01$0.125$0.50Long context$0.20$0.02$0.25$0.75Data Zone Standard (US)Short context$0.11$0.011$0.1375$0.55Long context$0.22$0.022$0.275$0.825Data Zone Standard (EU)Short context$0.12$0.012$0.15$0.60Long context$0.24$0.024$0.30$0.90

**Pricing for both Provisioned Throughput and Priority Processing varies by deployment type. For each offer, U.S. Data Zone is priced at a 10% premium to Global. For current rates and terms, see the Azure OpenAI pricing page.

Build safer AI agents with Microsoft Foundry

GPT-6 models running on Azure have multiple layers of safety and security built directly into the model and around it. At the core, the model itself carries the alignment and safety training built in, while the prompts and outputs around it are protected by content filters and guardrails that govern what the agent can say. Beyond that, tool calls and responses are protected by controls and prompt injection mitigation that govern what the agent can do, and identity and access are protected by enterprise policies that govern what it can reach.

Foundry helps teams continuously strengthen safety layers as risks evolve. It applies guardrails at key checkpoints, including prompts, outputs, tool calls, and tool responses. Identity and access controls govern what agents can do and reach. Microsoft Purview applies enterprise data policies. Evaluation, tracing, and monitoring give teams the evidence to optimize those controls over time, with human checkpoints at every phase.

Move to GPT-6. Build your next generation of agents.

Build your next agentic workloads in Microsoft Foundry. Start with GPT-6 Astra for demanding reasoning, Sol for general production use, and scale high-volume tasks with GPT-6 Luna. For customers of legacy models, we recommend evaluating an upgrade to GPT-5.6 Sol and above.

Your next agent needs more than a powerful model. Foundry brings an open intelligence stack, deployment flexibility, and Azure enterprise controls together so you can build with confidence and scale from your first workload to production.

Start building in Foundry today

Access GPT-6 models, evaluate the right fit for your workload, and scale from experimentation to production.

Begin here

The post GPT-6 Astra, Sol, and Luna: For production agents in Microsoft Foundry appeared first on Microsoft Azure Blog.
Quelle: Azure

Designing agent-first platforms: What changes when agents do the work

For decades, applications have been designed to wait. A user clicks, a request arrives, code runs, a response goes back. And we got very good at this. We learned to forecast traffic, scale on demand, wrap everything in enterprise controls, and run it all with the operational discipline that keeps critical business systems available around the clock.

That model is being turned on its head, and being asked to serve apps that continuously act, and wait for no one.

What changed is not the infrastructure underneath, but the software being written on top of it. The work we used to capture as deterministic code, where every branch was defined in advance and every step was known before the first line ran, is now being rewritten as multi-agent applications that work out the steps at runtime. A developer used to encode the path, and now a developer describes the outcome and lets a set of agents reason their way toward it.

Agents work differently. Given an outcome, an agent reasons through the problem, breaks it into steps, writes code to solve it, runs that code, looks at the result, and goes again. The work happens in a loop that no human is standing inside. That change puts pressure on assumptions our platforms were built on, because an application that responds and an agent that acts need very different things underneath them.

The organizations pulling ahead right now are the ones who understood this early. They are not simply adding AI to what they already have. They are designing for a different kind of software.

What it takes to run an agent you can depend on

Getting an agent working is no longer the hard part. A team can connect a capable model to a few tools, ground it in company data, and have something genuinely useful inside a week. That is real progress, and it is why so many organizations now have a pilot that impressed the room.

The distance between that pilot and an agent the business depends on around the clock is where the real challenge is.

An agent operating continuously on behalf of a company gets held to the same bar as everything else in production. It needs its own identity, with permissions scoped to what it is allowed to see. It needs to be watched while it works, so a team can trace every step it took, evaluate whether the outcome was right, and catch the drift that shows up quietly weeks after launch. It needs guardrails that are enforced at runtime. And it has to clear the same security and compliance standards as the rest of the estate. No one is going to grant an agent an exemption.

None of that is work a team should be doing for itself. That is the job of an agent platform. Microsoft Foundry is where agents are built, grounded in enterprise knowledge, given a first-class identity through Entra Agent ID, and traced and evaluated once they are live. The Foundry Control Plane governs the agent, but it does not dictate where the agent’s work actually runs. That is a separate decision, and a separate layer.

Get started with Microsoft Foundry

Where the work actually runs

The moment an agent stops answering questions and starts completing tasks, it has to execute code. It clones a repository. It installs a package. It runs an analysis against live data and calls into a system of record. That execution needs a runtime environment. In most cases, it simply inherits the one the host application is already running on, because that is the path of least resistance.

Run the agent on shared infrastructure and every workload inherits the blast radius of every other one. Give it broad access so it can be useful and you have handed an autonomous process far more reach than you intended. Lock it down until it is safe and the agent can no longer do the job you built it for. Teams get stuck in this trade-off, and it is where most promising agents usually stall before they reach production.

The answer is not to limit what the agent can do. It is to give it a dedicated environment, with its own identity and guardrails for execution.

Azure Container Apps Sandboxes provides exactly that. Every agent execution gets a fully isolated environment of its own, created in seconds and gone when the work is finished. It runs as an identity you control, can access only the systems you have allowed it to reach, and never stores the credentials it uses to get there. And when a task spans hours or days, the environment can be paused and resumed with its full working context intact, so the agent picks up precisely where it left off.

There is real engineering behind this. Each environment runs inside its own hardware-isolated microVM, which is what makes strong separation and sub-second startup possible at the same time. But the mechanism is not the point. Isolation is built into the runtime rather than wrapped around it, so teams stop choosing between a capable agent and a controlled one.

Nothing disappears into the sandbox. The agent is still governed by Foundry, so what it sent into the sandbox and what came back stay on the record with every other step it took.

The architecture pattern emerging across the enterprise

Put the two together and a clear design pattern appears, one we are now seeing repeatedly across industries.

Build and govern the agent on Foundry. Extend its execution into an isolated sandbox on Azure Container Apps. The agent keeps its identity, its permissions, and its oversight. The agent does not change when its work moves. Only the ground it runs on does. The work it performs happens in an environment that is purpose-built for agent tasks with ultra-fast executions, scoped to what it needs, and dissolved afterward.

This is what allows an organization to move from a handful of supervised agents to thousands running concurrently, without asking security and platform teams to accept risk they should never be asked to accept.

What this looks like in practice

Regulated client work, delivered at scale. Digital Gateway Powered by Claude brings Claude’s capabilities into KPMG’s connected tax platform on Microsoft Azure, giving professionals a secure, trusted environment to work alongside AI. Within the platform, DG Cowork serves as the AI-powered workspace where professionals can analyze information, generate content, and advance complex work. Because client data must remain separated by engagement, the platform was built with engagement-specific workspaces and controls at its foundation. DG Cowork is designed for a global scale, with more than 30,000 Azure Container Apps Sandboxes running concurrently.

Delivering answers to the questions nobody had time to ask. Cognite serves industrial operators who face a common challenge: their most valuable questions—like which assets are underperforming and why— are often too time-consuming to answer. Because traditional analysis took days, these investigations were rarely commissioned, leaving teams to rely on experience alone. Cognite Atlas AI changes that. Each agent gets its own governed workspace grounded in live customer data in Cognite Data Fusion, turning days-long investigations into traceable answers delivered in minutes. And for more complex problems, agents can pause and resume investigations without losing context, allowing them to work through a problem over time much like an engineer would.

Atlas AI agents are powered by Azure OpenAI models in Microsoft Foundry, but to handle complex work in Cognite Data Fusion they needed to execute arbitrary code and work with files directly – which meant sandboxes that truly isolate each user’s agent, environment, and data. With Azure Container Apps Sandboxes we had a prototype running in hours and were testing with customers within weeks, because Azure handles the hard part: per-user isolation, egress policies, sub-second execution. For our industrial customers, that’s the difference between a days-long manual investigation into “which wells are underperforming and why?” and a cited draft in minutes.
—Christian Flasshoff, Architect, Atlas AI, Cognite

A safe place for every learner. The Department for Education in South Australia runs EdChat so students can learn by writing code and exploring data alongside AI, across 60,000 students and more than 40,000 staff. That model only works if every student gets an environment of their own, with clear guardrails, and can come back later to find their work exactly as they left it. Building that in house meant owning the machinery behind it. The department estimates that moving to Azure Container Apps Sandboxes lets them retire close to 50,000 lines of code written to manage custom code interpreter state themselves. It is a per-user execution model at the scale of a school system, and a maintenance burden the department no longer has to carry.

Three very different organizations. One common story. None of them were held back by what the models could do. They were held back by not having anywhere to run the work at their scale, against their real data, with economics that made sense.

Learn more about Azure Container Apps Sandboxes

We built this because we needed it

More than a million sandboxes per day run in production across Microsoft, powering GitHub Copilot, Copilot Studio, Security Copilot, Foundry Agent Service, Azure SRE Agent, and other Azure services.

Every one of those sandboxes has someone on the other end of it. A developer expecting a pull request to come back finished. An analyst chasing an alert before the shift ends. A support team working down a queue that has to be empty by morning. Their day moves at the speed this layer runs, and it either holds or it doesn’t. That is a sterner test than anything we could design internally, and it is the one this infrastructure has been passing at scale for a long while now.

One architecture sits beneath both our developer tools and our AI platform. That is the same architecture we are making generally available to you.

The decision in front of you

Every major platform shift eventually comes down to a design choice made early, by people who could see where things were heading.

The teams who will scale agents successfully over the next few years are making that choice now. They are separating the platform that governs the agent from the environment that runs its work, and they are treating that separation as a foundational decision rather than something to retrofit once a pilot succeeds.

The agents are ready. The question worth asking is whether your platform is designed for software that acts.

Azure Container Apps Sandboxes

Learn more about designing agent-first platforms with Azure.

Get started

The post Designing agent-first platforms: What changes when agents do the work appeared first on Microsoft Azure Blog.
Quelle: Azure

Your architecture diagram is not your resilience

This first article in our resilience series draws on a conversation with Mark Russinovich about how resilience is changing in the AI era and what it takes to continuously validate it at scale.

What surprises me most about resilience failures is how ordinary the drift is. A workload is deployed across availability zones, but a health probe still points to a single dependency. A database supports failover, but the application’s connection string is pinned to one region. Nothing looks broken. The architecture diagram still shows a resilient design even as the operational reality underneath it changes.

For years, resilience was something you set up once: configure disaster recovery, write a runbook, run the occasional failover test. That kept the lights on, but it treated resilience as a project with an end date rather than a property you maintain.

So, when an availability zone or a region has a bad day, the question is not whether a recovery plan exists on paper. It is whether resilience is still true today, and whether the team can prove it.

The dependency that breaks a workload is also changing. On Microsoft’s FY26 Q4 earnings call, Satya Nadella put it plainly: “For whatever reason, if a given model goes away, then you can’t be left high and dry. You need to be able to still continue your cyber operations.”

Traditional disaster recovery planning assumes the critical dependency is infrastructure. Increasingly it is an AI model, an inference endpoint, a retrieval pipeline, or a service operating under capacity constraints. A workload can be perfectly healthy from an infrastructure perspective and still fail its users because that dependency is unavailable, throttled, or economically impractical to run. That dependency rarely appears on the diagram at all.

There is a second shift underneath the first. An architecture diagram assumes a human drew it and a human will read it. Both of those assumptions are ending, and the dependencies it describes are no longer all deterministic. That changes what it means to know your estate is resilient.

This is the first in a series on how we are helping customers move to resilience that is designed in, measured as the estate changes, and improved over time. We have written before about how to design a resilient workload. This is a different problem: knowing whether hundreds of workloads still match their design today and being able to prove it. It is where a large share of our roadmap investment is now going.

Why resilience drifts

Resilience has always been a shared responsibility. We provide the availability zones, a secondary region of choice, and the replication primitives needed to support resiliency, and those do not drift. What drifts is the other half of the bargain: whether a given workload still uses them the way it was designed to, after a year of changes nobody flagged as risky. Change is where this concentrates. Across the industry, roughly 70 percent of cloud outages are related to change in some way—not dramatic failures, but ordinary modifications whose blast radius nobody re-evaluated.

That is why change discipline matters as much as design. Internally, a change rolls out to a canary region first, then a pilot region, with bake times where health signals are watched before it goes any further. That practice came out of an incident of our own, and it is the same discipline the Well-Architected Framework describes as safe deployment practices.

Learn more about the Azure Well-Architected Framework

Disaster recovery is reactive by design. Teams set recovery objectives when a project ships, stand up replication, and then move on, with little ongoing visibility into whether those objectives still hold as the workload changes. Resilience is designed once and rarely revisited. Across a growing estate of availability zones and regions, the distance between the resilience that was designed and the resilience that actually exists widens quietly, and it usually surfaces only during an incident.

const currentTheme =
localStorage.getItem(‘blogInABoxCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);

// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/1117657-resilience-drift_tbmnl_en-us?wid=1280″,”title”:”Resilience drift”,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-resilience-drift-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-resilience-drift-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-resilience-drift-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-resilience-drift-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/bloginabox/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F1117657-resilience-drift%2F1117657-resilience-drift_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-resilience-drift_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”}]};

if (currentTheme) {
options.playButtonTheme = currentTheme;
}

document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6ab4e1548fa53″, options);
});

We learned this the hard way. Mark tells the story of the storage change that came close to taking Azure down, and what it permanently changed about how we deploy.

What a diagram can’t tell you

A diagram is a claim about a system, made once, by someone reasoning about the system as they believed it to be. It is useful, and it is not evidence. There are four things it structurally cannot tell you.

Whether the goal is being met right now. A diagram has no timestamp. Health modeling does: described in the Well-Architected Framework and now available through health models in Azure Monitor, it represents an application as a hierarchy of its components and the signals underneath them, so health is expressed in terms the business recognizes rather than as a wall of resource-level metrics. Paired with service level indicators, it answers the only question that matters during an incident: is this application meeting its objective right now? The standard that matters is not our own. A service is only healthy if the customer thinks it is healthy—we can believe it is fine, but if the customer is not seeing a healthy service, we have a problem.

What “resilient” even means for this application. On a diagram, resilient is an adjective. A resiliency goal makes it a threshold you either meet or miss and defining it at the level of the application rather than resource by resource is what makes the answer meaningful.

Whether the failover path actually works. Every diagram draws the arrow. Only a test proves it.

The resources nobody drew. A diagram shows what someone remembered. Generated Infrastructure-as-Code covers every resource in the application. The difference between those two sets is where drift begins—and increasingly the reader on the other end is an agent rather than a person, working from the outcome you asked for instead of the picture you drew.

This is how we run Azure. Rather than asking each team to declare what healthy means for their service, we standardized on service level indicators, then applied machine learning to observed behavior so that healthy is defined by what the service actually does rather than by what someone assumed it would do.

This is the part I find most interesting. We wrote our documentation, our schemas, and our templates for people. Increasingly the thing reading them is an agent, working from the outcome you asked for rather than the picture you drew, and generating the resources itself. When the author and the reader are both machines, a diagram is no longer even the medium the decision is made in.

const currentTheme =
localStorage.getItem(‘blogInABoxCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);

// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/1117657-proving-resilience_tbmnl_en-us?wid=1280″,”title”:”Proving resilience”,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-proving-resilience-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-proving-resilience-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-proving-resilience-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-proving-resilience-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/bloginabox/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F1117657-proving-resilience%2F1117657-proving-resilience_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-proving-resilience_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-proving-resilience_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};

if (currentTheme) {
options.playButtonTheme = currentTheme;
}

document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6ab4e1548ff32″, options);
});

Mark on why we break our own services on purpose, what a game day actually tests, and why every failure mode we simulate is one that has really happened.

When the dependency is probabilistic

A model that disappears is the obvious risk. The subtler one is a model that answers, differently each time. It is a newer source of drift, and it does not behave like the old ones. Ask the same question of a model twice and you can get two different answers. That makes correctness harder to define, and it makes change harder to reason about: if you change the prompt, change the model, or change the harness and the skills around it, you have changed the software, and it deserves the same discipline as any other change.

Most teams smoke-test instead. It looks fine, so it ships. Evaluation is the step that gets skipped, and it is the one that matters: measuring the system against what you actually consider valuable, not simply whether it responded.

The first question is whether the system needs to be probabilistic at all. Stay as deterministic as you can and use AI where it earns its place, not everywhere. And where you can wrap a non-deterministic system in a deterministic check, do it. If an agent is only supposed to update dependency versions, have a second system verify that versions are the only thing that changed. Where a deterministic check is not possible, use adversarial review: a second agent whose whole job is to find what is wrong with the first one’s work.

And accountability does not transfer. When someone deploys an agent, someone remains answerable for what it does.

That applies to us as well. Our own incident triage system uses language models to answer which service is responsible for an incident—work that used to mean waking people up to argue over logs. It is genuinely faster, and it is still trust but verify.

const currentTheme =
localStorage.getItem(‘blogInABoxCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);

// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/1117657-ai-uncertainty_tbmnl_en-us?wid=1280″,”title”:”AI uncertainty”,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-ai-uncertainty-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-ai-uncertainty-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-ai-uncertainty-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-ai-uncertainty-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/bloginabox/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F1117657-ai-uncertainty%2F1117657-ai-uncertainty_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-ai-uncertainty_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-ai-uncertainty_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};

if (currentTheme) {
options.playButtonTheme = currentTheme;
}

document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6ab4e154902b2″, options);
});

Mark on why guardrails around AI should be deterministic wherever possible, and why the agent is never the one accountable.

What this looks like in practice

That discipline has to hold wherever a workload runs, and the foundations are familiar. The reliability guidance in the Well-Architected Framework already says to design resilience in from the start, and the Cloud Adoption Framework describes the operating half: carrying that intent into how the estate is actually run and reviewed month after month. Where an estate spans global, national, and sovereign or regulated environments, the word resilient has to mean the same thing in each rather than being redefined at every boundary; our guidance on reliability and sovereignty covers where those constraints intersect.

Your diagram shows three zones. It does not show that the health probe behind the load balancer resolves to one of them. Availability zones protect a workload from datacenter-level failures within a region, but only if compute, storage, and data tiers are genuinely spread across them.

Plan region resiliency for disaster recovery. Set explicit recovery objectives, an RTO and RPO, for each workload. Availability zones give you high availability inside a region, while a secondary region of choice provides a failover location when an entire region is affected. They answer different risks, and a resilient design is deliberate about both. In a regulated estate the choice narrows further, because a recovery region has to sit inside the same jurisdiction as the workload it protects.

Decide how much resilience is worth buying. Resilience is a cost decision as much as a design one. An application carrying 100 million dollars of revenue on a single day justifies an active-active topology across regions for that day; the same application may run in a single region with active-passive failover for the rest of the year. The right answer is deliberate, not maximal.

Know your blast radius. Understand what each workload depends on and where its hidden single points of failure are, then keep that picture current as the application changes. Internally we do this as reliability threat modeling: the same discipline as security threat modeling, asking of each component what would happen if it failed, and what we would do about it.

Check the dependencies your recovery path itself relies on. A workload can be replicated correctly and still be unrecoverable: if its encryption keys live only in the primary region, they are gone precisely when a region outage means you need them. Recovery paths have dependencies too, and they are rarely on the diagram.

Your diagram probably has no box for the AI dependency your application now relies on. Design for your application, workload, AI model, and service dependencies, not just infrastructure. Plan for graceful degradation and fallback so that if a critical dependency is deprecated, throttled, unavailable, or capacity-constrained, the workload continues to operate through an alternative path rather than failing outright.

This is not theoretical. Carne Group, one of Europe’s largest independent third-party asset managers with one trillion dollars under management, rebuilt its estate on Azure with infrastructure-as-code landing zones precisely so resilience would be reproducible rather than remembered. Because the definition lives in code, their team can stand up a duplicate site in another region and, as Carne Group’s global technology lead Stéphane Bebrone puts it, “even in the event of a worst-case scenario, we could be back up and running more or less in the same day.” They are working toward an active-passive topology across regions and plan to use Chaos Studio to verify those failover paths on a schedule rather than on an incident. Under DORA, they have to be able to prove it, not assert it.

Learn more about how Carne Group used Azure Site Recovery and Backup

Closing the gap between intent and reality

An architecture diagram is a statement of intent, not proof. It may show zone redundancy, regional failover, and protected dependencies, but only a test can determine whether those assumptions still hold. Assembling the underlying data into a clear view of application resiliency takes real effort and expertise. That is the customer’s half of the shared responsibility, and it is the gap Azure Infrastructure Resiliency Manager is built to help close. In public preview, its agentic-first experience helps teams start resilient, get resilient, and stay resilient.

Start resilient. Define what resilient means for an application, set explicit resiliency goals, and use the Resiliency Agent to generate resiliency-aware Infrastructure-as-Code up front, so a new workload starts resilient instead of being corrected months later. Service Groups help teams represent an application as a logical group of Azure resources in the portal, making it easier to manage resiliency posture at the application level rather than resource by resource.

Get resilient. See where the estate stands against the intended design, identify resources that were never zone resilient or stopped being so after a change, and prioritize the gaps that matter first. Rather than correlating findings across several tools, teams get recommendations and generated Infrastructure-as-Code for supported fixes, so remediation can move through a pull request instead of becoming a separate project.

Stay resilient. Validate the assumptions behind the recovery path before a real outage does it for you. For workloads where the customer manages the compute, such as virtual machines, a zone-down drill can simulate the loss of an availability zone and show what actually happens to the application. For other services, teams can use failover validation, product-specific recovery capabilities, and fault injection through Azure Chaos Studio to test the right failure modes.

We will be candid about the gaps too. Consistent, self-service resiliency assessment across every workload and environment is not finished work, and saying so matters. Resiliency improves when teams can see the gaps, measure them, and systematically close them over time. It is also work that never quite ends. As services harden the failure rate drops, but the failures that remain get rarer and stranger; you approach perfection asymptotically without ever arriving.

The bottom line: a diagram is not proof

Resilience is not a project you finish; it is a posture you maintain. The work is to design it in from the first architecture decision, then keep proving it as the estate changes, so drift is caught by a test rather than by an incident. All of it is anchored in the Azure Essentials frameworks, the Well-Architected Framework, and the Cloud Adoption Framework, so that resilient and sovereign carry the same meaning across every environment instead of being reinvented team by team.

None of this is a new framework. A diagram tells you what you intended; only a test tells you what you have. That was true when people drew the diagrams and read them. It matters more now that neither is reliably the case, and that some of what you depend on answers differently every time you ask. If resilience cannot be tested, it cannot be trusted.

In the next part of this series, we will look at how to measure that posture at scale.

const currentTheme =
localStorage.getItem(‘blogInABoxCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);

// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/1117657-full-interview_tbmnl_en-us?wid=1280″,”title”:”Full interview”,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-full-interview-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-full-interview-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-full-interview-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-full-interview-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/bloginabox/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F1117657-full-interview%2F1117657-full-interview_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-full-interview_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1117657-full-interview_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};

if (currentTheme) {
options.playButtonTheme = currentTheme;
}

document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6ab4e15490faf”, options);
});

The three clips above are drawn from a longer conversation covering the 2014 change that came close to taking Azure down, how we learned to measure health from the customer’s point of view, what breaks differently when a dependency is an AI model, and why the hardware in a datacenter fails every single day. Check out the full interview on the Azure Essentials YouTube channel.

Azure Essentials

Check out the full interview on the Azure Essentials YouTube channel.

Watch now

Resources

Cloud Resiliency

Azure Essentials

Azure Infrastructure Resiliency Manager

Reliability design principles—Azure Well-Architected Framework

Health modeling for workloads—Azure Well-Architected Framework

Health models in Azure Monitor (preview)

Cloud Adoption Framework for Azure

Azure Architecture Center

Reliability and Sovereignty in Azure

What’s new in the Resiliency service

Enable Zone Resiliency for Azure Workloads

Azure Chaos Studio documentation

Azure Site Recovery documentation

Azure Backup documentation

Carne Group boosts infrastructure and cyber resilience with Azure Site Recovery and Backup

Safe deployment practices—Azure Well-Architected Framework

Meet Brain: The AI system behind Azure reliability

Optimizing incident management with AIOps using the Triangle System

Proving application resilience on Azure with Chaos Studio

Advancing reliability—Azure Blog series

The post Your architecture diagram is not your resilience appeared first on Microsoft Azure Blog.
Quelle: Azure
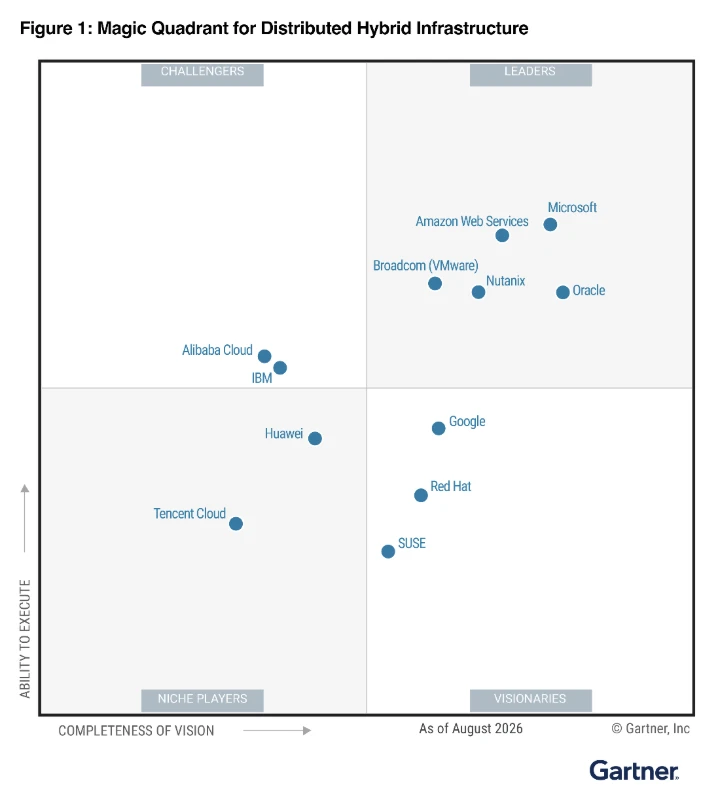
Microsoft recognized as a Leader in the 2026 Gartner® Magic Quadrant™ for Distributed Hybrid Infrastructure

We’re proud to share that Microsoft has been recognized as a Leader in the 2026 Gartner® Magic Quadrant™ for Distributed Hybrid Infrastructure for the fourth consecutive year. Microsoft is positioned highest for Ability to Execute.

We believe this recognition reflects the strength of Microsoft’s unified approach to distributed infrastructure. With Azure Local and Azure Arc, organizations can manage infrastructure across datacenters, edge locations, multi-cloud environments, and sovereign deployments through a consistent Azure foundation.

Read the full 2026 Gartner Magic Quadrant for Distributed Hybrid Infrastructure report

One Azure platform for distributed infrastructure

Customers want the flexibility to run workloads where it makes the most sense for their business without taking on additional operational complexity. As infrastructure extends across datacenters, edge locations, and the cloud, Microsoft helps customers maintain consistency through common tools, processes, and management experiences, reducing fragmentation and allowing teams to focus on delivering business value.

Azure Arc extends Azure management and governance to resources running in data centers, at the edge, and across multi-cloud environments. Azure Local brings Azure infrastructure and services into customer-controlled locations so organizations can run cloud services and AI workloads closer to their applications and data.

Together, Azure Arc and Azure Local give organizations a common way to operate across environments without requiring every workload to run in the same place. Some applications are best suited for the public cloud. Others may need to remain in a corporate data center, operate at the edge, or run within a customer-controlled sovereign environment. While deployment locations differ, management and governance can remain consistent.

Microsoft continues to expand the environments Azure Local can support, from small-form-factor edge deployments to large scale data center environments. Azure Local supports both hyperconverged architectures and options for disaggregated compute and external storage, so infrastructure can be designed around the needs of the workload rather than a single deployment model.

Choice and operational control for sovereign workloads

The same workload-centric approach applies to digital sovereignty, an increasingly important consideration for organizations around the world. Microsoft Sovereign Cloud is not a single deployment model, but a continuum of choices and controls.

For many workloads, sovereignty requirements can be addressed in public cloud through capabilities for data residency, encryption, confidential computing, policy enforcement, and operational oversight. Other workloads need to run in customer-controlled locations or require greater separation from public cloud operations.

Built on Azure Local, Microsoft Sovereign Private Cloud supports these scenarios by giving customers greater control over infrastructure, data, operations, and access, while retaining a familiar Azure foundation. For environments where connectivity to the cloud is restricted or unavailable, disconnected operations on Azure Local bring a local control plane into the customer environment. This enables customers to deploy and manage Azure Local and supported capabilities without ongoing connectivity to the cloud.

Together, these options allow organizations to apply different levels of sovereignty and operational control to different workloads instead of forcing the entire estate into a single architecture.

Bringing AI closer to applications and data

The growing adoption of AI is making workload placement decisions even more important.

For some workloads, the scale and breadth of the public cloud are the right fit. Others need inference to happen where data is generated because of latency, connectivity, governance, or sovereignty requirements.

Foundry Local on Azure Local extends AI inference into Azure Local environments, allowing organizations to deploy and run models closer to their applications and data using Kubernetes-native operations.

Investing in what comes next

We see the 2026 Gartner recognition as validation of a clear direction: distributed infrastructure should provide customers with choice over where workloads run without requiring fragmented management, governance, and operational models.

We will continue investing in connected and disconnected operations, scalable infrastructure, data and AI capabilities, and consistent Azure management across distributed environments.

We are grateful for the trust our customers place in us and remain committed to delivering the flexible, consistent, and secure platform they need to power the next generation of distributed infrastructure.

Learn more about Azure Local and Azure Arc

Explore digital sovereignty at Microsoft

Join us at Microsoft Ignite this November

Recognized as a Leader

2026 Gartner Magic Quadrant for Distributed Hybrid Infrastructure

Read the report

Gartner, Magic Quadrant for Distributed Hybrid Infrastructure, [Julia Palmer, Elaine Zhang, Adrian Wong, Daniel Bowers; 7 September 2026].

Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.

Gartner and Magic Quadrant are a trademark of Gartner, Inc., and/or its affiliates.

This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request from Microsoft.
The post Microsoft recognized as a Leader in the 2026 Gartner® Magic Quadrant™ for Distributed Hybrid Infrastructure appeared first on Microsoft Azure Blog.
Quelle: Azure
Two zones or three? A design framework for zone-resilient Azure workloads

Takeaway: Zone resiliency isn’t a single number you apply to a whole workload. The useful question isn’t “how many zones?” but “how many zones does each component need to survive the loss of one?” Decide zone patterns component by component, use service-managed zone redundancy wherever it fits, and reserve three-zone designs for the components that genuinely require a third failure domain. For a deeper, decision-oriented walkthrough on choosing between two-zone and three-zone patterns for your specific workloads, see the companion post, Choosing two-zone and three-zone patterns for zone-resilient Azure workloads.

Ask a room of architects how many Microsoft Azure availability zones a production workload needs, and most will answer “three.” It’s a reasonable instinct, but “three zones everywhere” is a rule of thumb standing in for a decision that deserves more thought. Treating it as a default quietly costs you capacity, money, and operational complexity you may not need while occasionally giving you less protection than you assumed.

Zone resiliency is not a property you switch on for an entire workload. It’s a set of decisions you make component by component. Some components are fully protected across two zones. Some genuinely need a third. And for a growing number, Azure manages zone redundancy for you, and the best decision is to let it. This post is about how to tell the difference.

Learn architecture strategies for availability zones and regions

What availability zones protect against (and what they don’t)

An Azure region that supports availability zones is made up of separate groups of datacenters, each with independent power, cooling, and networking. Zone resiliency protects you against the loss of one of those zones. It does not protect you against the loss of the entire region. If your workload is mission-critical or carries strict disaster-recovery requirements, zones are necessary but not sufficient: you also need a multi-region conversation, and that’s a separate design exercise.

It’s worth being precise about what “using zones” means, because Azure services expose it in two different ways:

Zone-redundant resources are spread or replicated across zones by Azure itself. Azure handles the replication, request distribution, and failover. Where a service offers zone redundancy and it meets your requirements, it should generally be the starting point, especially for production workloads.

Zonal resources are pinned to one zone. A zonal resource is isolated from failures in other zones, but it is not automatically resilient to a failure in its own. To make a zonal design resilient, you deploy instances across zones yourself and own the routing, replication, failure detection, and recovery.

That distinction matters, because reliability on Azure is a shared responsibility. The resilience of a zone-redundant service is Microsoft’s responsibility to deliver; the resilience of a zonal design you assemble yourself is largely yours to configure and prove. No layer makes up for a gap in another.

Decide at the component level, not the workload level

The reason “three zones everywhere” may not be the correct starting point is that a workload is not one thing. It’s a stateless front end, an application tier, a queue, a cache, a relational database, an object store, and often a quorum-based system or two each with different failure behavior. Applying one zone count to all of them optimizes for none of them.

Break the workload down by critical flow, then by component, and ask three questions of each:

Resource availability: If one zone goes down, can the remaining zone or zones carry the operating state you need? For a single-zone failure, two zones and three zones can both meet the objective. The third zone does not, by itself, make a component resilient to more than one zone failure in the same region.

Data consistency and durability: Does the component’s correctness depend on a third failure domain? Quorum, consensus, leader election, split-brain prevention, and the highest durability targets often do.

Cost and capacity: For the same post-failure performance, recovery capacity is distributed differently across two zones versus three. Decide the resiliency objective first, then optimize cost, not the other way around.

One subtlety worth flagging: If more than one zone is unavailable in the same region at once, your problem has usually stopped being a workload problem and become a regional one: foundational regional services themselves depend on surviving zones. Designing past a single-zone failure puts you in disaster-recovery territory, which is a different conversation.

A starting point: Where common components tend to land

Most components fall into one of a few buckets. Treat this as a first read, not a support matrix. Zone behavior varies by service, SKU, tier, region, and configuration, so always validate against the service’s own reliability guidance.

Component typeTypical zone decisionStateless compute, application, or network components (no persistent data)Two or three zones, based on remaining capacity, routing, latency, and operations. Both can meet a single-zone objective.Stateful systems using quorum, consensus, or leader electionThree zones, a third failure domain, or a product-specific witness pattern to avoid split-brain and quorum loss.Critical data stores needing three replicas for the highest durability targetsThree-zone replication is often required to reach the intended durability level. Validate the service’s specific claims.Other stateful resourcesTwo-zone, three-zone, or service-managed, depending on recovery time objective (RTO), recovery point objective (RPO), durability, and failover behavior.Anything Azure can make zone-redundant for youUse service-managed zone redundancy when it meets your requirements.

Where two zones are enough

Two zones is not a compromise. For many components it’s simply the right answer: fully meeting a single-zone failure objective while being simpler to deploy, test, and operate. Two zones tend to be enough when:

The component is stateless or easily replaced, and traffic can shift to the surviving zone.

An active-active or active-passive pair is easier to reason about and operate.

A latency-sensitive synchronous path performs within budget on a tested zone pair.

A customer-managed zonal design has validated capacity, failover, monitoring, recovery, and failback.

The component can run in an approved degraded state after losing a zone.

Whichever you choose, define exactly what happens when a zone goes away: remaining capacity, acceptable degradation, data consistency, failover behavior, recovery steps, observability, and who owns each of them.

Where three zones earn their keep

Three zones are required when two cannot meet the component’s needs during or after a single-zone failure. In practice that’s usually one of:

A post-failure operating state the remaining zone in a two-zone design simply can’t sustain

Durability or replication that depends on placement across three zones: triple-replica placement for the highest durability targets

Quorum, consensus, or leader-election designs that need a third failure domain or witness to avoid losing quorum or splitting brain.

A caution that trips up even experienced teams: three replicas are not the same as three failure domains. Place a majority-quorum system’s replicas across only two zones and you can still lose quorum when the majority-holding zone goes down. Replica count is not replica placement.

Be honest, too, about a middle category. Some components don’t require a third zone but benefit from one for capacity distribution, maintenance flexibility, or operational margin. That’s a legitimate reason to choose three zones. It’s just a different reason than “we’d lose the system otherwise,” and it’s worth writing down which one applies.

The cost conversation comes last

Cost and operational complexity are real, but they belong at the end of the decision, not the start. Don’t let them talk you out of a two-zone design that meets requirements, and don’t let them justify a two-zone design that doesn’t. Counterintuitively, for the same post-failure capacity target, a three-zone design can provision less total capacity than a two-zone one, because the recovery headroom is spread across more zones. Model that tradeoff before you optimize, use commitment-based discounts such as Azure savings plans or Azure Reservations where usage is predictable, and make sure whichever you pick can actually be operated: deployed, monitored, tested, failed over, recovered, and reviewed.

Discover saving plans for compute and databases workloads

Component classification checklist

Run each component through this checklist and confirm that:

Every critical flow is decomposed into the components that support it.

Each component is evaluated for resource availability, data consistency and durability, and cost or capacity impact.

Each component is classified as service-managed zone-redundant, two-zone customer-managed, or three-zone required.

Wherever three zones are required, the specific requirement driving that decision is written down.

Each service’s zone support is validated for the SKU, tier, region, and configuration you’re actually using.

Customer-managed zonal resources have validated routing, load balancing, replication, failover, monitoring, recovery, and failback.

Remaining capacity and acceptable degradation after one zone loss are documented.

Quorum-based components have validated replica placement, witness or tie-breaker behavior, leader election, and split-brain prevention.

Latency-sensitive paths are tested across the actual zone placement they’ll run on.

Security, identity, monitoring, and data-protection requirements are preserved across the design.

Ownership for testing, incident response, failover, failback, and periodic reassessment are assigned.

The discipline is in the details

Zone resiliency isn’t a slider you set once for an entire workload, and it isn’t a number you can copy from someone else’s architecture. It’s a series of deliberate, component-level decisions about how much failure each part of your system has to absorb. The discipline is in making each one on purpose, writing down why, and validating that the design behaves the way you assumed when a zone actually goes down.

Get that right, and “two zones or three?” stops being a debate. It becomes what it should be: an answer you can defend, component by component.

Related resources

Azure services that support availability zones

Enable zone resiliency for Azure workloads

Zonal resources and zone resiliency

What are Azure availability zones

Architecture strategies for availability zones and regions

Design for resilience with Azure Regions and Availability Zones

Learn how to use Azure regions and Availability Zones to improve workload resiliency, reduce downtime, and support business continuity with well-architected deployment strategies.

Explore best practices

The post Two zones or three? A design framework for zone-resilient Azure workloads appeared first on Microsoft Azure Blog.
Quelle: Azure
The future of infrastructure resiliency starts with modernization

Why infrastructure resiliency is essential for modern applications and AI workloads

Organizations today face constant pressure to modernize; business-critical applications are being transformed, AI workloads are becoming foundational to business operations, and infrastructure environments continue to grow in complexity. Yet modernization only succeeds when organizations have confidence that their applications, data, and infrastructure can withstand disruption and continue supporting critical operations.

As organizations adopt distributed applications, AI-powered services, and hybrid and multicloud architectures, the resiliency of their IT estate has become more than a technical consideration, it is a business requirement. Resiliency is the ability of infrastructure and workloads to withstand, adapt to, and recover from disruptions while maintaining critical business operations. Organizations need infrastructure platforms that can help reduce the impact of disruption, maintain workload availability, and support effective recovery when challenges occur.

Learn about resilient cloud applications

At the same time, resiliency strategy is evolving. Historically, organizations often approached resiliency through backups, redundancy, and disaster recovery plans. While these capabilities remain essential, modern resiliency requires a broader approach that spans architecture, operations, recovery, and continuous optimization. Customers increasingly recognize that resiliency is not about preventing every disruption. It is about designing for uncertainty, minimizing operational impact, recovering effectively, and continuously strengthening readiness over time.

At Microsoft, we believe Azure IaaS resiliency is an ongoing partnership and shared responsibility that helps organizations modernize with confidence. Microsoft Azure provides the infrastructure foundation, platform capabilities, and guidance that enable customers to build resilience into workloads from the start, maintain operational continuity as environments evolve, and continuously improve recovery readiness over time.

Resilient by design

Resiliency starts long before an outage occurs.

As organizations modernize business-critical applications, cloud-native services, and AI workloads, resiliency can no longer be bolted on after deployment. The most effective resiliency strategies begin during planning and design, with architectures that align availability, recovery, performance, compliance, and operational requirements to the needs of each workload. Not every application requires the same resiliency strategy, and a one-size-fits-all approach is no longer sufficient. This is especially true for AI and business-critical workloads, where downtime, performance degradation, or data loss can have significant business consequences.

Azure helps organizations build resiliency into infrastructure from the start through availability zones, resilient networking architectures, durable storage options, recovery services, and proven guidance from the Azure Well-Architected Framework and Azure Architecture Center.

The recently announced Azure Infrastructure Resiliency Manager extends this foundation by helping organizations define resiliency goals, understand workload criticality, identify gaps, and evaluate resiliency posture at the application level. Rather than relying on manual reviews and static assessments, organizations can continuously understand how workloads align to resiliency objectives and where improvements may be needed.

Explore Azure Infrastructure Resiliency Manager

To further simplify resiliency adoption, Azure Infrastructure Resiliency Manager provides recommendations, deployment guidance, and AI-assisted experiences through the resiliency agent in Azure Copilot. Teams can describe workloads, generate resilient deployment templates, assess existing environments, and receive recommendations aligned to their resiliency goals. This helps organizations embed resiliency earlier in the lifecycle and reduce the effort required to operationalize best practices.

The goal is simple: make resiliency part of how applications are designed, not something organizations revisit only after a disruption has occurred.

Innovate without interruption

Modernization is not a one-time project. Applications evolve, new services are introduced, new dependencies emerge, and infrastructure environments continuously change.

As environments evolve, resiliency must evolve with them.

One of the most common challenges organizations face is maintaining operational continuity while introducing change. New deployments, configuration drift, scaling requirements, infrastructure updates, and evolving application architectures can gradually move workloads away from their original resiliency objectives. What was resilient six months ago may no longer meet current availability or recovery requirements.

This is why resiliency is becoming a continuous operational practice rather than a one-time design exercise. Organizations increasingly need visibility into resiliency posture, the ability to prioritize remediation efforts, and mechanisms for validating whether workloads continue to meet business objectives as they grow and change. Azure Infrastructure Resiliency Manager helps organizations continuously assess resiliency posture, identify high-priority gaps, and increase uptime through recommendations, operational guidance, and application-centric resiliency management.

Azure is also embedding resiliency more deeply across the infrastructure stack, enabling the platform to respond to certain component-level disruptions while helping unaffected resources continue operating. This increasingly self-healing approach can reduce the blast radius of isolated failures and help maintain continuity as infrastructure conditions change.

Per-disk resiliency for Azure Managed Disks, now available in public preview in select regions, illustrates this approach at the storage layer. Traditionally, when a virtual machine lost connectivity to an attached managed disk for an extended period, Azure recovered the virtual machine after connectivity was restored. With per-disk resiliency enabled, Azure can temporarily take only the affected data disk offline while allowing the virtual machine and its remaining disks to continue operating. After connectivity is restored, Azure automatically reattaches the disk.

For workloads that can tolerate the temporary loss of an individual data disk, including clustered applications, workloads using auxiliary disks, and certain containerized architectures, this approach can help reduce the impact of isolated storage disruptions and allow critical workload operations to continue. It reflects a broader trend in cloud resiliency: reducing the blast radius of failures and helping organizations continue innovating even when individual infrastructure components encounter issues.

Improve workload availability with per-disk resiliency

Recover with confidence

No organization can prevent every disruption.

The measure of resiliency is not whether disruption occurs. It is how effectively organizations prepare for, respond to, recover from, and learn from those events.

Historically, recovery planning was often treated as a periodic exercise. Today, leading organizations recognize that recovery readiness must be continuously validated. Recovery plans that have never been tested may not perform as expected during an actual disruption.

Azure helps organizations improve recovery readiness through integrated backup, disaster recovery, monitoring, and resiliency management capabilities. Organizations can define recovery objectives, validate failover strategies, monitor recovery performance, and continuously improve resiliency posture over time. Azure Infrastructure Resiliency Manager and Azure Chaos Studio extend this process by helping teams test recovery plans under controlled conditions, validate failover procedures, identify hidden dependencies, and measure recovery outcomes against defined objectives before a real disruption occurs.

A configuration that looks resilient on paper still has to withstand a real failure. Azure Chaos Studio helps organizations simulate outage conditions and validate how applications respond. From availability zone failures and database failovers to DNS and Microsoft Entra disruptions, teams can safely test assumptions, verify recovery procedures, and build confidence that their resiliency strategies will perform as intended. Guided drills, automated cleanup, and audit-ready reporting help transform resiliency validation into an ongoing operational practice rather than an infrequent event.

Recovery confidence also depends on protecting data and preparing for increasingly sophisticated cyber threats. Infrastructure failures are only part of the resiliency equation. Organizations must also plan for accidental deletion, data corruption, ransomware, and compromised credentials.

Azure Backup helps organizations improve recovery readiness with built-in capabilities that protect backup data, support cyber resilience, and simplify recovery. Features such as immutable vaults, soft delete, multi-user authorization, and recovery orchestration help organizations preserve clean recovery points and restore critical workloads with confidence.

When recovery involves a cyberattack rather than an infrastructure failure, trust becomes just as important as speed. Capabilities such as immutable vaults, multi-user authorization, and isolated recovery experiences help organizations identify trusted recovery points and restore operations without reintroducing compromised data or configurations.

The future of resiliency is not simply recovering faster. It is enabling organizations to build resilient foundations, operate with confidence as environments evolve, and continuously strengthen recovery readiness over time.

Modernize confidently with help from the Azure IaaS Resource Center

See Azure resiliency capabilities in action

Join Microsoft’s Azure webinar series “Minimize downtime with resilient cloud applications” episode on September 17 at 10:00 AM PT, where Azure resiliency experts will demonstrate how organizations can build resilient architectures, assess resiliency posture, validate recovery readiness, and strengthen recovery outcomes using Azure Infrastructure Resiliency Manager, Azure Backup, Azure Site Recovery, Azure Chaos Studio, and the Azure Copilot Resiliency Agent.

Minimize downtime with resilient cloud applications

Learn strategies to improve application resilience, reduce downtime, and maintain business continuity in the cloud.

Register for webinar

The post The future of infrastructure resiliency starts with modernization appeared first on Microsoft Azure Blog.
Quelle: Azure
The Economics of Agent Optimization: How AI agent governance controls cost and proves ROI

This blog post is the fourth and final installment of The Economics of Agent Optimization, which shares the strategies, capabilities, and proof points that can help you optimize agent costs and run AI as a managed investment system on Microsoft Foundry. The first post set out the three decisions that systems rest on, the second post took the request at runtime, and the third post took the workflow over time. This post takes the decision that never stops running: governing the spend.

AI agents are moving from isolated pilots into an enterprise estate. They work across teams, connect to data and tools, and make decisions with varying degrees of autonomy. For IT leaders, that creates a broader operating question: how do you govern a agentic system that can grow and act faster than traditional applications?

AI agent governance starts with knowing which agents exist, who owns them, what they can access, and which policies apply. It is often discussed in terms of security, compliance, and lifecycle management. It is also fundamental to cost optimization. Without consistent governance, each team makes its own choices about models, tools, capacity, and limits—and small inefficiencies multiply across every agent and every turn.

Good governance makes consumption visible, attributable, and bounded. IT needs to see which agents and teams are driving usage. Finance needs budgets and cost allocation it can trust, without discovering an unexpected increase after the invoice closes. Developers need controls that can respond at the speed agents run.

That last requirement exposes an important distinction. Traditional cost management tools can track spending and alert on actual or forecasted costs, but they typically operate on billing data rather than in the request path. An agent caught in a retry loop does not wait for the next budget evaluation.

A budget alert is a smoke detector. An agent also needs a circuit breaker. Effective cost governance therefore depends on three things: seeing the spend, bounding it, and proving the return.

See the spend where it starts

AI costs become difficult to manage when they arrive as one aggregate number. One deployment may serve several agents; one agent may use several models and tools; and one outcome may require many turns. By the time that appears on an invoice, the business context has disappeared.

Cost management capabilities in Foundry brings that context closer to the systems creating it. Teams can see estimated costs across projects, inspect cost and token usage for individual agents, and monitor model costs. These estimates support operating decisions; Microsoft Cost Management and invoiced charges remain the system of record for financial reconciliation.

Foundry also supports project-level cost attribution. Every Foundry project is automatically associated with a project tag on its underlying usage. FinOps teams can filter Cost Analysis by that tag to allocate spending to the business unit, team, or workload that incurred it. This capability is currently in preview for models sold by Microsoft Azure, including Azure OpenAI.

At the gateway, Azure API Management’s AI Gateway can emit token metrics by API, product, user, subscription, gateway, and backend. Tracing in Foundry captures tool usage, retries, latency, token consumption, and costs for an agent run.

Together, observability signals explain not only how much an agent consumed, but why:

Traces reveal model calls, tool invocations, retries, latency, and token usage.

Monitoring surfaces production trends and anomalies.

Evaluations measure quality, safety, groundedness, and task completion. Run continuously, they give teams evidence to test whether a smaller model still meets their quality bar rather than defaulting to the largest one. Safety evaluators can also flag issues such as prompt injection, sensitive data leakage, and harmful content before they reach production, where remediation can be costly.

Viewed together, these signals help teams understand whether rising costs are driven by customer demand, inefficient agent behavior, quality regressions, or architectural issues.

That context turns cost data into actionable governance. Before teams can set limits or measure ROI, they need to understand how agents behave in production.

Set spend limits at every layer

Visibility tells you where the money went. Limits determine whether it can keep going. There are three layers to the control system, each working at a different scope and speed:

1. Enforce limits in Foundry

With AI Gateway configured, Foundry Control Plane can enforce tokens-per-minute rate limits and total token quotas for model deployments at the project scope. A request that exceeds the rate limit receives a 429 Too Many Requests response. A caller that exhausts its token quota receives a 403 Forbidden response.

Unlike a cost alert, enforcement happens in the request path. Teams can contain one project’s consumption before it monopolizes shared capacity and establish different boundaries for different projects. Quotas can operate over hourly, daily, weekly, monthly, or yearly periods. Teams can configure the Azure API Management-backed gateway and manage its token limits through Foundry Control Plane.

2. Apply policy across models and providers

For controls spanning projects or model providers, the llm-token-limit policy limits consumption per key using a rate, a cumulative quota, or both. The key can represent a subscription, application, team, customer, workload identity, or another business boundary.

AI Gateway applies the same governance model across OpenAI-compatible APIs, the Anthropic Messages API, as well as MCP servers and agent-to-agent APIs. Backend load balancing can prioritize provisioned capacity before spilling over to pay-as-you-go deployments, while circuit breakers can temporarily stop sending requests to a failing or throttled backend.

Like any distributed limit, these controls have boundaries. Counters are maintained independently at each gateway, and concurrent requests can create a small temporary overage because final token consumption is known only after responses return. The goal is to replace unbounded consumption with a predictable operating boundary.

3. Use financial budgets for accountability and escalation

Microsoft Cost Management budgets serve a different purpose from token limits. They use Azure billing data, including actual prices, credits, and purchasing commitments, to give finance and IT an authoritative view of what the organization has spent and is forecast to spend.

Teams can set budget thresholds and notify owners when actual or forecasted costs approach them. They can also connect a budget to an Azure Monitor action group, which can invoke a customer-designed workflow such as opening a ticket, notifying an operations team, or starting a Logic App or automation runbook. Cost anomaly detection provides another warning when spending departs from its historical pattern.

These are valuable accountability and escalation tools, but they are not instant spending caps. They respond to billing data after consumption occurs. Token limits operate earlier, in the path of each model request, where they can reject new calls after a rate limit or quota is reached. Organizations need both: token limits to contain consumption as agents run, and financial budgets to keep owners accountable and prevent finance from being surprised.

Today, these two layers use different units. The platform enforces consumption in tokens, while finance plans and allocates investment in dollars. Because token prices vary by model and offer, a token quota does not translate into one stable dollar amount.

We are actively working to close that gap with future capabilities in Microsoft Foundry and the AI Gateway in Azure API Management that bring dollar-denominated budgets, finer-grained attribution, and policy-driven controls closer to where agents run.

Measure the value the agent creates

Putting a ceiling on consumption solves only half of the governance problem.

While cost controls can help organizations manage spending, they do not answer a more important question: is the agent delivering enough business value to justify that investment?

The least expensive agent is not necessarily the best investment. An agent that costs more but resolves substantially more cases may deserve additional capacity. An inexpensive agent that rarely completes its task may not. Governance therefore needs a second unit alongside tokens and dollars: business outcomes.

This is ultimately an ROI problem. Organizations want to understand whether their agents are creating more value than they cost. However, connecting business outcomes to the underlying cost of running an agent can be difficult.

ROI for agents in Foundry, currently in private preview, helps organizations connect agent costs to business outcomes. Teams define the outcomes they want to track, such as successful task completion, customer satisfaction, or case deflection. They then assign a business value to those outcomes and define how success should be measured. Foundry tracks which outcomes an agent achieves, and the model and tool costs incurred along the way, calculating:

Value generated: The total value attributed to successful business outcomes.

Total cost: The model and tool costs incurred to achieve those outcomes.

Net value: The value remaining after costs are subtracted.

ROI: The return generated relative to the investment required.

The dashboard shows daily trends and separates models from tool costs. Teams can compare agent versions using average value per conversation, pass rate, and improvement percentage. That makes optimization decisions defensible in business terms: not merely “the new version uses fewer tokens,” but “the new version produces more net value.”

The ROI feature also connects the business view to engineering evidence. Teams can inspect the lowest-ROI conversations and traces to find an oversized model, repetitive tool calls, or a workflow consuming tokens without producing meaningful outcomes. Because ROI is connected to observability data, teams can move directly from a business metric to the traces, evaluations, and operational signals that explain what is driving cost, quality, and business outcomes.

A low-ROI trace can point to a request that should be routed differently, context that should be removed, or an agent configuration that should be optimized. The same telemetry used to improve quality and efficiency can now help organizations answer the question the business ultimately asks: is this agent worth what it costs?

Run AI as one managed investment system

Together, the four posts in this series describe one optimization system operating at three speeds. At runtime, model routing, deployment choices, and caching right-size each request. Over days and weeks, context engineering, memory, tools, and agent optimization improve the workflow. Continuously, governance attributes consumption, enforces limits, and measures whether the portfolio is creating value.

The same evidence connects every layer, and answers different questions:

Traces show what an agent did on a run, exposing expensive requests and inefficient context.

Evaluations show whether the output was good, protecting quality as configurations change.

Cost attribution shows where the money went, pointing to the project, agent, or model to intervene on.

ROI shows whether the work was worth it, telling leaders whether to optimize an agent, give it more capacity, or retire it.

Cost is only one part of a much bigger governance story, and it helps to be clear about who owns which part.

Foundry is built for developers creating agents. It’s where developers build, test, and optimize, and Foundry Control Plane gives them an operating view of everything they’ve shipped, from cost trends and anomalies to token usage and lifecycle controls, with Azure Policy, Microsoft Defender, and Microsoft Purview woven in so compliance and security aren’t an afterthought.

Microsoft Agent 365 is built for the people responsible for the entire enterprise estate. IT administrators and security teams use it to discover, inventory, secure, and manage every agent in the tenant, whether it came out of Foundry, Microsoft 365, or a partner platform, and to extend the same identity, access, and data protections to agents that they already apply to people.

The FinOps capabilities we’ve covered in this series live on the Foundry side of that line, giving developers and platform teams the levers to keep spend predictable, while IT and security govern the estate around them in Agent 365.

Agent optimization isn’t about driving the cost of every request to zero. It’s about running agents with the same discipline you’d apply to any other serious investment, and that is what Foundry is built for: helping developers build and manage agents that are efficient by design, contained as they scale, and accountable for the value they create.

Get started

If you’re governing agents today, start by making their consumption visible and attributable. Identify which agents and teams are driving usage, apply request-time limits to contain unexpected consumption, and pair those controls with financial budgets and alerts. Then connect cost to business outcomes so you can decide which agents to optimize, scale, or retire.

Enforce token limits for model deployments in Microsoft Foundry.

Plan, monitor, and allocate AI costs in Microsoft Foundry costs.

Create budgets and alerts in Cost Management.

Explore AI Gateway governance capabilities in Azure API Management.

Learn about observability and ROI for agents in Foundry.

Microsoft Foundry

The enterprise AI platform to build, ground, and govern AI apps and agents at scale.

Start managing agents

Did you miss these posts in The Economics of Agent Optimization series?

AI cost management: From AI pilots to measurable ROI

AI cost optimization: How to lower AI spend

AI agent optimization: How context engineering lowers AI costs

The post The Economics of Agent Optimization: How AI agent governance controls cost and proves ROI appeared first on Microsoft Azure Blog.
Quelle: Azure
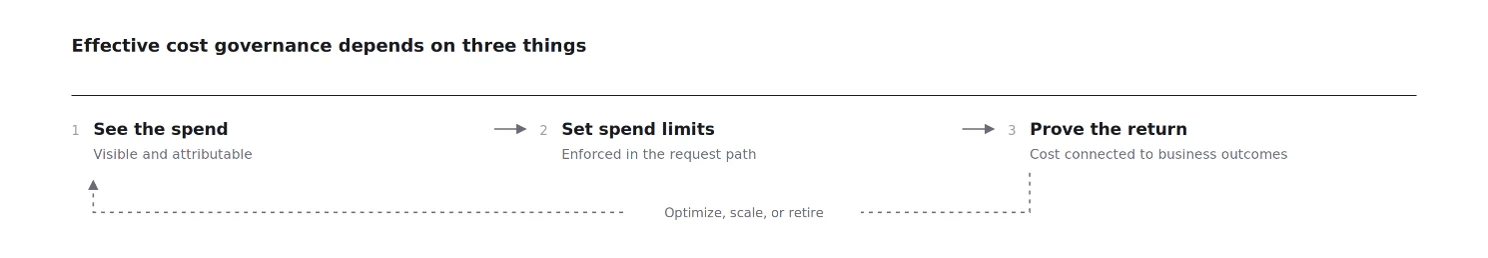
Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management

I am pleased to share that Microsoft has been named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management, positioned furthest to the right on Completeness of Vision. We believe this recognition reflects our ability to help customers modernize existing applications and embrace AI workloads without adding operational complexity.

Furthermore, this recognition comes at a moment when container platforms are being asked to support a far broader range of workloads, operating models, and deployment environments than many organizations ever anticipated.

Read the Gartner® Magic Quadrant™ Report

When we started working on Kubernetes over a decade ago, the problem was narrow: democratize distributed systems so that reliable services were easier to build. We were careful to describe workloads in terms of what they needed instead of where they should go, mostly because we wanted the scheduler to have room to make good decisions. That turned out to matter more than we expected, because it meant the system never had strong opinions about what the workloads actually were.

AI has reshaped the requirements for container management. While Kubernetes has proved well suited for AI workloads, the bigger shift is that applications and AI now need to run closer to data and users, and increasingly inside specific sovereign and regulatory boundaries. Organizations now need more than container orchestration; they need a platform that provides a consistent operating model across cloud, edge, and hybrid deployments while adapting to new requirements without needing applications to be rebuilt. This vision underpins Microsoft’s container portfolio, spanning Azure Kubernetes Service (AKS), Azure Container Apps, Azure Arc, and Azure Kubernetes Fleet Manager..

Run AI on the platform you already operate

Across customer deployments, we’ve seen it settle into two distinct architectural models. In the first, a platform team owns a persistent serving layer, GPU scheduling, model lifecycle, and the compliance boundary around the system. Once volume is high and predictable, organizations increasingly want AI infrastructure to behave like any other platform capability: application teams consume it, while platform teams retain control over how it is operated and governed. On AKS, open-source tooling such as the AI toolchain operator helps automate model deployment and GPU provisioning, while AKS holding CNCF AI Conformance certification gives customers confidence that the ecosystem around their applications remains compatible as it evolves.

In the second model, an application or agent invokes inference when needed, runs generated code, and releases capacity when the work finishes. This model places a premium on elasticity and isolation. Capacity needs to appear quickly, be removed when it’s no longer needed, and safely contain workloads whose behavior isn’t always predictable in advance. Azure Container Apps is designed around that operating model, with serverless GPUs for on-demand inference, and hardware-isolated sandboxes for agent hosting that preserve state between interactions.

Almost every enterprise we work with needs both, and I’d argue the interesting engineering problem is making the boundary between them easy to cross: the same image, the same identity and network controls, the same policy, whichever side a team lands on. Platform teams want the control the first model gives them for the models the business depends on. Application teams and agent frameworks want the second, and they often want it without learning Kubernetes.

Keep one operating model as the estate spreads out

Once inference follows the data, the estate stops being centralized. Clusters accumulate across regions, in datacenters, at sites, and in environments where connectivity is intermittent or prohibited outright, often because sovereignty rules require the workload and its data to stay inside a jurisdiction. The resulting failures are usually coordination failures rather than single-cluster failures: configuration drift between locations, upgrades landing unevenly, and policy being applied in one environment but not another. Hybrid strategies can often fail when teams treat coordination problems as isolated cluster issues instead of platform problems.

We know that AI needs to spread from cloud to edge. To address that, we’ve built AKS Everywhere to enable a consistent, Azure-built and secured Kubernetes platform from cloud to edge. Going even broader, with Azure Arc for Kubernetes we extend a common identity, policy, and observability model across CNCF-conformant Kubernetes environments, including clusters in other clouds. With many clusters comes cluster sprawl, and Azure Kubernetes Fleet Manager addresses the coordination problem that emerges as estates grow, helping organizations manage upgrades, workload placement, and policy consistently across fleets.

Holding all of that together depends on AKS staying close to upstream Kubernetes, and we’ve kept it there deliberately. There’s no proprietary fork, and open-source is at the core of our strategy. Microsoft is the second-largest contributor to CNCF projects overall and the largest among cloud providers for the past three years. That work is what keeps the API you build against stable no matter where the workload lands, and why the ecosystem around your cluster looks the same inside Azure and outside it.

Hold operations steady as the estate grows

Cluster counts often grow faster than operations teams do, and most organizations feel that pain before they have a plan for it.

Some of the answer is better defaults. AKS Automatic applies operational practices derived from Microsoft’s experience running Kubernetes at scale, while preserving the flexibility of the Kubernetes API.

The larger shift, however, is agentic operations. I expect this area to change more than any other over the next few years. Azure SRE Agent and the AKS MCP Server help operators move from alert to diagnosis to remediation using the same permissions and controls they already use today. The goal isn’t to replace operators; it’s to reduce the amount of routine investigation that still consumes too much operational time.

A platform built to absorb new requirements has more surface area than one built for a single scenario, and that demands more judgment from the people running it. Our job is to keep pulling that complexity into the platform, and the work is not finished.

Customer momentum

These examples highlight how customers are applying Azure’s container portfolio across AI, business-critical applications, and hybrid environments.

Wayve trains its autonomous driving models on petabytes of video and sensor data, using AKS to pull thousands of GPUs into what amounts to a single elastic training system.

AT&T built Ask AT&T with AKS as the orchestration core for its containerized agents, and every agent clears legal, security, and finance review before it reaches production.

Replit‘s agent takes a plain-language description, writes the application, and deploys it as a Container App inside the customer’s own Azure environment, where it picks up that customer’s network and compliance controls from the first deployment onward. Roughly three-quarters of their enterprise users don’t write code for a living.

SimCorp moved the investment management platform behind many of the world’s largest asset managers from virtual machines onto AKS, driven by the need for identity, logging, and security policy to apply identically for every client in every jurisdiction, and to be auditable when someone asks.

Emirates Global Aluminium runs about two-thirds of its estate in Azure and a third on-premises at its own sites, with image and video analytics running next to the plant floor and applications moving between the two without being re-engineered.

A training cluster spanning thousands of GPUs has very little in common with a regulated multi-tenant SaaS platform or with analytics running beside a smelter. What connects them is that each one eventually needed something its original architecture wasn’t built for.

Azure Kubernetes Service gives us the control and cost efficiency we need. We can scale GPU resources based on call volume and test new models without touching production.
Brian Sutliffe, Vice President of Engineering, CallRevu

Being named a Leader in this Magic Quadrant is an honor for us, and it solidifies clear expectations for our work ahead. At the end of the day, only the team running a workload can decide where it belongs, and the answer will vary across an estate. The platform’s role is to let that answer change without forcing the team to redesign the application or adopt a second operating model. I also want to personally thank all of Azure Cloud Native since this recognition reflects a lot of hard work by many people throughout Microsoft and Azure.

You can read a complimentary copy of the 2026 Gartner® Magic Quadrant™ for Container Management here.

Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management

Read the report

Gartner ® Magic Quadrant™ for Container Management, Dennis Smith, Tony Iams, Wataru Katsurashima, Lucas Albuquerque, 2 September 2026

Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.

Gartner and Magic Quadrant are trademarks of Gartner, Inc., and/or its affiliates.

This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request here.

The post Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Container Management appeared first on Microsoft Azure Blog.
Quelle: Azure
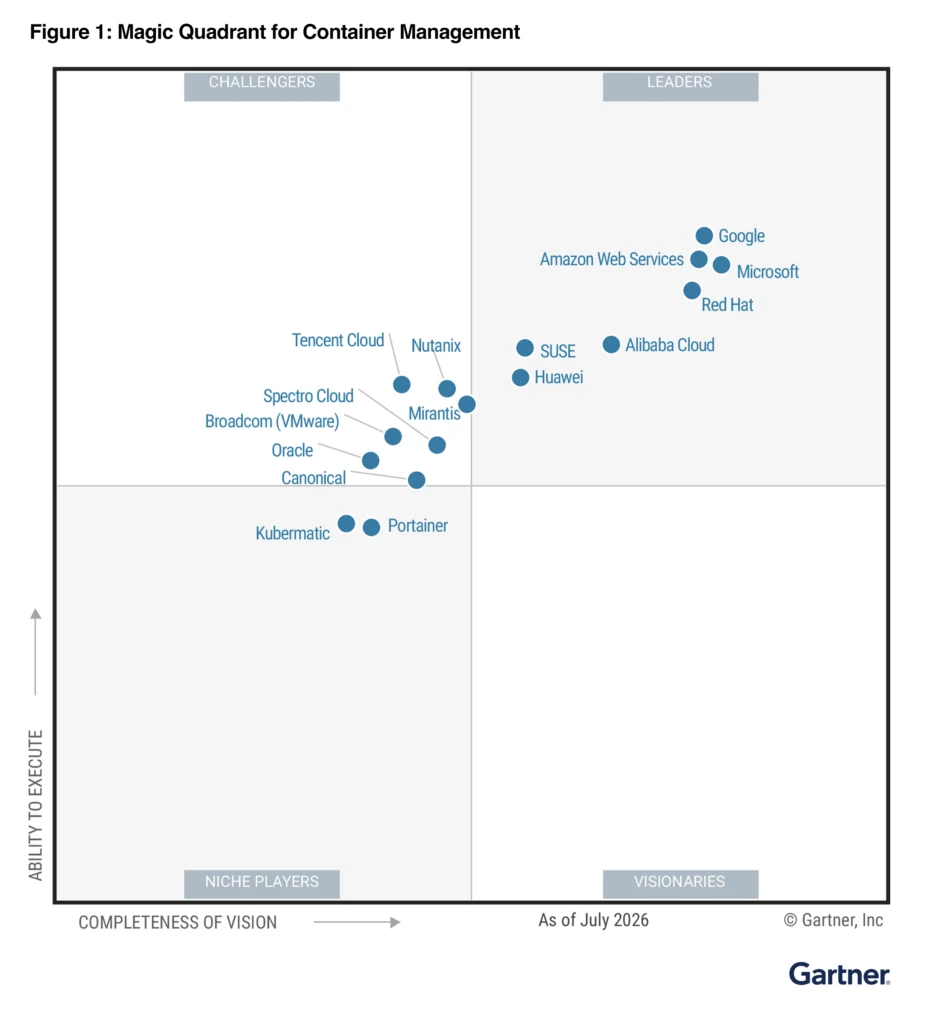
Beyond the benchmark: How an adaptive approach drives scientific discovery

For research and development (R&D) organizations, the promise of agentic AI is not a better one-time answer. It is a new way to explore complex scientific and engineering problems: pursuing multiple hypotheses, validating them against evidence, learning from what does not work, and adapting their approach as new information becomes available.

This unique nature of the agentic discovery process has been a core area of research for Microsoft, and a design principle for Microsoft Discovery, our platform for organizations embracing Frontier R&D.

Learn how Microsoft Discovery explores science

Measuring adaptive AI for scientific discovery

A new benchmark result shows how that opportunity is becoming real. On Agent’s Last Exam, a demanding evaluation of long-running, tool-using professional tasks, Microsoft Discovery Engine with CLIO (Cognitive Loop via In-Situ Optimization) achieved higher scores than the other agentic harnesses evaluated across three scientific domains: 61.6% in health and medicine, 75.2% in physical sciences, and 64.6% in life sciences.

This result builds on Microsoft’s core research into what makes agentic discovery distinctive. CLIO enables independent reasoning paths to explore a problem, compare and share learning, and resolve the strongest trajectory into a single evidence-backed result. The system can determine when to keep exploring, change strategy, use a different model, or bring a domain expert into the loop.

The CLIO benchmark blog post describes this adaptive reasoning approach in depth. More broadly, this core innovation for scientific discovery, powered by agentic AI, is available to R&D organizations in every industry and the scientific community with Microsoft Discovery not only as a research breakthrough, but as a foundation for real R&D work.

Explore Microsoft Discovery

Why scientific discovery requires adaptive reasoning

Many of the hardest scientific and engineering challenges do not have a clearly defined workflow or a known answer. A researcher may need to navigate incomplete evidence, competing objectives, specialized tools, and changing constraints. A materials team may be balancing performance, safety, cost, and manufacturability. A life sciences team may need to connect literature, proprietary data, models, and experimental evidence before deciding what to validate next. An engineering team may need to search a vast design space without sacrificing physical fidelity or traceability.

In these settings, a single model response is not enough. Practitioners need systems that can reason over time, preserve evidence, challenge assumptions, and work within the tools, data, governance, and review processes their experts already use. Just as importantly, they need to understand how a conclusion was reached and where human judgment should enter the process.

Microsoft Discovery was designed as an enterprise platform for agentic R&D, combining the scientific mindset of hypothesis, experimentation, and refinement with the engineering rigor of problem decomposition, structured execution, and reproducibility. CLIO strengthens that foundation with a more adaptive reasoning loop and a diverse model ecosystem, while allowing researchers to use a diverse model ecosystem and multiple reasoning paths.

Try Microsoft Discovery app

From benchmarks to real-world impact

The greater opportunity extends beyond benchmark rankings into real research environments. Discovery Engine with CLIO has already supported work that discovered a novel organic redox flow battery. The same approach has potential across design simulation (like for silicon chips), formulation and process optimization (for example in manufacturing and CPG), materials and molecular discovery (which can drive sustainability and drug discovery), and lab automation, areas where organizations need to shorten research cycles, without sacrificing rigor or traceability.

Agentic discovery does not replace scientists and engineers. It expands what they can explore, helps them learn faster from evidence, and gives them a more systematic and transparent way to move from an idea toward an outcome that experts can evaluate and validate.

Realizing the enormous opportunity to redefine R&D requires a platform built for the tools, data, governance, and review processes researchers already use. Microsoft Discovery was designed with that need in mind: to bring agentic discovery to researchers and scientists in R&D organizations across every industry and throughout the scientific community.

We are still early in this journey, but this benchmark milestone demonstrates what becomes possible when AI is built for the way discovery actually happens: iteratively, collaboratively, and adaptively. I look forward to seeing what organizations, researchers, and partners discover next.

Adaptive AI for scientific discovery

Learn how Microsoft Discovery uses adaptive, agentic approaches to explore complex scientific and engineering challenges, helping R&D teams accelerate innovation and uncover new possibilities.

Read the blog

The post Beyond the benchmark: How an adaptive approach drives scientific discovery appeared first on Microsoft Azure Blog.
Quelle: Azure
GPT-6 Astra: Frontier intelligence for work, now generally available in Microsoft Foundry

The next era of enterprise AI will not be defined by chat experiences. It will be defined by how well a model can work for and with you. GPT-6 Astra, OpenAI’s newest frontier model, is now generally available for all customers in Microsoft Foundry. It is designed to help organizations make decisions for complex work and execute across the applications and systems where your business operates.

We are investing to make it easier for customers to use advanced technology like Astra. AI initiatives often slow down on identity, networking, governance, data handling, evaluation, and compliance. Microsoft Foundry brings these fundamentals together in Azure, helping teams move from experimentation to production with speed and trust.

Turn open-ended goals into action

Astra is built to take an open-ended challenge, reason through it in multiple steps, create a plan, and produce a polished result. It can weigh trade-offs, incorporate new direction as work progresses, and use tools across applications and systems. 

For enterprises, this shifts AI from conversational assistance toward delivering more substantial units of work:

Deliberate planning and decision support. Astra can break a challenge into steps, evaluate options, communicate its recommendation, and identify the next actions for review.

Polished, purposeful output. Astra can apply context, templates, and quality standards throughout a workflow, helping produce documents, spreadsheets, presentations, and analyses that are ready for review.

Execution across applications. With advanced tool use and computer use, Astra can interact with software on a person’s behalf, move between apps, and complete multi-step tasks with appropriate human oversight.

At Replit, our mission is making useful intelligence accessible to everyone. GPT-6 Astra available through Microsoft Foundry unlocks a new level of agentic capability that goes beyond code generation to active software creation and more. We’re excited about the opportunities created for developers and entrepreneurs to build more ambitious applications with an intelligent software-building partner.
—Luis Hector Chavez, CTO, Replit

Computer use across applications

Astra’s computer-use capabilities are designed to work across familiar applications, including workflows without dedicated APIs. It can interpret on-screen information and interact with approved interfaces to support tasks such as updating records, navigating development tools, testing software, and assembling results into reports. OpenAI reports state-of-the-art results on selected computer-use evaluations; performance varies by task, tools, configuration, and safeguards.

Capability this direct demands containment. Content displayed in an application may be incomplete, misleading, or designed to influence an agent’s behavior. Foundry helps customers define access, approvals, and monitoring, and design workflows with scoped credentials, approved resources, human checkpoints for consequential actions, and activity records aligned to their risk requirements.

Enterprise scenarios we’re seeing

Software engineering: Astra can reproduce complex bugs, investigate likely causes, propose fixes, and prepare changes for developer testing and review.

Business intelligence: Astra can build and refine dashboards in Power BI, helping analysts compare data, identify trade-offs, and prepare insights to share.

Professional work: Astra can produce documents, spreadsheets, and presentations that follow existing templates and business standards, creating polished artifacts for expert review.

Application workflows: Astra can support tasks such as updating customer records, processing forms, testing websites, and working through approved interfaces where dedicated APIs are limited. 

Enterprise controls for agentic work

OpenAI describes Astra as its most aligned model to date and plans to publish supporting alignment, safety, and computer-use evaluations in its supporting launch materials. Foundry complements that model-level work with enterprise security, safety, and compliance capabilities, including Microsoft Entra identity and access management, encryption in transit and at rest, private networking options, role-based access controls, content filtering, safety evaluations, monitoring, and governance tools.

Prompts and outputs are not used to train the models. These capabilities help customers configure safeguards and maintain oversight, but do not eliminate risk or replace each organization’s responsibility to select and configure controls appropriate to its scenarios and regulatory obligations.

At Albertsons Companies, we believe the real advantage in frontier AI is the ability to evolve as quickly as the technology does, without compromising enterprise discipline. That means creating an environment where we can evaluate new capabilities, put the right ones to work quickly and maintain consistent security, governance and operational controls as we scale. Azure OpenAI on Microsoft Foundry helps us create that balance of speed and control, so our teams can stay focused on delivering meaningful outcomes for our customers, associates and the business.
—Anirban Nandi, VP, Data and AI, Albertsons Companies

Global scale with service level to match

GPT-6 Astra is available in Foundry models with Standard and Provisioned Throughput deployment options, in both Global and US Data Zone geographies. Standard provides pay-as-you-go flexibility for variable demand, while Provisioned Throughput provides dedicated model-processing capacity for workloads requiring consistent latency and guaranteed throughput. Customers can choose the right deployment based on workload requirements.

Astra is designed for token efficiency on complex work, helping customers manage consumption as they scale. Actual usage and costs will vary by workload and configuration.

GPT-6 Astra pricing*

Deployment Context Length Pricing (USD $/million tokens) Input Cached Input Cached Writes Output Standard Global Short context $10.00 $1.00 $12.50 $50.00 Long context $20.00 $2.00 $25.00 $75.00 Standard Data Zone (US) Short context $11.00 $1.10 $13.75 $55.00 Long context $22.00 $2.20 $27.50 $82.50 Provisioned Throughput pricing varies by deployment type. U.S. Data Zone Provisioned Throughput is priced at a 10% premium to Global Provisioned Throughput. For current rates and terms, see the Azure OpenAI pricing page.

Get started today

Explore the model: Try GPT-6 Astra in Foundry Models to see its advanced capabilities firsthand.

Build agentic workflows: Start with the Foundry Agent Service to bring cross-application task execution to your workflows.

Try GPT-6 Astra today

Explore the model and start building agentic workflows.

Learn more

The post GPT-6 Astra: Frontier intelligence for work, now generally available in Microsoft Foundry appeared first on Microsoft Azure Blog.
Quelle: Azure