In this article
Introducing Rayfin: From prompt to production backendMicrosoft Databases, designed for AI applicationsBuilding an AI‑ready data foundation with Microsoft FabricWatch these announcements from Microsoft BuildExplore additional resources for Microsoft Fabric
AI is driving a fundamental shift in how work gets done and how applications are built. As the 2026 Microsoft Work Trend Index Report highlights, a growing share of workers are moving beyond asking questions to handing off entire tasks and orchestrating multi-agent systems.
This shift introduces a new constraint. The challenge is no longer model capability, but consistent, shared data context across the business.
Developers and business users know what they want to automate, and today’s models can deliver. The bottleneck is context. Every new agent starts from zero, relearning how the business works, where data lives, and what rules to follow. Without a consistent foundation, agents can’t coordinate or scale.
That’s the challenge we are solving with Microsoft Fabric. It provides a unified data and AI platform that empowers you to bring together data and move from isolated AI experiments to production-ready agent systems, in which each new agent builds on shared organizational context. This vision is already driving strong momentum among the millions of developers building on Fabric and Microsoft Databases.
At Microsoft Build, we are extending this foundation with new capabilities that help developers move from prototype to production faster. These include Rayfin, a new software development kit (SDK) and command-line interface (CLI) designed to make Fabric a production-ready application backend, and Azure HorizonDB, a new PostgreSQL database designed for AI‑powered applications, now in public preview.
Unify teams and data with Microsoft Fabric
Introducing Rayfin: From prompt to production backend
Coding agents are accelerating app development. Moving those applications from prototype to production, however, remains a challenge. Agent-created or not, every production-ready application still relies on a backend to manage data, enforce identity and permissions, coordinate state, and operate reliably over time. Existing software-service platforms were either not designed for agents or do not fully meet enterprise requirements for deployment, security, and governance.
Rayfin, a new open-source SDK and CLI, is designed to close that gap. It lets developers and coding agents describe what to build and get an enterprise-grade application backend directly into the application code, including a database, authentication, and more. Rayfin then deploys directly to Microsoft Fabric, giving every application enterprise-grade security and scale from day one. Developers and AI agents can now move from prompt to production without managing infrastructure.
With Rayfin, developers work through familiar GitHub‑based workflows to define data models, backend logic, and access policies entirely in code, giving teams and agents a consistent, programmable interface for building and managing applications. Watch Rayfin in action:
const currentTheme =
localStorage.getItem(‘msxcmCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);
// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/4009254-Rayfin-Demo_tbmnl_en-us?wid=1280″,”title”:””,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009254-Rayfin-Demo-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009254-Rayfin-Demo-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009254-Rayfin-Demo-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009254-Rayfin-Demo-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/msxcm/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F4009254-rayfin-demo%2F4009254-Rayfin-Demo_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009254-Rayfin-Demo_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009254-Rayfin-Demo_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};
if (currentTheme) {
options.playButtonTheme = currentTheme;
}
document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6a2923443f750″, options);
});
Because Rayfin can be deployed directly on Fabric, application data lands directly in OneLake, where it is immediately available to the full Fabric data stack, unified with analytics, operational and real-time data, and AI engines by default. This enables developers to build their enterprise apps on trusted business logic, integrate with semantic models, and embed rich data visuals.
We’re excited to partner with Replit, a leading AI coding platform, to help customers build enterprise-grade apps in the interface they know and love while keeping app, data, and services managed in their own Fabric tenant.
Rayfin unlocks a new development model for our users. Agents write the code. Fabric ships it quickly and safely. Together, we’re giving developers something they’ve never had before: a path from idea to enterprise-grade production that’s measured in hours, not months.
—Amjad Masad, Chief Executive Officer (CEO) of Replit
Learn more about Rayfin by watching the Microsoft Build session “BRK225 – Data, apps, and agents: the future of app dev with Microsoft Fabric” on Wednesday, June 3, 2026, at 1:30 PM PT.
Microsoft Databases, designed for AI applications
For decades, databases have been the backbone of enterprise applications. As applications become more intelligent and agent‑powered, we are evolving Microsoft Databases into the foundation optimized for real‑time, AI‑ready, and operationally rich experiences.
Azure HorizonDB: Enterprise-ready PostgreSQL built for the demands of AI applications
As a leading PostgreSQL committer, Microsoft has long invested in the PostgreSQL community. But as AI‑powered applications place new strains on scale, latency, and resilience, the demand for a new class of PostgreSQL database is clear.
Azure HorizonDB is that next step. Now available in public preview, HorizonDB is a fully managed, PostgreSQL‑compatible database that combines PostgreSQL familiarity with cloud‑scale architecture. It’s zone resilient by default and delivers elastic storage that scales to 128 TB, massive scale‑out compute up to 3,072 vCores, and can sustain sub‑millisecond, multi‑zone commit latency for demanding transactional scenarios.
Learn more about the Azure HorizonDB preview
As our data demands have expanded exponentially because of our use of Azure AI to chat with our data, HorizonDB has come at the perfect time to meet the performance, scale, and security we need to shift into this new world of AI-enabled data.
—Rand Morimoto, President of Convergent Computing (CCO)
const currentTheme =
localStorage.getItem(‘msxcmCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);
// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://azure.microsoft.com/en-us/blog/wp-content/uploads/2025/11/Azure-HorizonDB.png”,”title”:””,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1092957-Azure-HorizonDB-for-Postgres-Scale-smarter-build-faster-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1092957-Azure-HorizonDB-for-Postgres-Scale-smarter-build-faster-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1092957-Azure-HorizonDB-for-Postgres-Scale-smarter-build-faster-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1092957-Azure-HorizonDB-for-Postgres-Scale-smarter-build-faster-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/msxcm/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F1092957-azure-horizondb-for-postgres-scale-smarter-build-faster%2F1092957-Azure-HorizonDB-for-Postgres-Scale-smarter-build-faster_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/1092957-Azure-HorizonDB-for-Postgres-Scale-smarter-build-faster_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”}]};
if (currentTheme) {
options.playButtonTheme = currentTheme;
}
document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6a2923443fc4c”, options);
});
Beyond scalability, we’ve also infused Azure HorizonDB with experiences designed specifically for AI applications like vector search, integrated AI model management, and direct connectivity to Microsoft Foundry and Fabric. These features provide a modern foundation for building, modernizing, and scaling AI‑powered applications with confidence. Mohsin Shafqat, Director of Software Engineering at NASDAQ, mentioned, “What stood out with HorizonDB is that it aligns closely with how we already think about the problem. Instead of stitching together multiple components, it brings transactional data, vector search, and AI capabilities into a single platform, which simplifies the architecture without forcing a complete rethink.”
Learn more by watching the Microsoft Build session “BRK223 – From rows to reasoning: Designing databases for AI apps and agents” on Tuesday, June 2, 2026, at 2:30 PM PT.
New security and migration tooling for Azure Database for PostgreSQL
As Azure HorizonDB powers a new class of high-scale, mission‑critical applications built for AI, Azure Database for PostgreSQL remains a trusted, open‑source foundation for modernizing and operating existing PostgreSQL workloads.
Today’s updates introduce two meaningful enhancements. First is the Microsoft Defender for Cloud integration, now in preview, which delivers continuous security and compliance assessments to help teams identify misconfigurations and reduce risk. Second, we’ve released new discovery and assessment tooling to help you more confidently plan migrations to Azure Database for PostgreSQL. These tools evaluate Oracle and PostgreSQL environments and provide readiness insights, sizing guidance, and cost estimates. Learn more about this migration tooling in the Microsoft Build on-demand session “OD822 – Smarter PostgreSQL migrations to power modern, intelligent apps.”
Powering intelligent, multi‑agent systems at global scale with Azure Cosmos DB
Azure Cosmos DB is Microsoft’s AI-ready NoSQL and vector database for building responsive applications and intelligent AI experiences at any scale. OpenAI, for example, chose Azure Cosmos DB as its primary operational database “because of its automatic scaling and schema-less flexibility, allowing us to iterate quickly,” said Nick Cooper, senior technical staff member at OpenAI.
At Microsoft Build, we are focused on improving developer productivity and AI quality. The Azure Cosmos DB Linux Emulator is now generally available, enabling developers to build, test, and validate applications locally across Linux, macOS, and Windows without a cloud dependency. New AI capabilities are also now in preview, including semantic reranking, which improves search relevance using built‑in contextual understanding. In addition, a new agent memory toolkit helps developers standardize persistent memory for AI agents using Azure Cosmos DB, Azure Durable Functions, and Microsoft Foundry models. Learn more in the Microsoft Build on‑demand session “OD820 – Designing reliable multi-agent apps with Azure Cosmos DB.”
Unifying databases and Fabric on a single platform
Microsoft Databases can be centrally managed through the new Database Hub in Fabric, currently in private preview, and mirrored into OneLake, bringing operational and analytical data onto a single foundation. From there, you can use Fabric to make it trusted, contextual, and ready for AI.
Building an AI‑ready data foundation with Microsoft Fabric
In the era of AI, data is the fuel, but data alone is not enough. Equally important is how that data is understood: the definitions of customers, orders, products, revenue, and the relationships between them. Today, that understanding is fragmented across customer relationship management (CRM) and enterprise resource planning (ERP) systems, productivity tools, and spreadsheets, and too often it does not travel with the data. Organizations have long relied on people to recreate this context. But as agents take on more responsibility, this gap becomes critical. Without a shared understanding of the business, agents cannot reliably reason, coordinate, or act.
Microsoft IQ addresses this missing layer by unifying enterprise intelligence into a shared foundation built to activate AI agents. It enables consistent reasoning and enterprise-scale impact, rather than isolated interactions and and brings together four interconnected capabilities: Work IQ captures how work happens, Fabric IQ models how the business operates, Foundry IQ enables agents to discover and reuse knowledge, and the new Web IQ, announced today at Microsoft Build, adds real-time global context from the web.
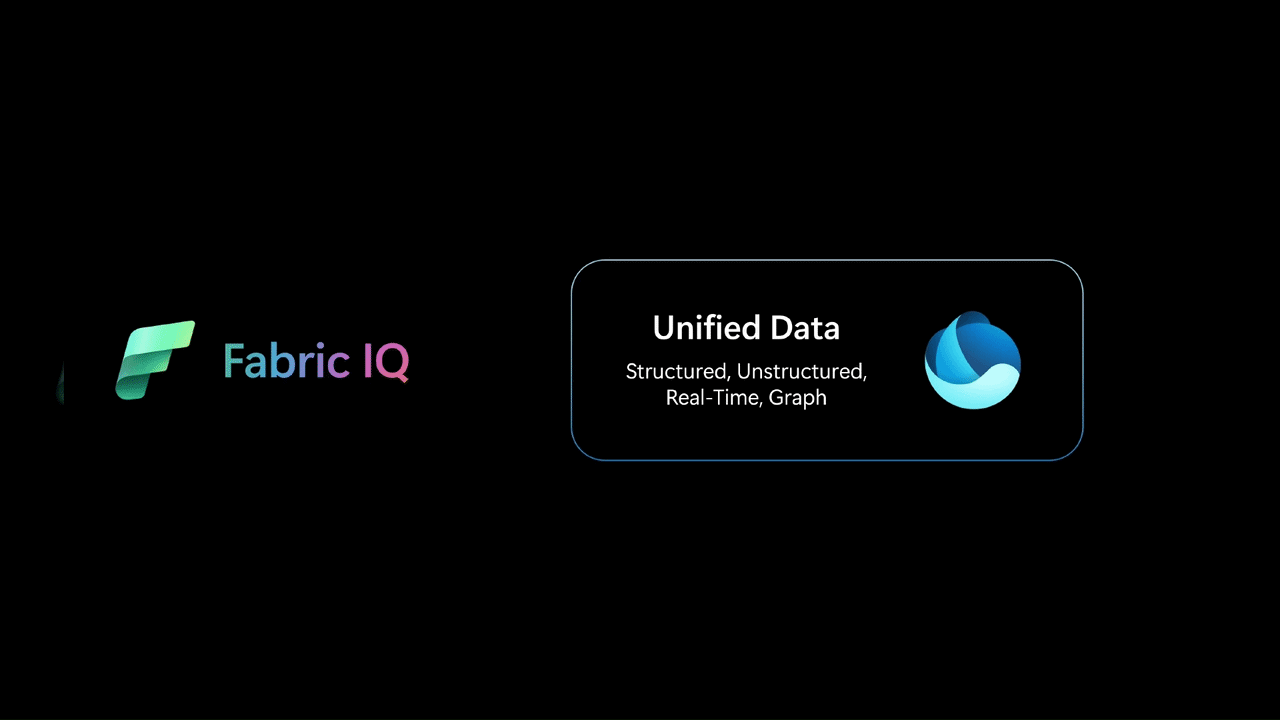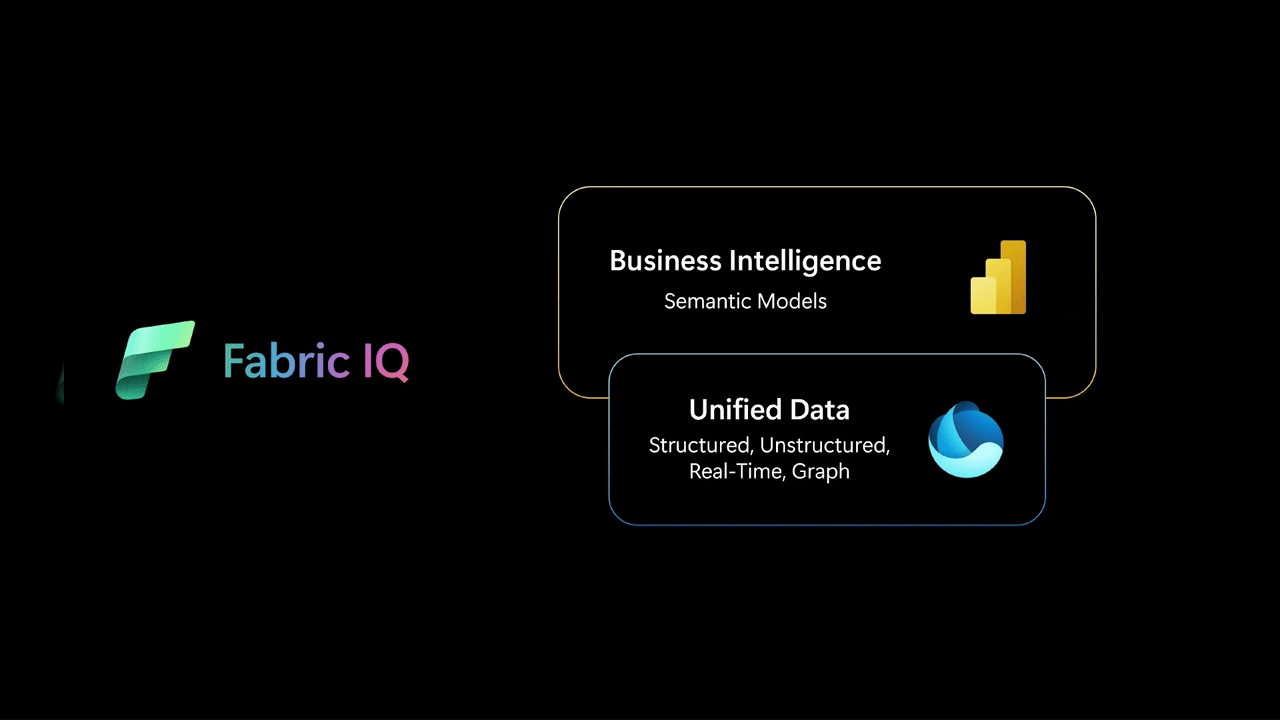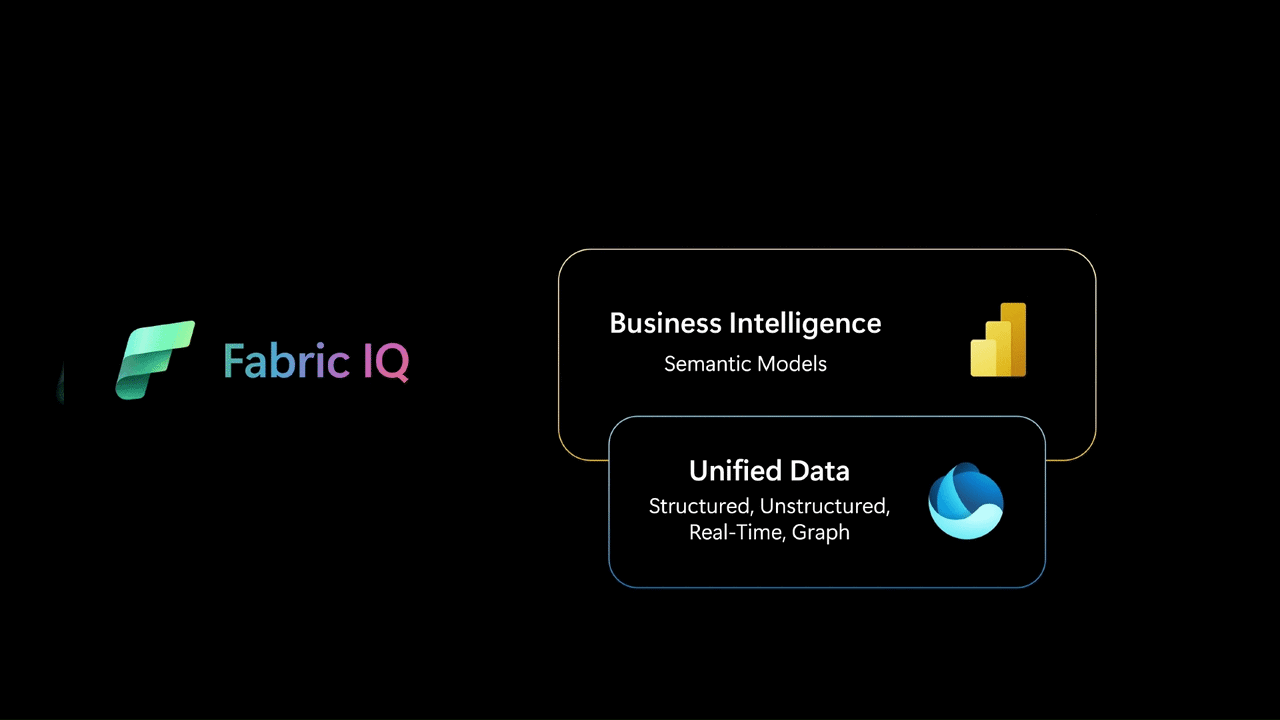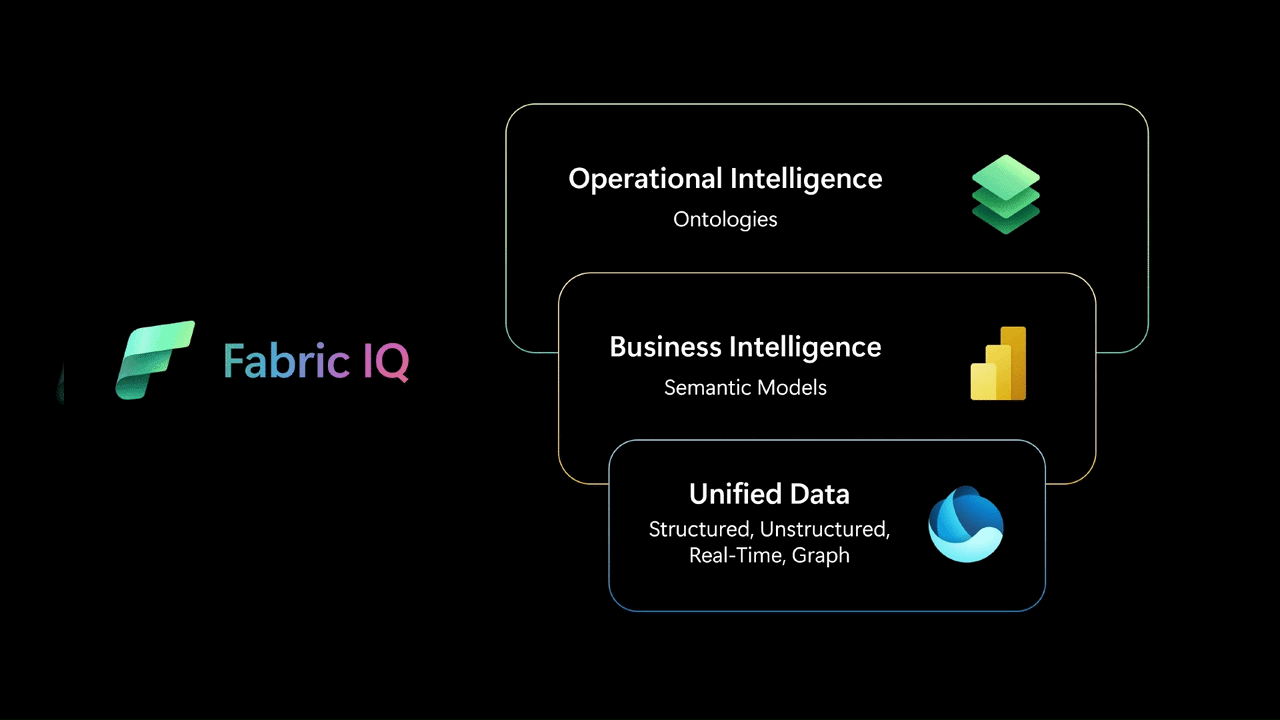
Fabric IQ is central to this system. It powers a continuous operational loop where people and agents observe live signals, reason over shared context, and take governed action in the moment across analytics, operations, and the productivity tools where work happens. It provides three integrated layers of business context:
Unified data: OneLake unifies the organization’s data estate, spanning analytical and operational data into a single, accessible layer.
Business intelligence: Semantic models provide structured, governed representations of that data which organizations already rely on for trusted business metrics and analyze their business.
Operational intelligence: Ontologies capture operational context by defining business entities and their relationships so agents can reason in the language of the business. This context can include live signals from Fabric Real-Time Intelligence, enabling organizations and their agents to understand what is happening right now and act in time to change outcomes.
This three-tiered foundation helps ensure that every agent starts with the same understanding of the business and can apply it correctly across workflows. But Frontier organizations cannot start at the IQ layer. Building this capability requires a unified data foundation. Microsoft Fabric delivers this through four core capabilities:
Unifying your data estate
Processing and harmonizing data
Curating semantic meaning
Empowering AI agents to act
Learn more about how Fabric can help you create an AI-ready data foundation in the Microsoft Build on-demand session “OD811 – Powering the next AI frontier with a unified data platform.”
1. Unifying your data estate with Microsoft OneLake
Most organizations struggle to see their entire data estate. It is spread across systems, duplicated in multiple places, and owned by different teams, making it difficult to know what exists, where it lives, and how it connects. Microsoft OneLake brings it together into a single, AI‑ready data lake that unifies your multi‑cloud estate and enables organization‑wide access for analytics and AI.
We are making it easier to connect existing data to OneLake without moving or duplicating it with the release of shortcuts to SharePoint and OneDrive into general availability and the ability to create shortcuts directly from Fabric Data Warehouses, now in preview. We are also adding the preview of workspace-level Azure Private Link support for mirrored data sources.
The general availability of the OneLake catalog in Microsoft Foundry
At the same time, we are making it easier to connect that data to AI. With the recent general availability of the OneLake catalog in Microsoft Foundry, you can discover trusted data, explore rich metadata, and connect it directly to AI solutions. The catalog is embedded within Foundry’s Knowledge experience, making it simple to move from data discovery to AI development in a single workflow.
const currentTheme =
localStorage.getItem(‘msxcmCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);
// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo_tbmnl_en-us?wid=1280″,”title”:””,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/msxcm/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F4009252-onelake-foundry-integration-demo%2F4009252-OneLake-Foundry-Integration-Demo_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009252-OneLake-Foundry-Integration-Demo_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};
if (currentTheme) {
options.playButtonTheme = currentTheme;
}
document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6a29234441676″, options);
});
Learn more about all of these OneLake announcements by watching the Microsoft Build on-demand session “OD815 – Unify your entire data estate on a single, AI-ready data lake.”
2. Process data faster with a new class of GPU-accelerated analytics
Once data is unified, the next challenge is turning it into insights quickly, reliably, and at scale. We are introducing GPU-acceleration built directly into Fabric Data Warehouse to unlock a new level of performance without adding complexity.
The research behind this innovation was recently recognized by ACM SIGMOD as the “Best Industry Paper of 2026.” This breakthrough establishes Fabric Data Warehouse as the first fully managed data warehouse to offer GPU acceleration.
By integrating NVIDIA accelerated computing, query acceleration in Fabric Data Warehouse fundamentally changes how fast queries can run. In internal benchmarking conducted in May 2026, the GPU-accelerated Fabric Data Warehouse delivered up to 7x faster performance relative to three comparable external vendors for reporting and application workloads at 64-user concurrency.
This shift reflects a broader change in how modern data systems need to operate. As Ian Buck, Vice President of Hyperscale and HPC at NVIDIA, explains, “AI applications are redefining how a data warehouse needs to perform. As AI agents reason over enterprise data, analytics systems need low-latency performance for many simultaneous users. With NVIDIA accelerated computing and custom CUDA kernels built directly into Microsoft Fabric Data Warehouse, Microsoft is bringing the SQL workflows customers already use into the production AI era.”
Customers are already seeing that impact. At UNC Health, “We’re seeing up to 5x improvement in our query speeds, which allows our teams to spend less time managing performance and more time delivering meaningful insights,” said Shaun McDonald, IT Manager.
Query acceleration works automatically within Fabric, speeding up queries without requiring any query rewrites. The result is consistently low‑latency analytics that power responsive applications, interactive reporting, and agent‑driven analysis, delivering fresher insights and greater confidence in data.
const currentTheme =
localStorage.getItem(‘msxcmCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);
// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://cdn-dynmedia-1.microsoft.com/is/image/microsoftcorp/4009251-GPU-Acceleration-Query-Demo_tbmnl_en-us?wid=1280″,”title”:””,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009251-GPU-Acceleration-Query-Demo-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009251-GPU-Acceleration-Query-Demo-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009251-GPU-Acceleration-Query-Demo-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009251-GPU-Acceleration-Query-Demo-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}],”ccFiles”:[{“url”:”https://azure.microsoft.com/en-us/blog/wp-json/msxcm/v1/get-captions?url=https%3A%2F%2Fwww.microsoft.com%2Fcontent%2Fdam%2Fmicrosoft%2Fbade%2Fvideos%2Fproducts-and-services%2Fen-us%2Fazure%2F4009251-gpu-acceleration-query-demo%2F4009251-GPU-Acceleration-Query-Demo_cc_en-us.ttml”,”locale”:”en-us”,”ccType”:”TTML”}],”downloadableFiles”:[{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009251-GPU-Acceleration-Query-Demo_transcript_en-us”,”locale”:”en-us”,”mediaType”:”transcript”},{“url”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009251-GPU-Acceleration-Query-Demo_audio_en-us”,”locale”:”en-us”,”mediaType”:”audio”}]};
if (currentTheme) {
options.playButtonTheme = currentTheme;
}
document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6a292344418f1″, options);
});
Query acceleration will be available for an early access preview in the next few weeks. You can learn more by watching the Microsoft Build on-demand session “OD813 – Powering modern data analytics in Fabric Data Warehouse.”
3. Curating semantic meaning with Fabric IQ, now generally available
Once data is prepared, the next challenge is not access but understanding. Most organizations lack a shared layer of business context, forcing every agent to relearn how the business works from fragmented data. Fabric IQ, now generally available, addresses this gap.
With data unified in OneLake, Power BI’s industry-leading semantic models then provide structured representations of your data for trusted business intelligence, serving as an ideal foundation for training agents.
Ontologies in Fabric IQ, expected to be generally available in the coming months, extend semantic models by adding operational context. They define business entities, relationships, properties, rules, and actions, and connect to live signals from Fabric Real-Time Intelligence. Operations agents, now generally available, then reason over shared live context, make decisions based on policy, and take action in the moment. Running on the governed foundation of Fabric and integrated with Microsoft Foundry, operations agents move beyond answering questions to driving action and outcomes.
Announcing the general availability of graph and planning in Fabric
We’re announcing the general availability of graph in Fabric, with general availability of the planning in Fabric coming later this month. Available today, graph introduces a highly scalable, relationship‑first model that connects business entities, systems, and signals so teams and agents can understand how changes propagate across the enterprise and act with full context. Planning extends this foundation by enabling organizations to create plans, budgets, forecasts, and scenario models on top of Fabric’s semantic models. Notably, planning in Fabric is not just static outputs. They can be written back into Fabric to drive execution, enabling closed-loop alignment with the same system of data and context.
Extending Fabric IQ to Microsoft Foundry and Agent 365
Today, we are extending Fabric IQ across the agent ecosystem so this shared understanding can be used consistently across every agent and application.
Microsoft Foundry and Agent 365
Now in preview, Ontologies are accessible directly from Microsoft Foundry as knowledge sources, bringing trusted business context into both custom and built-in agent experiences. Also in preview, Fabric IQ is now integrated with Microsoft Agent 365 as a first-party model context protocol (MCP) tool, enabling organizations to ground agents in shared meaning and ensure consistent behavior across their agent estate.
Microsoft 365 Copilot: Cowork and Copilot Chat
Fabric IQ is also extending into Microsoft 365 Copilot, including Cowork and Copilot Chat. This enables agents to access governed Fabric data, starting with Power BI reports and semantic models, to turn insights into action. Instead of static dashboards, agents can detect changes in key metrics, generate updates, trigger follow-ups, and schedule next steps, all grounded in trusted, governed data. The result is faster, more consistent execution across the organization. These experiences are currently available customers in Frontier with a Microsoft 365 Copilot license. Join the program today.
GitHub Copilot CLI
Using Agent Skills for Fabric, Fabric IQ tools and skills for data insights are accessible through GitHub Copilot CLI, bringing governed semantic context directly into the terminal. Now you can also query Power BI reports and semantic models from the command line, grounded in governed semantic context in Fabric IQ. Teams can ask natural language questions about usage, metrics, or customer behavior and get answers grounded in Fabric data directly within their workflow, reducing back-and-forth and accelerating data-driven decisions.
Learn more about these enhancements in the Build on‑demand session “OD812 – Bringing Enterprise Ontology Directly into the Developer Workflow.”
4. Empowering agents to act with operations agents and Copilot in Fabric
Enterprises are increasingly moving to multi-agent systems made up of specialized agents grounded in specific data or domain expertise. These agents can be reused across multiple systems, making it easier to scale and deliver more consistent outcomes.
Announcing the general availability of operations agents
Microsoft Fabric supports this shift with native agent capabilities, including Fabric data agents and operations agents. I’m excited to share operations agents are now generally available. These agents are designed to continuously monitor real-time data, detect patterns or anomalies, and act based on predefined business logic.
const currentTheme =
localStorage.getItem(‘msxcmCurrentTheme’) ||
(window.matchMedia(‘(prefers-color-scheme: dark)’).matches ? ‘dark’ : ‘light’);
// Modify player theme based on localStorage value.
let options = {“autoplay”:false,”hideControls”:null,”language”:”en-us”,”loop”:false,”partnerName”:”cloud-blogs”,”poster”:”https://azure.microsoft.com/en-us/blog/wp-content/uploads/2026/06/Screenshot-2026-06-02-093232.png”,”title”:””,”sources”:[{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009253-Ops-Agent-Demo-0x1080-6439k”,”type”:”video/mp4″,”quality”:”HQ”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009253-Ops-Agent-Demo-0x720-3266k”,”type”:”video/mp4″,”quality”:”HD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009253-Ops-Agent-Demo-0x540-2160k”,”type”:”video/mp4″,”quality”:”SD”},{“src”:”https://cdn-dynmedia-1.microsoft.com/is/content/microsoftcorp/4009253-Ops-Agent-Demo-0x360-958k”,”type”:”video/mp4″,”quality”:”LO”}]};
if (currentTheme) {
options.playButtonTheme = currentTheme;
}
document.addEventListener(‘DOMContentLoaded’, () => {
ump(“ump-6a29234442a09″, options);
});
Apply agentic analytics in Power BI
In addition, we recently released open-source Agent Skills for Fabric, designed to make it easier for AI tools and agents to interact directly with Fabric. These capabilities now extend to Power BI, enabling developers and analysts to create reports using natural language or even a screenshot of the desired outcome, significantly accelerating how insights are built and shared.
Copilot in Power BI can now also modify semantic models, with built-in recommendations that improve performance and make models more AI-ready. This helps teams iterate faster and deliver insights more quickly without leaving the tools they already use.
Learn more by reading the Power BI blog or by watching the Microsoft Build on-demand session “OD817 – Agentic analytics with Power BI and Microsoft Fabric.”
Watch these announcements from Microsoft Build
If you’re interested in learning more and seeing live demos on these announcements, I encourage you to watch the Microsoft Database and Microsoft Fabric sessions at Microsoft Build, available in the Microsoft Build catalog.
Tuesday, June 2, 2026
BRK223 – From rows to reasoning: Designing databases for AI apps and agents from 2:30 PM PT to 3:15 PM PT.
Wednesday, June 3, 2026
BRK225 – Data, apps, and agents: the future of app dev with Microsoft Fabric from 1:30 PM PT to 2:15 PM PT.
BRK224 – PepsiCo’s blueprint for agentic AI from 2:45 PM PT to 3:30 PM PT.
On-demand sessions (available now)
Click the links below to watch immediately.
Microsoft Databases
OD820 – Designing reliable multi-agent apps with Azure Cosmos DB
OD821 – Building Azure DocumentDB on open-source foundations
OD822 – Smarter PostgreSQL migrations to power modern, intelligent apps
OD823 – Faster AI Responses with Semantic Caching in Azure Managed Redis
OD824 – Scalable Applications Without Polyglot tax: Azure SQL Hyperscale
Microsoft Fabric
OD811 – Powering the next AI frontier with a unified data platform
OD812 – Bringing Enterprise Ontology Directly into the Developer Workflow
OD813 – Powering modern data analytics in Fabric Data Warehouse
OD815 – Unify your entire data estate on a single, AI-ready data lake
OD816 – Securing, scaling, and sustaining your data estate in Microsoft Fabric
OD817 – Agentic analytics with Power BI and Microsoft Fabric
OD818 – The AI-native data engineer
OD819 – Real-Time Intelligence: Bringing event-driven AI apps & agents
OD810 – Build fast, not fragile on Microsoft Fabric
Explore additional resources for Microsoft Fabric
Sign up for the Microsoft Fabric free trial.
View the updated Fabric Roadmap.
Try the Microsoft Fabric SKU Estimator.
Visit the Fabric website.
Join the Fabric community.
Read other in-depth, technical blogs on the Microsoft Fabric Updates Blog.
Get started with Microsoft Fabric
The post Microsoft Build 2026: Building agentic apps with Microsoft Fabric and Microsoft Databases appeared first on Microsoft Azure Blog.
Quelle: Azure