Gesundheitsgefährdender Algorithmus: EU fordert grundlegende Änderungen bei Tiktok
Die EU-Kommission sieht Hinweise darauf, dass Tiktok seine Nutzer durch das Empfehlungssystem der App gesundheitlich gefährdet. (Tiktok, Politik)
Quelle: Golem

Die EU-Kommission sieht Hinweise darauf, dass Tiktok seine Nutzer durch das Empfehlungssystem der App gesundheitlich gefährdet. (Tiktok, Politik)
Quelle: Golem

Blinkende Röhrenmonitore, klackernde Joysticks, Spiele aus den 1970ern: Im Mikado lebt Videospielgeschichte. Daneben wirken moderne Arcades wie Spielzeugläden. Eine Reportage von Peter Steinlechner (PC, Bandai Namco)
Quelle: Golem

Die künftige texanische Gouverneurin reagiert auf Proteste aus der Bevölkerung und will den Ausbau von Rechenzentren stoppen, bis Schutzgesetze stehen. (Rechenzentrum, KI)
Quelle: Golem

Nach dem Drohnenanschlag auf den Flughafen Leipzig suchen Generalbundesanwalt und BKA mit einem ungewöhnlichen Mittel nach einer unbekannten Person. (KI, Security)
Quelle: Golem
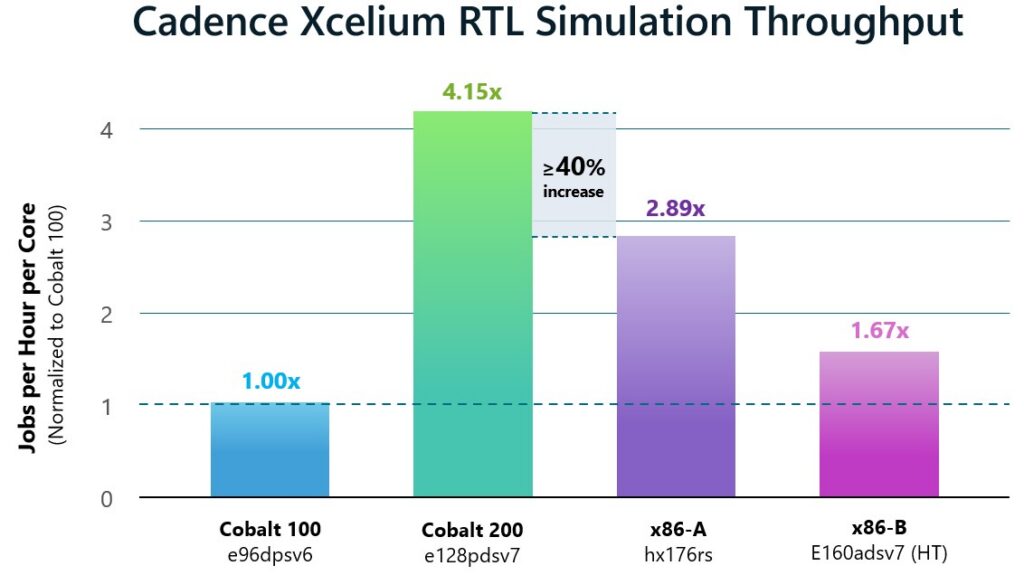
Every Azure chip Microsoft has built started as electronic design automation (EDA) jobs used to design, test, and validate silicon before it is manufactured. This includes simulation sweeps that run for days, verification regressions that fan out across thousands of cores overnight, and physical signoff runs that use hundreds of gigabytes of memory for a single block. Together, these workloads account for hundreds of millions of compute jobs each year. Today we’re sharing early results from our next step in that evolution: running EDA workloads on Azure Cobalt 200, Azure’s custom compute infrastructure built on the Arm Neoverse CSS V3. In our silicon design environment, the evaluated EDA workloads ran with 1.30x to 4.15x more performance than on Cobalt 100 across a range of testing scenarios, from simulation to verification to static timing analysis.
Learn more about Azure Cobalt 200 VMs
Traditionally, EDA workloads ran on fixed, on-premise x86 server capacity, sized for peak demand with periods of underutilization. The shift to cloud-based EDA on Microsoft Azure offered a new level of flexibility, scale, and reliability on compute-intensive silicon design workloads. Using Azure Cobalt-based virtual machine (VM) instances, silicon engineering teams at Microsoft are experiencing significant performance and efficiency improvements on EDA workloads that Azure customers are seeing across many workloads—optimizing the performance and speed of designing increasingly sophisticated silicon for increasingly complex cloud systems.
In this blog, we highlight results from Cadence Xcelium and Cadence Spectre, Synopsys PrimeTime and Synopsys VCS, and Siemens Calibre tools. Tools enabled on Cobalt 100 ran unmodified in our Cobalt 200 evaluation, allowing us to focus on performance testing rather than functionality.
Why Cobalt 200 suits EDA
EDA spans workloads with very different compute requirements:
Circuit and analog simulation — optimized for highly parallel workloads, with sensitivity to memory behavior.
Functional and formal verification — throughput-driven, with large numbers of independent jobs running concurrently.
Implementation and signoff — memory-intensive and bandwidth-sensitive, with long-running jobs.
For computer-aided design (CAD) managers, predictable per-core performance is essential to planning overnight regressions. Per-core performance measured on a lightly loaded VM does not necessarily hold as concurrency increases. Verification farms need predictable throughput when VMs are heavily loaded.
Cobalt 200 combines physical cores without the overhead of hyperthreading, dedicated 3MB L2 cache per core, and high provisioned memory bandwidth to support concurrent workloads. These core and memory architecture characteristics support strong per-core performance at high utilization.
What we measured
We tested Cobalt 200 with workloads from several stages of Microsoft’s silicon development flow, including RTL and gate-level simulation, static timing, physical verification, and analog simulation, comparing job completion time with Cobalt 100 and selected x86 Azure VMs.
All tested VMs were configured with the maximum number of cores possible for high throughput 5, multiple jobs were concurrently executed on the VM to validate the performance under high load conditions. Throughput is normalized per logical core. For the Cobalt 100, Cobalt 200, and hx176rs configurations, logical cores are also physical cores.
Consolidated EDA workload results
WorkloadEDA toolMeasureCobalt 200 resultDigital simulationCadence Xcelium1Peak throughput per logical coreMore than 40% higher than any other tested systemDigital simulationSynopsys VCS1Peak throughput per logical coreMore than 40% higher than any other tested systemAnalog and mixed-signal simulationCadence Spectre2Throughput per logical core38% higher generation over generation; exceeded tested x86 Azure VMsPhysical verificationSiemens Calibre3 DRCWall time / relative performance23% lower wall time; 1.30× relative performance versus Cobalt 100Static timing analysisSynopsys PrimeTime4Peak throughput per logical core2.0× Cobalt 100; exceeded tested x86 Azure VMs
Digital simulation
Cadence Xcelium and Synopsys VCS are tools used to simulate and verify digital designs. RTL simulation is central to functional verification and can consume significant compute capacity as teams run large regression suites. When testing RTL workloads using both simulators, optimally loaded Cobalt 200 systems delivered significantly greater peak throughput than the previous generation. For the workload tested on Xcelium and VCS, Cobalt 200 delivered more than 40% higher throughput per logical core than any other system we tested.
Throughput is normalized per logical core to account for the VMs’ different core counts.
Cobalt 200 was optimized for EDA workloads through increased cache size and improved memory bandwidth per core. Our results demonstrate that Cobalt 200 design optimizations generate significantly improved performance for logic simulation workloads.
Figure 1 and 2. Cadence Xcelium RTL and Synopsys VCS simulation throughput for an internal real simulation test case, normalized jobs per hour per logical core; Cobalt 100 = 1.0.
Analog and mixed signal simulation
Cadence Spectre is used for analog and mixed-signal circuit simulation. Analog and mixed-signal circuit simulation workloads differ from RTL simulation and are dominated by multithreaded performance. We tested Cadence Spectre on Cobalt 200 and observed 38% higher throughput per logical core generation over generation, and delivered 11-52% higher throughput per logical core compared with all other platforms tested.
Figure 3. Cadence Spectre analog simulation throughput for an internal test case, normalized jobs per hour per logical core; Cobalt 100 = 1.0.
This result shows meaningful progress between Cobalt generations.
Physical verification
Siemens Calibre DRC checks a design’s physical layout against manufacturing design rules before tapeout.
For the Calibre workload we tested DRC against an IP Macro with 16 cores per job, Cobalt 200 completed the run in approximately 23% lower wall time than Cobalt 100, equivalent to 1.30x relative performance. It also outperformed the selected x86 Azure VMs at the same per-job core count.
Figure 4. Siemens Calibre DRC performance for an internal test case using 16 cores per job. Relative performance is Cobalt 100 mean total wall time divided by each platform’s mean total wall time; Cobalt 100 = 1.0.
Static timing analysis on Synopsys PrimeTime
Synopsys PrimeTime is used for static timing analysis to verify that a design meets its timing requirements. For the PrimeTime workload tested with 16 cores per job, Cobalt 200 delivered 2x the peak throughput per logical core of Cobalt 100 and exceeded the selected x86 Azure VMs. Figure 5 compares each VM platform’s highest measured throughput value, normalized to Cobalt 100.
Figure 5. Synopsys PrimeTime peak job throughput for an internal test case, using 16 cores per job and normalized to jobs per hour per logical core; Cobalt 100 = 1.0.
More than just an SoC: Platform-level advantages to Cobalt 200
A higher-performance compute SoC only helps if the rest of the platform scales its performance as well. EDA workloads depend on high-bandwidth and low-latency storage and data movement, and demand varies throughout a silicon program. Verification activity can spike before a milestone, while physical verification and signoff activity increase toward tapeout. Demand can fall sharply once those milestones are completed.
Running on Azure pairs Cobalt 200 compute with:
Elastic capacity: provisioning compute capacity for a regression campaign or signoff push, then release it as demand falls. Size for the workload, not the annual peak.
High-performance storage: supporting the data demands of large design databases, waveform dumps, and physical verification runs.
Global capacity: aligning deployments with engineering locations, data residency requirements, and regional availability.
Adjacency to Azure AI services: As agentic and AI-assisted design workflows evolve, proximity between AI inference services and Cobalt 200 compute creates opportunities for tighter integration of AI-powered reasoning with EDA execution. This reduces data movement overhead, accelerates iterative design and verification cycles, and enables AI agents to orchestrate complex engineering workflows more efficiently.
Microsoft is a key partner for Cadence, and our collaboration on Cobalt spans multiple generations of Azure silicon. With Cadence EDA workflows now qualified on Cobalt 200, we are extending that collaboration to the latest generation of Azure infrastructure and giving semiconductor teams greater flexibility in how they access and scale compute for demanding design and verification workloads.
—Paul Cunningham, Sr. VP & GM, System Verification Group, Cadence
As semiconductor designs grow increasingly complex, engineering teams face mounting pressure to accelerate silicon development while managing growing compute demands. Executing Siemens EDA solutions on Microsoft Azure Cobalt 200 provides an efficient, scalable platform for demanding verification and signoff workloads. Our collaboration with Microsoft demonstrates the value of matching the right workloads to the right compute architecture to advance silicon innovation.
—Craig Johnson, VP of Cloud Solutions, Siemens EDA
Our longstanding partnership with Microsoft is grounded in a shared commitment to help engineering teams tackle increasingly complex design challenges. We congratulate Microsoft on the impressive performance of Cobalt 200, developed using Synopsys’ comprehensive EDA flow spanning verification, implementation and signoff, together with HAPS hardware prototyping and Synopsys IP. We’re excited to see Cobalt 200 delivering meaningful performance gains generation-on-generation, including more than 40% faster runtimes with Synopsys VCS and 2x per-core throughput with Synopsys PrimeTime. We look forward to continuing our collaboration to help engineering teams advance the next generation of AI silicon.
—Sanjay Bali, Senior Vice President of EDA Product Management and Strategy at Synopsys
Designing Next-Generation Cobalt with Cobalt 200
There’s a virtuous cycle between silicon development and EDA performance: EDA tools helped bring Cobalt 200 to life, and now Cobalt 200 is accelerating those same design and verification workloads for our next-generation Cobalt products. By observing how EDA workloads perform at scale, we gain insights that help shape future generations of Cobalt and Azure compute infrastructure, with each generation helping design and improve the next.
What comes next
Our early tests show significant progress for EDA on Cobalt 200. Existing Arm-enabled tools ran without workflow changes, and the tested workloads performed competitively against the selected x86 Azure VMs. Xcelium and PrimeTime showed a particularly large improvement over Cobalt 100. Spectre and Calibre which were strong performers on Cobalt 100 also improved generation over generation, and we are working with our EDA partners on further tuning of multiple tools.
We are broadening workload coverage, validating results on a greater scale, and continuing to collaborate with our EDA partners as Cobalt 200 enters general availability.
If you’re evaluating cloud infrastructure for semiconductor design, we invite you to test your EDA workflows on Azure Cobalt 200 VMs.
Learn more about Cobalt at Microsoft Ignite: Cobalt 200: Delivering Azure’s Best Performance And Efficiency
Check out Microsoft’s silicon to system approach to infrastructure.
Run next-generation AI workloads with Azure Cobalt 200
Learn more
1. Cadence Xcelium and Synopsys VCS results use an internal RTL simulation test case, concurrently run. Throughput is calculated from mean full-job wall time at the tested concurrency. Each platform’s highest measured throughput is normalized to Cobalt 100. Throughput is normalized as jobs per hour per logical core to account for different VM core counts.
2. Cadence Spectre results use an internal analog simulation test case, concurrently run with mt=16 per job. Peak throughput is normalized as jobs per hour per logical core to account for different VM core counts. The 38% figure is the measured generation-over-generation throughput improvement from Cobalt 100 to Cobalt 200 for the evaluated workload.
3. Siemens Calibre DRC results use an internal IP Macro test case, run with mt=16 on a quiet VM. Relative performance is calculated as Cobalt 100 mean total wall time divided by each platform’s mean total wall time.
4. Synopsys PrimeTime results use an internal static-timing test case, concurrently run with 16 cores per job. Throughput is calculated from mean full-job wall time at the tested concurrency. Each platform’s highest measured throughput per logical core is normalized to Cobalt 100. Throughput is normalized as jobs per hour per logical core to account for different VM core counts.
5. Results are from internal Microsoft test cases and apply only to the evaluated workloads, software versions, VM configurations, concurrency levels, and test conditions. Tested VMs included Cobalt 100 (96 cores), Cobalt 200 (128 cores), hx176rs (176 cores), and e160adsv7 (160 logical cores, hyperthreading enabled).
The post Designing Azure silicon on Azure silicon: EDA workloads on Cobalt 200 appeared first on Microsoft Azure Blog.
Quelle: Azure
Transformation begins at the line between an experiment that works and a capability the business depends on. Scaling intelligence requires production capabilities built for sustained business performance, with investments prioritized against financial thresholds, tied to measurable outcomes, instrumented for unit costs, and owned by accountable leaders. This approach manages cost, performance, governance, and reliability as adoption grows.
A new IDC InfoBrief, sponsored by Microsoft, Scaling AI Without Scaling Costs*, on how organizations are funding and governing AI, shows both the urgency of that shift and the friction holding it back.
Read the IDC InfoBrief
Nearly 90% of organizations apply financial thresholds beforeapproving AI initiatives.
Scaling AI Without Scaling Costs
Only 17% of organizations build models to project how costs scale in production—even as about 78% prioritize cost efficiency when selecting a model. 86% expect financial results within six to 24 months—roughly one budget cycle to show something real. Together, those findings point to a new operating reality: AI must be selected, architected, and managed as a continuous business discipline, not a series of isolated projects. The market has moved from proving it works to proving it can scale economically.
Four questions to answer before your next funding decision
Run each candidate through four questions that follow a scaled workload’s life: fund it, run it, improve it, prove it.
1. How can we predict and track costs at scale?
A pilot proves the idea, rarely the economics: only 17% of organizations model how costs scale in production. Before you fund, project usage at 3 times and 10 times, and make sure spend traces to an application, team, and agent. Compare models on cost, quality, and latency, and commit steady demand to reserved capacity. If cost rises with usage while value flattens, you’ve found an architecture problem while it’s still cheap to fix.
2. How can we optimize model costs for every request?
One successful outcome can take a dozen model requests, so what matters is cost per outcome, not price per token. Ask:
Is routine work like classification paying frontier-model prices?
Are the same instructions reprocessed on every turn?
Is work that can wait running at a lower-cost tier?
The goal is the right model for every request, with evaluation proving quality held.
3. How can we continuously improve agent performance and costs?
Retrieved documents, tool definitions, instructions, and history are often an agent’s largest cost and a common cause of weak answers. Check:
Does the agent retrieve the relevant passage or the whole document?
Does it carry every tool description on every turn?
Is the same procedure copied into every agent?
Does it replay full transcripts instead of remembering what matters?
Trimming what the model doesn’t need lowers cost without hurting quality.
4. How can we control spending and measure ROI?
A budget alert reports the fire after it starts; a runaway agent needs a circuit breaker on every request. Cost must tie to the outcome the business pays for, such as a resolved case, so leaders can optimize, scale, or retire an agent. The business owner also needs an evaluation suite, cost and latency budgets, a rollback path, and regular reviews. With 86% of organizations expecting financial results within six to 24 months, that evidence has about one budget cycle to appear.
All four answers depend on evidence captured where AI runs: per request, agent, and outcome. If each team builds it by hand, the discipline won’t survive the tenth agent. It has to come from the platform.
How Microsoft Foundry supports continuous cost optimization
When customers ask for a few practical ways to scale AI while controlling costs, I recommend:
Use model routing across the over 11,000 models available in Microsoft Foundry.
Implement Microsoft IQ to improve relevance and reduce costs.
Use the plan, control, and optimize capabilities described below to strengthen operations across the organization.
Microsoft Foundry is the enterprise platform to build, ground, and govern AI apps and agents at scale. It brings together your full agent lifecycle with open development, built-in intelligence, and consistent security, compliance, and policy controls across every agent. Think of it as a repeatable production line rather than a set of one-off builds, where the same controls, evidence, and economics apply to the tenth agent as to the first.
This is what makes the operating loop practical at scale. Across the loop:
Plan: Compare models on cost, quality, and performance before committing to an architecture, and match predictable baseline demand to reserved capacity while keeping the flexibility to burst. The decisions that set your production cost curve get made with data rather than intuition.
Control: Observability that reports cost alongside quality, latency, and safety in one view, so the economics of a workload are visible while it’s running rather than reconstructed at quarter-end. That’s what makes cost per outcome a number you can put in front of your CFO.
Optimize: Model routing that sends each request to the smallest model that can serve it, an intelligence layer that provides context and retrieval centrally and addresses a common source of avoidable token spend, and evaluation tooling that catches quality regression when you make a cost decision—because a cheaper system that quietly degrades isn’t a saving.
The value compounds with volume. When every agent inherits the same grounding, governance, and cost telemetry from the platform, scaling from one use case to 20 doesn’t mean rebuilding the discipline 20 times. What Foundry does is make sure the evidence exists when the funding conversation comes around, and the levers are within reach when you need them.
Next steps for optimizing AI agent costs and ROI
Scaling AI isn’t a bigger experiment. It’s a different discipline: a shared threshold, a unit cost, a value curve that outruns the cost curve, and an owner whose name is on the result.
Go deeper with our four-part blog series on The Economics of Agent Optimization in Microsoft Foundry, which takes each of these questions from principle to implementation:
AI cost management: From AI pilots to measurable ROI
AI cost optimization: How to lower AI spend
AI agent optimization: How context engineering lowers AI costs
AI agent governance: How to measure AI value and ROI
Then join us at Microsoft Ignite, November 17–20 in San Francisco or online, to see it in action and go hands-on with the team that built it.
Microsoft Foundry
The AI app and agent factory.
Get started
*Source: doc ##US54538926-IB, July 2026
The post Stop treating agents as one-off projects and start running them as a continuous discipline appeared first on Microsoft Azure Blog.
Quelle: Azure
Amazon Simple Email Service (Amazon SES) is now available in the Asia Pacific (New Zealand, Melbourne, Taipei, Thailand), Mexico (Central), EU (Spain). Customers can now use these new Regions to leverage Amazon SES to send emails and, if needed, to help manage data requirements.
Amazon SES is a scalable, cost-effective, and flexible cloud-based email service that allows digital marketers and application developers to send marketing, notification, and transactional emails from within any application. To learn more about Amazon SES, visit this page .
With this launch, Amazon SES is available in 35 AWS Regions globally: US East (N. Virginia, Ohio), US West (N. California, Oregon), AWS GovCloud (US-West, US-East), Asia Pacific (Osaka, Mumbai, Hyderabad, Sydney, Singapore, Seoul, Tokyo, Jakarta, Malaysia, New Zealand, Melbourne, Taipei, Thailand), Canada (Central, Calgary), EU (Ireland, Frankfurt, London, Paris, Stockholm, Milan, Zurich,Spain), Middle East (Bahrain, UAE), Israel (Tel Aviv), South America (Sao Paulo), Mexico (Central) and Africa (Cape Town).
For a complete list of all of the regional endpoints for Amazon SES, see AWS Service Endpoints in the AWS General Reference.
Quelle: aws.amazon.com
AWS Glue Data Catalog now supports external catalog’s vended credentials in Apache Iceberg REST catalog federation. You can now read external Iceberg tables from Amazon Athena, Amazon EMR, Amazon Redshift, and AWS Glue using coarse-grained table grants in your external Iceberg catalog.
Glue Data Catalog already federates to external Iceberg REST catalogs through an AWS IAM role that you configure with access to your Amazon S3 buckets. This enhancement in Glue Data Catalog provides another way to connect to an external Iceberg catalog and read only the tables that the external catalog authorizes. It uses temporary security credentials that are scoped to the Amazon S3 storage prefix and vended by your external Iceberg catalog. AWS Lake Formation manages access control when you query an external table using any AWS analytics engine, letting you restrict access further down to specific rows and columns and share external Iceberg tables across AWS accounts.
This feature is available through the AWS Lake Formation Management Console, AWS CLI, and the AWS Glue and Lake Formation SDKs. This feature is available in all commercial AWS Regions where Glue and Lake Formation are supported. To learn more, visit the documentation.
Quelle: aws.amazon.com
Starting today, you can add Amazon EC2 Capacity Blocks for ML and interruptible Capacity Reservations to Capacity Reservation Resource Groups in AWS GovCloud (US) Regions. Amazon EC2 offers different reservation offerings such as On-Demand Capacity Reservations (ODCRs), interruptible Capacity Reservations, and Capacity Blocks for ML. Previously, a Capacity Reservation Resource Group could only include ODCRs. Now you can add any type of Capacity Reservation to a Capacity Reservation Resource Group, making it easier to launch EC2 instances across your entire portfolio of reserved capacity.
To use this feature, create a Capacity Reservation Resource Group, add any Capacity Reservation to it, and then target the group in your launch request. When using EC2 Fleet and EC2 Auto Scaling groups, you can also specify your prioritization preferences across reservation types, and configure automatic fall back to EC2 On-Demand capacity when there is no capacity remaining across your reservations.
There are no additional charges for using this feature. With the addition of AWS GovCloud (US) Regions, this feature is now available in all AWS Regions where Capacity Blocks for ML and interruptible ODCRs are supported, excluding China Regions. To get started, see Capacity Reservation Resource Groups and the Capacity Reservations user guide.
Quelle: aws.amazon.com
AWS Data Exports for Cost and Usage Report (CUR) 2.0 and AWS Cost Explorer now amortize the upfront fee for Amazon EC2 Capacity Blocks for ML across the duration of each reservation. You can see the amortized cost of each instance launched into a Capacity Block and the amortized cost of unused capacity, so you can attribute your upfront fee to the workloads that used it and identify capacity that went unused.
Previously, a Capacity Block’s upfront fee appeared as a single charge on the purchase date, making it difficult to see how that cost was spread across usage over the reservation. Now the amortized cost appears alongside your instance usage, so you can allocate GPU costs to the teams, projects, and applications that ran on the reserved capacity. You can also see what share of your reservation went unused and plan future Capacity Block purchases. In CUR 2.0, the amortized costs appear in the reservation_amortized_upfront_fee_for_billing_period, reservation_effective_cost columns, and reservation_net_effective_cost shows the amortized cost after discounts. In Cost Explorer, select the amortized cost view to see Capacity Block costs allocated for the reservation.
Amortization for Capacity Blocks is available at no additional charge in all AWS Regions except the AWS GovCloud (US) Regions and the China Regions. To learn more, see the CUR 2.0 data dictionary and exploring your data using Cost Explorer.
Quelle: aws.amazon.com






