Entertainmentsystem: BMW gibt das Abomodell bei Carplay auf
BMW hat sein Abomodell für die Carplay-Funktion in seinen Fahrzeugen aufgegeben. Nun soll die Nutzung von Apples Carplay teilweise kostenfrei werden. (Carplay, Apple)
Quelle: Golem

BMW hat sein Abomodell für die Carplay-Funktion in seinen Fahrzeugen aufgegeben. Nun soll die Nutzung von Apples Carplay teilweise kostenfrei werden. (Carplay, Apple)
Quelle: Golem

Mit Pocketalk lassen sich 74 Sprachen in beliebiger Kombination übersetzen, was besonders im Urlaub praktisch ist. Im Test erkennt der kleine Übersetzer eingesprochene Sätze gut, allerdings braucht das Gerät angesichts der App-Konkurrenz eigentlich niemand. Ein Test von Tobias Költzsch (Google, Microsoft)
Quelle: Golem

Der IT-Konzern Google erweitert seinen Aktionsradius in das Gesundheitswesen. Mit der Fitbit-Übernahme und Deepmind-Projekten zur Analyse von Patientendaten stellen sich aber Datenschutzfragen. Ein Bericht von Christiane Schulzki-Haddouti (Google, Datenschutz)
Quelle: Golem

On November 25, 2019, AWS announced the release of AWS IoT Greengrass 1.10 allowing developers to package applications into Docker container images and deploy these to edge devices. Deploying and running Docker containers on AWS IoT Greengrass devices enables application portability across development environments, edge locations, and the cloud. Docker images can easily be stored in Docker Hub, private container registries, or with Amazon Elastic Container Registry (Amazon ECR).
Docker is committed to working with cloud service provider partners such as AWS who offer Docker-compatible on-demand container infrastructure services for both individual containers as well as multi-container apps. To make it even easier for developers to benefit from the speed of these services but without giving up app portability and infrastructure choice, Docker Hub will seamlessly integrate developers’ “build” and “share” workflows with the cloud “run” services of their choosing.
“Docker and AWS are collaborating on our shared vision of how workloads can be more easily deployed to edge devices. Docker’s industry-leading container technology including Docker Desktop and Docker Hub are integral to advancing developer workflows for modern apps and IoT solutions. Our customers can now deploy and run Docker containers seamlessly on AWS IoT Greengrass devices, enabling development teams to ship apps faster and accelerate the migration of apps from the data center to the cloud, and now to edge devices,” according to David Messina, EVP Strategic Alliances for Docker.
If you are interested in how to actually deploy a Docker container-based application to an AWS IoT Greengrass core device, AWS’ Danilo Poccia has a great blog that walks developers step-by-step through the process. Developers who are interested in learning more about how to get started with Docker technologies, you can expand your understanding of Docker and Kubernetes with these additional free and paid resources here.
The post AWS IoT Greengrass 1.10 Now Supports Docker Containers appeared first on Docker Blog.
Quelle: https://blog.docker.com/feed/

IBM is like many of its clients when it comes to application modernization. The company faces the same challenges of trying to balance preserving the business value of established investments while remaining agile enough to respond to changing market demands.
Within IBM Global Financing, the financing arm that provides leases and loans to IBM clients and business partners, IBM is always looking for ways to modernize its own portfolio of mission-critical applications. Each application is periodically evaluated to determine how best to evolve, whether it’s a large mainframe application with up to 20 million lines of code or a newer web-based application.
IBM Global Financing thought it had its transformation plan mapped out. However, the advent of Red Hat OpenShift allowed the group to accelerate its plans.
Live and in production in just over one month
With the IBM acquisition of Red Hat in July 2019, several IBM Global Financing squads began experimenting with Red Hat OpenShift to accelerate modernization efforts.
Just over one month later (including two weeks of testing), IBM Global Financing went live with its first application using Red Hat OpenShift on IBM Cloud. The new application, called IBM Global Financing Concierge, is a Watson Assistant-based chatbot that serves up information from back-end heritage systems to help IBM Global Financing employees answer client questions and make decisions with greater speed and accuracy.
A key differentiator of the new Red Hat OpenShift environment is the concept of self-service, which enables developers to put their tested code directly into production. Prior to using Red Hat OpenShift, IBM Global Financing had a complex deployment process involving multiple IBM teams. Now, the development team has full authority to deploy new code end to end.
The quick success with the Watson Assistant chatbot spawned ideas to scale Red Hat OpenShift more broadly across the IBM Global Financing portfolio. IBM Global Financing formed a Red Hat Think Tank to bring together IBM Global Financing architects from around the world who had deep knowledge of the IBM application portfolio, and challenged them to figure out the patterns and migration paths to take advantage of Red Hat OpenShift.
Three lessons learned from adopting Red Hat OpenShift
Using Red Hat OpenShift enabled IBM Global Financing to accelerate in three important ways.
Scalability: IBM Global Financing, like many other parts of IBM, gets massive surges at the end of every quarter. Prior to Red Hat OpenShift, IBM Global Financing had to employ manual efforts to ensure its infrastructure could handle these surges. With Red Hat OpenShift, applications are automatically scaled up or down based on user volumes. IBM Global Financing is able to dynamically scale the performance of its applications to handle surge volume.
Resiliency: If there are problems with the IT infrastructure, Red Hat OpenShift can adjust by dynamically spawning extra containers that enable applications to continue to function without any down time.
Uptime: Red Hat OpenShift has allowed IBM Global Financing to eliminate the eight to 12-hour maintenance windows. Instead of employees scrambling to make deployments work during a weekend, they can apply a blue-green strategy and seamlessly deploy without disrupting users.
The results: Accelerating the application modernization journey
Since July, the IBM Global Financing team has modernized four assets on Red Hat OpenShift and it plans to complete two more by the end of the year. The team will be using modern web front-end applications to tap into mainframe functions through APIs and microservices.
The IBM Global Financing team has accelerated the application modernization journey through the use of Red Hat OpenShift. In just a few months it has redefined the future of innovation across IBM Global Financing IT with Red Hat OpenShift as the model architecture. Learn how Red Hat OpenShift can benefit your business.
IBM Global Financing is the world’s largest IT captive IT financier with an asset base of over $41 billion. With clients in more than 60 countries, and expertise in IT financing, working capital and credit, IBM Global Financing offers flexible payment plans and leasing solutions for IBM software, services and IT infrastructure – including Red Hat OpenShift. Learn more about IBM Global Financing.
The post Lessons learned: How IBM Global Financing tackles application modernization with Red Hat OpenShift appeared first on Cloud computing news.
Quelle: Thoughts on Cloud

Nach gut einem Jahr ist Schluss: Das Busunternehmen Flixbus stellt seine Fernverbindung mit einem Elektrobus wieder ein. Nun sollen andere Antriebe ausprobiert werden. (Elektroauto, Technologie)
Quelle: Golem
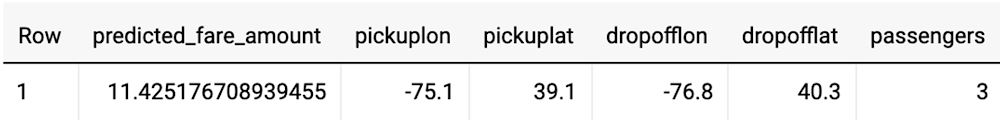
Building machine learning models on structured data commonly requires a large number of data transformations in order to be successful. Furthermore, those transformations also need to be applied at the time of predictions, usually by a different data engineering team than the data science team that trained those models. Keeping the set of transformations consistent between training and inference can be quite hard because of differences in toolsets between the two teams. We’re announcing some new features in BigQuery ML that can help preprocess and transform the data with simple SQL functions. In addition, because BigQuery automatically applies these transformations at the time of predictions, the productionization of ML models is greatly simplified.In a 2003 book on exploratory data mining, Dasu and Johnson observed that 80% of data analysis is spent on cleaning the data. This hasn’t changed with machine learning. Here at Google Cloud, we often observe that in our machine learning projects, a vast majority of the time is spent getting the data ready for machine learning. This includes tasks such as:Writing ETL pipelines to get the data from various source systems into a single place (a data lake)Cleaning the data to correct errors in the data collection or extractionConverting the raw data in the data lakes into a format that makes it possible to join datasets from different sourcesPreprocessing the data to remove outliers, impute missing values, scale numerical columns, embed sparse columns, and moreEngineering new features from the raw data using operations such as feature crosses to allow the ML models to be simpler and converge faster Converting the joined, preprocessed, and engineered data into a format, such as TensorFlow Records, that’s efficient for machine learningReplicating this series of data processing steps in the inference system, which might be written in a different programming languageProductionizing the training and prediction pipelinesTaking advantage of a data warehouse with built-in machine learningA large part of machine learning projects consists of data wrangling and moving data around. Instead of writing custom ETL pipelines for each project to move data into a data lake, and task every ML project with having to understand the data and convert it into a joinable form, we recommend that organizations build an enterprise data warehouse (EDW). If the EDW is cloud-based and offers separation of compute and storage (like BigQuery does), any business unit or even external partner can access this data without having to move any data around. All that’s needed to access the data is an appropriate Identity and Access Management (IAM) role.With this type of EDW, data engineering teams can write the ETL pipelines once to capture changes in source systems and flush them to the data warehouse, rather than machine learning teams having to code them piecemeal. Data scientists can focus on gaining insights from the data, rather than on converting data from one format to another. And if the EDW provides machine learning capabilities and integration with a powerful ML infrastructure such as AI Platform, you can avoid moving data entirely. On Google Cloud, when you train a deep neural network model in BigQuery ML, the actual training is carried out in AI Platform—the linkage is seamless.For example, to train a machine learning model on a dataset of New York taxicab rides to predict the fare, all we need is a SQL query (see this earlier blog post for more details):Productionizing with scheduled queriesOnce the model has been trained, we can determine the fare for a specific ride by providing the pickup and dropoff points:This returns:If you use a cloud-based, modern EDW like BigQuery that provides machine learning capabilities, much of the pain associated with data movement goes away. Note how the query above is able to train an ML model simply off a SELECT statement. This takes care of the first three pain points we identified at the beginning of this article. Productionizing the training of the ML model and carrying out batch predictions is as simple as scheduling the above two SQL queries, thus greatly reducing the pain point associated with productionization. The BigQuery ML preprocessing and transformation features we’re announcing today address the rest of the obstacles, allowing you to carry out data munging effectively, train machine learning models quickly, and carry out predictions without fear of training-serving skew. Preprocessing in BigQuery MLA data warehouse stores the raw data in a way that is applicable to a wide variety of data analysis tasks. For example, dashboards commonly depict data in the data warehouse, and data analysts commonly carry out ad hoc queries. However, a common requirement when training machine learning models is to not train on the raw data, but to filter out outliers, and carry out operations such as bucketizing and scaling in order to improve trainability and convergence.Filtering can be carried out in SQL using a WHERE clause, like this:Once we determine the operations necessary to clean and correct the data, it is possible to create a materialized view:Because materialized views are currently in alpha in BigQuery, you might choose to use a logical view or export the data to a new table instead. The advantage of using a materialized view in the ML context is that you can offload the problem of keeping the data up to date in BigQuery. As new rows are added to the original table, cleaned-up rows will appear in the materialized view.Similarly, scaling can be implemented in SQL. For example, this code does a zero-norm of the four input fields:It is possible to store these scaled data in the materialized view, but because the mean/variance will change over time, we do not recommend doing this. The scaling operation is an example of ML preprocessing operations that require an analysis pass (here, to determine the mean and variance). Because the results of the analysis pass will change as new data is added, it is better to perform preprocessing operations that require an analysis pass as part of your ML training query. Note also that we are taking advantage of convenience UDFs defined in a community GitHub repository.BigQuery provides out-of-the-box support for several common machine learning operations that do not require a separate analysis pass through the data. For example, here’s an example of bucketizing the inputs, knowing the latitude and longitude boundaries of New York:Note that now the fields are categorical and correspond to the bin that the pickup and dropoff points correspond to:Limiting training-serving skew using TRANSFORMThe problem with training a model as shown above is that productionization becomes quite hard. It is no longer as simple as sending the latitudes and longitudes to the model. Instead, we also have to remember and replicate the preprocessing steps in the prediction pipeline:This is why we’re announcing support for the TRANSFORM keyword. Put all your preprocessing operations in a special TRANSFORM clause, and BigQuery ML will automatically carry out the same preprocessing operations during prediction. This helps you limit training-serving skew.The following example shows computing GIS quantities, carrying out the extraction of features from a timestamp, doing a feature cross, and even concatenating the various pickup and dropoff bins (very complex preprocessing, in other words):The prediction code remains very straightforward and simple and does not have to replicate any of the preprocessing steps:Enjoy these new features!Get started:Find a list of preprocessing functions in the documentation.The queries in this post can be found in these two notebooks on GitHub. Try them out from an AI Platform notebook or from Colab.To learn more about BigQuery ML, try this quest in Qwiklabs.Check out chapter 9 of BigQuery: The Definitive Guide for a thorough introduction to machine learning in BigQuery.
Quelle: Google Cloud Platform

Die Telekom wird von Bewerbern für ihre Aktion Wir jagen Funklöcher überrannt. Das war wohl auch die Absicht, trotz zu wenigen Plätzen. (Telekom, Mobilfunk)
Quelle: Golem
November brought lots of news and tips, while cloud practitioners gathered at Next UK. It was, dare we say, a brimming cornucopia of cloud technology. Here’s a quick look at last month’s highlights from around Google Cloud Platform (GCP).Paving the path to cloudIn November, we announced the acquisition of CloudSimple, which provides a secure, dedicated environment to run VMware workloads in the cloud. This makes it easier for businesses running all kinds of apps on VMware to easily migrate those workloads to the cloud. Enterprise customers want simple, flexible ways to migrate their workloads, so we’re excited to bring this option to you.Cloud Run became generally available last month, making it easier for developers to write code for cloud apps in any language, using any binary, in a fully managed way. It’s both natively serverless and based on containers. The announcement covered both Cloud Run, which is a serverless execution environment for running stateless HTTP-driven containers, and Cloud Run for Anthos, which lets you deploy Cloud Run apps to an Anthos GKE cluster on-prem or in Google Cloud. Our Bare-Metal Solution became available at Next UK, giving Google Cloud users another option for easy cloud migration. It’s designed for those on-prem apps that might be holding back cloud migration, such as Oracle databases. Bare Metal Solution consists of all the infrastructure you need to run specialized workloads, connected with a dedicated, low-latency interconnect to all native Google Cloud services. And here’s a wrapup of all the news from the Next UK show.Ever-easier development for cloudDevelopers creating Kubernetes-native apps can now use Skaffold, an automation tool that helps build and manage container images across registries, update Kubernetes manifests, and redeploy apps when code changes. Skaffold is the underlying engine of Cloud Code, and it lets you focus on code changes and see them reflected right away in your cluster. Data science platform Kaggle now integrates with AutoML products to help its more than 3.5 million community members learn and apply machine learning. Google’s AutoML is a suite of products that lets users build custom ML models for problems in data, vision, natural language, structured data and more. This new integration means Kaggle users can access the AutoML SDK directly from Kaggle Notebooks—and start using ML models without a large and intimidating upfront time investment.What’s new on the shelves at Google CloudThe newly introduced Network Intelligence Center can monitor, verify, and optimize your network across the cloud and on-prem data centers. Network operations teams often work with fragmented tools and legacy systems to understand network health, which becomes especially problematic when operating in a multi-cloud environment. Network Intelligence Center is designed for simpler, comprehensive network monitoring, with four modules to start: connectivity tests, network topology, performance dashboard, and firewall metrics and insights.Our Contact Center AI platform became generally available last month, letting you add personalized customer care to your services. Two features of Contact Center AI, Virtual Agent and Agent Assist (which just became generally available), both improve the customer experience while increasing operational efficiency. Virtual Agent lets you offer customers 24/7 access to immediate, conversational self-service, while Agent Assist helps live agents with continuous support in real time, including call transcription and recommendations for workflows and more.That’s a wrap for November! Till next time, keep up with us on Twitter.
Quelle: Google Cloud Platform

Mit dem nun für alle Nutzer freigeschalteten Focus Mode können Nutzer von Android 10 bestimmte Apps ausblenden, um Ablenkungen zu vermeiden. Die Anwendungen werden ausgegraut und können nicht mehr ohne weiteres geöffnet werden, auch Benachrichtigungen werden deaktiviert. (Google, Soziales Netz)
Quelle: Golem






