Kubernetes 1.17: Volume Snapshots Beta and Scheduler changes for stability and extensibility

It’s almost become boring to say that Kubernetes has become boring. This massive open source project has now been in development for so long that the major changes from revision to revision tend to focus on stability, reliability and performance: the sorts of changes that make life easier every day, but do not look so exciting when listed out in a change log.
In truth, nothing in Kubernetes 1.17 will drastically change how you use containers, but they will result in more powerful and dependable architectures, capable of scaling to meet enterprise needs without buckling under pressure. Indeed, Kubernetes is now not only a stable platform for constructing cloud-native infrastructure, it is a stable foundation for the entire ecosystem of services and projects which rely upon it: from Prometheus to Istio to Fluentd to data services layers and Operators.
That’s not to say there aren’t major enhancements in-bound in this release of the platform. One of those new additions, in fact, can directly affect data services – volume snapshots. That new feature is currently in beta with this release, but has been in development for a considerable amount of time.
Volume Snapshots for better backup, data replication and migration
After two years and two alpha implementations, volume snapshots are beta in this release. Volume snapshots allow users to take a point in time snapshot of their data stored on a PersistentVolume and restore it later as a new volume. Snapshots can be used in a wide variety of use cases, from backup to data replication or migration. 
Kubernetes can use the snapshot feature of any storage backend that implements Container Storage Interface (CSI) 1.0, which has more than 50 drivers already. It is not tied to a couple of hard coded storage providers as in the first alpha implementation. 
The snapshot functionality is in a new external snapshot-controller and csi-snapshotter sidecar. Moving these pieces outside of the kube-controller-manager and kubelet allowed for faster development, better separation of concerns, and proof of the extensibility of the Kubernetes platform.

snapshot-controller, deployed during Kubernetes installation, manages the whole lifecycle of volume snapshots, including taking snapshots, binding of pre-existing snapshots, and restoring or deleting snapshots.
csi-snapshotter sidecar, which runs in the same pod as a CSI driver and is deployed by a CSI driver vendor, serves as a bridge between the snapshot controller and the CSI driver and issues CSI requests to the driver, so CSI drivers do not need to worry about Kubernetes internals.

 
Volume snapshots help users to consume abstract storage resources for more efficient backup, data replication, migration and more, but there is still work to do. In Kubernetes 1.17, functionality is limited to taking and restoring snapshots of a single volume, but we already have plans to add new features in future Kubernetes releases to allow application-consistent snapshots using execution hooks or taking snapshots of whole StatefulSets.
Scheduling changes
Over the past several releases the scheduling special interest group (sig-scheduling) put together a proposal to improve the extensibility of the default Kubernetes scheduler. The current extensions mechanism is very limited, as it only allows two operations to be specified, namely Filtering and Prioritizing. Additionally, it requires invoking external HTTP requests, which might significantly extend the scheduling time, and lower the overall throughput of the scheduler. 
The new mechanism will allow plugins to be decoupled from core Kubernetes code, while also allowing easier exchange of information between plugins and the scheduler (such as access to the scheduler cache).

The main extension points depicted in the picture above, are as follows:

Sorting – responsible for sorting the pods in the scheduling queue.
Pre-filtering – used for pre-processing the information about pods being currently processed.
Filtering – the process responsible for matching a pod with a particular set of nodes the pod can run on.
Post-filtering – used mainly for information, such as to update the plugin internal state. Alternatively, it can be used as a pre-scoring step.
Scoring – responsible for ranking nodes, scoring has 2 phases:

Scoring – the actual scoring algorithm
Normalize Scoring – to update the score from the previous phase to fit within [MinNodeScore, MaxNodeScore] range. 

Reserve – an informational point, which plugins can use to update its internal state after scoring completes.
Permit – responsible for approving, denying or delaying a pod.
Pre-binding – performs any work required before binding a pod.
Binding – assigns a pod to an actual node.
Post-binding – another informational point, which plugins can use to update its internal state after scoring completes.

More information about the new scheduling framework is available in the KEP. 
It’s important to note that the new mechanism is meant not only for the extenders. To improve the maintainability of the main scheduler components over the course of the next few releases sig-scheduling will be rewriting all the pre-existing scheduler logic to follow the new scheduler framework. 
Volume snapshots and a new scheduler mechanism are two of many pieces that increase the stability and extensibility of Kubernetes.  
Kubernetes 1.17 is expected to be available for download on GitHub this week. This release of Kubernetes is planned to be integrated into a future release of Red Hat OpenShift.
The post Kubernetes 1.17: Volume Snapshots Beta and Scheduler changes for stability and extensibility appeared first on Red Hat OpenShift Blog.
Quelle: OpenShift
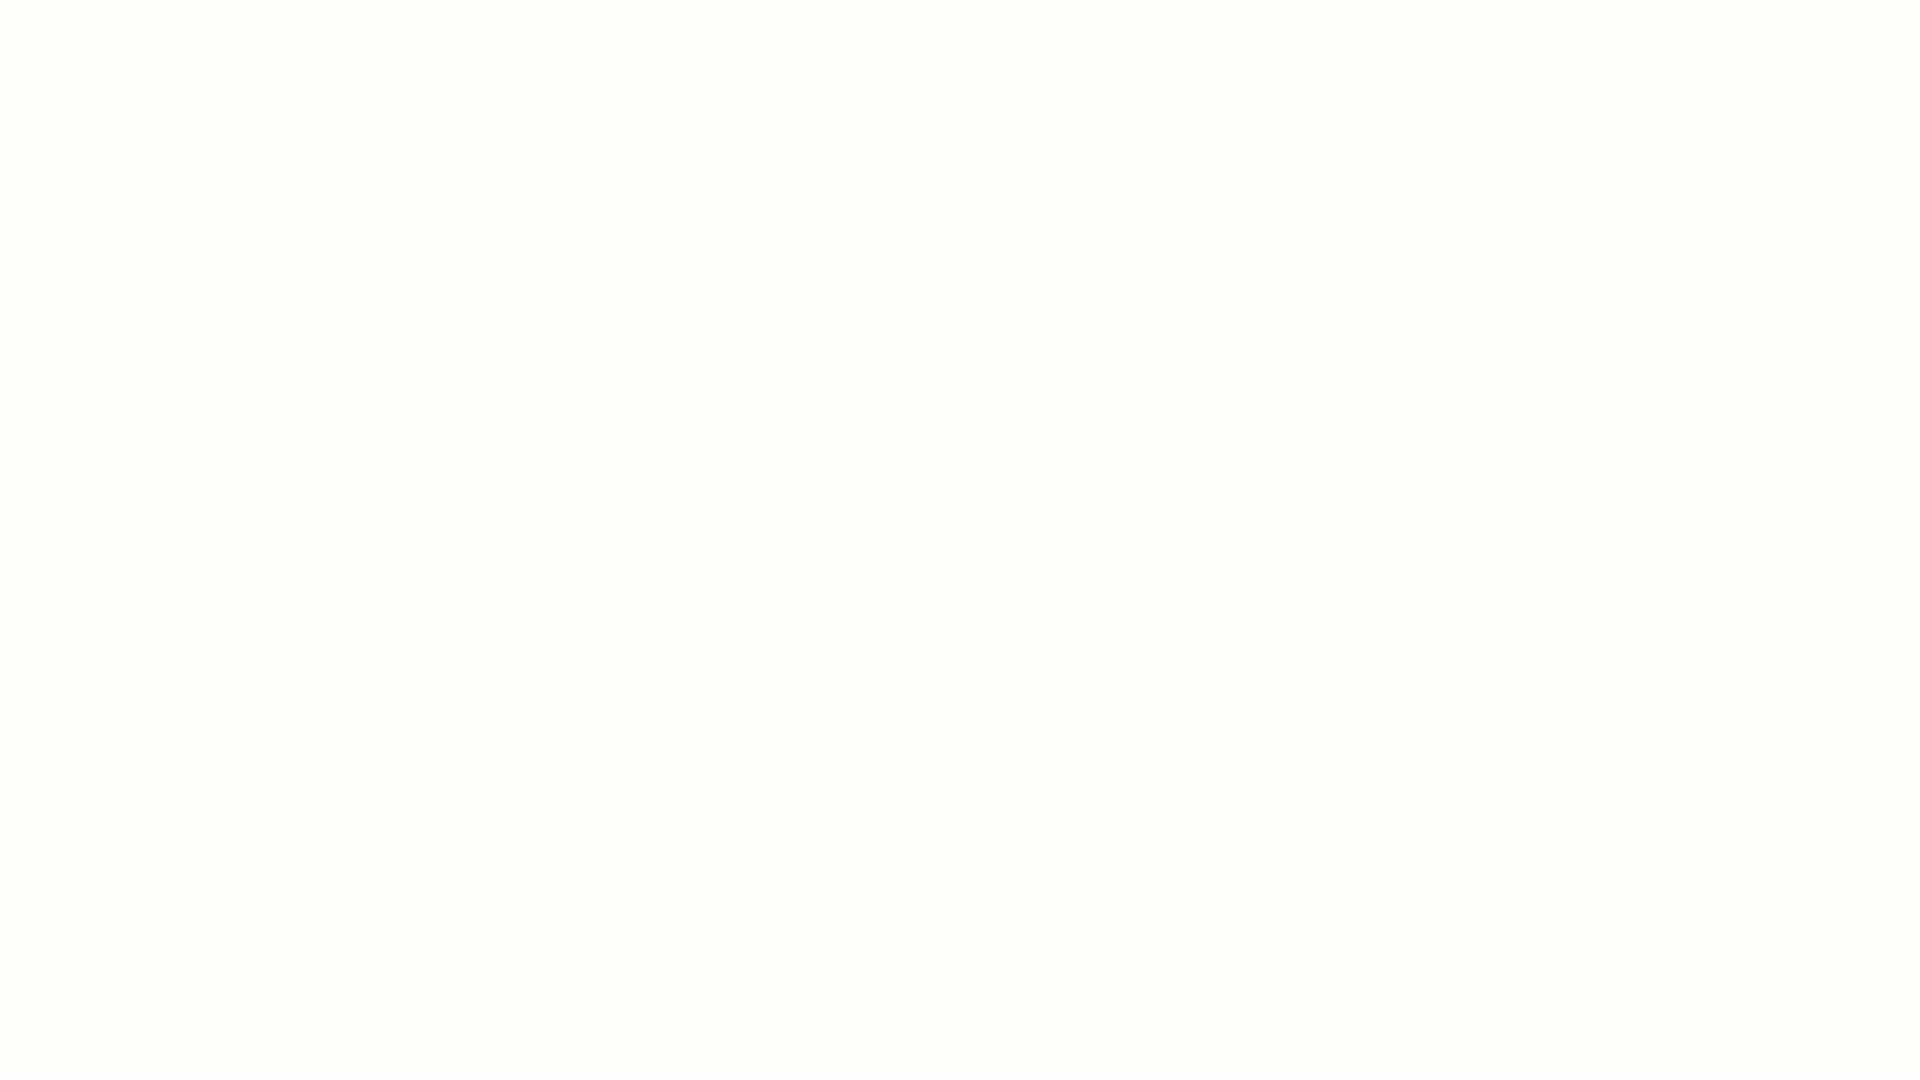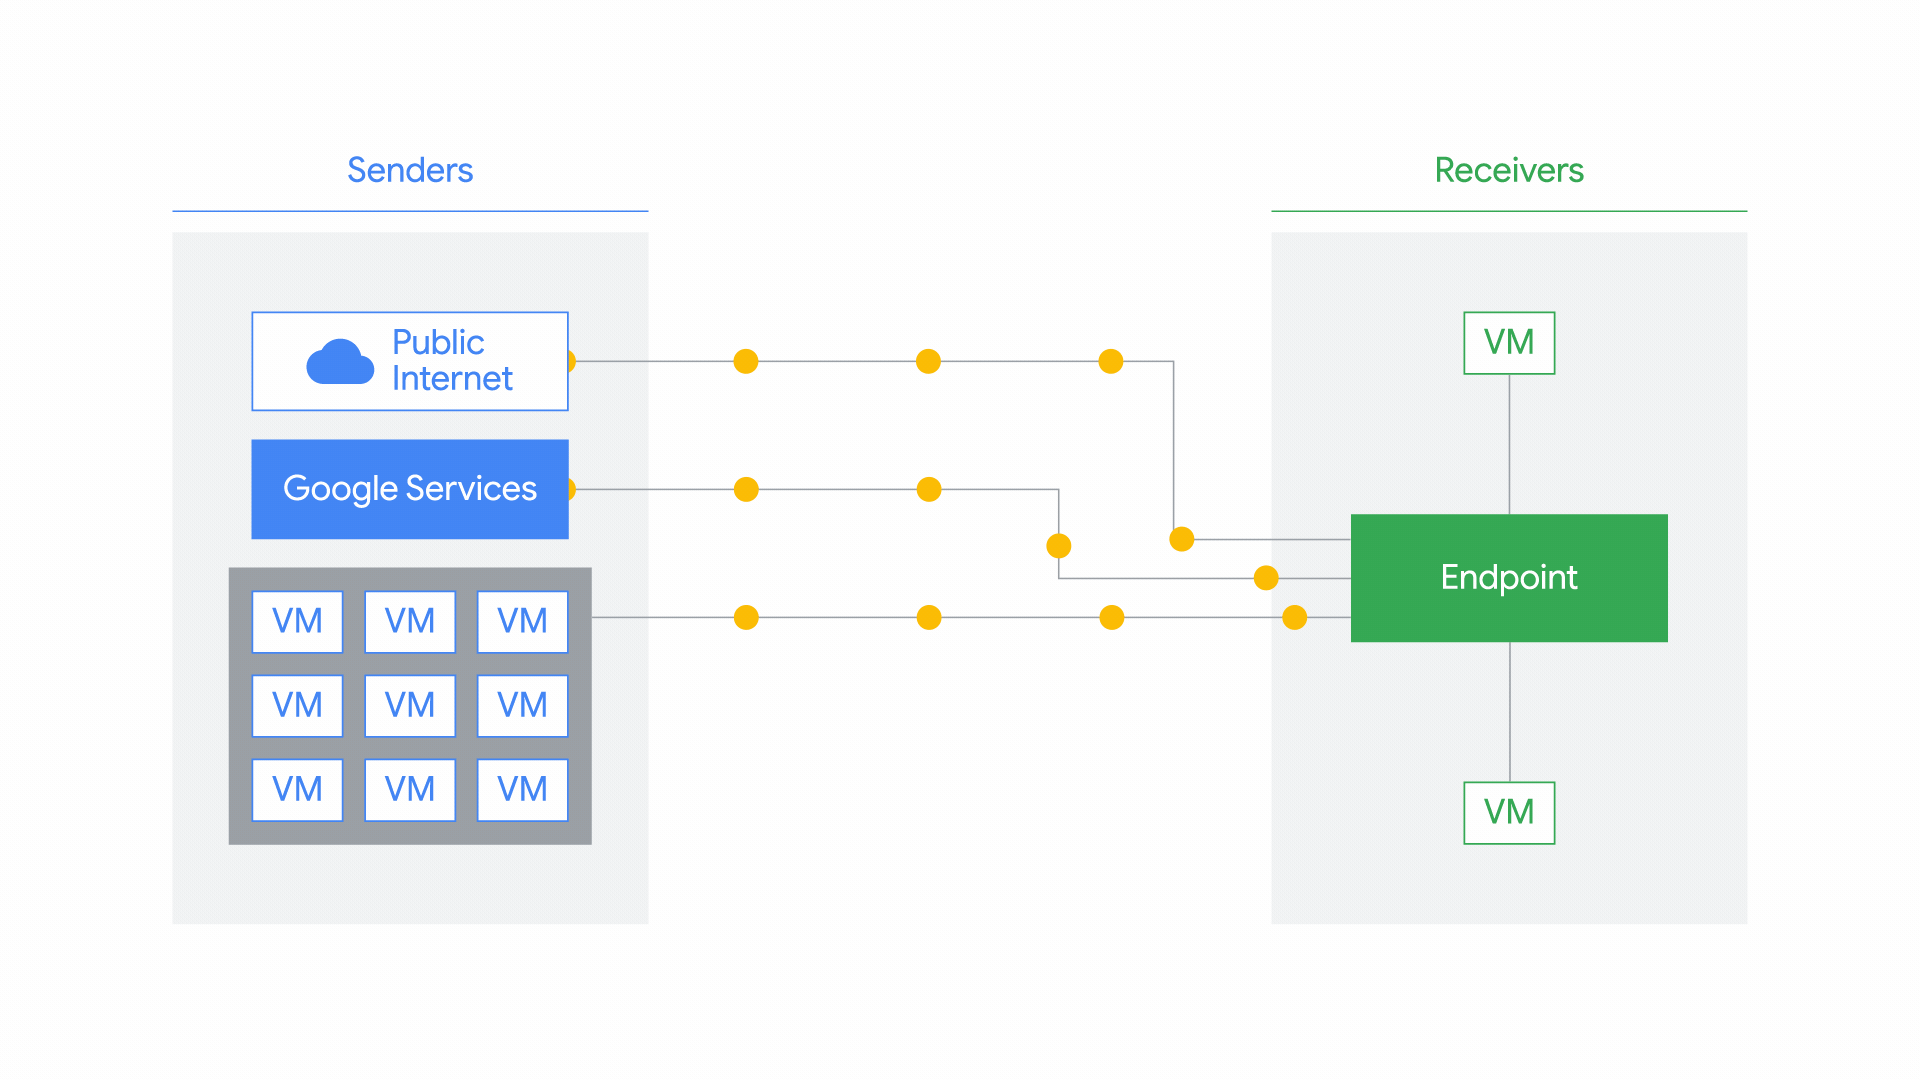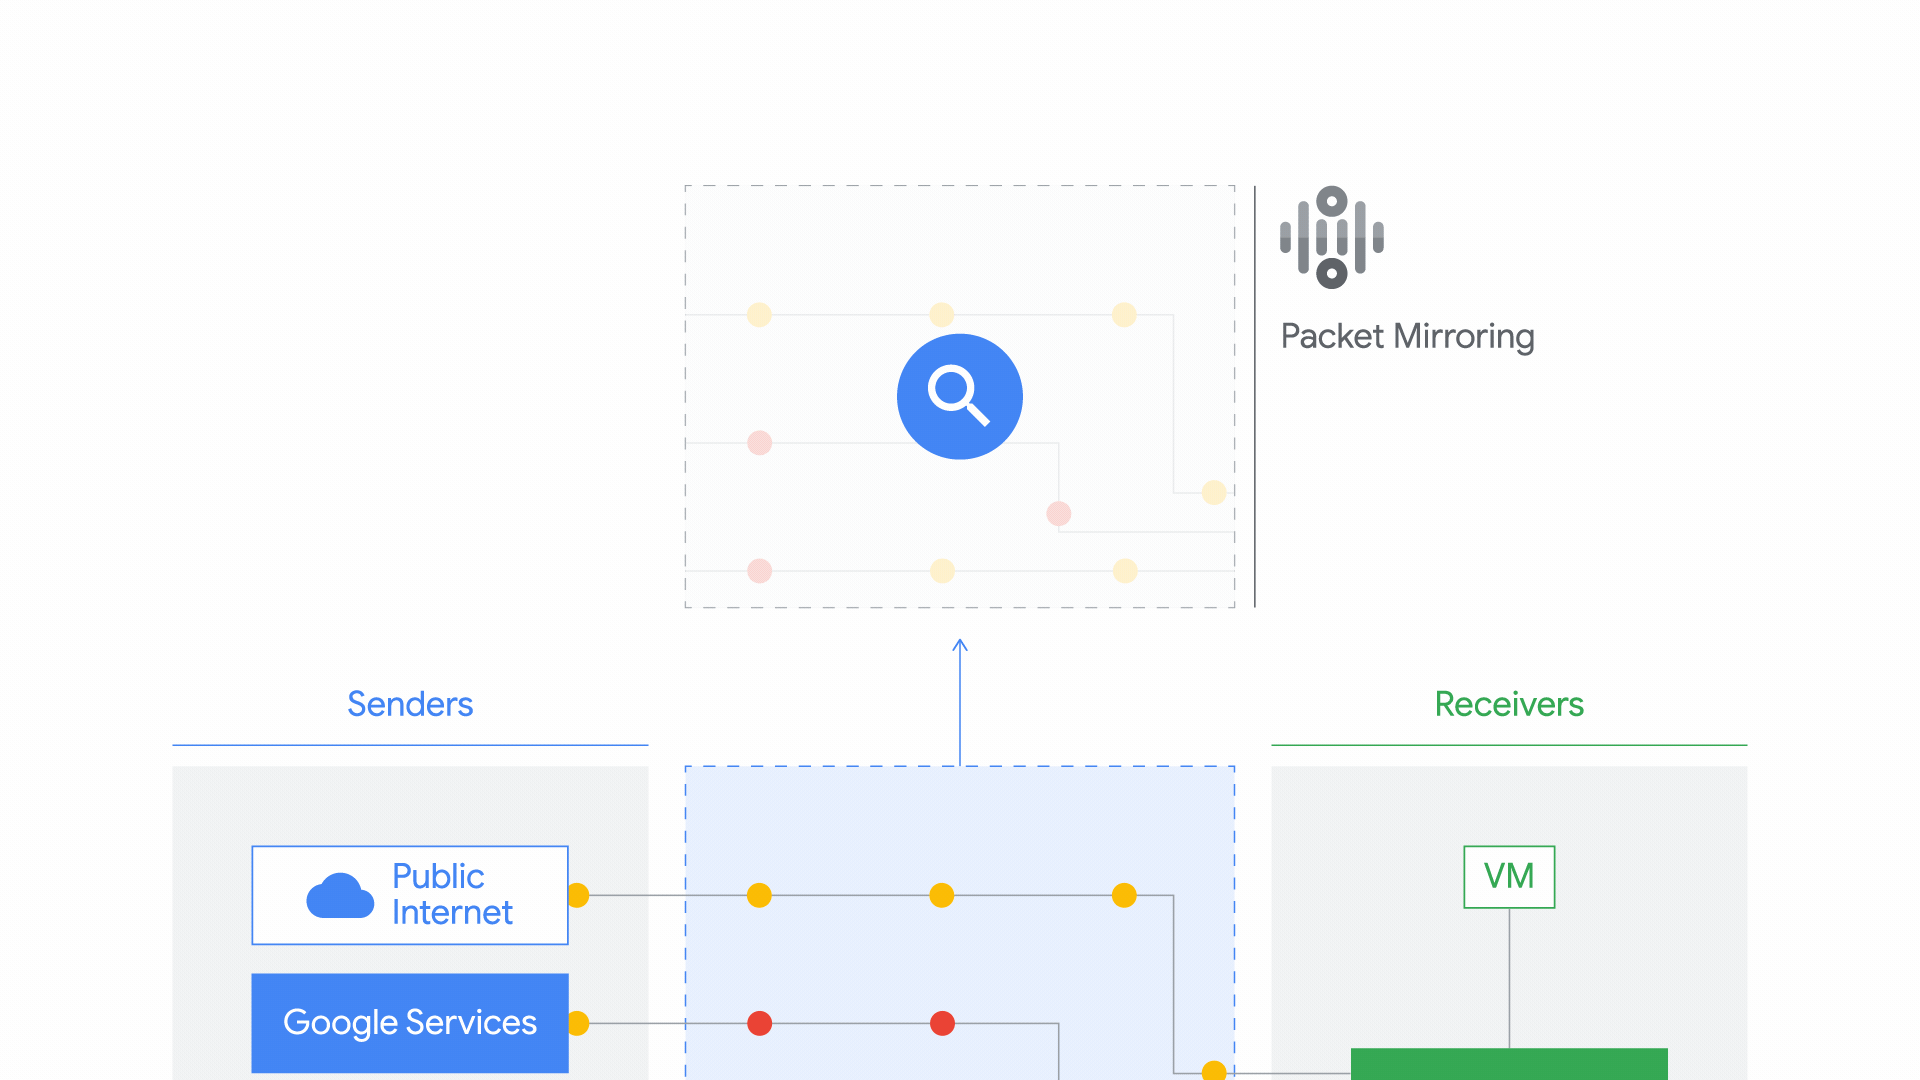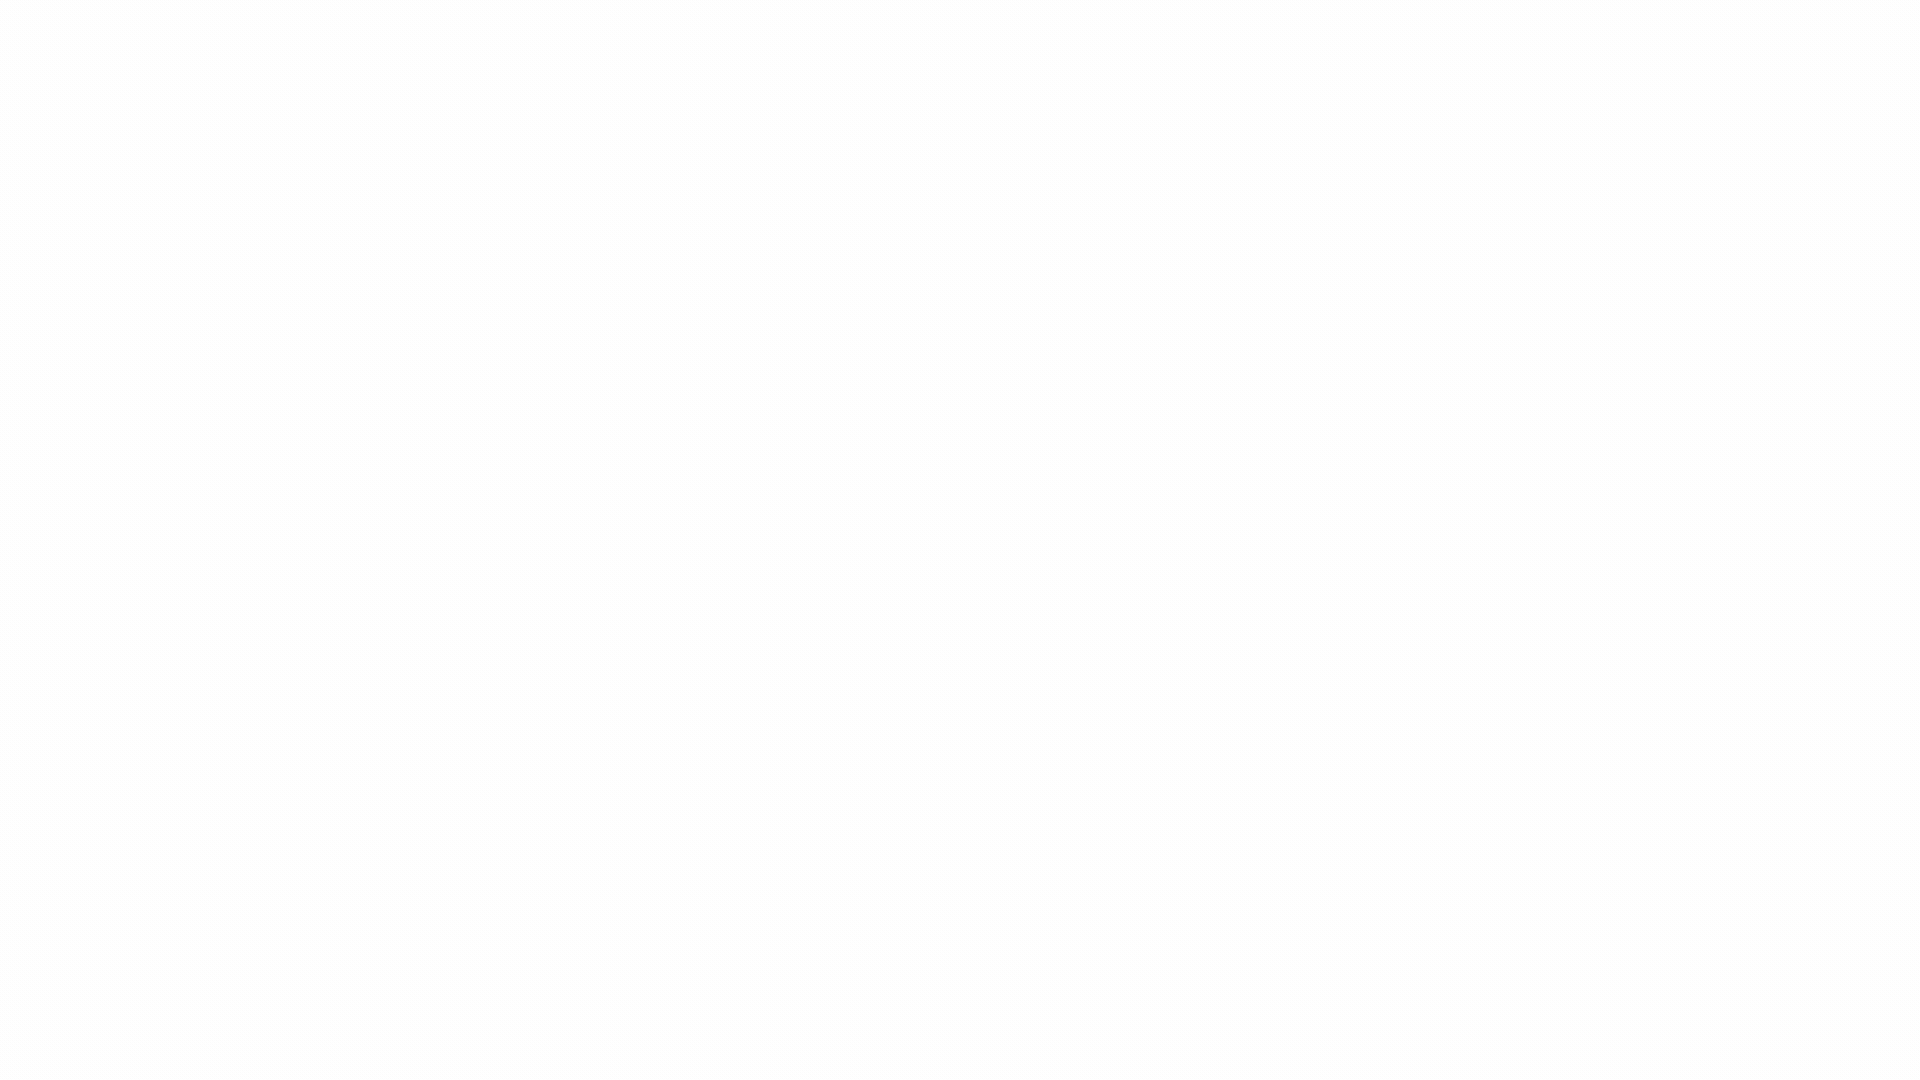
Packet Mirroring: Visualize and protect your cloud network

As networks grow in complexity, network and security administrators need to be able to analyze and monitor network traffic to respond to security breaches and attacks. However, in public cloud environments, getting access to network traffic can be challenging.Many customers use advanced security and traffic inspection tools on-prem, and need the same tools to be available in the cloud for certain applications. Our new Packet Mirroring service is now in beta, and allows you to troubleshoot your existing Virtual Private Clouds (VPCs). With this service, you can use third-party tools to collect and inspect network traffic at scale, provide intrusion detection, application performance monitoring, and better security controls, helping you ensure the security and compliance of workloads running in Compute Engine and Google Kubernetes Engine (GKE). For more, watch this video.For instance, Packet Mirroring lets you identify network anomalies within and across VPCs,  internal traffic from VMs to VMs, traffic between end locations on the Internet and VMs, and also traffic between VMs to Google services in production. Packet Mirroring is available in all Google Cloud Platform (GCP) regions, for all machine types, for both Compute Engine instances and GKE clusters.In short, Packet Mirroring allows you to:Help ensure advanced network security by proactively detecting threats. Respond to intrusions with signature-based detection on predetermined attack patterns, and also identify previously unknown attacks with anomaly-based detection.Improve application availability and performance with the capability to diagnose and analyze what’s going on over the wire instead of relying only on application logs.Support regulatory and compliance requirements by logging and monitoring of transactions for auditing purposes.“Google Cloud’s new Packet Mirroring service accelerates our cloud adoption by giving us the visibility we need to secure our applications and protect our most precious asset, our customers.” – Diane Brown, Senior Director IT Risk Management, Ulta BeautyPacket Mirroring is important for enterprise users from both a security and networking perspective. You can use Packet Mirroring in a variety of deployment setups for different network topologies, such as VPC Network Peering and Shared VPC. In Shared VPC environments, for instance, an organization may have packet mirroring policies and collector backends that were set up by the networking or security team in the host project; the packet mirroring policy, meanwhile, is enabled in the service projects where the developer team runs its applications. This centralized deployment mode improves the ease of use of Packet Mirroring for security and networking teams, at the same time making it transparent to the development teams.Packet Mirroring is natively integrated with Google’s Andromeda SDN fabric. This approach keeps Packet Mirroring performance and management overhead low, as the receiving software appliances running on the collector backends don’t need to perform any decapsulation operation to parse the receive packet mirrored data. Partnering for network securityWe’ve been working with several partners to help us test and develop Packet Mirroring, and have received valuable feedback along the way. Here are our Packet Mirroring partners, and how they work with the tool:Awake Security – Awake Delivers Security with Network Traffic Analysis in Google CloudCheck Point -CloudGuard IaaS Now Integrates with Google Cloud Packet MirroringCisco – Cisco Stealthwatch Cloud and Google Cloud continue partnership to secure customersCorelight – Finding Truth in the Cloud: Google Cloud Packet Mirroring & Corelight Network Traffic AnalysiscPacket Networks – Googling Packets Inside Google CloudExtraHop Networks – ExtraHop Reveal(x) + Google Cloud Packet MirroringFlowmon – Enhancing Network Visibility & Security in Google CloudIxia by Keysight Technologies – Improving cloud visibility with CloudLens and Packet MirroringNetscout – NETSCOUT Extends Its Visibility Without Borders into Google Cloud with Packet MirroringPalo Alto Networks – Announcing the new VM-Series Integration with Google Cloud Packet Mirroring ServiceHelp ensure security and compliance in the cloudOur goal is to give you the right advanced security solutions for connecting your business to Google Cloud. With Packet Mirroring, you can reduce risk, diagnose to ensure the availability of your mission-critical applications and services and meet compliance requirements. Click here to learn more about GCP’s cloud networking portfolio and reach out to us with feedback at  gcp-networking@google.com.
Quelle: Google Cloud Platform

8 production-ready features you’ll find in Cloud Run fully managed

Since we launched Cloud Run at Google Cloud Next in April, developers have discovered that “serverless” and “containers” run well together. With Cloud Run, not only do you benefit from fully managed infrastructure, up and down auto-scaling, and pay-as-you-go pricing, but you’re also able to package your workload however you like, inside a stateless container listening for incoming requests, with any language, runtime, or library of your choice. And you get all this without compromising portability, thanks to its Knative open-source underpinnings. Many Google Cloud customers already use Cloud Run in production, for example, to deploy public websites or APIs, or as a way to perform fast and lightweight data transformations or background operations. “Cloud Run promises to dramatically reduce the operational complexity of deploying containerized software. The ability to put an automatically scaling service in production with one command is very attractive.” – Jamie Talbot, Principal Engineer at Mailchimp.Cloud Run recently became generally available, as both a fully managed platform or on Anthos, and offers a bunch of new features. What are those new capabilities? Today, let’s take a look at what’s new in the fully managed Cloud Run platform.1. Service level agreementWith general availability, Cloud Run now comes with a Service Level Agreement (SLA). In addition, it now offers data location commitments that allow you to store customer data in a specific region/multi-region. 2. Available in 9 GCP regionsIn addition to South Carolina, Iowa, Tokyo, and Belgium, in the coming weeks, you’ll also be able to deploy containers to Cloud Run in North Virginia, Oregon, Netherlands, Finland, and Taiwan, for a total of nine cloud regions.3. Max instancesAuto-scaling can be magic, but there are times when you want to limit the maximum number of instances of your Cloud Run services, for example, to limit costs. Or imagine a backend service like a database is limited to a certain number of connections—you might want to limit the number of instances that can connect to that service. With the max instance feature, you can now set such a limit.Use the Cloud Console or Cloud SDK to set this limit:gcloud run services update SERVICE-NAME –max-instances 424. More secure: HTTPS onlyAll fully managed Cloud Run services receive a stable and secure URL. Cloud Run now only accepts secure HTTPS connection and redirects any HTTP connection to the HTTPS endpoint. But having an HTTPS endpoint does not mean that your service is publicly accessible—you are in control and can opt into allowing public access to your service. Alternatively, you can require authentication by leveraging the “Cloud Run Invoker” IAM role.5. Unary gRPC protocol supportCloud Run now lets you deploy and run unary gRPC services (i.e., non-streaming gRPC), allowing your microservices to leverage this RPC framework. To learn more, read Peter Malinas’ tutorial on Serverless gRPC with Cloud Run using Go, as well as Ahmet Alp Balkan’s article on gRPC authentication on Cloud Run.6. New metrics to track your instancesOut of the box, Cloud Run integrates with Stackdriver Monitoring. From within the Google Cloud Console, the Cloud Run page now includes a new “Metrics” tab that shows charts of key performance indicators for your Cloud Run service: requests per second, request latency, used instance time, CPU and memory.A new built-in Stackdriver metric called container/billable_instance_time gives you insights into the number of container instances for a service, with the billable time aggregated from all container instances.7. LabelsLike the bibs that identify the runners in a race, GCP labels can help you easily identify a set of services, break down costs, or distinguish different environments.You can set labels from the Cloud Run service list page in Cloud Console, or update labels with this command and flag:gcloud run services update SERVICE-NAME –update-labels KEY=VALUE8. Terraform supportFinally, if you practice Infrastructure as Code, you’ll be glad to know that Terraform now  supports Cloud Run, allowing you to provision Cloud Run services from a Terraform configuration. Ready, set, go!The baton is now in your hands. To start deploying your container images to Cloud Run, head over to our quickstart guides on building and deploying your images. With the always free tier and the $300 credit for new GCP accounts, you’re ready to take Cloud Run for a spin. To learn more, there’s the documentation of course, as well as the numerous samples with different language runtimes (don’t miss the “Run on Google Cloud” button to automatically deploy your code). In addition, be sure to check out the community-contributed resources on the Awesome Cloud Run github project. We’re looking forward to seeing what you build and deploy!
Quelle: Google Cloud Platform

Microsoft partner ANSYS extends ability of Azure Digital Twins platform

Digital twins have moved from an exciting concept to reality. More companies than ever are connecting assets and production networks with sensors and using analytics to optimize operations across machinery, plants, and industrial networks. As exact virtual representations of the physical environment, digital twins incorporate historical and real-time data to enable sophisticated spatial analysis of key relationships. Teams can use digital twins to model the impact of process changes before putting them into production, reducing time, cost, and risk.

For the second year in a row, Gartner has identified digital twins as one of the top 10 strategic technology trends. According to Gartner, while 13 percent of organizations that are implementing IoT have already adopted digital twins, 62 percent are in the process or plan to do so. Gartner predicts a tipping point in 2022 when two out of three companies will have deployed at least one digital twin to optimize some facet of their business processes.

This is why we’re excited by the great work of ANSYS, a Microsoft partner working to extend the value of the Microsoft Azure Digital Twins platform for our joint customers. The ANSYS Twin Builder combines the power of physics-based simulations and analytics-driven digital twins to provide real-time data transfer, reusable components, ultrafast modeling, and other tools that enable teams to perform myriad “what-if” analyses, and build, validate, and deploy complex systems more easily.

“Collaborating with ANSYS to create an advanced IoT digital twins framework provides our customers with an unprecedented understanding of their deployed assets’ performance by leveraging physics and simulation-based analytics.” — Sam George, corporate vice president of Azure IoT, Microsoft

Digital twins model key relationships, simplifying design

Digital twins will be first and most widely adopted in manufacturing, as industrial companies invest millions to build, maintain, and track the performance of remotely deployed IoT-enabled assets, machinery, and vehicles. Operators depend on near-continuous asset uptime to achieve production goals, meaning supply-chain bottlenecks, machine failures, or other unexpected downtime can hamper production output and reduce revenue recognition for the company and its customers. The use of digital twins, analytics, business rules, and automation helps companies avoid many of these issues by guiding decision-making and enabling instant informed action.

Digital twins can also simulate a multidimensional view of asset performance that can be endlessly manipulated and perfected prior to producing new systems or devices, ending not just the guesswork of manually predicting new processes, but also the cost of developing multiple prototypes. Digital twins, analytics-based tools, and automation also equip companies to avoid unnecessary costs by prioritizing issues for investment and resolution.

Digital twins can optimize production across networks

Longer-term, companies can more easily operate global supply chains, production networks, and digital ecosystems through the use of IoT, digital twins, and other tools. Enterprise teams and their partners will be able to pivot from sensing and reacting to changes to predicting them and responding immediately based on predetermined business rules. Utilities will be better prepared to predict and prevent accidents, companies poised to address infrastructure issues before customers complain, and stores more strategically set up to maintain adequate inventories.

Simulations increase digital twins’ effectiveness

ANSYS’ engineering simulation software enables customers to model the design of nearly every physical product or process. The simulations are then compiled into runtime modules that can execute in a docker container and integrate automatically into IoT processing systems, reducing the heavy lift of IoT customization.

With the combined Microsoft Azure Digital Twins-ANSYS physics-based simulation capabilities, customers can now:

Simulate baseline and failure data resulting in accurate, physics-based digital twins models.
Use physics-based predictive models to increase accuracy and improve ROI from predictive maintenance programs.
Leverage “what-if analyses” to simulate different solutions before selecting the best one.
Use virtual sensors to estimate critical quantities through simulation.

In addition, companies can use physics-based simulations within the Microsoft-ANSYS platform to pursue high-value use cases such as these:

 Optimize asset performance: Teams can use digital twins to model asset performance to evaluate current performance versus targets, identifying, resolving, and prioritizing issues for resolution based on the value they create.
 Manage systems across their lifecycle: Teams can take a systems approach to managing complex and costly assets, driving throughput and retiring systems at the ideal time to avoid over-investing in market-lagging capabilities.
 Perform predictive maintenance: Teams can use analytics to determine and schedule maintenance, reduce unplanned downtime and costly break-fix repairs, and perform repairs in order of importance, which frees team members from unnecessary work.
 Orchestrate systems: Companies will eventually create systems of intelligence by linking their equipment, systems, and networks to orchestrate production across plants, campuses, and regions, attaining new levels of visibility and efficiency.
 Fuel product innovation: With rapid virtual prototyping, teams will be able to explore myriad product versions, reducing the time and cost required to innovate products, decreasing product failures, and enabling the development of customized products.
 Enhance employee training: Companies can use digital twins to conduct training with employees, improving their effectiveness on the job while reducing production design errors due to human error.
 Eliminate physical constraints: Digital twins eliminate the physical barriers to experimentation, meaning users can simulate tests and conditions for remote assets, such as equipment in other plants, regions, or space.

Opening up new opportunities for partners

According to Gartner, more than 20 billion connected devices are projected by 2020 and adoption of IoT and digital twins is only going to accelerate—in fact, MarketsandMarkets™ estimates that the digital twins market will reach a value of $3.8 billion in 2019 and grow to $35.8 billion by 2025. Our recent IoT Signals research found that 85 percent of decision-makers have already adopted IoT, 74 percent have projects in the “use” phase, and businesses expect to achieve 30 percent ROI on their IoT projects going forward. The top use case participants want to pursue is operations optimization (56 percent), to reap more value from the assets and processes they already possess. That’s why digital twins is so important right now because it provides a framework to accomplish this goal with greater accuracy than was possible before.

“As industrial companies require comprehensive field data and actionable insights to further optimize deployed asset performance, ecosystem partners must collaborate to form business solutions. ANSYS Twins Builder’s complementary simulation data stream augments Azure IoT Services and greatly enhances its customers’ understanding of asset performance.”—Eric Bantegnie, vice president and general manager at ANSYS

Thanks to Microsoft partners like ANSYS, companies are better equipped to unlock productivity and efficiency gains by removing critical constraints, including physical barriers, from process modeling. With tools like digital twins, companies will be limited only by their own creativity, creating a more intelligent and connected world where all have more opportunities to flourish.

Learn more about Microsoft Azure Digital Twins and ANSYS Twin Builder.
Quelle: Azure

Introducing maintenance control for platform updates

Today we are announcing the preview of a maintenance control feature for Azure Virtual Machines that gives more control to customers with highly sensitive workloads for platform maintenance. Using this feature, customers can control all impactful host updates, including rebootless updates, for up to 35 days.

Azure frequently updates its infrastructure to improve the reliability, performance, and security, or to launch new features. Almost all updates have zero impact on your Azure virtual machines (VMs). When updates do have an effect, Azure chooses the least impactful method for updates:

If the update does not require a reboot, the VM is briefly paused while the host is updated, or it's live migrated to an already updated host. These rebootless maintenance operations are applied fault domain by fault domain, and progress is stopped if any warning health signals are received.
In the extremely rare scenario when the maintenance requires a reboot, the customer is notified of the planned maintenance. Azure also provides a time window in which you can start the maintenance yourself, at a time that works for you.

Typically, rebootless updates do not impact the overall customer experience. However, certain very sensitive workloads may require full control of all maintenance activities. This new feature will benefit those customers who deploy this type of workload.

Who is this for?

The ability to control the maintenance window is particularly useful when you deploy workloads that are extremely sensitive to interruptions running on an Azure Dedicated Host or an Isolated VM, where the underlying physical server runs a single customer’s workload. This feature is not supported for VMs deployed in hosts shared with other customers.

The typical customer who should consider using this feature requires full control over updates because while they need to have the latest updates in place, their business requires that at least some of their cloud resources must be updated with zero impact on their own schedule.

Customers like financial services providers, gaming companies, or media streaming services using Azure Dedicated Hosts or Isolated VMs will benefit by being able to manage necessary updates without any impact on their most critical Azure resources.

How does it work?

You can enable the maintenance control feature for platform updates by adding a custom maintenance configuration to a resource (either an Azure Dedicated Host or an Isolated VM). When the Azure updater sees this custom configuration, it will skip all non-zero-impact updates, including rebootless updates. For as long as the maintenance configuration is applied to the resource, it will be your responsibility to determine when to initiate updates for that resource. You can check for pending updates on the resource and apply updates within the 35-day window. When you initiate an update on the resource, Azure applies all pending host updates. A new 35-day window starts after another update becomes pending on the resource. If you choose not to apply the updates within the 35-day window, Azure will automatically apply all pending updates for you, to ensure that your resources remain secure and get other fixes and features.

Things to consider

You can automate platform updates for your maintenance window by calling “apply pending update” commands through your automation scripts. This can be batched with your application maintenance. You can also make use of Azure Functions and schedule updates at regular intervals.
Maintenance configurations are supported across subscriptions and resource groups, so you can manage all maintenance configurations in one place and use them anywhere they're needed.

Getting started

The maintenance control feature for platform updates is available in preview now. You can get started by using CLI, PowerShell, REST APIs, .NET, or SDK. Azure portal support will follow.

For more information, please refer to the documentation: Maintenance for virtual machines in Azure.

FAQ

Q: Are there cases where I can’t control certain updates? 

A:  In case of a high-severity security issue that may endanger the Azure platform or our customers, Azure may need to override customer control of the maintenance window and push the change. This is a rare occurrence that would only be used in extreme cases, such as a last resort to protect you from critical security issues.

Q: If I don’t self-update within 35-days what action will Azure take?

A:  If you don’t execute a platform update within 35-days, Azure will apply the pending updates on a fault domain by fault domain basis. This is done to maintain security and performance, and to fix any defects.

Q: Is this feature supported in all regions?

A:   Maintenance Control is supported in all public cloud regions. Currently we don't support gov cloud regions, but this support will come later.
Quelle: Azure






