Strafverfolgung: Google rückt IP-Adressen von Suchanfragen heraus
Es ist eine besondere Art der Vorratsdatenspeicherung: Google hilft US-Behörden umfangreich bei der Suche nach Verdächtigen. (Datenschutz, Smartphone)
Quelle: Golem

Es ist eine besondere Art der Vorratsdatenspeicherung: Google hilft US-Behörden umfangreich bei der Suche nach Verdächtigen. (Datenschutz, Smartphone)
Quelle: Golem
Today, we are excited to announce a collaboration between Google Cloud Healthcare & Life Sciences and the Broad Institute of MIT and Harvard to provide free access to one of the world’s most comprehensive public genomic datasets, the Genome Aggregation Database (gnomAD). gnomAD brings together data from numerous large-scale sequencing projects, including population and disease-specific genetic studies. With more than 241 million unique short human genetic variants and 335,000 structural variants observed in more than 141,000 healthy adult individuals across a diverse range of genetic ancestry groups, this dataset is a near-ubiquitous resource for human genetics research and clinical variant interpretation. It is used in clinical genetic diagnostic pipelines worldwide.gnomAD data is hosted in several formats to address a broad range of biomedical and healthcare use cases. This data is available in Hail-formatted tables and Variant Call Format (VCF) files in Google Cloud Storage. This data is also made available in BigQuery as part of the Public Datasets Program. Users receive 1TB of free BigQuery processing every month, which can be used to run queries on this public dataset. Google Cloud users can securely access this data in any of these formats across all Google Cloud regions through their bioinformatics pipelines on Google Cloud without paying egress charges.To make gnomAD available in BigQuery, the Google Cloud team used Variant Transforms to ingest VCF files. Once ingested, the variants were sharded to split the output tables by chromosome. In addition, we utilized integer range partitioning and clustering to reduce the cost of queries. This work enables researchers to explore gnomAD quickly and efficiently, without needing to request or pay for dedicated cloud compute resources. By querying a smaller targeted genomic region, query costs are expected to be reduced significantly compared to querying the whole dataset. This application of Variant Transforms has been leveraged by partners and customers like the Mayo Clinic and Color Genomics to accelerate their genomics research. More information on using gnomAD in BigQuery is available in this tutorial.The data in the Google Cloud Storage bucket also includes standard truth sets used to assess and validate variant calls, data from the Broad Institute’s papers in Nature, interval lists, and other annotation resources.To access gnomAD on Google Cloud, explore the documentation here. Files can also be browsed and downloaded using the Cloud Console or the command line tool gsutil. After installing gsutil, start browsing with $ gsutil ls gs://gcp-public-data–gnomad.Explore additional Healthcare and Life Sciences dataset offerings on Google Cloud here.Related ArticleGenomics analysis with Hail, BigQuery, and DataprocTry data analytics for genomics research in the cloud using BigQuery, Dataproc and Hail for fast large-scale research.Read Article
Quelle: Google Cloud Platform

As a developer building a new application, you want to focus on writing code, not containerizing it. And if you already use containers, you know that creating a good, secure container image can be complicated and time-consuming. Today we’re launching broad support across Google Cloud for buildpacks—an open-source technology that makes it fast and easy for you to create secure, production-ready container images from source code and without a Dockerfile.At the center of this release are a collection of open-source buildpacks and builders. Based on the CNCF buildpacks v3 specification, these buildpacks produce container images that follow best practices and are suitable for running on all of our container platforms: Cloud Run (fully managed), Anthos, and Google Kubernetes Engine (GKE). These buildpacks are production hardened and tested; they have been used at scale powering most builds for App Engine and Cloud Functions since March. Using buildpacksYou can use buildpacks in several ways: First, if you haven’t already fully adopted containerization, buildpacks are a way to use the latest container runtime and delivery platforms. They’re also useful for quick projects when you don’t have time to properly vet and customize a Dockerfile that you might find in the wild.You can try out the Google Cloud buildpacks right now. To do a complete source-to-deploy with a Go project, Buildpacks, and Cloud Run, just click on the ‘Run on Google Cloud’ button.To try Buildpacks locally with an application, install Docker and the ’pack’ CLI tool then run:(Go, Java, Node, Python, and .Net are supported. They might need additional configuration to build properly.)Or, if you don’t want to install anything, you can run a buildpack based build in Cloud Build, and then easily deploy to Cloud Run:How do buildpacks work?Buildpacks are distributed and executed in OCI images called builders. Each builder can have one or more buildpacks. The builder of the Google Cloud buildpacks that we are releasing today is available gcr.io/buildpacks/builder. Builders have the ability to auto-detect the language of your source code. This is accomplished by a `bin/detect` executable in the buildpack. The detection scripts are invoked in a particular order and stop once an appropriate number of buildpacks have opted in to the build. For example, most Node.js buildpacks look for the presence of a packages.json file. You can also manually specify which buildpack to use, thereby skipping the auto-detection step.Once the buildpack has been selected, its `bin/build` is executed. This script transforms your source code into an executable artifact, typically performing actions such as installing dependencies or compiling code. The output of this build step is then added on top of a “run” OCI base image, creating a final container image which can then be run on the platform of your choice.Google Cloud buildpacksGoogle Cloud’s buildpacks are optimized for security, speed, and reusability. They allow you to build both apps and functions into container images. When building a function, they package it using Google Cloud’s open-source Functions Framework.Google Cloud buildpacks use a managed base Ubuntu 18.04 base image that is regularly scanned for security vulnerabilities; any detected vulnerabilities are automatically patched. This ensures that when you build your source code with buildpacks, it will be as secure as possible.Google Cloud buildpacks can also be customized with additional system packages or to meet your development team’s particular needs. The buildpacks themselves are all written in Go. Rather than create a single buildpack for each language, you can combine smaller, modular buildpacks together. For example, there is an NPM buildpack which (unsurprisingly) installs node packages. This is of course used for Node.js builds, but it can also be used for other languages and frameworks that use NPM packages (Ruby on Rails, for example).Broad support in Google CloudIn addition to the open-source buildpacks, we support buildpacks across a range of our products:Cloud Build now natively supports buildpacks via the gcloud CLI tool: gcloud alpha builds submit –pack image=gcr.io/[project-id]/my-app. (see documentation)Cloud Run – Continuous deployment to Cloud Run (via Cloud Build triggers) can be configured to use buildpacks (see documentation). App Engine – Buildpacks are now the default mechanism for source deployments on most newer App Engine runtimes. Notably, buildpacks enable source-based Java deployments (previously only JAR-based deploys were supported). All newly released runtimes will use buildpacks moving forward. Cloud Functions – Like App Engine, buildpacks are the default mechanism for building deployed functions.Cloud Code – Cloud Code IDEs can build your source code with buildpacks and deploy the resulting containers directly to GKE. Skaffold supports live development with buildpacks. As you edit your source code, buildpacks can continuously re-build your app, allowing you to preview changes in a local instance of your app.Cloud Shell – The pack CLI tool is now installed in Cloud Shell by default. This allows you to execute buildpacks in Cloud Shell without installing any additional packages.Get started todayLearn more about Google Cloud’s buildpacks on the GitHub repository. Then, deploy an app sample using buildpacks in the click of a button.
Quelle: Google Cloud Platform

Was am 9. Oktober 2020 neben den großen Meldungen sonst noch passiert ist, in aller Kürze. (Kurznews, Google)
Quelle: Golem

Die Fördermilliarden für die IT in Schulen und Glasfaser kommen nur langsam an. Die Behörden haben Engpässe. (Schulen, Glasfaser)
Quelle: Golem

Interessierte Nutzer können das Linux-Phone durch eine Abstimmung über Lieblingsapps zur Umsetzung unterstützen. (librem5, Linux)
Quelle: Golem

Jetbrains veröffentlicht die Roadmap und gibt dabei einen Ausblick auf die geplanten Änderungen. (Kotlin, Java)
Quelle: Golem

Die Meinungen darüber, ob es Roaming in den 4G-Netzen geben muss, gehen weit auseinander. 1&1 Drillisch bleibt hier energisch, ohne ein 5G-Netz zu haben. (Drillisch Online, Telefónica)
Quelle: Golem
As your website grows, it becomes challenging for visitors to find exactly what they need. Being prolific and publishing lots of posts and pages is a net positive for engaging and growing your audience, but it also means visitors may be more likely to find content that isn’t relevant to their interests.
This is where Jetpack Search comes into the picture: It turns your website into a place where visitors can search, refine their results, and find the specific content and products that interest them.
Built by the same team that created WordPress.com, Jetpack Search is a powerful search solution backed by Elasticsearch (an open source search platform), Jetpack Stats, and our globally distributed data centers — the very same ones that keep your WordPress.com website up, running, and secure day in and day out. Jetpack Search uses multiple technologies to build a modern search experience that improves website engagement. You can now add Jetpack Search to your WordPress.com site with just a few clicks.
What makes Jetpack Search better than regular search?
A modern search experience combines great result rankings with a fast and intuitive user interface. Most WordPress themes can’t do this yet, because the default WordPress search function offers only basic options to show the most relevant content to viewers.
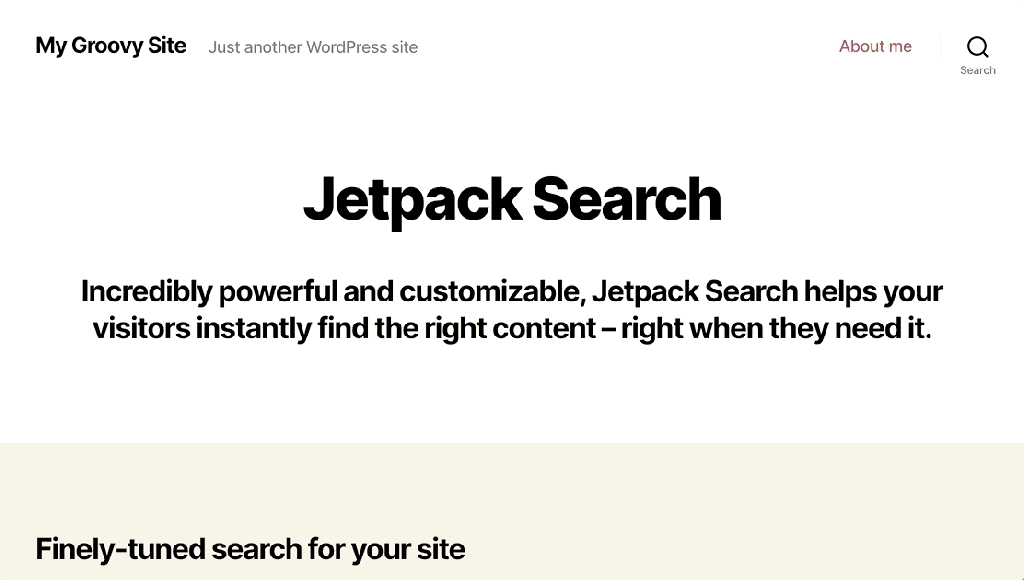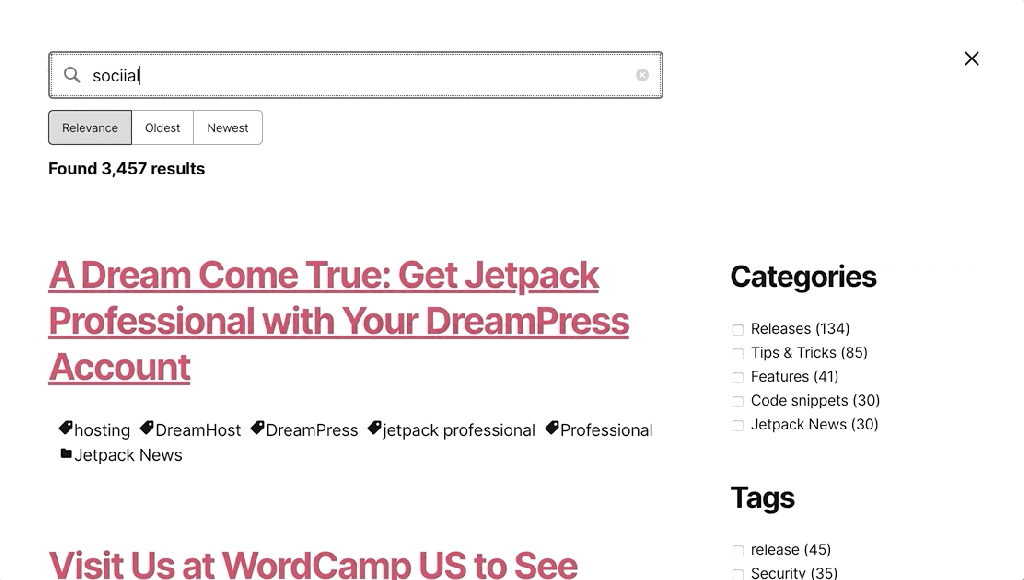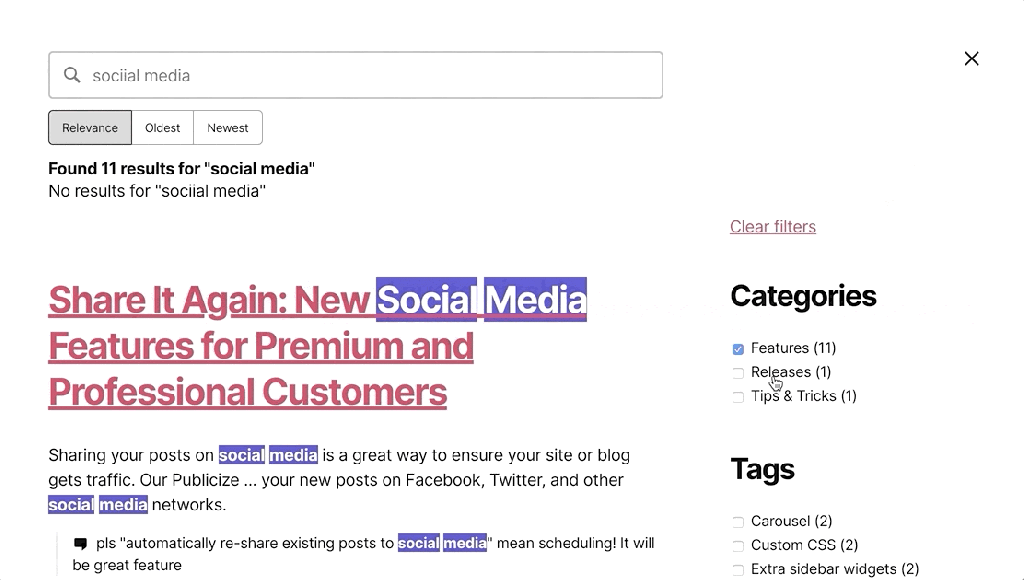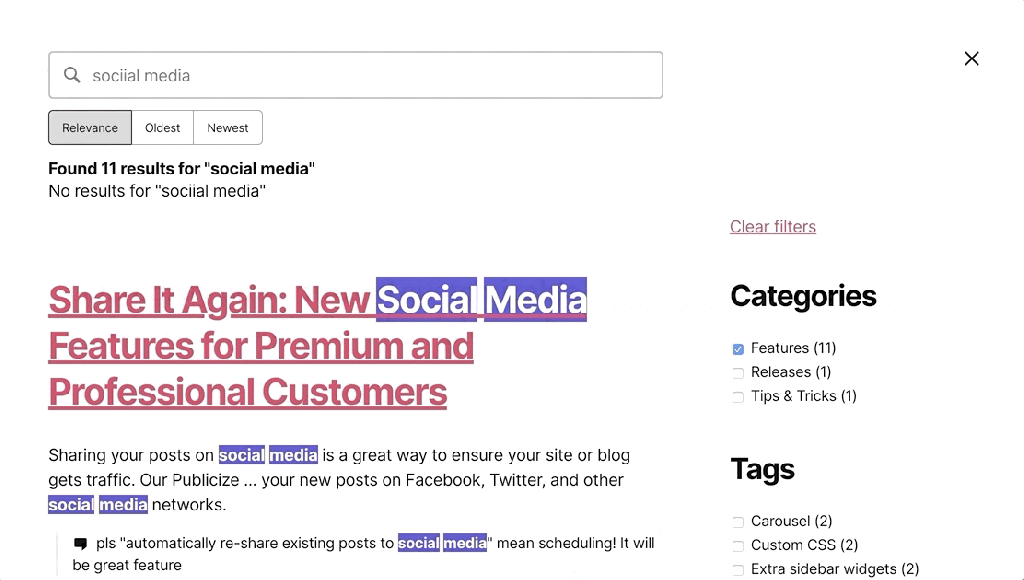
Jetpack Search combines modern ranking algorithms with your traffic stats so that the best results will float to the top and engage your visitors. Our search algorithms work well with numerous languages and provide custom handling for 29 of the most widely used languages in the world. A large percentage of searches contain typos or spelling errors, but Jetpack Search instantly corrects the search query when there are no matches — so if a potential customer is looking for, say, collectables, they will still see the most popular collectibles you offer on your online store. Any changes you make to your site will be reflected in your search results within a few minutes.
Great algorithms are not enough, though. Jetpack Search displays results instantly, as your readers type into the search box. It does its magic equally well on both mobile devices and desktop computers, and in any theme — even those without widget areas. As the user refines their search terms or filters the results, Jetpack Search continues to update the results instantly. The user’s search terms will be highlighted in the results, which they will be able to narrow down further with displayed filters.
Instant search, spelling correction, and filtering on TwentyTwenty theme.
All of these benefits come together to provide a compelling and beautiful user experience that will encourage people to stay on your site longer.
Get Started with Jetpack Search
We wanted to make Jetpack Search accessible for website owners of all stripes, from those who publish a personal blog to owners of thriving online stores. So we’re offering this new add-on at a price that takes into account how many searchable items — posts, pages, products, and custom post types — your site contains.
Record LimitPrice Per Month100$51,000$1010,000$25100,000$601,000,000$200Over one million$200 per million
All purchases are fully refundable for 30 days. Even better, when you add Jetpack Search to your site with an annual subscription, you get two months free — so you only pay for 10 months every year. When your purchase renews after a year, the price will automatically adjust based on the number of items in your search index.
We think you’ll love Jetpack Search — but more importantly, your site visitors will love it too.
Follow the link below to purchase your Jetpack Search subscription. Once you buy it, Jetpack Search will automatically be enabled for your site. You can then customize the colors, filtering, and other details if you’d like — though the out-of-the-box settings work great, too.
Get Jetpack Search
Read about how we made Jetpack Search
Quelle: RedHat Stack
In yesterday’s blog about improvements to the end-to-end Docker developer experience, I was thrilled to share how we are integrating security into image development, and to announce the launch of vulnerability scanning for images pushed to the Hub. This release is one step in our collaboration with our partner Snyk where we are integrating their security testing technology into the Docker platform. Today, I want to expand on our announcements and show you how to get started with image scanning with Snyk.
In this blog I will show you why scanning Hub images is important, how to configure the Hub pages to trigger Snyk vulnerability scans, and how to run your scans and understand the results. I will also provide suggestions incorporating vulnerability scanning into your development workflows so that you include regular security checkpoints along each step of your application deployment.
Software vulnerability scanners have been around for a while to detect vulnerabilities that hackers use for software exploitation. Traditionally security teams ran scanners after developers thought that their work was done, frequently sending code back to developers to fix known vulnerabilities. In today’s “shift-left” paradigm, scanning is applied earlier during the development and CI cycles but most organizations have to build their own automation to connect the scan functions to the CI instruments. Yesterday’s release changes this equation and provides built in automated scanning as an integral step within the CI cycle.
Now you decide which repos to configure for vulnerability scanning to trigger a scan every time you push an image into that repo, and when the scan is completed you can view the scan results in your Hub account. Vulnerability data is organized in the Hub in several different layers: vulnerability severity summary, list of all vulnerabilities, and detailed information about a specific security flaw. The scanning function is available for Pro and Team users, creating a simple method of validation for each image update.
How It Works
Step 1 – Enable Repo Scanning Functions
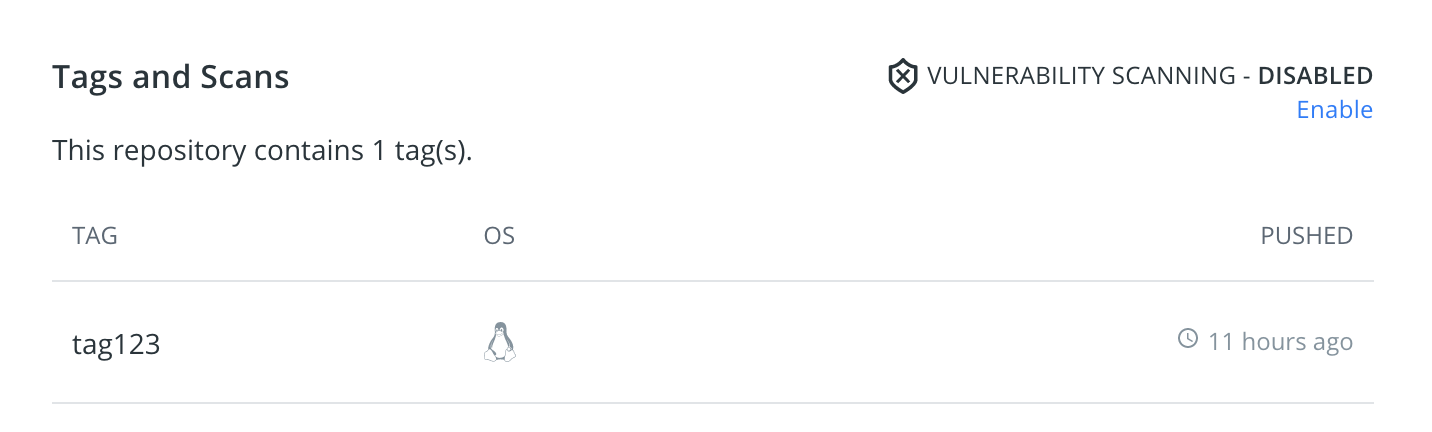
Enabling repo scanning is a simple, single-click process, but the default setting is for disabled scanning so make sure you turn it on.
Scanning is separately configurable for each repo so you can decide how you want to start incorporating scanning into your team collaboration cycles and application build steps. You can adopt these processes on a smaller scale and over time expand them to the rest of your organization. Conversely, if you decide that the repo that you have been scanning is no longer an active part of your development, you can use the same single-click option to disable scanning.
Step 2 – Run your scans
Once you enable scanning, each time that you push a tagged image into that repo you will automatically trigger a scan.
Step 3 – View the Results
After vulnerability scanning is completed, you can go to the repo page in the Hub to view the scan results. General Tab of the Hub Repo page includes results summary for all the repo image scans which will show the number of high, medium and low vulnerabilities identified during each scan.
Clicking on the Vulnerabilities section of a specific tag brings you to the Vulnerability Tab for that tag, which shows the total number of vulnerabilities identified during the scan. Vulnerabilities Tab includes the scan severities summary and shows you the full list of scan vulnerabilities.
The vulnerability list is organized so that you will see the most critical vulnerabilities first. The higher severity issues are prioritized above the lower ones, and the same severity vulnerabilities are organized in the descending order for the Common Vulnerability Scoring System (CVSS) . CVSS scores are a published standard for assigning numerical value to the severity of software vulnerabilities. Vulnerability list also includes Common Vulnerabilities and Exposures (CVEs), which are identification numbers for publicly known cybersecurity vulnerabilities as well as name and version of a package containing this vulnerability. If available, the ‘Fixed In’ column includes a higher version of the same package that has the vulnerability resolved. This is a very important part that gives you clear guidance on how to rebuild your image without the vulnerability.
Next to the ‘Fixed In’ column is a pop-up link to a page on the Snyk website, presenting detailed information about that specific vulnerability.
The little arrow located next to the Severity rating indicates that this vulnerability has dependencies. Clicking on this arrow expands the vulnerability box and displays these dependencies:
Learn More and Try It For Yourself
Hub scanning is already available. Please check the Docker Doc section link below for more information on how to get started and give us feedback:
https://docs.docker.com/docker-hub/vulnerability-scanning/
To learn more from experts about getting the most from Docker Hub vulnerability scanning, please plan on joining Docker’s Peter McKee and Snyk’s Jim Armstrong for a joint webinar on Wednesday, Oct 15. Register now!
The post Improve the Security of Hub Container Images with Automatic Vulnerability Scans appeared first on Docker Blog.
Quelle: https://blog.docker.com/feed/






