Stateful serverless on Google Cloud with Cloudstate and Akka Serverless

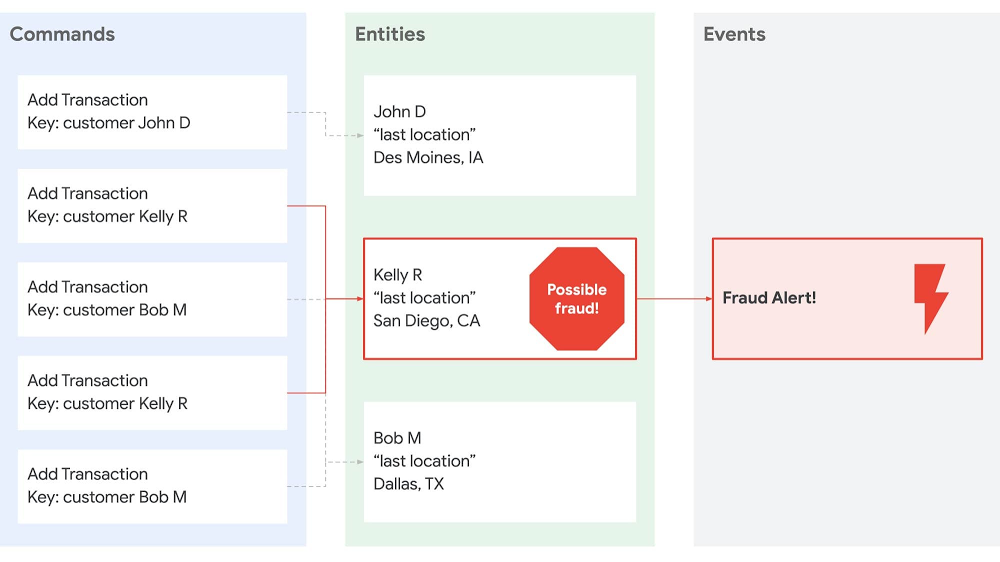
In recent years, stateless middle-tiers have been touted as a simple way to achieve horizontal scalability. But the rise of microservices has pushed the limits of the stateless architectural pattern, causing developers to look for alternatives.Stateless middle-tiers have been a preferred architectural pattern because they helped with horizontal scaling by alleviating the need for server affinity (aka sticky sessions). Server affinity made it easy to hold data in the middle-tier for low-latency access and easy cache invalidation. The stateless model pushed all “state” out of the middle-tier into backing data stores. In reality the stateless pattern just moved complexity and bottlenecks to that backing data tier. The growth of microservice architectures exacerbated the problem by putting more pressure on the middle tier, since technically, microservices should only talk to other services and not share data tiers. All manners of bailing wire and duct tape have been employed to overcome the challenges introduced by these patterns. New patterns are now emerging which fundamentally change how we compose a system from many services running on many machines.To take an example, imagine you have a fraud detection system. Traditionally the transactions would be stored in a gigantic database and the only way to perform some analysis on the data would be to periodically query the database, pull the necessary records into an application, and perform the analysis. But these systems do not partition or scale easily. Also, they lack the ability for real-time analysis. So architectures shifted to more of an event-driven approach where transactions were put onto a bus where a scalable fleet of event-consuming nodes could pull them off. This approach makes partitioning easier, but it still relies on gigantic databases that received a lot of queries. Thus, event-driven architectures often ran into challenges with multiple systems consuming the same events but at different rates.Another (we think better) approach, is to build an event-driven system that co-locates partitioned data in the application tier, while backing the event log in a durable external store. To take our fraud detection example, this means a consumer can receive transactions for a given customer, keep those transactions in memory for as long as needed, and perform real-time analysis without having to perform an external query. Each consumer instance receives a subset of commands (i.e., add a transaction) and maintains its own “query” / projection of the accumulated state. For instance:By separating commands and queries we can easily achieve end-to-end horizontal scaling, fault tolerance, and microservice decoupling. And with the data being partitioned in the application tier we can easily scale that tier up and down based on the number of events or size of data, achieving serverless operations. Making it work with CloudstateThis architecture is not entirely uncommon, going by the names Event Sourcing, Command Query Response Segregation (CQRS), and Conflict-Free Replicated Data Types. (Note: for a great overview of this see a presentation titled “Cloudstate – Towards Stateful Serverless” by Jonas Bonér.) But until now, it’s been pretty cumbersome to build systems with these architectures due to primitive programming and operational models. The new Cloudstate open-source project attempts to change that by building more approachable programming and operational models.Cloudstate’s programming model is built on top of protocol buffers (protobufs) which enable evolvable data schemas and generated service interaction stubs. When it comes to data schemas, protobufs allow you to add fields to event / message objects without breaking systems that are still using older versions of those objects. Likewise, with the gRPC project, protobufs can be automatically wrapped with client and server “stubs” so that no code needs to be written for handling protobuf-based network communication. For example, in the fraud detection system, the protobuf might be:The `Transaction` message contains the details about a transaction and the `user_id` field enables automatic sharding of data based on the user.Cloudstate adds support for event sourcing on top of this foundation so developers can focus on just the commands and accumulated state that a given component needs. For our fraud detection example, we can simply define a class / entity to hold the distributed state and handle each new transaction. You can use any language, but we use Kotlin, a Google-sponsored language that extends Java.With the exception of a tiny bit of bootstrapping code, that’s all you need to build an event-sourced system with Cloudstate!The operational model is also just as delightful since it is built on Kubernetes and Knative. First you need to containerize the service. For JVM-based builds (Maven, Gradle, etc.) you can do this with Jib. In our example we use Gradle and can just run:This creates a container image for the service and stores it on the Google Container Registry. To run the Cloudstate service on your own Kubernetes / Google Kubernetes Engine (GKE) cluster, you can use the Cloudstate operator and a deployment descriptor such as:There you have it—a scalable, distributed event-sourced service! And if you’d rather not manage your own Kubernetes cluster, then you can also run your Cloudstate service in the Akka Serverless managed environment, provided by Lightbend, the company behind Cloudstate.To deploy the Cloudstate service on Lightbend Cloudstate simply run:It’s that easy! Here is a video that walks through the full fraud detection sample:You can find the source for the sample on GitHub: github.com/jamesward/cloudstate-sample-fraudAkka Serverless under the hoodAs an added bonus, Akka Serverless itself is built on Google Cloud. To deliver this stateful serverless cloud service on Google Cloud, Cloudstate needs a distributed durable store for messages. With the open-source Cloudstate you can use PostgreSQL or Apache Cassandra. The managed Akka Serverless service is built on Google Cloud Spanner due to its global scale and high throughput. Lightbend also chose to build their workload execution on GKE to take advantage of its autoscaling and security features.Together, Lightbend and Google Cloud have many shared customers who have built modern, resilient, and scalable systems with Lightbend’s open source and Google’s Cloud services. So we are excited that Cloudstate brings together Lightbend and Google Cloud and we look forward to seeing what you will build with it! To get started check out the Open Source Cloudstate project and Lightbend’s Akka Serverless managed cloud service.
Quelle: Google Cloud Platform
What you can learn in our Q4 2020 Google Cloud Security Talks

2020 has brought with it some tremendous innovations in the area of cloud security. As cloud deployments and technologies have become an even more central part of organizations’ security program, we hope you’ll join us for the latest installment of our Google Cloud Security Talks, a live online event on November 18th, where we’ll help you navigate the latest thinking in cloud security.We’ll share expert insights into our security ecosystem and cover the following topicsSunil Potti and Rob Sadowski will open the digital event with our latest Google Cloud security announcements.This will be followed by a panel discussion with Dave Hannigan and Jeanette Manfra from Google Cloud’s Office of the CISO on how cloud migration is a unique opportunity to dismantle the legacy security debt of the past two decades.Kelly Waldher and Karthik Lakshminarayan will talk about the new Google Workspace and how it can enable users to access data safely and securely while preserving individual trust and privacy.We will present our vision of network security in the cloud with Shailesh Shukla and Peter Blum, where we’ll talk about the recent innovations that are making network security in the cloud powerful but invisible, protecting infrastructure and users from cyber attacks. Sam Lugani and Ibrahim Damlaj will do a deeper dive on Confidential Computing, and more specifically Confidential GKE Nodes and how they can add another layer of protection for containerized workloads.You will also learn how Security Command Center can help you identify misconfigurations in your virtual machines, containers, network, storage, and identity and access management policies as well vulnerabilities in your web applications, with Kathryn Shih and Timothy Peacock.Anton Chuvakin and Seth Vargo will talk about the differences between key management and secret management to help you choose the best security controls for your use cases.Finally, we will host the Google Cloud Security Showcase, a special segment where we’ll focus on a few security problems and show how we’ve recently helped customers solve them using the tools and products that Google Cloud provides. We look forward to sharing our latest security insights and solutions with you. Sign-up now to reserve your virtual seat.
Quelle: Google Cloud Platform

Preparing Google Cloud deployments for Docker Hub pull request limits

Docker Hub is a popular registry for hosting public container images. Earlier this summer, Docker announced it will begin rate-limiting the number of pull requests to the service by “Free Plan” users. For pull requests by anonymous users this limit is now 100 pull requests per 6 hours; authenticated users have a limit of 200 pull requests per 6 hours. When the new rate limits take effect on November 1st, they might disrupt your automated build and deployment processes on Cloud Build or how you deploy artifacts to Google Kubernetes Engine (GKE), Cloud Run or App Engine Flex from Docker Hub. This situation is made more challenging because, in many cases, you may not be aware that a Google Cloud service you are using is pulling images from Docker Hub. For example, if your Dockerfile has a statement like “FROM debian:latest”or your Kubernetes Deployment manifest has a statement like “image: postgres:latest” it is pulling the image directly from Docker Hub. To help you identify these cases, Google Cloud has prepared a guide with instructions on how to scan your codebase and workloads for container image dependencies from third-party container registries, like Docker Hub.We are committed to helping you run highly reliable workloads and automation processes. In the rest of the blog post, we’ll discuss how these new Docker Hub pull rate limits may affect your deployments running on various Google Cloud services, and strategies for mitigating against any potential impact. Be sure to check back often, as we will update this post regularly. Impact on Kubernetes and GKEOne of the groups that may see the most impact from these Docker Hub changes is users of managed container services. Like it does for other managed Kubernetes platforms, Docker Hub treats GKE as an anonymous user by default. This means that unless you are specifying Docker Hub credentials in your configuration, your cluster is subject to the new throttling of 100 image pulls per six hours, per IP. And many Kubernetes deployments on GKE use public images. In fact, any container name that doesn’t have a container registry prefix such as gcr.io is pulled from Docker Hub. Examples include nginx, and redis.Container Registry hosts a cache of the most requested Docker Hub images from Google Cloud, and GKE is configured to use this cache by default. This means that the majority of image pulls by GKE workloads should not be affected by Docker Hub’s new rate limits. Furthermore, to remove any chance that your images would not be in the cache in the future, we recommend that you migrate your dependencies into Container Registry, so that you can pull all your images from a registry under your control.In the interim, to verify whether or not you are affected, you can generate a list of DockerHub images your cluster consumes:You may want to know if the images you use are in the cache. The cache will change frequently but you can check for current images via a simple command:It is impractical to predict cache hit-rates, especially in times where usage will likely change dramatically. However, we are increasing cache retention times to ensure that most images that are in the cache stay in the cache.GKE nodes also have their own local disk cache, so when reviewing your usage of DockerHub, you only need to count the number of unique image pulls (of images not in our cache) made from GKE nodes: For private clusters, consider the total number of such image pulls across your cluster (as all image pulls will be routed via a single NAT gateway). For public clusters you have a bit of extra breathing room, as you only need to consider the number of unique image pulls on a per-node basis. For public nodes, you would need to churn through more than 100 unique public uncached images every 6 hours to be impacted, which is fairly uncommon.If you determine that your cluster may be  impacted, you can authenticate to DockerHub by adding imagePullSecrets with your Docker Hub credentials to every Pod that references a container image on Docker Hub.While GKE is one of the Google Cloud services that may see an impact from the Docker Hub rate limits, any service that relies on container images may be affected, including similar Cloud Build, Cloud Run, App Engine, etc.Finding the right path forward Upgrade to a paid Docker Hub accountArguably, the simplest—but most expensive—solution to Docker Hub’s new rate limits is to upgrade to a paid Docker Hub account. If you choose to do that and you use Cloud Build, Cloud Run on Anthos, or GKE, you can configure the runtime to pull with your credentials. Below are instructions for how to configure each of these services:Cloud Build: Interacting with Docker Hub imagesCloud Run on Anthos: Deploying private container images from other container registriesGoogle Kubernetes Engine: Pull an Image from a Private RegistrySwitch to Container RegistryAnother way to avoid this issue is to move any container artifacts you use from Docker Hub to Container Registry. Container Registry stores images as Google Cloud Storage objects, allowing you to incorporate container image management as part of your overall Google Cloud environment. More to the point, opting for a private image repository for your organization puts you in control of your software delivery destiny. To help you migrate, the above-mentioned guide also provides instructions on how to copy your container image dependencies from Docker Hub and other third-party container image registries to Container Registry. Please note that these instructions are not exhaustive—you will have to adjust them based on the structure of your codebase.Additionally, you can use Managed Base Images, which are automatically patched by Google for security vulnerabilities, using the most recent patches available from the project upstream (for example, GitHub). These images are available in the GCP Marketplace.Here to help you weather the changeThe new rate limits on Docker Hub pull requests will have a swift and significant impact on how organizations build and deploy container-based applications. In partnership with the Open Container Initiative (OCI), a community devoted to open industry standards around container formats and runtimes, we are committed to ensuring that you weather this change as painlessly as possible.
Quelle: Google Cloud Platform

Docker V2 Github Action is Now GA

Docker is happy to announce the GA of our V2 Github Action. We’ve been working with @crazy-max over the last few months along with getting feedback from the wider community on how we can improve our existing Github Action. We have now moved from our single action to a clearer division and advanced set of options that not only allow you to just build & push but also support features like multiple architectures and build cache.

The big change with the advent of our V2 action is also the expansion of the number of actions that Docker is providing on Github. This more modular approach and the power of Github Actions has allowed us to make the minimal UX changes to the original action and add a lot more functionality.

We still have our more meta build/push action which does not actually require all of these preconfiguration steps and can still be used to deliver the same workflow we had with the previous workflow! To Upgrade the only changes are that we have split out the login to a new step and also now have a step to setup our builder. 

–
name: Setup Docker Buildx
uses: docker/setup-buildx-action@v1

This step is setting up our builder, this is the tool we are going to use to build our Docker image. 

This means our full Github Action is now: 

name: ci

on:
push:
branches: main

jobs:
main:
runs-on: ubuntu-latest
steps:
–
name: Setup Docker Buildx
uses: docker/setup-buildx-action@v1
–
name: Login to DockerHub
uses: docker/login-action@v1
with:
username: ${{ secrets.DOCKERHUB_USERNAME }}
password: ${{ secrets.DOCKERHUB_TOKEN }}
–
name: Build and push
id: docker_build
uses: docker/build-push-action@v2
with:
push: true
tags: bengotch/samplepython:latest

For users looking for more information on how to move from V1 of the Github Action to V2, check out our release migration notes. 

Let’s now look at some of the more advanced features we have unlocked by adding in this step and the new QEMU option.

Multi platform

By making use of BuildKit we now have access to multi-architecture builds, this allows us to build images targeted at more than one platform and also build Arm images.

To do this, we will need to add in our QEMU step: 

name: Set up QEMU
uses: docker/setup-qemu-action@v1

And then within our build & push step we will need to specify out platform to use: 

–
name: Build and push
uses: docker/build-push-action@v2
with:
context: .
file: ./Dockerfile
platforms: linux/386,linux/amd64,linux/arm/v6,linux/arm/v7,linux/arm64,linux/ppc64le,linux/s390x
push: true
tags: |
bengotch/app:latest

Cache Registry 

To make use of caching to speed up my builds I can now make use of the 

name: ci

on:
push:
branches: master

jobs:
registry-cache:
runs-on: ubuntu-latest
steps:
–
name: Set up Docker Buildx
uses: docker/setup-buildx-action@v1
–
name: Login to DockerHub
uses: docker/login-action@v1
with:
username: ${{ secrets.DOCKERHUB_USERNAME }}
password: ${{ secrets.DOCKERHUB_TOKEN }}
–
name: Build and push
uses: docker/build-push-action@v2
with:
push: true
tags: user/app:latest
cache-from: type=registry,ref=user/app:latest
cache-to: type=inline

To see more examples of the best practices for using our latest version of the Github Action check out Chads example repohttps://github.com/metcalfc/docker-action-examples. You can make use of the features in here or some of the more advanced features we can now offer with the V2 action such as push to multiple registries, use of a local registry for e2e test, export an image to the Docker client and more! 

To learn more about the changes to our Github Action, have a read through our updated usage documentation or check out our blog post on the best practices with Docker and Github Actions. If you have questions or feedback on the changes from V1 to V2 please raise tickets on our repo or our public roadmap
The post Docker V2 Github Action is Now GA appeared first on Docker Blog.
Quelle: https://blog.docker.com/feed/

Docker’s Next Chapter: Our First Year

2020 has been quite the year. Pandemic, lockdowns, virtual conferences and back-to-back Zoom meetings. Global economic pressures, confinement and webcams aside, we at Docker have been focused on delivering what we set out to do when we announced Docker’s Next Chapter: Advancing Developer Workflows for Modern Apps last November 2019. I wish to thank the Docker team for their “can do!” spirit and efforts throughout this unprecedented year, as well as our community, our Docker Captains, our ecosystem partners, and our customers for their non-stop enthusiasm and support. We could not have had the year we had without you.

This next chapter is being jointly written with you, the developer, as so much of our motivation and inspiration comes from your sharing with us how you’re using Docker. Consider the Washington University School of Medicine (WUSM): WUSM’s team of bioinformatics developers uses Docker to build pipelines – consisting of up to 25 Docker images in some cases – for analyzing the genome sequence data of cancer patients to inform diagnosis and treatments. Furthermore, they collaborate with each other internally and with other cancer research institutions by sharing their Docker images through Docker Hub. In the words of WUSM’s Dr. Chris Miller, this collaboration “helps to accelerate science and medicine globally.”

WUSM is but one of the many examples we’ve heard this last year of Docker’s role in simplifying and accelerating how development teams build, share, and run modern apps. This inspires us to make the development of modern apps even simpler, to offer even more choices in app stacks and tools, and to help you move even faster.

Early indicators suggest we’re on the right path. There’s been a significant increase in Docker usage this past year as more and more developers embrace Docker to build, share, and run modern applications. Specifically, 11.3 million monthly active users sharing apps from 7.9 million Docker Hub repositories at a rate of 13.6 billion pulls per month – up 70% year-over-year. Furthermore, in May the 2020 Stack Overflow Developer Survey of 65,000 developers resulted in Docker as the #1 most wanted, the #2 most loved, and the #3 most popular platform.

One of the reasons for this growth is that Docker offers choice to developers by integrating with best-of-breed tools and services. This past year, the industry’s largest cloud providers – AWS and Microsoft – partnered with Docker to create fast, friction-free “code-to-cloud” automations for developers. We partnered with Snyk to “shift left” security and make it a natural part of a developer’s inner loop as well as to secure Docker Official Images and Docker Certified Images. And to help development teams further automate their pipelines, this year we shipped our own Docker GitHub Action. We’ll be sharing more in the months to come on how Docker and its ecosystem partners are working together to bring more choices to developers so watch this space. 

Sustainable Community, Code, & Company

The sustainability of open source businesses is often a topic of discussion. Docker isn’t immune to economic realities, and this past year we’ve focused on the sustainability of the community, code, and company. For the community, we’ve made investments to make it even more accessible, including virtual DockerCon which attracted 80,000 attendees from around the world. For the code, to ensure we can effectively engage and support we’ve intentionally aligned our open source efforts around projects relevant to developers, including BuildKit, Notary, OCI, the Docker GitHub Action, the Compose spec, and our Compose integrations with cloud providers.

For the company, achieving sustainability has been a multi-step process with the objective of continuing to offer all developers 100% free build, share, run tools and, as they scale their use, to provide compelling value in our subscriptions. First, we introduced per-seat pricing to make our subscriptions easier to understand for developers and development teams. Then we introduced annual purchasing options which offer discounts for longer-term commitments. More recently, we announced establishing upper limits on ‘docker pulls’ as the first step in our move toward usage-based pricing. This ensures we scale sustainably while continuing to offer 100% free build, share, and run tools to the tens of millions more developers joining the Docker community.

What’s Next?

As busy as our first year has been, we’re looking forward to working with our developer community in the coming year to deliver more great tools and integrations that help development teams build, share, and run modern apps. In fact, you’ve already given us plenty of great ideas and feedback in our public roadmap on GitHub – keep ‘em comin’. To prioritize and focus our efforts, our guiding questions continue to be:

“Does this feature simplify for the development team the complexity of building, sharing, and running a modern app?”

“Does this offer the development team more choice in terms of app stack technologies and/or pipeline tools – without introducing complexity?”

“Does this help a development team iterate more quickly and accelerate the delivery of their application?”

With that, here’s a sneak peek of what to look for in our second year:

App Dev Environments – To help teams get up-and-running quickly with new projects, expect more prescriptive development environments and pipeline tools in a “batteries included, but swappable” approach. You’ve maybe already seen our early hints around this for Go, Python, and Node.js – more to come.

Container Image Management – Expect more visibility and more tools for development teams to proactively manage their images.

Pipeline Automation –  Our GitHub- and Atlassian BitBucket-integrated autobuilds service and our Docker GitHub Action are loved by many of you, but you also have other favorite build and CI tools you’d like to see more tightly integrated. Stay tuned.

Collaboration –  Getting an app from code-to-cloud is a team effort. The more effortlessly a team can share – code, images, context, automation, and more – the faster they can ship. Docker Compose has already proven its value for development team collaboration; look for us to build on its success.

Content – Developers have already voted with their pulls – Docker Official Images are by far the most popular category of images pulled. Why? Because development teams trust them as the basis for their modern apps. In the coming year, look for additional breadth and depth of trusted content to be made available. This includes apps from ISVs distributing Docker Certified Images as Docker Verified Publishers. In fact, this program already recognizes more than 90 ISVs, with more joining every day.

As we look forward to 2021 – hopefully a year that frees us to meet safely together in person again – Docker remains committed to providing a collaborative application development platform to help teams build, share, and run modern apps that transform their organizations. The Docker team is thankful that we’re on this journey together with our community members, contributors, ecosystem partners, and customers – let’s have a great year!
The post Docker’s Next Chapter: Our First Year appeared first on Docker Blog.
Quelle: https://blog.docker.com/feed/





