Demystifying Cloud Security Compliance Webinar with Transcript, Deck & Links

With security on everyone’s mind, we wanted to bring you this webinar, “Demystifying Cloud Security Compliance”, which Bryan Langston, Director of Architecture and Jason James, Director of Security provided earlier this year. Please enjoy the video or read the transcript below, and let us know how we can help! Cloud Security Compliance Presenters Bryan Langston … Continued
Quelle: Mirantis

How Cloud Bigtable helps Ravelin detect retail fraud with low latency

Editor’s note: Today we are hearing from Jono MacDougall , Principal Software Engineer at Ravelin. Ravelin delivers market-leading online fraud detection and payment acceptance solutions for online retailers. To help us meet the scaling, throughput, and latency demands of our growing roster of large-scale clients, we migrated to Google Cloud and its suite of managed services, including Cloud Bigtable, the scalable NoSQL database for large workloads.As a fraud detection company for online retailers, each new client brings new data that must be kept in a secure manner and new financial transactions to analyze. This means our data infrastructure must be highly scalable and constantly maintain low latency. Our goal is to bring these new organizations on quickly without interrupting their business. We help our clients with checkout flows, so we need latencies that won’t interrupt that process—a critical concern in the booming online retail sector. We like Cloud Bigtable because it can quickly and securely ingest and process a high volume of data. Our software accesses data in Bigtable every time it makes a fraud decision. When a client’s customer places an order, we need to process their full history and as much data as possible about that customer in order to detect fraud, all while keeping their data secure. Bigtable excels at accessing and processing that data in a short time window. With a customer key, we can quickly access data, bring it into our feature extraction process, and generate features for our models and rules. The data stays encrypted at rest in Bigtable, which keeps us and our customers safe.Bigtable also lets us present customer profiles in our dashboard to our client, so that if we make a fraud decision, our clients can confirm the fraud using the same data source we use.Retailers can use Ravelin’s dashboard to understand fraud decisionsWe have configured our bigtable clusters to only be accessible within our private network and have restricted our pods access to it using targeted service accounts. This way the majority of our code does not have access to bigtable and only the bits that do the reading and writing have those privileges.We also use Bigtable for debugging, logging, and tracing, because we have spare capacity and it’s a fast, convenient location. We conduct load testings against Bigtable.  We started at a low rate of ~10 Bigtable requests per second and we peaked at ~167000 mixed read and write requests per second  at absolute peak. The only intervention that was done to achieve this was pressing a single button to increase the number of nodes in the database. No other changes were made.In terms of real traffic to our production system, we have seen ~22,000 req/s (combined read/write) on Bigtable in our live environment as a peak within the last 6 weeks.Migrating seamlessly to Google Cloud Like many startups, we started with Postgres, since it was easy and it was what we knew, but we quickly realized that scaling would be a challenge, and we didn’t want to manage enormous Postgres instances. We looked for a kind of key value store, because we weren’t doing crazy JOINS or complex WHERE clauses. We wanted to provide a customer ID and get everything we knew about it, and that’s where key value really shines.  I used Cassandra at a previous company, but we had to hire several people just for that chore. At Ravelin we wanted to move to managed services and save ourselves that headache. We were already heavy users and fans of BigQuery, Google Cloud’s serverless, scalable data warehouse, and we also wanted to start using Kubernetes. This was five years ago, and though quite a few providers offer Kubernetes services now, we still see Google Cloud at the top of that stack with Google Kubernetes Engine (GKE). We also like Bigtable’s versioning capability that helped with a use case involving upserts. All of these features helped us choose Bigtable.Migrations can be intimidating, especially in retail where downtime isn’t an option. We were migrating not just from Postgres to Bigtable, but also from AWS to Google Cloud. To prepare, we ran in AWS like always, but at the same time we set up a queue at our API level to mirror every request over to Google Cloud. We looked at those requests to see if any were failing, and confirmed if the results and response times were the same as in AWS. We did that for a month, fine tuning along the way. Then we took the big step and flipped a config flag and it was 100% over to Google Cloud. At the exact same time, we flipped the queue over to AWS so that we could still send traffic into our legacy environment. That way, if anything went wrong, we could fail back without missing data. We ran like that for about a month, and we never had to fail back. In the end, we pulled off a seamless, issue-free online migration to Google Cloud.Flexing Bigtable’s featuresFor our database structure, we originally had everything spread across rows, and we’d use a hash of a customer ID as a prefix. Then we could scan each record of history, such as orders or transactions. But eventually we got customers that were too big, where the scanning wasn’t fast enough. So we switched and put all of the customer data into one row and the history into columns. Then each cell was a different record, order, payment method, or transaction. Now, we can quickly look up the one row and get all the necessary details of that customer. Some of our clients send us test customers who place an order, say, every minute, and that quickly becomes problematic if you want to pull out enormous amounts of data without any limits on your row size. The garbage collection feature makes it easy to clean up big customers.  We also use Bigtable replication to increase reliability, atomicity, and consistency. We need strong consistency guarantees within the context of a single request to our API since we make multiple bigtable requests within that scope. So within a request we always hit the same replica of Bigtable and if we have a failure, we retry the whole request. That allows us to make use of the replica and some of the consistency guarantees, a nice little trade-off where we can choose where we want our consistency to live.We also use BigQuery with Bigtable for training on customer records or queries with complicated WHERE clauses. We put the data in Bigtable, and also asynchronously in BigQuery using streaming inserts, which allows our data scientists to query it in every way you can imagine, build models, and investigate patterns and not worry about query engine limitations. Since our Bigtable production cluster is completely separate, doing a query on BigQuery has no impact on our response times. When we were on Postgres many years ago, it was used for both analysis and real time traffic and it was not the optimal solution for us. We also use Elasticsearch for powering text searches for our dashboard.If you’re using Bigtable, we recommend three features:Key visualizer. If we get latency or errors coming back from Bigtable, we look at the key visualizer first. We may have a hotkey or a wide row, and the visualizer will alert us and provide the exact key range where the key lives, or the row in question. Then we can go in and fix it at that level. It’s useful to know how your data is hitting Bigtable and if you’re using any anti-patterns or if your clients have changed their traffic pattern that exacerbated some issue.Garbage collection. We can prevent big row issues by putting size limits in place with the garbage collection policies.  Cell versioning. Bigtable has a 3d array, with rows, columns, and cells, which are all the different versions. You can make use of the versioning to get history of a particular value or to build a time series within one row. Getting a single row is very fast in Bigtable so as long as you can keep the data volume in check for that row, making use of cell versions is a very powerful and fast option. There are patterns in the docs that are quite useful and not immediately obvious. For example, one trick is to reverse your timestamps (MAXINT64 – now) so instead of the latest version, you can get the oldest version effectively reversing the cell version sorting if you need it.Google Cloud and Bigtable help us meet the low-latency demands of the growing online retail sector, with speed and easy integration with other Google Cloud services like BigQuery. With their managed services, we freed up time to focus on innovations and meet the needs of bigger and bigger customers. Learn more about Ravelin and Bigtable, and check out our recent blog, How BIG is Cloud Bigtable?Related ArticleCloud Bigtable brings database stability and performance to PrecognitiveUsing Google’s Cloud Bigtable database improved performance and cut latency and maintenance time for software developer Precognitive.Read Article
Quelle: Google Cloud Platform

Bringing Kubernetes’ goodness to Windows Server apps with Anthos

Today, many applications in organizations’ data centers run on Windows Server. Modernizing these traditional Windows apps onto Kubernetes promises a host of benefits: a consistent platform across environments, better portability, scalability, availability, simplified management and speed of deployment, just to name a few. But how? Rewriting traditional .NET applications to run on Linux with .NET Core can be challenging and time-consuming. There is, however, a lower-toil, more developer friendly option.Last year, we announced support for Windows Server containers running on Google Kubernetes Engine (GKE), our cloud-based managed Kubernetes service, which lets you take the advantage of containers without porting your apps to .NET core or rewriting them for Linux. Today, we’re going a step further with support for Windows Server containers on Anthos clusters on VMware in your on-premises environment. Now available in preview, you can consolidate all your Windows operations across on-prem and Google Cloud.Bringing Windows Server support to our family of Kubernetes-based services—GKE running on Google Cloud, and Anthos everywhere—with the same experience, lets you modernize apps faster and achieve a consistent development and deployment experience across hybrid and cloud environments. Further, by running Windows and Linux workloads side by side, you get operational consistency and efficiency—no need to have multiple teams specializing in different tooling or platforms to manage different workloads. The single-pane-of-glass view and the ability to manage policies from a central control plane simplifies the management experience, while bin packing multiple Windows applications drives better resource utilization, leading to infrastructure and license savings.Google Cloud Console provides a single pane of glass view for managing your clusters in different environmentsWith all these benefits, it’s no surprise that customers such as Thales, a French multinational firm specializing in aerospace and security services, have been able to reap significant benefits by moving Windows applications to GKE. “We moved our Windows applications from VMs to Windows containers on GKE and now have a unified mechanism for Linux and Windows-based application management, scaling, logging, and monitoring. Earlier, setting up these applications in VMs and configuring them for high availability used to take up to a week, and the applications were not easily scalable,”said Najam Siddiqui, Solutions Architect at Thales.“Now with GKE, the setup takes only a few minutes. GKE’s automatic scaling and built-in resiliency features make scaling and high-availability setup seamless. Also, manually maintaining the VMs and applying security patches used to be tedious, which is now handled by GKE.” Let’s take a deeper look at the architecture that lets you run your Windows container-based workloads on-prem. Windows Server running on-prem with Anthos The diagram below illustrates the high-level architecture of running Windows container-based workloads in an on-prem GKE cluster with Anthos. Windows server node-pools can be added to an existing or new Anthos cluster. Kubelet and Kube-proxy run natively on Windows nodes, allowing you to run mixed Windows and Linux containers in the same cluster. The admin cluster and the user cluster control plane continue to be Linux-based, providing you a consistent orchestration experience and management ease across Windows and Linux workloads.Windows Server and Linux containers running side-by-side in the same Anthos on-prem clusterGet started todayWhen considering modernizing your on-prem Windows estate, we recommend running Windows Server containers on Anthos in your own data center. If you are new to Anthos, the Anthos getting started page and the Coursera course on Architecting Hybrid Cloud with Anthos are good places to start. You can also find detailed documentation on our website, and our partners are eager to help you with any questions related to the published solutions, as is the GCP sales team. And as always, please don’t hesitate to reach out to us at anthos-onprem-windows@google.com if you have any feedback or need help unblocking your use case.Related ArticleWindows Server containers on GKE now GA, with ecosystem supportWindows Server containers are now GA on Google CloudRead Article
Quelle: Google Cloud Platform
GKE best practices: Create a cost-optimized cluster in just a few clicks

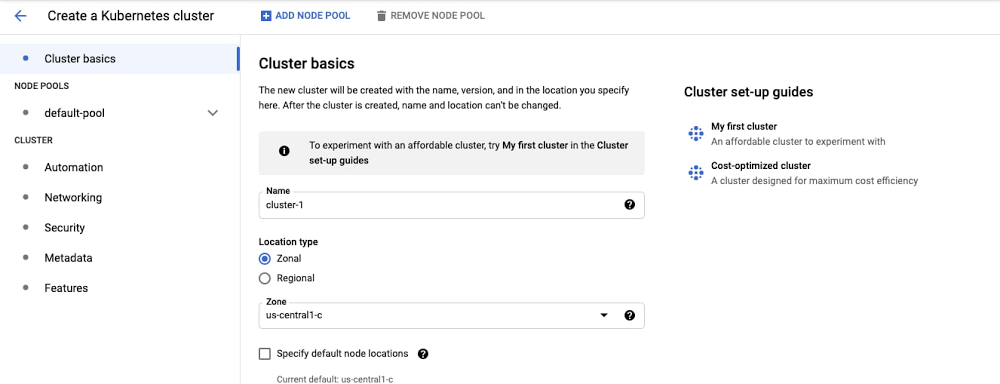
No one wants to spend more on compute infrastructure than they have to—and that includes your Kubernetes platform. With Google Kubernetes Engine (GKE), the easiest way to stand up a cost-optimized cluster is to choose GKE Autopilot. However, some organizations may not be ready to use Autopilot yet. For them, there’s our guide, Best practices for running cost-optimized Kubernetes applications on GKE, which details GKE’s core cost-optimization capabilities and organizational considerations for getting them implemented. And now, to make it much easier to apply those learnings, we’re introducing the built-in GKE cost-optimized cluster setup guide.With the new cluster setup guide, you can set up a cost-optimized Kubernetes cluster in a couple of clicks, and effortlessly learn about GKE’s top cost optimization capabilities without ever leaving your cluster creation workflow. This setup guide is a great resource for:The user that only wants to provide the size of the cluster, and let Google guide them through setting up the most cost optimal cluster The seasoned GKE operator who wants  a quick walkthrough of GKE’s latest cost-optimization featuresThe developer who wants an environment with a good balance between cost and performanceOr, those just getting started on their GKE journey.Behind the scenes, the setup guide suggests intelligent defaults for configuring your cluster. This will simplify the following decisions and bring your GKE Standard setup closer to the best practices implemented in GKE Autopilot.Choice of machine types and sizesWhether to enable cluster autoscalerHow many node pools of what machine sizes to configureHow to automate the configuration of appropriately sized nodes (check node auto-provisioning)Whether to enable vertical pod autoscalingThe right settings for tracking cluster costs out of the boxUsing the GKE cost-optimized setup guideYou can access the setup guide right out of the GKE cluster creation option in the Cloud Console.All you have to do is:Name your cluster, select your region and preferred release channelSpecify your desired cluster-size range, in number of CPUsPoint to your GKE usage metering data export location…and GKE does the rest for you. While you advance through the guide, we walk you through the exact settings of the cluster as it’s being configured. If all this sounds simple, it’s because it is!What’s going on under the hood?The setup guide makes it easy to set up a cost-optimized cluster, but behind the scenes, there’s a lot going on..The first step to a cost-optimal cluster is the cluster’s size. In this step, we enable node auto-provisioning. All you have to do is enter the minimum and maximum number of CPUs, and we’ll suggest the right memory ratio for your cluster.The next step lets you verify the machine type. This solves a very common question: “What machine size should I use for my default node pool?”Beyond your workloads, GKE runs components such as agents and proxies on a cluster’s nodes, so it’s important to strike the right balance between VM size for the best balance between cost and  performance. We achieve this by proposing a machine type and size based on the minimum and maximum size of the cluster that was specified in the previous step. Again—you retain full control over your final choice. By default, we select the cost-optimized general purpose machine type.The next step takes us to the advanced settings, where we preconfigure a number of important settings for you. We don’t expect you to change any of these (even though you can).For instance, we set the cluster autoscaling profile to optimize utilization—this optimizes for utilization over keeping spare resources in the cluster. When selected, the cluster autoscaler scales down the cluster more aggressively: it can remove more nodes, and remove nodes faster. Additionally, we enable cluster autoscaler just for the default pool, allowing you to keep the default node pool within the specified boundaries. We also activate vertical pod autoscaling by default, making sure the cluster is ready to provide recommendations for your workload if needed. This setting is non-disruptive to your cluster or workloads.Finally, you can’t optimize what you don’t measure. Observing and measuring your cluster usage is a core way to understand and improve your cluster utilization at any point in its life cycle. To help with that, we activate GKE usage metering by default. All you have to do is choose the BigQuery dataset to export the data to. As with everything in the setup guide, you can skip this step.That’s it—your new, cost optimized cluster is ready to go! Pro tip – select the “Make changes” option to apply the setup guide settings to the main cluster creation flow, and continue editing your cluster!While your cluster is spinning up, take some time and check the next steps you would want to take beyond infrastructure optimization.Our best practices guide will give you more insights on how to optimize beyond infrastructure, and how to approach workload-level optimization for when your cluster is up and running. You should also check out our collection of advanced GKE cost optimization materials and video series. Share them with your team and become a true GKE cost optimization hero!
Quelle: Google Cloud Platform

BigQuery Admin reference guide: Storage internals

So far on the BigQuery Admin Reference Guide series, we’ve talked about the different logical resources available inside of BigQuery. Now, we’re going to begin talking about BigQuery’s architecture. In this post we’re diving into how BigQuery stores your data in native storage, and what levers you can pull to optimize how your data is stored. Columnar storage formatBigQuery offers fully managed storage, meaning you don’t have to provision servers. Sizing is done automatically and you only pay for what you use. Because BigQuery was designed for large scale data analytics data is stored in columnar format.Traditional relational databases, like Postgres and MySQL, store data row-by-row in record-oriented storage. This makes them great for transactional updates and OLTP (Online Transaction Processing) use cases because they only need to open up a single row to read or write data. However, if you want to perform an aggregation like a sum of an entire column, you would need to read the entire table into memory.BigQuery uses columnar storage where each column is stored in a separate file block. This makes BigQuery an ideal solution for OLAP (Online Analytical Processing) use cases. When you want to perform aggregations you only need to read the column that you are aggregating over.Optimized storage formatInternally, BigQuery stores data in a proprietary columnar format called Capacitor. We know Capacitor is a column-oriented format as discussed above. This means that the values of each field, or column,  are stored separately so the  overhead of reading the file is proportional to the number of fields you actually read. This doesn’t necessarily mean that each column is in its own file, it just means that each column is stored in a file block, which is actually compressed independently for increased optimization.What’s really cool is that Capacitor builds an approximation model that takes in relevant factors like the type of data (e.g. a really long string vs. an integer) and usage of the data (e.g. some columns are more likely to be used as filters in WHERE clauses) in order to reshuffle rows and encode columns. While every column is being encoded, BigQuery also collects various statistics about the data — which are persisted and used later during query execution.If you want to learn more about Capacitor, check out this blog post from Google’s own Chief BigQuery Officer. Encryption and managed durabilityNow that we understand how the data is saved in specific files, we can talk about where these files actually live. BigQuery’s persistence layer is provided by Google’s distributed file system, Colossus, where data is automatically compressed, encrypted, replicated, and distributed.There are many levels of defense against unauthorized access in Google Cloud Platform, one of them being that 100% of data is encrypted at rest. Plus, if you want to control encryption yourself, you can use customer-managed encryption keys.Colossus also ensures durability by using something called erasure encoding – which breaks data into fragments and saves redundant pieces across a set of different disks.  However, to ensure the data is both durable and available, the data is also replicated to another availability zone within the same region that was designated when you created your dataset.This means data is saved in a different building that has a different power system and network. The chances of multiple availability zones going offline at once is very small. But if you use “Multi-Region” locations- like the US or EU – BigQuery stores another copy of the data in an off-region replica. That way, the data is recoverable in the event of a major disaster.This is all accomplished without impacting the compute resources available for your queries. Plus encoding, encryption and replication are included in the price of BigQuery storage – no hidden costs!Optimizing storage for query performanceBigQuery has a built-in storage optimizer that helps arrange data into the optimal shape for querying, by periodically rewriting files. Files may be written first in a format that is fast to write but later BigQuery will format them in a way that is fast to query. Aside from the optimization happening behind the scenes, there are also a few things you can do to further enhance storage.PartitioningA partitioned table is a special table that is divided into segments, called partitions. BigQuery leverages partitioning to minimize the amount of data that workers read from disk. Queries that contain filters on the partitioning column can dramatically reduce the overall data scanned, which can yield improved performance and reduced query cost for on-demand queries. New data written to a partitioned table is automatically delivered to the appropriate partition.BigQuery supports the following ways to create partitioned tables:Ingestion time partitioned tables: daily partitions reflecting the time the data was ingested into BigQuery. This option is useful if you’ll be filtering data based on when new data was added. For example, the new Google Trends Dataset is refreshed each day, you might only be interested in the latest trends. Time-unit column partitioned tables: BigQuery routes data to the appropriate partition based on date value in the partitioning column. You can create partitions with granularity starting from hourly partitioning. This option is useful if you’ll be filtering data based on the date value in the table, for example looking at the most recent transactions by including a WHERE clause for transaction_created_dateINTEGER range partitioned tables: Partitioned based on an integer column  that can be bucketed. This option is useful if you’ll be filtering data based on an integer column in the table, for example focusing on specific customers using customer_id. You can bucket the integer values to create appropriately sized partitions, like having all customers with IDs from 0-100 in the same partition. Partitioning is a great way to optimize query performance, especially for large tables that are often filtered down during analytics. When deciding on the appropriate partition key, make sure to consider how everyone in your organization is leveraging the table. For large tables that could cause some expensive queries, you might want to require partitions to be used.Partitions are designed for places where there is a large amount of data and a low number of distinct values. A good rule of thumb is making sure partitions are greater than 1 GB. If you over partition your tables, you’ll create a lot of metadata – which means that reading in lots of partitions may actually slow down your query. ClusteringWhen atable is clusteredin BigQuery, the data is automatically sorted based on the contents of one or more columns (up to 4, that you specify). Usually high cardinality and non-temporal columns are preferred for clustering, as opposed to partitioning which is better for fields with lower cardinality. You’re not limited to choosing just one, you can have a single table that is both partitioned and clustered!The order of clustered columns determines the sort order of the data. When new data is added to a table or a specific partition, BigQuery performs free, automatic re-clustering in the background. Specifically, clustering can improve the performance for queries:Containing where clauses with a clustered column: BigQuery uses the sorted blocks to eliminate scans of unnecessary data. The order of the filters in the where clause matters, so use filters that leverage clustering firstThat aggregate data based on values in a clustered column: performance is improved because the sorted blocks collocate rows with similar valuesWith joins where the join key is used to cluster the table: less data is scanned, for some queries this offers a performance boost over partitioning!Looking for some more information and example queries? Check out this blog post! DenormalizingIf you come from a traditional database background, you’re probably used to creating normalized schemas – where you optimize your structure so that data is not repeated. This is important for OLTP workloads (as we discussed earlier) because you’re often making updates to the data. If your customer’s address is stored every place they have made a purchase, then it might be cumbersome to update their address if it changes. However, when performing analytical operations on normalized schemas, usually multiple tables need to be joined together. If we instead denormalize our data, so that information (like the customer address) is repeated and stored in the same table, then we can eliminate the need to have a JOIN in our query. For BigQuery specifically, we can also take advantage of support for nested and repeated structures. Expressing records using STRUCTs and ARRAYs can not only provide a more natural representation of the underlying data, but in some cases it can also eliminate the need to use a GROUP BY statement. For example, using ARRAY_LENGTH instead of COUNT.Keep in mind that denormalization has some disadvantages. First off, they aren’t storage-optimal. Although, many times the low cost of BigQuery storage addresses this concern. Second, maintaining data integrity can require increased machine time and sometimes human time for testing and verification. We recommend that you prioritize partitioning and clustering before denormalization, and then focus on data that rarely requires updates. Optimizing for storage costsWhen it comes to optimizing storage costs in BigQuery, you may want to focus on removing unneeded tables and partitions. You can configure the default table expiration for your datasets, configure the expiration time for your tables, and configure the partition expiration for partitioned tables. This can be especially useful if you’re creating materialized views or tables for ad-hoc workflows, or if you only need access to the most recent data.Additionally, you can take advantage of BigQuery’s long term storage. If you have a table that is not used for 90 consecutive days, the price of storage for that table automatically drops by 50 percent to $0.01 per GB, per month. This is the same cost as Cloud Storage Nearline, so it might make sense to keep older, unused data in BigQuery as opposed to exporting it to Cloud Storage.Thanks for tuning in this week! Next week, we’re talking about query processing – a precursor to some query optimization techniques that will help you troubleshoot and cut costs.  Be sure to stay up-to-date on this series by following me on LinkedIn and Twitter!Related ArticleBigQuery Admin reference guide: Jobs & reservation modelLearn all about workload management in BigQuery by understanding what a job is and how slot reservations can be leveraged across your org…Read Article
Quelle: Google Cloud Platform





