Tiler: E-Bikes kabellos über den Fahrradständer laden
E-Bikes könnten künftig ohne Stecker geladen werden. Das Tiler-System arbeitet per Induktion. Berührungspunkt ist der Fahrradständer. (E-Bike, Technologie)
Quelle: Golem

E-Bikes könnten künftig ohne Stecker geladen werden. Das Tiler-System arbeitet per Induktion. Berührungspunkt ist der Fahrradständer. (E-Bike, Technologie)
Quelle: Golem
itnext.io – If you are familiar with Kubernetes, you must know Kubernetes installation is one of the challenging topics of Kubernetes. This challenge occurs because a multitude of installation methods exists. In…
Quelle: news.kubernauts.io

In past posts, we have seen how to provision and manage Cloud Spanner in production environments and how to use the Cloud Spanner Emulator in your development workflow with a sample Node.js app called OmegaTrade. We’ve covered:The Cloud Spanner emulator’s various deployment models,Running the emulator locally with OmegaTrade, and Running the emulator remotely with OmegaTradeIn this post, we will cover how to use the Cloud Spanner emulator in your Continuous Integration and Continuous Delivery/Deployment (CI/CD) pipelines, with sample steps covering the following tools: Cloud BuildJenkinsGitHub ActionsCircleCIAs a refresher, OmegaTrade is a stock ticker visualization application that stores stock prices in Cloud Spanner and renders visualizations using Google Charts. It consists of a frontend service that renders the visualizations and a backend service that writes to and reads from the Cloud Spanner instance. For the sake of simplicity, we focus on the backend service of the OmegaTrade application in this blog post and demonstrate how to use the Cloud Spanner emulator in CI/CD pipelines for this service. If you’d prefer to deploy the OmegaTrade backend manually, you can learn all about how to do that by reading this blog post and focusing on the section Manual deployment steps.CI/CD Approach for deploying OmegaTradeThe steps for all of the CI/CD tools we discuss are similar. The code is stored in a public GitHub repository, Docker files are used for creating the application docker image, Google Container Registry is used as the docker image repository and gcloud commands are used for application deployment to Cloud Run.Please note that all of the CI/CD tools require access to a GCP Service Account (SA) as well as integration with your GitHub repository. The main branch keeps the application code to be deployed on the dev environment where we will be deploying the Cloud Spanner emulator. Since it is using the emulator, we are calling this a dev environment.The prod branch keeps the application code to be deployed on the prod environment where we will be deploying an actual Cloud Spanner instance. We have two dockerfiles, one for dev (dockerfile.local.emulator) where we will be deploying the Cloud Spanner emulator, and another for prod (dockerfile.prod). dockerfile.local.emulator contains the Cloud Spanner emulator as well as the application layers (for testing purposes) whereas dockerfile.prod only contains the application code layer.Cloud BuildTo set up CI/CD with Cloud Build, please ensure the Cloud Build API is enabled from your Cloud Console as a prerequisite. The first step is to connect our GitHub repository with Cloud Build for automated deployment of our application over Cloud Run. From the Connect Repository option in the Cloud Build Triggers screen, select the source as GitHub (Cloud Build GitHub App), authenticate, select GitHub Account and Repository.In the backend, Cloud Build will install the Cloud Build app in your GitHub repository. You can find Cloud Build in Repo Settings ➞ Integrations. This app will monitor your repository and trigger pipeline processing upon any commit or push to whichever branch you mention in the trigger. Cloud Build allows folder-specific triggers.For this blog, we are going to create 2 triggers, one dedicated to dev deployment and another to prod. The Dev deployment will be communicating with the Spanner emulator whereas Prod one will be communicating with an actual Cloud Spanner instance.Create Google Cloud Build TriggersWe are using the Cloud Build.yaml file (build config file) for the deployment. A build config file defines the fields that are needed for Cloud Build to perform your tasks. We can create either a .yml or .json file for Cloud Build where we write instructions for our CI/CD pipeline.The Cloud Build config is purely parameterized which means we are using the same build config file for our frontend as well as backend deployment and providing values while creating triggers in the GCP UI.The substitution_option: ‘ALLOW_LOOSE’ allows Cloud Build triggers to run despite any missing substitution variable. We are using this option because we need some extra values for backend deployment. In this case, Cloud Build won’t return any errors.To set up the backend trigger, follow the below steps:From Cloud Build ➞ Create Trigger, enter a unique name, description for the triggerSelect Event as Push to a branchChoose GitHub repo in Source Enter ^main$ under BranchEnter backend/** in the Included files filter (this option triggers a backend trigger when there is any change(s) in the folder)Enter Cloud Build.yaml in Build Configuration. Similarly, create one for prod deployment with ^prod$ under Branch and substitute the rest of the fields with actual Cloud Spanner instance values.Here is a video walkthrough of the configuration steps for Cloud Build:JenkinsPrerequisites: Basic Knowledge of JenkinsJenkins must be installed and setupTo set up Jenkins CI/CD, we are using the Jenkins Multibranch Pipeline, which allows for creating and triggering pipelines based on branch and pull requests. For this blog post, we are going to create 2 branches: dev and prod. Dev app code will be communicating with the Spanner emulator hosted on Google Compute Engine whereas the Prod one would be communicating with an actual Cloud Spanner instance.Create service accounts in GCPAfter installing Jenkins on GKE, we need to create a service account (SA) in GCP. After creating the SA, we’ll need to give it the correct permissions.For this blog, we’ve given wide scope permission — admin, but in your environment, you may want to follow the Principle of Least Privilege.Once done, create an SA key, as we’re going to need it later.Now let’s create one secret — kaniko-secret in Kubernetes with the kaniko service account key. kaniko is a tool to build container images from a Dockerfile, inside a container or Kubernetes cluster.For this, we’re using a cloud shell, so before applying the commands we have to upload key.json here.Connect Jenkins with GitHubIntegrating Jenkins with GitHub keeps your project updated. With this, your Jenkins build will automatically schedule when there is any new push/commit to the branch by pulling the code and data files from GitHub to Jenkins.To do this, add a webhook from the settings option of your repo. Enter the Jenkins URL, append /github-webhook/, and choose application/json in the content type. Select from which events you would like to trigger this webhook For instance, you can go with the 3rd option — Let me select individual events, and then allow Push and Pull Requests. Upon saving you will see a green check, which means the first (testing) delivery is successful.Create a GitHub Personal Access TokenA GitHub Personal access token is a good alternative to using passwords for authentication to GitHub when using the GitHub API or the command line. Generate one from your GitHub profile settings➞Developer Settings➞Personal Access Tokens with all necessary permission that you want to give to this token. Copy the token value.Add CredentialsCredentials allow Jenkins to interact with 3rd party services or tools like Docker Container Registry in an authorized manner. Jenkins stores credentials in encrypted form on the master Jenkins instance (encrypted by the Jenkins instance ID) and the credentials are only handled in Pipeline projects via their credential IDs.Here we’ll be adding the kaniko-executor-sa key (created above) in Jenkins, which allows Jenkins to communicate with GCR.From the admin option on the top left, go to Credentials➞Stores from parent(in right)➞Global credentials (unrestricted)➞Add Credentials.Select Secret File from Kind and upload the file.Create one Secret with username and password where the username will be your GitHub username and the password will be the Access Token that you copied above.Install PluginsWe’ll be installing some plugins that help make the multibranch pipeline experience smoother.From Manage Plugins in Manage Jenkins, install:Pipeline: Multibranch build strategy extensionBlue OceanCreate Multibranch PipelineTo create a multibranch pipeline, go to New Item➞Multibranch Pipeline. Enter the item name, the display name, and the description.Choose GitHub from Branch Source, select GitHub Personal Access Token that you’ve created before, enter the GitHub repo name, and hit validate. It should show Credentials OK.From Behaviors, you may want to select the following:You can select other available options based on your trigger requirements. The options mentioned above tend to help improve discoverability.From Build Strategies, choose Trigger builds for included regions.Build StrategiesThis feature is based on the Pipeline: Multibranch build strategy extension plugin. Without it, you won’t be able to create GitHub folder-based triggers.If you have the code for more than one service in a single repo, then creating a repo-based trigger is not recommended, because all the pipelines will get triggered by any change in the repo. With this plugin, however, you can specify folders from which a build will occur. Like in the above example, this particular pipeline will only get triggered when there is a change in the specific folder.Under Build Configuration, enter the Jenkinsfile pathLeave the rest of the options as it is and hit Save. As you save it, Jenkins will scan the repository and display logs. Once it is done, Jenkins will start building and deploying the app over GCP Cloud Run.Jenkins CI/CD CodeHere is a video walkthrough of the configuration steps for Jenkins:GitHub ActionsWith GitHub Actions, we create workflows. Here we’ll be creating 2 workflows, one dedicated to dev and another one to prod. The Dev deployment will be communicating to the Spanner emulator whereas the Prod one will talk to the actual Cloud Spanner instance.First, we have to set up some secrets in GitHub which will be used by GitHub Actions during deployments.To create a multibranch pipeline, go to Setting➞Secrets. We need to create 2 secrets here. One secret for GCP Service Account email would be used for deployments and another secret would be for the associated Service Account key. To generate your Service Account key from the GCP Console, Go to Service Account➞Choose your SA and from 3 vertical dots, Create Key.Here, the first secret, i.e. GCP_SA_EMAIL is the Service Account email and the second one, i.e GCP_SA_KEY is the Service Account key we generated.Refer to the screenshots below.From the GitHub repo, go to Actions, where you will find the pre-created workflows. Choose any of them, clear all the code from there, paste the Workflow code and name the file. As you commit that, you will see a .github/workflows folder appear in the GitHub repository.From Actions, you can see your pipeline running and working.The GitHub Actions workflows are branch and folder-specific as we have mentioned the keywords push for branch and working-directory for folder. The commit needs to satisfy these 2 things to run a specific workflow. We are using previously created GitHub Actions for configuring the Google Cloud SDK in the GitHub Actions environment and here we are passing Service account and SA keys for authorization. Once authorization is done, we are building, tagging, and pushing docker images to GCR and deploying applications over Cloud Run. This workflow pipeline will run on GitHub hosted infrastructure with the latest Ubuntu version as an underlying OS.Here is a video walkthrough of the configuration steps for GitHub Actions:CircleCIFor CircleCI integration, you need to have an account on CircleCI and add your GitHub Repository as a project in CircleCI. Once this is done, CircleCI will take care of deployments of your app on GCP Cloud Run.Once you add a project, CircleCI will ask you to write and commit config.yml to your GitHub repository. There are templates already present for different languages and frameworks. You can ignore these right now and follow the CircleCI Pipeline Code. You can just paste it and commit it.This pipeline has 2 jobs, one for dockerizing and deploying apps in the dev environment, and another one for the prod environment. The pipeline for the Dev environment will run when there is a change or commit in the main branch whereas the one for the prod environment will run when there is a change or commit in the prod branch.To allow CircleCI to deploy apps to GCP, we have to add the GCP Service Account in the CircleCI Environment variables which will be passed each time the CircleCI pipeline runs. From Projects➞Your Project➞Projects Settings (on the top right)➞Environment Variables. Click add Environment Variables and add the Service Account Key.Once this is done, CircleCI will deploy your app over GCP Cloud Run.Below is a video walkthrough of the configuration steps for CircleCI:ConclusionIn this blog post, we have shown how to deploy the backend service of the OmegaTrade app with the Cloud Spanner emulator in 4 different CI/CD pipelines:Cloud BuildJenkinsGitHub ActionsCircleCIWe’ve also briefly covered deploying to production. Note that if you’re setting up a Development environment, you may wish to consider using the emulator for your testing/validation needs. This blog post has more details on how you can set that up (locally or remotely).To learn more about Cloud Spanner, visit the product page. To learn more about the Cloud Spanner emulator, take a look at the official documentation.Related ArticleDeploying the Cloud Spanner Emulator remotelyLearn how to deploy the Cloud Spanner emulator remotely to GCE and Cloud Run, both manually and via Terraform.Read Article
Quelle: Google Cloud Platform

Milliardenschwere IT-Konzerne aus den USA zahlen heute niedrigere Steuersätze als ihre Beschäftigten. Dagegen ist die globale Mindeststeuer nur ein erster kleiner Schritt. Eine Analyse von Achim Sawall (Politik/Recht, Google)
Quelle: Golem

Facebook hat Ärger und Twitch verteilt Geld: die Woche im Video. (Golem-Wochenrückblick, Soziales Netz)
Quelle: Golem
Avoimuuden hengessä, avaamme eri toimialojen IT-johtajien kanssa käymiämme keskusteluja ja jaamme heidän näkemyksiään teknologiaan, avoimeen lähdekoodiin, kulttuuriin ja moneen muuhun. Meitä ajaa halu oppia heidän haasteistaan ja miten voimme paremmin ratkaista ongelmia jatkossa.
Quelle: CloudForms
Sebastian Hetze is a Red Hat Principal Solution Architect, but was a taxi cab driver when he first started getting into free software. We’ve seen people from all different backgrounds contribute to Linux and open source. Read his story:
Quelle: CloudForms
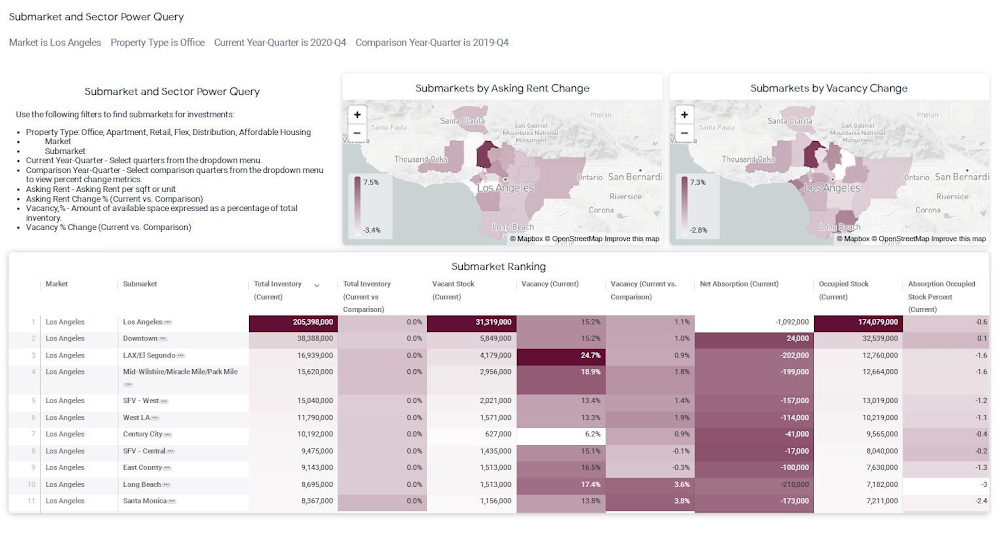
Editor’s note: Today we are hearing from Ben Hizak, co-founder of Cherre. He shares Cherre’s approach to consolidating multiple data sets into one data warehouse to power BI and analytics for their customers. He explains how the company uses Google Cloud and Cloud SQL to bring real estate datasets together and help customers make better data-driven decisions.Cherre’s quest to transform real estate investing and underwriting into a science requires us to connect thousands of datasets and make them accessible for investment, management and underwriting decisions. By delivering actionable insights based on fresh data, our clients can answer questions that they could never answer before. Each of our clients is interested in a different combination of public and paid datasets, which is then to be combined with that client’s private data. All of this has to be done in a secure, scalable and repeatable manner. We process this data in BigQuery and then store it in Cloud SQL for PostgreSQL, a single source of truth that our clients can use to train machine learning models, consume via an API which runs on Google Kubernetes Engine (GKE), or visualize using BI tools like Looker.A sample combination of public and paid datasets displayed in LookerBefore Cherre, this kind of consolidated data work was simply not available in the real estate industry. Before Cherre, datasets were never in one place, and each dataset contained different properties with different attributes. For example, data on transactions from one vendor and data on securitized debt from another lived in completely different worlds prior to Cherre. And private data vendors never before let raw data leave their systems. Building that trust so those vendors now allow their data onto our platform has been a unique honor and responsibility.Our clients are large organizations such as large real estate funds, banks, and insurance companies, which manage billions of dollars each. For them, the difference between a right decision and a wrong decision can make the difference between a successful business and a failed business. Their need for speed is insatiable. We enable our clients to make better decisions faster by putting clean, connected data at their fingertips. Cherre customers can evaluate opportunities and trends faster and more accurately, and efficiently manage their portfolios, while saving millions of dollars in manual data collection and analytics costs.Consolidating data to turn investing into a scienceConsolidating thousands of datasets and millions of data points requires both technical capabilities and human sensitivities. We serve as a center point for two sets of stakeholders — for large institutions that require the highest levels of security and for providers of proprietary data that stake their reputations on our ability to deliver their data on comparable or better infrastructure than they provide to their own clients. Our reputation relies on the strength of our technical infrastructure. Why PostgresWhen choosing a database to back our API, Postgres was the natural solution. It is feature-rich, fast, and has a strong community. Postgres also has strong geospatial abilities, which is an absolute requirement for clients in our industry.Postgres and GraphQL combine well to serve different use cases in a ‘wide data’ scenarioTo understand our stack, it helps to understand our data. Most data engineers are working in a “thin and fast” scenario; a small number of fields have to be processed very rapidly. Our case is the opposite. Real estate data is “wide and slow(er)”; our input consists of many thousands of tables. We reduce these to something more manageable, just over 100 tables and thousands of columns for certain clients, which they then can consume via our API and visualize in Looker. Some of our clients even run their calculations directly on our infrastructureREST doesn’t cut itEvery client asks different questions from their data. While some might care about specifics in a certain building — number of tenants, average occupancy or length of occupancy — others will be more interested in general information, such as fire safety codes. . Our clients expect to be able to filter on any column and traverse datasets without having to understand how they join together. In the classic world of REST APIs, clients would have to pull all the objects and know how to assemble them on the client’s side. However, that would be antithetical to our purpose — to make data ingestions as simple as possible. Data wrangling is our job. We had to look for a different approach, which required a very different architecture.GraphQL—a more modern type of API — comes in handy. Not only does it prevent over-fetching and under-fetching of data, but it also joins tables and traverses relationships (one-to-many, many-to-one, many-to-many) in a way that is seamless for the client. Real estate data can be difficult to wrangle in that it comes from thousands of authorities, in various formats and qualities. The data is built on various objects, often lacking a consistent key or identical data point, which makes for complex and very subtle joins. Cherre wanted to take on that burden, and not pass it to our clients. This is where GraphQL shines. Employing GraphQL lets Cherre focus on the minutiae so that our clients can focus on the big picture.GraphQL allows each of our clients to query only the objects and fields that they care about, and have them be joined, filtered and aggregated on the server side, yielding a response that is easy to consume. Take the following example in which we conduct a one-to-many join: buildings with their apartments (units), and filtering on both entities:In this example, we can see a many-to-one query, because each apartment belongs to only one building:And in this example we can see a one-to-many query that pulls apartments based on the building they belong to (in this case buildings that were built after 2010 and have a doorman).Disposable tables – Because you can’t always get it right the first timeSince Cherre is working on thousands of datasets and tens of thousands of input fields, the chances that we will misunderstand and miscalculate a field are so high as to be a certainty. To preempt this, we wanted to be able to rebuild our output from scratch. We were looking for something like “disposable infrastructure” but for datasets. We decided that Cherre would not operate on existing data and instead, would always recompute what we need from scratch. This approach is often called immutable tables. If there’s a mistake, you can fix the code and rerun — voila, mistake corrected.To achieve this, Cherre builds immutable tables that live for a short time. We then funnel some or all of the client traffic to the new table. We keep the old table in case we need to do a zero-downtime rollback, but ultimately delete the old table to conserve space. We delete data with full confidence that we can rebuild it from scratch, by running the appropriate version of the code.Immutable tables are more costly and take longer to compute, but they allow Cherre to iterate more quickly with the confidence that nothing is ever lost. It also allows us to compare two versions of our output.Why Cloud SQLAs you can see, our database needs are not trivial, which is why we chose Cloud SQL for PostgreSQL. We need to control our costs, and we do it using Cloud SQL committed-use discounts (CUDs and) and a cost monitoring tool from DoIT international. We also need high availability, read replicas, and backup management. Cloud SQL does all that for us so we don’t have to spend development time on it. It also saves us time we’d have otherwise had to spend patching and upgrading the software. We use Google Cloud projects to implement robust information security, so having a database that sits well within the Google projects system enables us to be consistent across the organization with the way we manage permissions and security. And we leverage Config Connector, which allows us to provision Google Cloud resources through Kubernetes. Since we want to use infrastructure-as-code for everything and we are using Google Kubernetes Engine (GKE), it was natural for us to use Config Connector for our operations.Looking aheadWe’re extremely proud of what we’ve built, but there’s always room for improvement. As technology continues to evolve and as we continue to develop, we’re seeking out new opportunities to become more efficient. We’re also looking to leverage deeper database optimization, which is much easier to do now, thanks to Query Insights. More information is becoming available every day. The buyers, sellers and other real estate professionals that can make smarter decisions based on that data will gain an edge in the marketplace. We’re committed to making the connections they need to get ahead. Read more about Cloud SQL, Cloud SQL insights and Looker in our documentation or take the Cloud SQL insights code lab.
Quelle: Google Cloud Platform
Google Cloud Next is less than a week away. Register now to join us October 12–14, 2021, for our no-cost, three-day flagship event to discover live and on-demand content that allows you to connect with experts, see the latest tech in action, and sharpen your skills around all things cloud.To make the most of Next ’21, be sure to check out as many of these top five things to do as possible:Kick off the first two days with a keynote. On October 12 at 9 AM PT, get your daily dose of cloud insights from leaders like Google and Alphabet CEO Sundar Pichai and Google Cloud CEO Thomas Kurian. On day two, be sure to catch the Developer keynote with Google Cloud SVP of Technical Infrastructure Urs Hölzle where he reveals our vision for the top three cloud technology trends for the next decade.Customize your content. Search and filter the catalog to find your favorite sessions, build your own playlists, and share them on Twitter, LinkedIn, and more – don’t forget to tag your posts with #GoogleCloudNext. Need some inspiration? Check out our personal playlists like Advanced app dev for developers! from Director of Product Management Aparna Sinha, Developer Advocate Stephanie Wong’s Looking for more technical data sessions? – and my own, Marketers who love data, with a side of collaboration. Or take a quick quiz and we’ll build a suggested playlist based on your availability and interests.Engage with experts. Get help solving your toughest business challenges. Participate in expert-led live Q&As with topics on data cloud, open cloud infrastructure, and more than 40 online interactive labs. Meet your peers in over 20 community conversations covering everything from building with Google Workspace to getting started with Vertex AI. Or chat with the Women Techmakers team, the authors of the 2021 State of DevOps report, or Google developers from APAC, EMEA and India.Dive in to demos. See how forward-thinking businesses use Google Cloud with our featured demos. Chess.com drives the future of the 1,500-year-old game by scaling to meet the demands of 11 million live matches per day with in-game, real-time player feedback. And international automaker Renault built its industry data management platform on Google Cloud to optimize production and operations worldwide. Chat with presenters at our live demos as you learn what’s new with Google Workspace, how to go beyond the basics of zero trust with BeyondCorp Enterprise, and more. Take action with Diversity, Equity & Inclusion (DEI) sessions. Learn how you can champion diversity, build community, and drive change with data-driven DEI discussions and sessions that explore how to turn core DEI values into real-world impact. Learn how healthcare providers enable accessible healthcare through technology to predict outcomes and craft personalized prevention plans. Or join Jim Hogan, principal innovation strategist at Google Cloud, in conversation with one of the founders of the internet, Vint Cerf, as they discuss how Cerf’s personal experiences with disability led to his belief that accessibility is the cornerstone of innovation.Be sure to tune in to Next ’21 on October 12–14 to get informed, be inspired, and expand your expertise.Related ArticleNext OnAir as it happens: All the announcements in one placeWe’ll be sharing lots of news, updates, and learning opportunities throughout Next OnAir. Check back here to see a running list of what’s…Read Article
Quelle: Google Cloud Platform

Migrations are not easy: they take time, energy and effort to make them successful. BigQuery makes it easier with customizable tools and years of expertise to help out with your journey to the cloud. In line with our commitment to providing an open and flexible platform, we have built these migration tools following an open approach which enables flexibility and choice for you and your partners when migrating to BigQuery. Comprehensive solution for migration to BigQueryToday, we are announcing the preview of BigQuery Migration Service, a set of free-to-use tools to help you with your end-to-end migration needs. This service speeds up Teradata to BigQuery migrations with tooling covering migration planning, data transfer, automated SQL/script conversion and data verification. Support for additional data warehouses is coming soon.Assessment: Plan and manage migration risks and costsWhen we work with customers and partners on migrations, the most important step is to understand their ecosystem, requirements and business goals. We use this information to create a custom migration plan to help prepare and execute migrations. Over and over again, we have seen that identifying and addressing migration complexities ahead of time leads to reduced TCO and lower risk migrations.To that end, we are excited to announce private preview of our automated assessment tool as part of the BigQuery Migration Service. Assessment leverages our many years of experience helping some of the large organizations in the world modernize with BigQuery. It provides an easy and automated way to collect statistics from your legacy warehouse and generates a state analysis report consisting of: List of database objects, data I/O patterns and dependenciesAutomated query translation coverage and resultsQuery-to-Object mapping (e.g., which tables, views, functions it uses)User-to-Table mapping (e.g., which users access which tables)Table correlations (e.g., tables which are often joined or sub queried)List of BI/ETL tools in useThe summary report helps you efficiently prioritize and have a clear understanding of all the components and the amount of work required to execute a migration. In addition, all the underlying assessment data is made available within a BigQuery dataset for complete customization and ad-hoc analysis for you and your migration partners. SQL translation: Reduce manual effort, time and errors One of the hardest pieces of a data warehouse migration is modernizing legacy business logic, such as SQL queries, scripts and stored procedures. This process normally involves substantial manual query rewrites and verifications, which is time consuming and error prone. Today, we are excited to announce the public preview of batch and interactive SQL translation which helps automate much of this process, thus speeding up your path to a successful migration. Batch and interactive SQL translation provides fast, semantically correct and human readable translations of legacy objects with no ongoing dependencies post migration. It supports a broad range of Teradata artifacts including DML, DDL and BTEQ. Translations can be run in batch mode or ad-hoc directly from the BigQuery SQL workspace. Early users of SQL translation saw ~95% successful translations on 10M+ queries, leaving only ~5% of queries for manual review with their migration partners. Interactive SQL translation provides a split view within the BigQuery SQL editor. Users can type in SQL queries in non-BigQuery dialects and view the translated BigQuery SQL immediately. Interactive SQL translation provides users with a live, real time SQL translation tool which allows users to self-serve translation of their queries in parallel with a centralized large-scale SQL migration effort. This not only reduces the time and effort for analysts to migrate their queries, but also increases how quickly they learn to leverage the modern capabilities of BigQuery.Data Validation: Verify correctness of dataData validation is a crucial step in data warehouse migration projects. It compares structured and semi-structured data from the source and target to confirm data and logic has been moved correctly. The GCP Data Validation Tool (DVT) is an open sourced CLI tool that leverages open-source frameworks. It offers customized multi-level validation functions to compare source and target tables on the table level, column level, and row level. It is also flexible, meaning that new validation rules can easily be plugged in as you see fit. Furthermore, to facilitate automation, orchestration and scheduling, it can also be integrated with Cloud Functions, Cloud Run, and Composer for recurring validation.Customize BigQuery Migration Service to your needsWith BigQuery Migration Service we are fast tracking, simplifying and de-risking your migration so that you can modernize your data warehouse with BigQuery, a truly serverless and modern data warehouse, with confidence. We are starting with Teradata migration capabilities, but will add support for additional data warehouses soon. We have built end-to-end tools with openness top-of-mind which you and your migration partner of choice can customize to help ensure a successful migration. From assessment which streamlines metrics collection and exposes the raw dataset for full customization to our open source Data Validation Tool, where you and your partner can add custom validation logic, we are committed to giving you migrations tools you can customize to your unique needs. Our tools are freely available to help speed up your migration. If you would like to leverage our tools for an upcoming proof-of-concept or migration, reach out to your favorite GCP partner, your GCP sales rep or check out our documentation. We look forward to partnering with you on your journey to the cloud.
Quelle: Google Cloud Platform