Clusterübergreifende Replikation wird jetzt auf bestehenden Amazon-OpenSearch-Service-Domänen unterstützt

Amazon OpenSearch Service unterstützt jetzt die clusterübergreifende Replikation auf bestehenden Domänen. Mit der clusterübergreifenden Replikation können Sie automatisch Indexe von einer Domäne in eine andere mit geringer Latenz in denselben oder in verschiedenen AWS-Konten oder -Regionen kopieren und synchronisieren. Mit der clusterübergreifenden Replikation, können Sie eine hohe Verfügbarkeit für Ihre unternehmenskritischen Anwendungen mit sequenzieller Datenkonsistenz erreichen.
Quelle: aws.amazon.com

Cloud Native and Industry News — Week of March 30, 2022

Every Thursday, Nick Chase and Eric Gregory from Mirantis go over the week’s cloud native and industry news. This week they discussed: Log4j and other security news in the cloud native space Cybercrime in 2021 Amazon and the Cloud ecosystem Legislation impacting cloud technology Developments in Go and Java You can watch the full replay … Continued
Quelle: Mirantis

Congrats to Chandra Dodda, Outstanding Employee Award Winner

At Mirantis, our strength and success comes from the talent and hard work of our employees, and we believe in recognizing and rewarding excellence. Each quarter, our HR team asks managers across the company to nominate candidates for our Outstanding Employee awards. Outstanding Employees not only embody Mirantis’ core values but also produce outstanding results … Continued
Quelle: Mirantis

Boost the power of your transactional data with Cloud Spanner change streams

Data is one of the most valuable assets in today’s digital economy. One way to unlock the value of your data is to give it life after it’s first collected. A transactional database, like Cloud Spanner, captures incremental changes to your data in real time, at scale, so you can leverage it in more powerful ways. Cloud Spanner is our fully managed relational database that offers near unlimited scale, strong consistency, and industry-leading high availability of up to 99.999%. The traditional way for downstream systems to use incremental data that’s been captured in a transactional database is through change data capture (CDC), which allows you to trigger behavior based on changes to your database, such as a deleted account or an updated inventory count.Today, we are announcing Spanner change streams, coming soon, that lets you capture change data from  Spanner databases and easily integrate it with other systems to unlock new value. Change streams for Spanner goes above and beyond the traditional CDC capabilities of tracking inserts, updates, and deletes. Change streams are highly flexible and configurable, letting you track changes on exact tables and columns or across an entire database. You can replicate changes from Spanner to BigQuery for real-time analytics, trigger downstream application behavior using Pub/Sub, and store changes in Google Cloud Storage (GCS) for compliance. This ensures you have the freshest data to optimize business outcomes. Change streams provides a wide range of options to integrate change data with other Google Cloud services and partner applications through turnkey connectors, including custom Dataflow processing pipelines or the change streams read API.Spanner consistently processes over 1.2 billion requests per second. Since change streams are built right into Spanner, you not only get industry-leading availability and global scale—you also don’t have to spin up any additional resources. The same IAM permissions that already protect your Spanner databases can be used to access change streams queries.Change stream queries are protected by spanner.databases.select, and change stream DDL operations are protected by spanner.databases.updateDdl.Change streams in actionIn this section, we’ll look at how to set up a change stream that sends change data from Spanner to an analytic data warehouse in BigQuery.Creating a change stream As discussed above, a change stream tracks changes on an entire database, a set of tables, or a set of columns in a database. Each change stream can have a retention period of anywhere from one day to seven days, and you can set up multiple change streams to track exactly what you need for your specific business objectives. First, we’ll create a change stream on a table called InventoryLedger. This table tracks inventory changes on two columns: InventoryLedgerProductSku and InventoryLedgerChangedUnits with a 7-day retention period.Change recordsEach change record contains a wealth of information, including primary key, the commit timestamp, transaction ID, and of course, the old and new values of the changed data, wherever applicable. This makes it easy to process change records as an entire transaction, in sequence based on their commit timestamp, or individually as they arrive, depending on your business needs. Back to the inventory example, now that we’ve created a change stream on the InventoryLedger table, all inserts, updates, and deletes on this table will be published to the InventoryStream change stream. These changes are strongly consistent with the commits on the InventoryLedger table: When a transaction commit succeeds, the relevant changes will automatically persist in the change stream. You never have to worry about missing a change record.Processing a change streamThere are numerous ways that you can process change streams depending on the use case:Analytics: You can send the change records to BigQuery, either as a set of change logs or by updating the tables.  Event triggering: You can send change logs to Pub/Sub for further processing by downstream systems. Compliance: You can retain the change log to Google Cloud Storage for archiving purposes. The easiest way to process change stream data is to use our Spanner connector for Dataflow, where you can take advantage of Dataflow’s built-in pipelines to BigQuery, Pub/Sub, and Google Cloud Storage. The diagram below shows a Dataflow pipeline that processes this change stream and imports change data directly into BigQuery.Alternatively, you can build a custom Dataflow pipeline to process change data with Apache Beam. In this case, we provide a Dataflow connector that outputs change data as an Apache Beam PCollection of DataChangeRecord objects. For even more flexibility, you can use the underlying change streams query API. The query API is a powerful interface that lets you read directly from a change stream to implement your own connector and stream changes to the pipeline of your choice. On the query API side, a change stream is divided into multiple partitions, which can be used to query a change stream in parallel for higher throughput. Spanner dynamically creates these partitions based on load and size. Partitions are associated with a Spanner database split, allowing change streams to scale as effortlessly as the rest of Spanner.Get started with change streamsWith change streams, your Spanner data follows you wherever you need it, whether that’s for analytics with BigQuery, for triggering events in downstream applications, or for compliance and archiving. Change streams are highly flexible and configurable —allowing you to capture change data for the exact data you care about, and for the exact period of time that matters for your business. And because change streams are built into  Spanner, there’s no software to install, and you get external consistency, high scale, and up to 99.999% availability.There’s no extra charge for using change streams, and you’ll pay only for extra compute and storage of the change data at the regular Spanner rates.To get started with Spanner, create an instance, or try it out with a Spanner Qwiklab.We’re excited to see how Spanner change streams will help you unlock more value out of your data!Related ArticleCloud Spanner myths bustedThe blog talks about the 7 most common myths and elaborates the truth for each of the myths.Read Article
Quelle: Google Cloud Platform

Meet Google’s unified data and AI offering

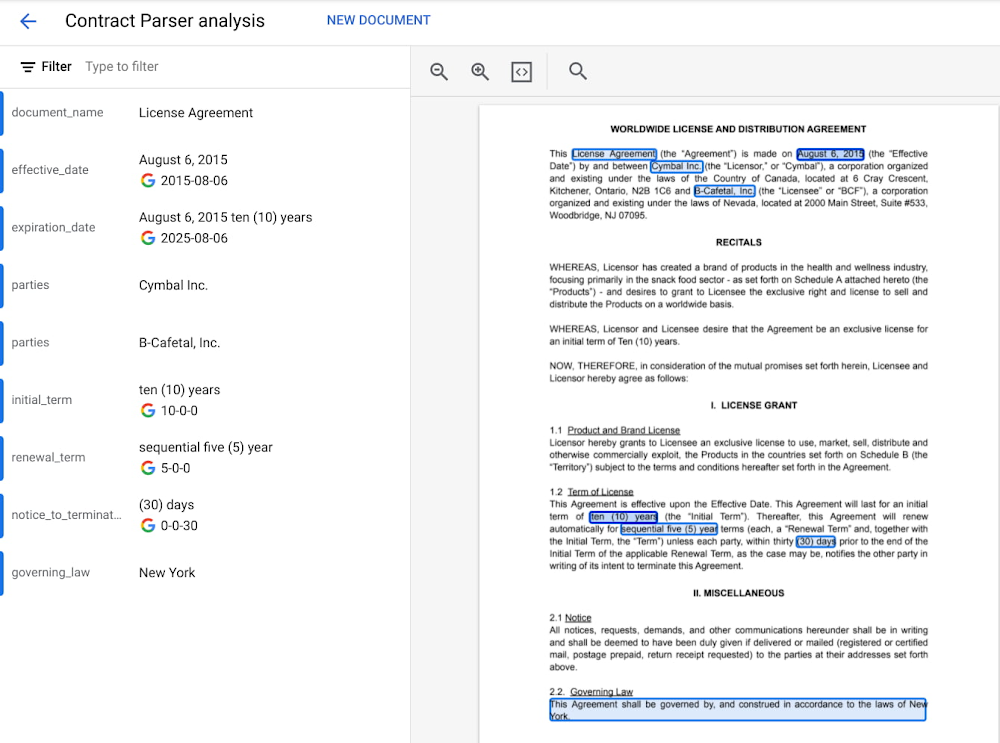
Without AI, you’re not getting the most out of your data.Without data, you risk stale, out-of-date, suboptimal models.But most companies are still struggling with how to keep these highly interdependent technologies in sync and operationalize AI to take meaningful action from data.We’ve learned from Google’s years of experience in AI development how to make data-to-AI workflows as cohesive as possible and as a result our data cloud is the most complete and unified data and AI solution provider in the market. By bridging data and AI, data analysts can take advantage of user-friendly, accessible ML tools, and data scientists can get the most out of their organization’s data. All of this comes together with built-in MLOps to ensure all AI work — across teams — is ready for production use. In this blog we’ll show you how all of this works, including exciting announcements from the Data Cloud Summit:Vertex AI Workbench is now GA bringing together Google Cloud’s data and ML systems into a single interface so that teams have a common toolset across data analytics, data science, and machine learning. With native integrations across BigQuery, Spark, Dataproc, and Dataplex data scientists can build, train and deploy ML models 5X faster than traditional notebooks. Introducing Vertex AI Model Registry, a central repository to manage and govern the lifecycle of your ML models. Designed to work with any type of model and deployment target, including BigQuery ML, Vertex AI Model Registry makes it easy to manage and deploy models. Use ML to get the most out of your data, no matter the formatAnalyzing structured data in a data warehouse, like using SQL in BigQuery, is the bread and butter for many data analysts. Once you have data in a database, you can see trends, generate reports, and get a better sense of your business. Unfortunately, a lot of useful business data isn’t in the tidy tabular format of rows and columns. It’s often spread out over multiple locations and in different formats, frequently as so-called “unstructured data” — images, videos, audio transcripts, PDFs — can be cumbersome and difficult to work with. Here, AI can help. ML models can be used to transcribe audio and videos, analyze language, and extract text from images—that is, to translate elements of unstructured data into a form that can be stored and queried in a database like BigQuery. Google Cloud’s Document AI platform, for example, uses ML to understand documents like forms and contracts. Below, you can see how this platform is able to intelligently extract structured text data from an unstructured document like a resume. Once this data is extracted, it can be stored in a data warehouse like BigQuery.Bring machine learning to data analysts via familiar toolsToday, one of the biggest barriers to ML is that the tools and frameworks needed to do ML are new and unfamiliar. But this doesn’t have to be the case. BigQuery ML, for example, allows you to train sophisticated ML models at scale using SQL code, directly from within BigQuery. Bringing ML to your data warehouse alleviates the complexities of setting up additional infrastructure and writing model code. Anyone who can write SQL code can train a ML model quickly and easily.Easily access data with a unified notebook interfaceOne of the most popular ML interfaces today are notebooks: interactive environments that allow you to write code, visualize and pre-process data, train models, and a whole lot more. Data scientists often spend most of their day building models within notebook environments. It’s crucial, then, that notebook environments have access to all of the data that makes your organization run, including tools that make that data easy to work with. Vertex AI Workbench, now generally available, is the single development environment for the entire data science workflow. Integrations across Google Cloud’s data portfolio allow you to natively analyze your data without switching between services:Cloud Storage: access unstructured dataBigQuery: access data with SQL, take advantage of models trained with BigQuery MLDataproc: execute your notebook using your Dataproc cluster for controlSpark: transform and prepare data with autoscaling serverless SparkBelow, you’ll see how you can easily run a SQL query on BigQuery data with Vertex AI Workbench.But what happens after you’ve trained the model? How can both data analysts and data scientists make sure their models can be utilized by application developers and maintained over time?Go from prototyping to production with MLOpsWhile training accurate models is important, getting those models to be scalable, resilient, and accurate in production is its own art, known as MLOps. MLOps allow you to:Know what data your models are trained onMonitor models in productionMake training process repeatableServe and scale model predictionsA whole lot more! (See the “Practitioners Guide to MLOps” whitepaper for a full and detailed overview of MLOps)Built-in MLOps tools within Vertex AI’s unified platform remove the complexity of model maintenance. Practical tools can help with everything from training and hosting ML models, managing model metadata, governance, model monitoring, and running pipelines – all critical aspects of running ML in production and at scale. And now, we’re extending our capabilities to make MLOps accessible to anyone working with ML in your organization. Easy handoff to MLOps with Vertex AI Model RegistryToday, we’re announcing Vertex AI Model Registry, a central repository that allows you to register, organize, track, and version trained ML models and is designed to work with any type of model and deployment target, whether that’s through BigQuery, Vertex AI, AutoML, custom deployments on GCP or even out of the cloud.Vertex AI Model Registry is particularly beneficial for BigQuery ML. While BigQuery ML brings the powerful scalability of BigQuery for batch predictions, using a data warehouse engine for real-time predictions just isn’t practical. Furthermore, you might start to wonder how to orchestrate your ML workflows based in BigQuery. You can now discover and manage  BigQuery ML models and easily deploy those models to Vertex AI for real-time predictions and MLOps tools. End-to-End MLOps with pipelinesOne of the most popular approaches to MLOps is the concept of ML pipelines: where each distinct step in your ML workflow from data preparation to model training and deployment are automated for sharing and reliably reproducing. Vertex AI Pipelines is a serverless tool for orchestrating ML tasks using pre-built components or your own custom code. Now, you can easily process data and train models with BigQuery, BigQuery ML, and Dataproc directly within a pipeline. With this capability, you can combine familiar ML development within BigQuery and Dataproc into reproducible, resilient pipelines and orchestrate your ML workflows faster than ever.See an example of how this works with the new BigQuery and BigQuery ML components.Learn more about how to use BigQuery and BigQuery ML components with Vertex AI Pipelines.Learn more and get started We’re excited to share more about our unified data and AI offering today at the Data Cloud Summit. Please join us for the spotlight session on our “AI/ML strategy and product roadmap” or the “AI/ML notebooks ‘how to’ session.”And if you’re ready to get hands on with Vertex AI, check out these resources:Codelab: Training an AutoML model in Vertex AICodelab: Intro to Vertex AI WorkbenchVideo Series: AI Simplified: Vertex AIGitHub: Example NotebooksTraining: Vertex AI: Qwik StartRelated ArticleWhat is Vertex AI? Developer advocates share moreDeveloper Advocates Priyanka Vergadia and Sara Robinson explain how Vertex AI supports your entire ML workflow—from data management all t…Read Article
Quelle: Google Cloud Platform