Elektroauto: Chinesischer Hersteller ahmt Tesla Model 3 nach
Der Changan Shenlan SL03 ist eine Elektroauto-Limousine, die an das Model 3 von Tesla erinnert, das ebenfalls in China produziert wurde. (Tesla, Technologie)
Quelle: Golem

Der Changan Shenlan SL03 ist eine Elektroauto-Limousine, die an das Model 3 von Tesla erinnert, das ebenfalls in China produziert wurde. (Tesla, Technologie)
Quelle: Golem

Einst nur in OEM-Systemen verfügbar, ist der Threadripper Pro 5995WX mit seiner brachialen Leistung mittlerweile einzeln erhältlich. Ein Test von Martin Böckmann (AMD Zen, Prozessor)
Quelle: Golem

Der Netgear AXE3000 ist ein WLAN-Adapter, der per Wi-Fi 6E im 6-GHz-Band funken kann. Das soll Datenraten und Funkstabilität erhöhen. (Wi-Fi 6, Netzwerk)
Quelle: Golem

Das Mining von Kryptowährungen solle vorerst weiterlaufen. Berichten zufolge hat Compute North 500 Millionen US-Dollar Schulden. (Kryptomining, Kryptowährung)
Quelle: Golem

Für die Umsetzung bei Youtube arbeitet Google wohl an Open-Source-Alternativen zu Dolby Vision und Dolby Atmos. Ein Konsortium könnte folgen. (Google, Raumklang)
Quelle: Golem

Java and Go vulnerability scanning supportGoogle Cloud’s Container Scanning API now automatically scans Maven and Go packages for vulnerabilities.With the Container Scanning API enabled, any containers including Java (in Maven repositories) and Go language packages that are uploaded to an Artifact Registry repository will be scanned for vulnerabilities. This capability builds on existing Linux OS based vulnerability detection and provides customers with deeper insight into their applications. This feature is in Public Preview which makes it available to all Google Cloud customers.Get started with Artifact Registry via the instructions for Go or the instructions for Java.How it worksOnce the API is enabled, upload a container image which contains Go and/or Maven packages.Vulnerability totals for each image digest are displayed in the Vulnerabilities column. Customers can then drill down on the vulnerability to get CVE numbers, and if available, a suggested fix.Vulnerabilities can also be displayed via the gcloud CLI and the API.To view a list of vulnerabilities from the gcloud CLI, the following can be used.code_block[StructValue([(u’code’, u’gcloud artifacts docker images list –show-occurrences LOCATION-docker.pkg.dev/PROJECT_ID/REPOSITORY/IMAGE_ID –format=json’), (u’language’, u”), (u’caption’, <wagtail.wagtailcore.rich_text.RichText object at 0x3e36f7539950>)])]To view a list of vulnerabilities with the API, run the following command.code_block[StructValue([(u’code’, u’curl -X GET -H “Content-Type: application/json” -H \rn “Authorization: Bearer $(gcloud auth print-access-token)” \rn https://containeranalysis.googleapis.com/v1/projects/PROJECT_ID/occurrences’), (u’language’, u”), (u’caption’, <wagtail.wagtailcore.rich_text.RichText object at 0x3e36f4ebf290>)])]Integrate your Workflows via API and Pub/SubThis feature now makes it possible to scan Java (in Maven repositories) and Go language packages both via the existing On-Demand scan capability, and with an automatic scan on push to Artifact Registry. Language scanning is in addition to the Linux OS scanning which is already available.This capability can be combined with Pub/Sub notifications to trigger additional actions for the vulnerabilities and other metadata. An example of this is sending an e-mail notification to those who need the information.Organizations are increasingly concerned about the supply chain risks associated with building their applications using open source software. Being able to scan applications for vulnerabilities is an important step for customers to enhance their security posture. Language package vulnerabilities are available in the same formats that customers are already familiar with. They appear alongside OS vulnerabilities within the Artifact Registry UI, and are available through existing CLI and APIs. These steps aid customers in identifying the potential vulnerabilities introduced in software packages and make appropriate decisions with that information. Learn more about types of vulnerability scanning.Related ArticleBuilding a secure CI/CD pipeline using Google Cloud built-in servicesBuild a secure CI/CD pipeline using Google Cloud’s built-in services using Cloud Build, Cloud Deploy, Artifact Registry, Binary Authoriza…Read Article
Quelle: Google Cloud Platform
We’re fortunate to work with some of the world’s most innovative customers on a daily basis, many of whom come to Google Cloud for our well-established expertise in data analytics and AI. As we’ve worked and partnered with these data leaders, we have encountered similar priorities among many of them: to remove the barriers of data complexity, unlock new use cases, and reach more people with more impact. These innovators and industry disruptors power their data innovation with a data cloud that lets their people work with data of any type, any source, any size, and at any speed, without capacity limits. A data cloud that lets them easily and securely move across workloads: from SQL to Spark, from business intelligence to machine learning, with little infrastructure set up required. A data cloud that acts as the open data ecosystem foundation needed to create data products that employees, customers, and partners use to drive meaningful decisions at scale.On October 11, we will be unveiling a series of new capabilities at Google Cloud Next ‘22 that continue to support this vision. If you haven’t registered yet for the Data Cloud track at Google Next, grab your spot today! But I know you data devotees probably can’t wait until then. So, we wanted to take some time before Next to share some recent innovations for data cloud that are generally available today. Consider these the data hors d’oeuvres to your October 11 data buffet.Removing the barriers of data sharing, real-time insights, and open ecosystemsThe data you need is rarely stored in one place. More often than not data is scattered across multiple sources and in various formats. While data exchanges were introduced decades ago, their results have been mixed. Traditional data exchanges often require painful data movement and can be mired with security and regulatory issues. This unique use case led us to design Analytics Hub, now generally available, as the data sharing platform for teams and organizations who want to curate internal and external exchanges securely and reliably. This innovation not only allows for the curation and sharing of a large selection of analytics-ready datasets globally, it also enables teams to tap into the unique datasets only Google provides, such as Google Search Trends or the Data Commons knowledge graph.Analytics Hub is a first-class experience within BigQuery. This means you can try it now for free using BigQuery, without having to enter any credit card information. Analytics Hub is not the only way to bring data into your analytical environment rapidly. We recently launched a new way to extract, load, and transform data in real-time into BigQuery: the Pub/Sub “BigQuery subscription.” This new ELT innovation simplifies streaming ingestion workloads, is simpler to implement, and is more economical since you don’t need to spin up new compute to move data and you no longer need to pay for streaming ingestion into BigQuery. But what if your data is distributed across lakes, warehouses, multiple clouds, and file formats? As more users demand more use cases, the traditional approach to build data movement infrastructure can prove difficult to scale, can be costly, and introduces risk. That’s why we introduced BigLake, a new storage engine that extends BigQuery storage innovation to open file formats running on public cloud object stores. BigLake lets customers build secure, data lakes over open file formats. And, because it provides consistent, fine-grained security controls for Google Cloud and open-source query engines, security only needs to be configured in one place to be enforced everywhere. Customers like Deutsche Bank, Synapse LLC, and Wizard have been taking advantage of BigLake in preview. Now that BigLake is generally available, I invite you to learn how it can help to build your own data ecosystem.Unlocking the ways of working with dataWhen data ecosystems expand to data of all shape, size, type, and format, organizations struggle to innovate quickly because their people have to move from one interface to the next, based on their workloads. This problem is often encountered in the field of machine learning, where the interface for ML is often different than that of business analysis. Our experience with BigQuery ML has been quite different: customers have been able to accelerate their path to innovation drastically because machine learning capabilities are built-in as part of BigQuery (as opposed to “bolted-on” in the case of alternative solutions).We’re now applying the same philosophy to log data by offering a Log Analytics service in Cloud Logging. This new capability, currently in preview, gives users the ability to gain deeper insights into their logging data with BigQuery. Log Analytics comes at no additional charge beyond existing Cloud Logging fees and takes advantage of soon-to-be generally available BigQuery features designed for analytics on logs: Search indexes,a JSON data type, and the Storage Write API. Customers that store, explore, and analyze their own machine generated data from servers, sensors, and other devices can tap into these same BigQuery features to make querying their logs a breeze. Users simply use standard BigQuery SQL to analyze operational log data alongside the rest of their business data!And there’s still more to come. We can’t wait to engage with you on Oct 11, during Next’22, to share more of the next generation of data cloud solutions. To tune into sessions tailored to your particular interests or roles, you can find top Next sessions for Data Engineers, Data Scientists, and Data Analysts — or create and share your own. Join us at Next’22 to hear how leaders like Boeing, Twitter, CNA Insurance, Telus, L’Oreal, and Wayfair, are transforming data-driven insights with Google’s data cloud. Related ArticleRegister for Google Cloud NextRegister now for Google Cloud Next ‘22, coming live to a city near you, as well as online and on demand.Read Article
Quelle: Google Cloud Platform
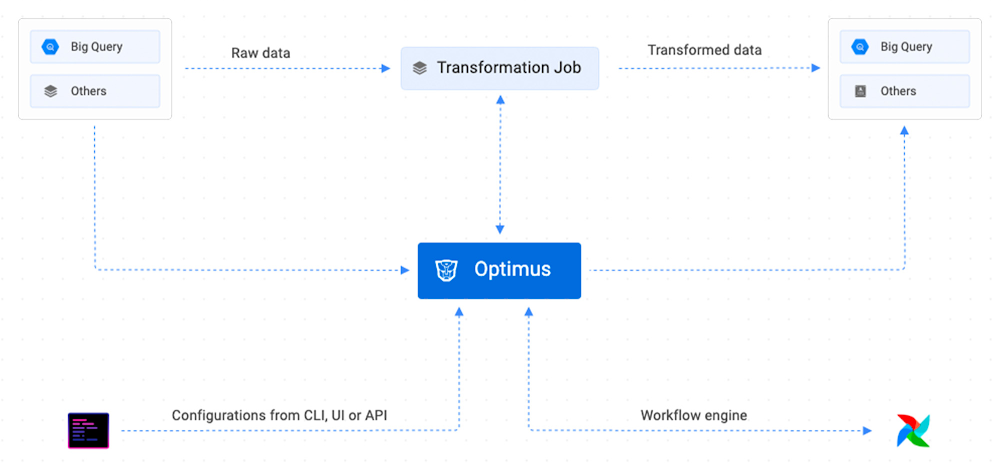
Editor’s note: Earlier this year, we heard from Gojek, the on-demand services platform, about the open-source data ingestion tool it developed for use with data warehouses like BigQuery. Today, Gojek VP of Engineering Ravi Suhag is back to discuss the open-source data transformation tool it is building.In a recent post, we introduced Firehose, an open source solution by Gojek for ingesting data to cloud data warehouses like Cloud Storage and BigQuery. Today, we take a look at another project within the data transformation and data processing flow.As Indonesia’s largest hyperlocal on-demand services platform, Gojek has diverse data needs across transportation, logistics, food delivery, and payments processing. We also run hundreds of microservices across billions of application events. While Firehose solved our need for smarter data ingestion across different use cases, our data transformation tool, Optimus, ensures the data is ready to be accessed with precision wherever it is needed.The challenges in implementing simplicityAt Gojek, we run our data warehousing across a large number of data layers within BigQuery to standardize and model data that’s on its way to being ready for use across our apps and services. Gojek’s data warehouse has thousands of BigQuery tables. More than 100 analytics engineers run nearly 4,000 jobs on a daily basis to transform data across these tables. These transformation jobs process more than 1 petabyte of data every day. Apart from the transformation of data within BigQuery tables, teams also regularly export the cleaned data to other storage locations to unlock features across various apps and services.This process addresses a number of challenges:Complex workflows: The large number of BigQuery tables and hundreds of analytics engineers writing transformation jobs simultaneously creates a huge dependency on very complex database availability groups (DAGs) to be scheduled and processed reliably. Support for different programming languages: Data transformation tools must ensure standardization of inputs and job configurations, but they must also comfortably support the needs of all data users. They cannot, for instance, limit users to only a single programming language. Difficult to use transformation tools: Some transformation tools are hard to use for anyone that’s not a data warehouse engineer. Having easy-to-use tools helps remove bottlenecks and ensure that every data user can produce their own analytical tables.Integrating changes to data governance rules: Decentralizing access to transformation tools requires strict adherence to data governance rules. The transformation tool needs to ensure columns and tables have personally identifiable information (PII) and non-PII data classifications correctly inserted, across a high volume of tables. Time-consuming manual feature updates: New requirements for data extraction and transformation for use in new applications and storage locations are part of Gojek’s operational routine. We need to design a data transformation tool that could be updated and extended with minimal development time and disruption to existing use cases.Enabling reliable data transformation on data warehouses like BigQuery With Optimus, Gojek created an easy-to-use and reliable performance workflow orchestrator for data transformation, data modeling, data pipelines, and data quality management. If you’re using BigQuery as your data warehouse, Optimus makes data transformation more accessible for your analysts and engineers. This is made possible through simple SQL queries and YAML configurations, with Optimus handling many key demands including dependency management, and scheduling data transformation jobs to run at scale.Key features include:Command line interface (CLI): The Optimus command line tool offers effective access to services and job specifications. Users can create, run, and replay jobs, dump a compiled specification for a scheduler, create resource specifications for data stores, add hooks to existing jobs, and more.Optimized scheduling: Optimus offers an easy way to schedule SQL transformation through YAML based configuration. While it recommends Airflow by default, it is extensible enough to support other schedulers that can execute Docker containers.Dependency resolution and dry runs: Optimus parses data transformation queries and builds dependency graphs automatically. Deployment queries are given a dry-run to ensure they pass basic sanity checks.Powerful templating: Users can write complex transformation logic with compile time template options for variables, loops, IF statements, macros, and more.Cross-tenant dependency: With more than two tenants registered, Optimus can resolve cross-tenant dependencies automatically.Built-in hooks: If you need to sink a BigQuery table to Kafka, Optimus can make it happen thanks to hooks for post-transformation logic that extend the functionality of your transformations.Extensibility with plugins: By focusing on the building blocks, Optimus leaves governance for how to execute a transformation to its plugin system. Each plugin features an adapter and a Docker image, and Optimus supports Python transformation for easy custom plugin development.Key advantages of OptimusLike Google Cloud, Gojek is all about flexibility and agility, so we love to see open source software like Optimus helping users take full advantage of multi-tenancy solutions to meet their specific needs. Through a variety of configuration options and a robust CLI, Optimus ensures that data transformation remains fast and focused by preparing SQL correctly. Optimus handles all scheduling, dependencies, and table creation. With the capability to build custom features quickly based on new needs through Optimus plugins, you can explore more possibilities. Errors are also minimized with a configurable alert system that flags job failures immediately. Whether to email or Slack, you can trigger alerts based on specific requirements – from point of failure to warnings based on SLA requirements.How you can contributeWith Firehose and Optimus working in tandem with Google Cloud, Gojek is helping pave the way in building tools that enable data users and engineers to achieve fast results in complex data environments.Optimus is developed and maintained at Github and uses Requests for Comments (RFCs) to communicate ideas for its ongoing development. The team is always keen to receive bug reports, feature requests, assistance with documentation, and general discussion as part of its Slack community.Related ArticleIntroducing Firehose: An open source tool from Gojek for seamless data ingestion to BigQuery and Cloud StorageThe Firehose open source tool allows Gojek to turbocharge the rate it streams its data into BigQuery and Cloud Storage.Read Article
Quelle: Google Cloud Platform
We recently announced the launch of Google Public Sector, a new Google subsidiary focused on helping U.S. federal, state, and local governments, and educational institutions accelerate their digital transformations. Google Public Sector brings Google technologies to government and education customers at scale, including open and scalable infrastructure; advanced data and analytics, artificial intelligence, and machine learning; modern collaboration tools like Google Workspace; advanced cybersecurity products; and more—so that agencies and institutions can better serve citizens and achieve their missions.In just the few months since the introduction of Google Public Sector, we’ve seen continued momentum. We announced that Google Workspace has achieved the U.S. Department of Defense’s (DOD) Impact Level 4 (IL4) authorization. And building on the success with government customers like the U.S. Navy,Defense Innovation Unit, and the U.S. Department of Veteran Affairs, we’ve also shared how we’re helping educational institutions like ASU Digital Prep—an accredited online K–12 school offered through Arizona State University—make remote immersive learning technology more accessible to students across the United States and around the world. Today, it is my pleasure to introduce Karen Dahut as the new CEO of Google Public Sector. With more than 25 years of experience in technology, cybersecurity, and analytics, Karen is a highly accomplished executive who has built businesses, developed and executed large-scale growth strategies, and created differentiated solutions across both commercial and federal industries. Karen joins us on Oct. 31. At that time, Will Grannis, who designed and launched Google Public Sector as founding CEO, will return to his role as the CTO of Google Cloud. Karen was previously sector president at Booz Allen Hamilton, where she led the company’s $4 billion global defense business—representing half of the firm’s annual revenue—and global commercial business sector, which delivered next-generation cybersecurity solutions to Fortune 500 companies. Under her leadership, Booz Allen became the premier digital integrator helping federal agencies use technology in support of their missions.Karen also has deep experience in building innovative solutions that help organizations tackle their toughest challenges. For example, at Booz Allen, she served as chief innovation officer and built the firm’s Strategic Innovation Group, which delivered new capabilities in cybersecurity, data science, and digital technologies. Prior to Booz Allen, Karen was an officer in the U.S. Navy and served as the controller for the Navy’s premier biomedical research institute. We believe Google Public Sector will continue to play a critical role in applying cloud technology to solve complex problems for our nation—across U.S. federal, state, and local governments, and educational institutions. We’re excited today to have Karen leading this new subsidiary, providing more choice in the public sector and helping scale our services to more government agencies nationwide.
Quelle: Google Cloud Platform
This blog post was co-authored by Espen Knudsen, Principal Digitalization and Innovation Advisor, Cegal.
The vast amount of applications and data in energy companies across isolated environments is exposing inefficiencies in collaboration. Together with Cegal Cetegra, Microsoft Energy Data Services will accelerate your journey toward seamless access to the data and applications you need for your day-to-day work by providing an easy-to-deploy managed service fully supported by Microsoft.
Cegal has been successfully collaborating with Microsoft and partners to help evaluate the new Microsoft Energy Data Services preview program, an enterprise-grade OSDU Data Platform powered by the cloud.
With Microsoft Energy Data Services, energy companies can leverage new cloud-based data management and collaboration capabilities provided by Cegal and Microsoft.
Microsoft Energy Data Services is a data platform fully supported by Microsoft, that enables efficient data management, standardization, liberation, and consumption in energy exploration. The solution is a hyperscale data ecosystem that leverages the capabilities of the OSDU Data Platform and Microsoft's secure and trustworthy cloud services with our partners’ extensive domain expertise.
Cegal and Microsoft create collaborative cloud-based applications on Microsoft Energy Data Services
As an ISV and a specialist systems integrator for the energy industry, Cegal has always seen great value in removing data silos to free organizations from dated constraints that can lead to lower productivity. Opening for universal access to one of the most critical assets in any organization—knowingly data—is an obvious path to innovation. Integrating proprietary IP in existing workflows, contextualizing data through new AI-based routines, and integrating best-of-breed applications to create new and innovative solutions are critical steps toward more efficient and productive operations.
To achieve this goal, Cegal and Microsoft closely collaborated over several months, during which multiple relevant use cases have been thoroughly assessed and tested on the Microsoft Energy Data Services platform. From operating the platform to developing new solutions on top of it, Cegal had the opportunity to put in context a wide range of scenarios, making sure the experience was as extensive as possible yet realistic for the energy industry.
Cegal recently released Cetegra, a cloud-based platform offering to its users a modern, collaborative environment, uniquely designed to cater to energy industry–specific needs in terms of digitalization and data management. Deployed through a fully scalable, pay-as-you-go model, Cetegra leverages the strengths of the Microsoft Cloud and will provide full support for the Microsoft Energy Data Services platform. Cetegra with Microsoft Energy Data Services delivers a one-stop shop for all types of data and applications tightly linked to OSDU, offering energy players a comprehensive integration of their applications portfolio, also allowing them to develop and test new apps within the Cetegra Innovation Space without impacting existing business operations.
With Microsoft Energy Data Services entering preview, Cegal looks forward to delivering operational support for the platform. As a global specialist in digitalization, capitalizing on years of experience within the energy sector, Cegal represents the partner of choice to support and guide energy players as they navigate their digital transformation journey.
How to work with Cegal Solutions on Microsoft Energy Data Services
Microsoft Energy Data Services is an enterprise-grade, fully-managed, OSDU Data Platform for the energy industry that is efficient, standardized, easy to deploy, and scalable for data management—for ingesting, aggregating, storing, searching, and retrieving data. The platform will provide the scale, security, privacy, and compliance that are expected by our enterprise customers. The platform offers out-of-the-box compatibility with Cegal Cetegra, a cloud-based platform offering a modern, collaborative environment, with data contained in Microsoft Energy Data Services.
Learn more
For detailed information on Cegal Solutions for Microsoft Energy Data Services please visit Cetegra's website.
Get started with Microsoft Energy Data Services today.
Quelle: Azure






