Cloud Logging pricing for Cloud Admins: How to approach it & save cost

Flexera’sState of the Cloud Report 2022 pointed out that significant cloud spending is wasted, a major issue that is getting more critical as cloud costs continue to rise. In the current macroeconomic conditions, companies focus on identifying ways to reduce spending. To  effectively do that, we need to understand the pricing model. We can then work towards the challenges of cost monitoring, optimization, and forecasting. One area that often gets overlooked in budgeting is observability—logging, monitoring, tracing. This can represent a significant cost, especially if it’s not optimized. Let’s explore how to understand and optimize our most voluminous data source—logs—within Google Cloud.Cloud Logging is a fully managed real-time log solution that allows you to ingest, route, store, search and analyze your logs to easily troubleshoot incidents using your log data. It can collect data from on-prem, Google Cloud and other clouds with open source agents that support over 150+ services. Unlike traditional licensing models or self hosted logging solutions, Cloud Logging pricing model is simple and based on actual usage. Let’s explore the various components of Cloud Logging and address a few commonly asked questions about pricing. Cloud Logging – Components & PurposeTo understand pricing better and be able to predict future costs, we need to understand the high-level components of Cloud Logging and where billing occurs in our system. There are three important components within Cloud Logging: Cloud Logging API, Cloud Logging Router (Log Router) and log buckets (Log Storage).The below table outlines the high-level components, purpose and pricing information for Cloud Logging. As indicated above, today billing in Cloud Logging occurs only for a log that is routed and ingested into a log bucket. “Ingestion” in Cloud Logging is the process of saving log data into a log bucket, not simply processing it in the Log Router. There are three options for log buckets – RequiredDefault User-defined or Custom. Only Default and User-defined buckets are billed.Today, ourlogging pricing is based on the volume of logs ingested in a chargeable log bucket—default or user-defined. All charges in Cloud Logging occur at the log bucket and all log types incur the same cost.  Logs dropped using sink filters or exclusion filters are not charged by Cloud Logging, even if these logs are routed to a destination outside of Cloud Logging. Now, we’ll address frequently asked questions about the Cloud Logging pricing model.  What Cloud Logging charges will I see on my bill?There are two types of charges your logs can potentially incur: An ingestion charge of 0.50 cents/GB which includes default storage of 30 days. Note that the first 50 GB in a project fall under the free tier quota. You get charged based on the volume of logs ingested into the Default and User-defined log buckets.Logs stored beyond 30 days will incur a retention charge of $0.01/GiB/month for non-required buckets. Note that this pricing is not currently enforced. We will begin charging in early 2023.For the latest pricing, check here.How can I reduce my bill?Because Cloud Logging pricing is based on actual usage, you can reduce your pricing by adjusting the ingestion volume or retention period.Reduce the volume of logs ingested per log bucket by identifying and keeping (ingesting) only valuable log data for analysis. If you do not need to keep data beyond the included 30 days, reduce the retention period. Because the first 30 days of retention are included with ingestion, reducing retention to less than 30 days will have no impact on your bill.Does Cloud Logging charge based on the number of queries, searches either from Cloud Logging UI or Client SDK/APIs?No, Cloud Logging does not charge for the number of queries, searches, logs read from disks during queries, or varied log types.  There is a quota limit for querying logs, though, so for integrations with SIEMs or other logging tools, it’s a best practice to set up a log sink via Pub/Sub to push the logs to the downstream system.Can I incur multiple ingestion charges?It is possible to be charged for ingesting the same log entry into Cloud Logging log buckets multiple times.  For example, if your sinks route a log entry to two log buckets, you will pay ingestion costs at two buckets. You may choose to do this to have independent retention of logs or to keep copies of logs in multiple regions for compliance reasons. Are there different costs for hot and cold storage?No, there are no differences between hot and cold storage. The beauty of Cloud Logging is that all logs are accessible throughout their lifespan. Cloud Logging is designed to scale easily and efficiently, which makes logs accessible for troubleshooting, investigating and compliance reasons whether they are seconds or years old. How much does it cost to route logs to other destinations?Today, Cloud Logging does not charge for centrally collecting and routing logs to other destinations like Cloud Storage, BigQuery, Pub/Sub. Usage rates for the destination services, Cloud Storage, BigQuery and Pub/Sub apply.Do Logs have a generation fee?For network telemetry logs such as VPC Logs, Firewall rules logs and Cloud NAT logs, you might incur an additional network generation charge if logs are not stored in Cloud Logging. If you store your logs in Cloud Logging, networking logs generation charges are waived, and only Cloud Logging charges apply. How do I understand my ingestion volume in Cloud Billing?To determine the cost per Project:Go to Cloud Console -> Billing -> Select the Billing Account -> Reports (left pane) On the right side, under filters -> Services -> select “Cloud Logging”Now, Let’s drill down to learn about the cost incurred by each log bucket. Select the Project on the top bar. On the Left pane, go to Logging -> Logs Storage. Now you should be able to see the log volume per bucket.Putting it all togetherNow that we understand pricing for Cloud Logging, we can optimize our usage. Here are four best practices:Recommendation #1: Use a log router to centralize your collection; get a 360 view of your log world and then use an exclusion filter to reduce noisy logs and send only valuable logs to the log bucket. Logs dropped using sink filters or exclusion filters are not charged by Cloud Logging, even if these logs are routed to a destination outside of Cloud Logging. Recommendation #2: Admin activity audit logs are captured by default for all GCP services for no additional cost. Leverage the audit logs from Required Bucket by identifying use-cases for your organizations and configure log-based-alerts on them. Recommendation #3: Logs can be stored cost effectively for up to 10 years and easily accessed via Cloud Logging. Cloud Logging will begin charging customers for long term log retention starting Jan 2023. Between now and Jan 2023, determine the required lifespan of a log and set the appropriate retention period for each log bucket.Recommendation #4: If you are a new customer, estimate your bills. This is a great way to compare costs with your current Cloud Logging solution. If you are an existing customer, create a budgetand set up alerts on your Cloud Logging bills. In addition to analyzing log volumes by buckets, customers may want to analyze the sources, projects, etc. Metrics explorer in Cloud Monitoring can also be used to identify costs. We will discuss this in the next blog.  For more information, join us in ourdiscussion forum. As always, we welcome your feedback. Interested in using Cloud Logging to save costs in your organization, contact us here. We are hosting a webinar to talk about how you can leverage Log Analytics, powered by BigQuery in Cloud Logging for no additional cost. Register here.
Quelle: Google Cloud Platform

From the NFL to Google’s Data Centers: Why KP Philpot still values teamwork over everything

Editor’s note: KP Philpot is the Environmental Health & Safety Manager at Alphabet’s data center campus in Douglas County, Georgia. It’s a long way from both a childhood in Chicago’s South Side, and standing in football stadiums with thousands of fans, but one thing has always held true for him: The importance of personal and team performance. How did you come to Google?At surface level, it was pretty direct. I was working as a site safety engineer for a contractor that was building a Google data center, and I was offered a job at Google. On a deeper level, it was a long and unexpected journey. I grew up in inner city Chicago, and we didn’t hear a lot about data center technicians and environmental engineering. We had blue collar jobs you stuck to, or you played sports. I played football and basketball, and was recruited by colleges for both. I set three NCAA records playing linebacker at Eastern Michigan University, and then I was with the Detroit Lions and played some Arena Football. A few years after that someone I played with in college brought me into the construction industry, and that’s what I did at three other companies before arriving at Google. How different is Google from other places?One thing that’s a breath of fresh air is that when you come to Google, it’s okay to not have all the answers. I think you work more freely and more confidently when there’s no expectation to know everything from day one. If someone you ask doesn’t know the answer, they’re interested in finding it out. There’s a healthy curiosity that you don’t find in most places. One other difference is that Google tends to be team oriented. That part comes naturally to me,  even if it is tech.  I’ve played on teams since I was a kid, and both my parents were athletes. On a team, everyone has a part to play. You have different people, with different skill sets, but everyone belongs. Their contributions are different, but the goal is the same.What is a typical day like?Many people see data centers as rooms full of servers and switches, but I assure you no two days are alike. There are many things to think about in terms of safety, since a data center has a lot of moving parts, especially when working with electricity, we have rigorous protocols to ensure safety for everyone on the site. We also take our environmental impact seriously. A big part of our environmental work is the innovative cooling system we have here in Douglas County — we recycle local sewer water that would otherwise be put in the Chattahoochee River. As for leftover water that does not evaporate, we treat it before returning it to the river. More than that, though, it’s the diversity of people you find in a data center. There may be construction people, who tend to have a lot of hands-on experience and are task focused; there are engineers and managers, who are more focused on how to optimize a process;and of course, there are Googlers. We all become interesting to each other. I get to coordinate and work alongside all of them, which I enjoy a lot.So is team building part of the job?Teamwork is the lens through which I see the world. I was raised by very principled people, who taught me how much your individual actions impact everyone. A family is a team as well. My grandfather would point at his first name, and say, “That’s my name,” then point at my last name, and say, “that’s our name. Every time you walk out the door, that’s who you are.” When I work, I see the world the same way, the need to be a principled person who’s part of a larger team, and constantly working to build respect and trust. Being in the NFL was more expected than being at Google, but these things don’t change.Related ArticleSales specialist, mentor, and woman in Web3: Anella Bokhari is building community and helping others tell their story along the waySales Specialist, Mentor, and Woman in Web3: Anella Bokhari Wears Many Hats But Has the Same “Why” – Helping Others Find & Tell Their Sto…Read Article
Quelle: Google Cloud Platform

Visualize and monitor Azure & hybrid networks with Azure Network Watcher

There is a critical need for increased visibility and control over the operational state of complex networks running sophisticated workloads. Multi-cloud and hybrid network environments power new demands of remote work, 5G/Edge connectivity, microservices based workloads, and increased cloud adoption. The advent of the cloud has added agility, cost benefits, and brought along the need for management of the infrastructure. Management and monitoring of the network underlying these complex applications plays a key role in ensuring end-user satisfaction.

Azure Network Watcher provides an entire suite of tools to visualize, monitor, diagnose, and troubleshoot network issues across Azure and Hybrid cloud environments. Network Watcher enables customers to detect anomalies across Azure and hybrid networks with comprehensive wide coverage, through a guided and intuitive drilled-down experience. Network Watcher helps customers monitor, manage, and understand their own networks for performance, connectivity, security, and compliance issues and furthermore, empowers customers to troubleshoot efficiently with actionable insights and proactive alerting, thus effectively reducing the mean time to resolve network issues.

The following new feature enhancements across Network Watcher suite aim to provide timely and complete visibility and actionable insights to customers of their hybrid networks in a manner that is easily accessible, readily usable, and reliable.

Visualize resource and network health with Topology

Topology enables users to quickly acquire system context, comprehend state, and troubleshoot issues efficiently by visualizing the resources in a network. It offers a visually connected experience for monitoring and managing inventory.

This new topology experience in Azure, which replaces the Network Watcher topology, will enable customers to create a consistent and dynamic topology across multiple subscriptions, regions, and resource groups (RGs)—comprising of numerous resources.

Allowing deep dives into the customer’s environment, Topology lets users drill down from regions, VNETs to subnets, and resource view diagram of resources supported in Azure.

Stitching the end-to-end monitoring and diagnostics story for all Network Monitoring needs, topology offers the capability to run Next Hop directly from a VM selected in the topology.

Significant features available with this preview: 

Multi-region and multi-subscription–dynamic drill-down visualization.
Health status of resources using resource health (RHC) status.
Diagnostics tool Next Hop integration.
Resource view diagram for all supported resources.

Monitor connectivity using Azure Monitor Agent with Connection Monitor


Integration of Azure Monitor Agent’s support consolidates multi-monitoring agents into a single connectivity monitoring agent in Azure Network Watcher’s Connection Monitor.

Connection Monitor, a multi-agent solution, monitors connectivity at regular intervals across Azure and Hybrid endpoints and provides aggregated data for packet loss, latency, and status codes over TCP, ICMP, and HTTP(s) pings.

Connection Monitor helps you troubleshoot network issues with faster alerts for lack of connectivity or reachability to the endpoints. The unified topology rendered provides a complete end-to-end visualization of the network path from source to destination, with actionable insights.

This agent integration enhancement addresses connectivity monitoring logs and metrics data collection needs across Azure and ARC-enabled on-premises machines, thus eliminating the overhead of management and enablement of multiple monitoring agents. Additionally, Azure Monitor Agent provides enhanced security and performance capabilities, effective cost savings, and ease of troubleshooting with simpler management of data collection. With this support, dependency on the soon-to-be-retired Log Analytics agent is eliminated, while increasing the coverage for on-premises machines with support for ARC-enabled endpoints.

Significant features available with preview:

Connectivity monitoring support for ARC-enabled on-premises endpoints.
Simpler management of monitoring extension.
One agent for monitoring Azure and non-Azure endpoints.
Enhanced security through Managed Identity and Azure Active Directory (Azure AD) tokens.             

Learn More

Please navigate to the Network Insights portal to try out Azure Topology.
Refer here to learn more about Network Insights.
Please navigate to the Connection Monitor portal to try out Connection Monitor with Azure Monitor Agent. 
Refer here to learn more about Connection Monitor.

Quelle: Azure

Enterprise-grade DDoS protection for SMBs now available in preview

This blog has been co-authored by Anupam Vij, Principal PDM Manager.

Distributed denial of service (DDoS) attacks are some of the largest availability and security concerns facing customers that are moving their applications to the cloud. While cyber-attacks are on the rise, they typically make the news only when a large organization has fallen victim to an attack. However, contrary to what many may think, small and medium businesses (SMBs) are just as enticing to cybercriminals.1 While large organizations have the resources needed to protect themselves, small businesses often lack the budget and qualified staff to defend against DDoS attacks.

At Microsoft, we continuously enhance our product offerings to meet the needs of all organizations, including helping SMBs on their digital transformation journey by ensuring that they are protected against the latest DDoS attack vectors. As we shared at Microsoft Ignite, Azure DDoS IP Protection SKU, a new SKU of Azure DDoS Protection built for SMBs, is now available in preview.

Cost-effective, enterprise-grade DDoS protection for small businesses

DDoS IP Protection is designed to meet the needs of SMBs, providing enterprise-grade DDoS protection at an affordable price point. It offers the same essential capabilities as Azure DDoS Network Protection (previously known as Azure DDoS Protection Standard) to protect your resources and applications against evolving DDoS attacks, including L3/L4 automatic attack detection and mitigation, metrics and alerts, mitigation flow logs, mitigation policies tuned to customer applications, and tight integration with Azure Firewall Manager, Microsoft Sentinel, and Microsoft Defender for Cloud.

With the DDoS IP Protection SKU, customers now have the flexibility to enable DDoS protection on individual public IP addresses. SMB customers who have a few public IP addresses to protect will benefit from this cost-effective DDoS protection option.

Key features of Azure DDoS IP Protection

Massive mitigation capacity and scale: Defend your workloads against the largest and most sophisticated attacks with cloud-scale DDoS protection backed by Azure’s global network.
Adaptive tuning: Protect your apps and resources while minimizing false negatives with adaptive tuning tuned to the scale and actual traffic patterns of your application.
Attack analytics, metrics, and logging: Monitor DDoS attacks near real-time and respond quickly to attacks with visibility into the attack lifecycle, vectors, and mitigation.
Integration with Azure Firewall Manager: Centrally manage your DDoS protection across your environment alongside other network security services.
Integration with Microsoft Sentinel and Microsoft Defender for Cloud: Strengthen your security posture with rich attack analytics and telemetry integrated with Microsoft Sentinel and security alerts and recommendations provided by Microsoft Defender for Cloud.

Choosing the right DDoS protection SKU for your needs

Azure DDoS protection now offers two SKUs:

DDoS IP Protection is recommended for SMB customers with a few public IP resources who need a comprehensive DDoS protection solution that is fully managed, and easy to deploy and monitor.
DDoS Network Protection (previously known as Azure DDoS Protection Standard) is recommended for larger enterprises and organizations looking to protect their entire deployment that spans multiple virtual networks and includes many public IP addresses. It also offers value-added features like cost protection, DDoS Rapid Response, and discounts on Azure Web Application Firewall.

Let’s see a detailed comparison of these two SKUs:

Azure DDoS IP Protection pricing

With DDoS IP Protection SKU, you only pay for the public IP resources protected. The monthly cost is fixed for each public IP resource protected with no additional variable costs. Prices may vary by region. Billing for IP Protection will be effective starting on February 1, 2023. For more details on pricing, visit the Azure DDoS Protection pricing page.

Get Started

DDoS IP Protection is currently available in preview in select regions and can only be enabled on Public IP Standard SKU. DDoS IP Protection is currently only available in the Azure Preview Portal and will be made available on the Azure Portal soon.

For more information on DDoS IP Protection, see the following:

Azure DDoS IP Protection documentation.
DDoS Protection pricing page.

1Diving back into SMB breaches, Data Breach Investigation Report, 2021, Verizon.com.
Quelle: Azure

Docker and Wasm Working Together? Find Out How at Wasm Day NA

You may have seen some hype around WebAssembly, or Wasm, as it’s often called. It’s a relatively new technology that allows you to compile application code written in languages like Rust, C, C++, Javascript, and Golang to byte code, then run it inside a sandboxed environment.

So why all the hype? Well, those sandboxed environments can run in a large variety of locations — including your web browser using a Javascript virtual machine. Not only does this mean the sandbox benefits from billions of dollars of investment in security, speed, and cross compatibility, it also means you can run existing code in your browser with some minor changes. And before you ask, yes, it can run Doom.

But running Doom in the browser is just one use case. Companies like WasmEdge are using Tensorflow to push the boundaries of what can be run with Wasm. Fermyon is building tools for Wasm to be used in microservices, while Vercel, Fastly, Shopify, and Cloudflare use Wasm for running code at the edge. Figma is using Wasm to provide higher performance in the browser for their application, and their new parent company Adobe is bringing their desktop applications to the Web using Wasm.

If all those examples don’t excite you about what’s possible with Wasm, I’m not sure what will!

How do Docker and Wasm fit together?

So what is Docker doing with Wasm? We see Wasm and containers as complementary technologies. The problem you’re solving will make one or the other more applicable, but they’re compatible, and should work well together in your cloud native application.

It really comes down to the use case. For example, Wasm’s quick startup time is great for short lived operations, and its isolation is a good match when you need strict security guarantees enforceable at the code level. But as of now, it doesn’t have multithreading or garbage collection capabilities, so any use case with those requirements isn’t a good fit. It also requires that you rebuild your software from source to work.

Join Docker at Cloud Native Wasm Day

We’ll be at the Cloud Native Wasm Day NA in Detroit on October 24, as a Diamond sponsor, to talk about how we’re providing developers the tooling they need using development experiences they already know and love.

Justin Cormack, our CTO, will be presenting during the keynote. In his presentation, he’ll talk about how the container, Docker, and cloud native communities are embracing Wasm — and give some insights as to where we can go from here. If you’ve never seen him speak, I highly recommend it!

Michael Yuan (WasmEdge) and I will also be giving a talk to show how WASI and container workloads work together in Docker Desktop. You’ll find out when to use Wasm, the current tooling options for Wasm, and how to use Docker and Wasm together. We’ll even share download links to the Docker + Wasm preview so you can give it a try yourself!

If you’re attending the Cloud Native Wasm Day don’t miss our keynote and talk!
Quelle: https://blog.docker.com/feed/

How to Fix and Debug Docker Containers Like a Superhero

While containers help developers rapidly build and run cross-platform applications, creating error-free apps remains a constant challenge. And while it’s not always obvious how container errors occur, this mystery is even harder for newer developers to unravel. Figuring out how to debug Docker containers can seem daunting.

In this Community All-Hands session, Ákos Takács demonstrated how to solve many of these pesky problems and gain the superpower of fixing containers.

Each issue can impact your image builds and final applications. Some bugs may not trigger clear error messages. To further complicate things, source-code inspection isn’t always helpful. 

But, common container issues don’t have to be your kryptonite! We’ll share Ákos’ favorite tips and show you how to conquer these development challenges.

In this tutorial:

Finding and fixing common container mistakesUsing the CLI for extra container visibilityChange your CLI output formatting for visibility and readabilityRemember to leverage your logsTackle issues with ENTRYPOINTAccess and inspect container contentDive deeply into files and foldersSolve Docker Build errorsSolve Docker Compose errorsOptional: Make direct file edits within running containersInvestigate less and develop more

Finding and fixing common container mistakes

Everyone is prone to the occasional silly mistake. You code when you’re tired, suffer from the occasional keyboard slip, or sometimes fail to copy text correctly between steps. These missteps can carry forward from one command to the next. And because easy-to-miss things like spelling errors or character omissions can fly under the radar, you’re left doing plenty of digging to solve basic problems. Nobody wants that, so what tools are at your disposal? 

Using the CLI for extra container visibility

Say we have an image downloaded from Docker Hub — any image at all — and use some variation of the docker run command to run it. The resulting container will be running the default command. If you want to surface that command, entering docker container ls –all will grab a list of containers with their respective commands. 

Users often copy these commands and reuse them within other longer CLI commands. As you’d expect, it’s incredibly easy to highlight incorrectly, copy an incomplete phrase, and run a faulty command that uses it.

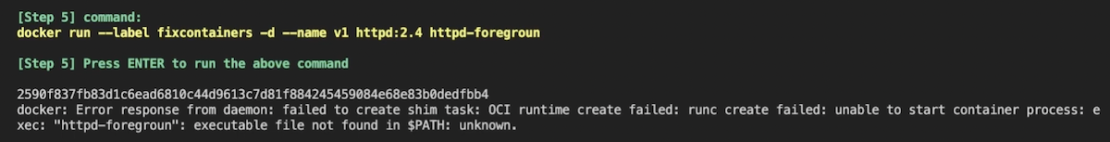
While spinning up a new container, you’ll hit a snag. The runtime in this instance will fail since Docker cannot find the executable. It’s not located in the PATH, which indicates a problem:

Running the docker container ls –all command also offers some hints. Note the httpd-foregroun container command paired with its created (but not running) container. Conversely, the v0 container that’s running successfully leverages a valid, complete command:

How do we investigate further? Use the docker run –rm -it –name MYCONTAINER [IMAGE] bash command to open an interactive terminal within your container. Take the container’s default command and attempt to run it again. A “command not found” error message will appear.

This is much more succinct and shows that you’ve likely entered the wrong command — in this case by forgetting a character. While Ákos’ example uses httpd, it’s applicable to almost any container image. 

Change your CLI output formatting for visibility and readability

Container commands are clipped once they exceed a certain length in the terminal output. That prevents you from inspecting the command in its entirety. 

Luckily, Ákos showed how the –format ‘{{ json . }}’ | jq -C flag can improve how your terminal displays outputs. Instead of cutting off portions of text, here’s how your docker container ls –all result will look:

You can read and compare any parameters in full. Nothing is hidden. If you don’t have jq installed, you could instead enter the following command to display outputs similarly minus syntax highlighting. This beats the default tabular layout for troubleshooting:

docker container ls –all –format ‘{{ json . }}’ | python3 -m json.tool –json-lines

Lastly, why not just expand the original table view while only displaying relevant information? Run the following command with the –no-trunc flag to expand those table rows and completely reveal each cell’s contents:

docker container ls –all –format ‘table {{ .Names }}/t{{ .Status }}/t{{ .Command }}’ –no-trunc

These examples highlight the importance of visibility and transparency in troubleshooting. When you can uncover and easily digest the information you need, making corrections is much easier.      

Remember to leverage your logs

By following best practices, any active application running within a Docker container will produce log outputs. While you might view logging as a problem-catching mechanism, many running containers don’t experience issues.

Ákos believes it’s important to understand how normal log entries look. As a result, identifying abnormal log entries becomes that much easier. The docker logs command enables this:

The process of tuning your logs differs between tools and languages. For example, Ákos drew from methods involving httpd — like trace for detailed trace-level messages or LogLevel for filtering error messages — but these practices are widely applicable. You’ll probably want to zero in on startup and runtime errors to diagnose most issues. 

Log handling is configurable. Here are some common commands to help you drill down into container issues (and reduce noise):

Grab your container’s last 100 logs:

docker logs –tail 100 [container ID]

Grab all logs for a specific container:

docker logs [container ID]

View all active processes within a running container, should its logs be inaccessible:

docker top [container ID]

Log inspection enables easier remediation. Alongside Ákos, we agree that you should confirm any container changes or fixes after making them. This means you’ve taken the right steps and can move ahead.

Want to view all your logs together within Docker Desktop? Download our Logs Explorer extension, which lets you browse through your logs using filters and advanced search capabilities. You can even view new logs as they populate.

Tackle issues with ENTRYPOINT

When running applications, you’ll need to run executable files within your container. The ENTRYPOINT portion of your Dockerfile sets the main command within a container and basically assigns it a task. These ENTRYPOINT instructions rely on executable files being in the container. 

In Ákos’ example, he tackles a scenario where improper permissions can prevent Docker from successfully mounting and running an entrypoint.sh executable. You can copy his approach by doing the following: 

Use the ls -l $PWD/examples/v6/entrypoint.sh command to view your file’s permissions, which may be inadequate.Confirm that permissions are incorrect. Run a chmod 774 command to let this file read, write, and execute for all users.Use docker run to spin up a container v7 from the original entrypoint, which may work briefly but soon stop running. Inspect the entrypoint.sh file to confirm our desired command exists. 

We can confirm this again by entering docker container inspect v7-exiting to view our container definition and parameters. While the Entrypoint is specified, its Cmd definition is null. That’s what’s causing the issue:

Why does this happen? Many don’t know that by setting –entrypoint, any image with a default command will empty that command automatically. You’ll need to redefine your command for your container to work properly. Here’s how that CLI command might look:

docker run -d -v $PWD/examples/v7/entrypoint.sh:/entrypoint.sh –entrypoint /entrypoint.sh –name v7-running httpd:2.4 httpd-foreground

This works for any container image but we’re just drawing from an earlier example. If you run this and list your containers again, v7 will be active. Confirm within your logs that everything looks good. 

Access and inspect container content

Carefully managing files and system resources is critical during local development. That’s doubly true while working with multiple images, containers, or resource constraints. There are scenarios where your containers bloat as their contents accumulate over time. 

Keeping your files tidy is one thing. However, you may also want to copy your files from your container and move them into a temporary folder — using the docker cp command with a specified directory. Using a variation of ls -la ./var/v8, borrowing from Ákos’ example, then produces a list containing every file. 

This is great for visibility and confirming your container’s contents. And we can diagnose any issues one step further with docker container diff v8 to view which files have been changed, appended, or even deleted. If you’re experiencing strange container behavior, digging into these files might be useful. 

Dive deeply into files and folders

Close inspection is where hexdump comes in handy. The hexdump function converts your file into hexadecimal code, which is much more readable than binary. Ákos used the following commands:

docker cp v8:/usr/local/apache2/bin/httpd ./var/v8-httpd`
`hexdump -C -n 100 ./var/v8-httpd

You can adjust this -n number to read additional or fewer initial bytes. If your file contains text, this content will stand out and reveal the file’s main purpose. But, say you want to access a folder. While changing your directory and running docker container inspect … is standard, this method doesn’t work for Docker Desktop users. Since Desktop runs things in a VM, the host cannot access the folders within. 

Ákos showcased CTO Justin Cormack’s own nsenter1 image on GitHub, which lets us tap into those containers running with Docker Desktop environments. Docker Captain Bret Fisher has since expanded upon nsenter1’s documentation while adding useful commands. With these pieces in place, run the following command:

docker run –rm –privileged –pid=host alpine:3.16.2 nsenter -t 1 -m -u -i -n -p — sh -c “ cd ”$(docker container inspect v8 –format ‘{{ .GraphDriver.Data.UpperDir }}’}” && find .”

This command’s output mirrors that from our earlier docker container diff command. You can also run a hexdump using that same image above, which gives you the same troubleshooting abilities regardless of your environment. You can also inspect your entrypoint.sh to make important changes.  

Solve Docker Build errors 

While Docker BuildKit is quick and resilient, you can encounter errors that prevent image build completion. To learn why, run the following command to view each sequential build stage:

docker build $PWD/[MY SOURCE] –tag “MY TAG” –progress plain

BuildKit will provide readable context for each step and display any errors that occur:

If you see a missing file or directory error like the one above, don’t worry! You can use the cat $PWD/[MY SOURCE]/[MY DOCKERFILE] command to view the contents of your Dockerfile. Not only can you see where you misstepped more clearly, but you can also add a new instruction before the failing command to list your folder’s contents. 

Maybe those contents need updating. Maybe your folder is empty! In that case, you need to update everything so docker build has something to leverage. 

Next, run the build command again with the –no-cache flag added. This flag tells Docker to cleanly build from scratch each time without relying on caching:

You can progressively build updated versions of your Dockerfile and test those changes, given the cascading nature of instructions. Writing new instructions after the last working instruction — or making changes earlier on in your file — can eliminate those pesky build issues. Mechanisms like unlink or cp are helpful. The first behaves like rm while accepting only one argument, while cp copies critical files and folders into your image from a source.  

Solve Docker Compose errors

We use Docker Compose to spin up multiple services simultaneously using the docker compose –project-directory $PWD/[MY SOURCE] up -d command. 

However, one or more of those containers might unexpectedly exit. By running docker compose –project-directory $PWD/[MY SOURCE] ps to list out our services, you can see which containers are running or exited.

To pinpoint the problem, you’d usually grab logs via the docker compose logs command. You won’t need to specify a project directory in most cases. However, your container produces no logs since it isn’t running. 

Next, run the cat $PWD/[MY SOURCE]/docker-compose.yml command to view your Docker Compose file’s contents. It’s likely that your services definitions need fixing, so digging line by line within the CLI is helpful. Enter the following command to make this output even clearer:

docker compose –project-directory $PWD/[MY SOURCE] config

Your container exits when the commands contained within are invalid — just like we saw earlier. You’ll be able to see if you’ve entered a command incorrectly or if that command is empty. From there, you can update your Compose file and re-run docker compose –project-directory $PWD/[MY SOURCE] up -d. You can now confirm that everything is working by listing your services again. Your terminal will also output logs! 

Optional: Make direct file edits within running containers

Finally, it’s possible (and tempting) to directly edit your files within your container. This is viable while testing new changes and inspecting your containers. However, it’s usually considered best practice to create a new image and container instead. 

If you want to make edits within running containers, an editor like VS Code allows this, while IntelliJ doesn’t by comparison. Install the Docker extension for VS Code. You can then browse through your containers in the left sidebar, expand your collection of resources, and directly access important files. For example, web developers can directly edit their index.html files to change how user content is structured. 

Investigate less and develop more

Overall, the process of fixing a container, on the surface, may seem daunting to newer Docker users. The methods we’ve highlighted above can dramatically reduce that troubleshooting complexity — saving you time and effort. You can spend less time investigating issues and more time creating the applications users love. And we think those skills are pretty heroic. 

For more information, you can view Ákos Takács’ full presentation on YouTube to carefully follow each step. Want to dive deeper? Check out these additional resources to become a Docker expert: 

Learn how to view logs for a container or serviceView our Docker Run reference documentationLearn about best practices for writing Dockerfiles
Quelle: https://blog.docker.com/feed/

Amazon EC2 bietet jetzt eine automatische Lösung für den Verbindungsaufbau zwischen EC2-Instance und RDS-Datenbank

Ab heute haben Sie in Amazon Elastic Compute Cloud (Amazon EC2) die Möglichkeit, automatisch die Konnektivität zwischen EC2-Instances und einer Amazon Relational Database Services (Amazon RDS)- oder Amazon Aurora-Datenbank einzurichten. Sobald Sie EC2-Instances bereitgestellt haben, können Sie eine RDS-DB-Instanz oder einen Cluster auswählen und mit einem einzigen Klick die Verbindungskonfiguration vornehmen, um den Datenverkehr von der EC2-Instance zur RDS-Datenbank zu ermöglichen. Amazon EC2 befolgt die Best Practices für Konnektivität und richtet automatisch Sicherheitsgruppen in Ihrem Namen ein, um eine sichere Verbindung herzustellen.
Quelle: aws.amazon.com

AWS Activate steht jetzt allen Startups offen

AWS Activate bietet Start-ups, sowohl kleineren Unternehmen in der Frühphase als auch fortgeschritteneren digitalen Unternehmen, kostenlose Tools und Ressourcen für einen schnellen Einstieg in AWS. Wir freuen uns, heute die Verfügbarkeit des neuen AWS Activate für alle selbsterklärten Startups bekannt zu geben. Activate ist voll von personalisierten Tools und Ressourcen, die Start-ups in jeder Phase ihres Weges unterstützen sollen, von der ersten Idee über den Aufbau eines MVP, die Sicherung des ersten Kunden bis hin zur Skalierung ihres Unternehmens auf AWS und darüber hinaus. Jedes Startup kann AWS Activate beitreten und erhält damit Zugang zu:
Quelle: aws.amazon.com