Tooling ≠ Glue: Why changing AI workflows still feels like duct tape

There’s a weird contradiction in modern AI development. We have better tools than ever. We’re building smarter systems with cleaner abstractions. And yet, every time you try to swap out a component in your stack, things fall apart. Again.

This isn’t just an inconvenience. It’s become the norm.

You’d think with all the frameworks and libraries out there (LangChain, Hugging Face, MLflow, Airflow) we’d be past this by now. These tools were supposed to make our workflows modular and composable. Swap an embedding model? No problem. Try a new vector store? Easy. Switch from OpenAI to an open-source LLM? Go ahead. That was the dream.

But here’s the reality: we’ve traded monoliths for a brittle patchwork of microtools, each with its own assumptions, quirks, and “standard interfaces.” And every time you replace one piece, you end up chasing down broken configs, mismatched input/output formats, and buried side effects in some YAML file you forgot existed.

Tooling was supposed to be the glue. But most days, it still feels like duct tape.

The composability myth

A lot of the tooling that’s emerged in AI came with solid intentions. Follow the UNIX philosophy. Build small pieces that do one thing well. Expose clear interfaces. Make everything swappable.

In theory, this should’ve made experimentation faster and integration smoother. But in practice, most tools were built in isolation. Everyone had their own take on what an embedding is, how prompts should be formatted, what retry logic should look like, or how to chunk a document.

So instead of composability, we got fragmentation. Instead of plug-and-play, we got “glue-and-hope-it-doesn’t-break.”

And this fragmentation isn’t just annoying; it slows everything down. Want to try a new RAG strategy? You might need to re-index your data, adjust your chunk sizes, tweak your scoring functions, and retrain your vector DB schema. None of that should be necessary. But it is.

The stack is shallow and wide

AI pipelines today span a bunch of layers:

Data ingestion

Feature extraction or embeddings

Vector storage and retrieval

LLM inference

Orchestration (LangChain, LlamaIndex, etc.)

Agent logic or RAG strategies

API / frontend layers

Each one looks like a clean block on a diagram. But under the hood, they’re often tightly coupled through undocumented assumptions about tokenization quirks, statefulness, retry behavior, latency expectations, etc.

The result? What should be a flexible stack is more like a house of cards. Change one component, and the whole thing can wobble.

Why everything keeps breaking

The short answer: abstractions leak — a lot.

Every abstraction simplifies something. And when that simplification doesn’t match the underlying complexity, weird things start to happen.

Take LLMs, for example. You might start with OpenAI’s API and everything just works. Predictable latency, consistent token limits, clean error handling. Then you switch to a local model. Suddenly:

The input format is different

You have to manage batching and GPU memory

Token limits aren’t well documented

Latency increases dramatically

You’re now in charge of quantization and caching

What was once a simple llm.predict() call becomes a whole new engineering problem. The abstraction has leaked, and you’re writing glue code again.

This isn’t just a one-off annoyance. It’s structural. We’re trying to standardize a landscape where variability is the rule, not the exception.

Where are the standards?

One big reason for the current mess is the lack of solid standards for interoperability.

In other fields, we’ve figured this out:

Containers → OCI, Docker

APIs → OpenAPI

Observability → OpenTelemetry

Data formats → Parquet, JSON Schema, Avro

In AI? We’re not there yet. Most tools define their own contracts. Few agree on what’s universal. And as a result, reuse is hard, swapping is risky, and scaling becomes painful.

But in AI tooling?

There’s still no widely adopted standard for model I/O signatures.

Prompt formats, context windows, and tokenizer behavior vary across providers.

We do see promising efforts like MCP (Model Context Protocol) emerging, and that’s a good sign, but in practice, most RAG pipelines, agent tools, and vector store integrations still lack consistent, enforced contracts.

Error handling? It’s mostly improvised: retries, timeouts, fallbacks, and silent failures become your responsibility.

So yes, standards like MCP are starting to show up, and they matter. But today, most teams are still stitching things together manually. Until these protocols become part of the common tooling stack, supported by vendors and respected across libraries, the glue will keep leaking.

Local glue ≠ global composability

It’s tempting to say: “But it worked in the notebook.”

Yes, and that’s the problem.

The glue logic that works for your demo, local prototype, or proof-of-concept often breaks down in production. Why?

Notebooks aren’t production environments—they don’t have retries, monitoring, observability, or proper error surfaces.

Chaining tools with Python functions is different from composing them with real-time latency constraints, concurrency, and scale in mind.

Tools like LangChain often make it easy to compose components, until you hit race conditions, cascading failures, or subtle bugs in state management.

Much of today’s tooling is optimized for developer ergonomics during experimentation, not for durability in production. The result: we demo pipelines that look clean and modular, but behind the scenes are fragile webs of assumptions and implicit coupling.

Scaling this glue logic, making it testable, observable, and robust, requires more than clever wrappers. It requires system design, standards, and real engineering discipline.

The core problem: Illusion of modularity

What makes this even more dangerous is the illusion of modularity. On the surface, everything looks composable – API blocks, chain templates, toolkits – but the actual implementations are tightly coupled, poorly versioned, and frequently undocumented.

The AI stack doesn’t break because developers are careless. It breaks because the foundational abstractions are still immature, and the ecosystem hasn’t aligned on how to communicate, fail gracefully, or evolve in sync.

Until we address this, the glue will keep breaking, no matter how shiny the tools become.

Interface contracts, not SDK hype

Many AI tools offer SDKs filled with helper functions and syntactic sugar. But this often hides the actual interfaces and creates tight coupling between your code and a specific tool. Instead, composability means exposing formal interface contracts, like:

OpenAPI for REST APIs

Protocol Buffers for efficient, structured messaging

JSON Schema for validating data structures

These contracts:

Allow clear expectations for inputs/outputs.

Enable automated validation, code generation, and testing.

Make it easier to swap out models/tools without rewriting your code.

Encourage tool-agnostic architecture rather than SDK lock-in.

Build for failure, not just happy paths

Most current AI systems assume everything works smoothly (“happy path”). But in reality:

Models time out

APIs return vague errors

Outputs may be malformed or unsafe

A truly composable system should:

Provide explicit error types (e.g., RateLimitError, ModelTimeout, ValidationFailed)

Expose retry and fallback mechanisms natively (not hand-rolled)

Offer built-in observability—metrics, logs, traces

Make failure handling declarative and modular (e.g., try model B if model A fails)

Shift toward declarative pipelines

Today, most AI workflows are written in procedural code:

response = model.generate(prompt)
if response.score > 0.8:
store(response)

But this logic is hard to:

Reuse across toolsObserve or debug

Cache intermediate results

A declarative pipeline describes the what, not the how:

pipeline:
– step: generate
model: gpt-4
input: ${user_input}
– step: filter
condition: score > 0.8
– step: store
target: vector_database

Benefits of declarative pipelines:

Easier to optimize and cache

Tool-agnostic, works across providers

More maintainable and easier to reason about

Supports dynamic reconfiguration instead of rewrites

Key takeaways for developers

1. Be skeptical of “seamless” tools without contracts

Be skeptical of tools that promise seamless plug-and-play but lack strong interface contracts.

If a tool markets itself as easy to integrate but doesn’t offer:

A clear interface contract (OpenAPI, Protobuf, JSON schema)

Versioned APIs

Validation rules for input/output

Language-agnostic interfaces

Then the “plug-and-play” claim is misleading. These tools often lock you into an SDK and hide the true cost of integration.

2. Design defensively

Design your workflows defensively: isolate components, standardize formats, and expect things to break.

Good system design assumes things will fail.

Isolate responsibilities: e.g., don’t mix prompting, retrieval, and evaluation in one block of code.

Standardize formats: Use common schemas across tools (e.g., JSON-LD, shared metadata, or LangChain-style message objects).

Handle failures: Build with fallbacks, timeouts, retries, and observability from the start.

Tip: Treat every tool like an unreliable network service, even if it’s running locally.

3. Prefer declarative, interoperable pipelines

Embrace declarative and interoperable approaches: less code, more structure.

Declarative tools (e.g., YAML workflows, JSON pipelines) offer:

Clarity: You describe what should happen, not how.

Modularity: You can replace steps without rewriting everything.

Tool-neutrality: Works across providers or frameworks.

This is the difference between wiring by hand and using a circuit board. Declarative systems give you predictable interfaces and reusable components.

 Examples:

LangGraph

Flowise

PromptLayer + OpenAPI specs

Tools that use JSON as input/output with clear schemas

Conclusion

We’ve all seen what’s possible: modular pipelines, reusable components, and AI systems that don’t break every time you swap a model or change a backend. But let’s be honest, we’re not there yet. And we won’t get there just by waiting for someone else to fix it. If we want a future where AI workflows are truly composable, it’s on us, the people building and maintaining these systems, to push things forward.

That doesn’t mean reinventing everything. It means starting with what we already control: write clearer contracts, document your internal pipelines like someone else will use them (because someone will), choose tools that embrace interoperability, and speak up when things are too tightly coupled. The tooling landscape doesn’t change overnight, but with every decision we make, every PR we open, and every story we share, we move one step closer to infrastructure that’s built to last, not just duct-taped together.

Quelle: https://blog.docker.com/feed/
Remocal and Minimum Viable Models: Why Right-Sized Models Beat API Overkill

A practical approach to escaping the expensive, slow world of API-dependent AI

The $20K Monthly Reality Check

You built a simple sentiment analyzer for customer reviews. It works great. Except it costs $847/month in API calls and takes 2.3 seconds to classify a single review. Your “smart” document classifier burns through $3,200/month. Your chatbot feature? $15,000/month and counting.

The Shared Pain:

Bloated AI features that drain budgets faster than they create value

High latency that kills user experience (nobody waits 3 seconds for a “smart” response)

Privacy concerns when sensitive data must leave your network

Compliance nightmares when proprietary data goes through third-party APIs

Developer friction from being locked into massive, remote-only models

Remocal + Minimum Viable Models = Sweet Spot

Remocal (remote + local) is a novel hybrid development approach that combines local development environments with on-demand access to cloud resources, allowing developers to work locally while seamlessly tapping into powerful remote compute when needed. This approach solves longstanding problems in traditional development by eliminating the friction of deploying to staging environments for realistic testing, reducing the overhead of managing complex cloud setups, and providing instant access to production-scale resources without leaving the familiar local development workflow. 

It’s particularly effective for AI development because it addresses the fundamental tension between accessible local iteration and the substantial computational requirements of large modern AI models. With Remocal, developers can build and test their agents locally, using local models. They can also burst out to cloud GPUs when the AI use case or workload exceeds local viability. We believe this will democratize AI development by making it easier and cheaper to build AI applications with minimal resources. For businesses, a Remocal approach to AI development presents a much more affordable path to build machine learning applications and a much better developer experience that allows faster iteration and causes less frustration.

Remocal teaches us to develop locally and then add horsepower with cloud acceleration only when needed. A logical and increasingly essential extension of this principle is Minimum Viable Model (MVM).

In a nutshell, Minimum Viable Models (MVMs) means deploying the smallest, most efficient models that solve your core business problem effectively. It is also good guidance for deploying models in the cloud, as well. Just as you never spin up a massive Kubernetes cluster well before you need it or fire up an enormous PostgreSQL instance in the cloud simply to test out an application. Combine MVM with Remocal software development and you get the best of both worlds. 

Why Right-Sized Models Are Having Their Moment

In fact, if you can’t build a POC with a local model, you should think hard about what you are building because local models today can handle just about anything the vast majority of AI applications require during development stages. AI researchers have come up with a number of clever ways to shrink models without losing capability including:

Curated-data SLMs (small language models): Microsoft’s latest Phi-4 family shows that carefully filtered, high-quality training corpora let sub-15B models rival or beat much larger models on language, coding and math benchmarks, slashing memory and latency needs.

Quantization: Packing weights into NF4 4-bit blocks plus low-rank adapter layers preserves accuracy within ~1 pt while cutting GPU RAM by ~75% and allowing laptop-class training or inference.

Sparse Mixture-of-Experts (MoE): Architectures such as Mistral’s Mixtral 8×7B route each token through just two of 8 expert blocks, activating <25% of parameters per step yet matching dense peers, so serving costs scale with active, not total, parameters.

Memory-efficient attention kernels: Libraries like FlashAttention-2 reorder reads/writes so attention fits in on-chip SRAM, doubling throughput and enabling larger context windows on commodity GPUs.

On-device “nano” models: Google’s Gemini Nano ships directly inside Chrome and Android, proving that sub-4B models can run private, low-latency inference on phones and browsers without cloud calls.

MVM-Friendly Production-Ready Models

MVM-Ready Models

Model

Size (B params)

What it’s good at

Typical hardware footprint*

Why it punches above its weight

Qwen 3

32B

Dual-mode reasoning (thinking/non-thinking), multilingual (119 languages), long context (32K-128K), tool calling

RTX 4090 or H100; ~64GB VRAM full precision, ~16GB with 4-bit quantization

Hybrid thinking modes allow switching between fast responses and deep reasoning; competitive with much larger models on coding and math

Gemma 3

27B

Multimodal (text + images), 140+ languages, function calling, 128K context

Single H100 or RTX 3090 (24GB); ~54GB full precision, ~7GB with int4 quantization

Achieves 98% of DeepSeek-R1’s performance using only 1 GPU vs 32; optimized quantization maintains quality at 4x compression

Mistral Small 3.2

24B

Fast inference (150 tokens/s), multimodal, function calling, instruction following 

RTX 4090 or A100; ~55GB VRAM bf16/fp16, ~14GB with quantization

3x faster than Llama 3.3 70B; improved stability and reduced repetitive outputs; optimized for low-latency applications

Llama 3.1 70B

~70 B

Text + emerging multimodal, long context (128 K tokens)

Larger desktops in 4-bit quantization mode (~45GB VRAM)

trained on 15T high-quality tokens, competitive on benchmarks,  integrates well into RAG/ agent pipelines, versatile

SmolLM3

3B

Dual-mode reasoning, multilingual (6 languages), long context (128K), tool calling

RTX 3060 or modest hardware; ~6GB VRAM, runs on laptops and edge devices

Competes with 4B+ models despite 3B size; efficient architecture with grouped-query attention and optimized training curriculum

Phi-4 (Microsoft)

14B

Complex reasoning, math, coding, general chat

4-bit ≈ 10-15 GB VRAM; runs on RTX 4090 or H100

Trained on 9.8T tokens with synthetic data and rigorous filtering; outperforms Llama 3.3 70B on math/reasoning tasks while being 5x smaller

Hardware footprint notes: Requirements vary significantly with quantization level and context length. Full precision numbers assume bf16/fp16. Quantized models (4-bit/8-bit) can reduce memory requirements by 2-4x with minimal quality loss. Edge deployment possible for smaller models with appropriate optimization.

If anything, efforts to shrink models while maintaining efficacy are only getting started, so the future means Remocal + MVM will be even more viable and cover a wider swathe of currently inapplicable use cases. Right now, too, there are a number of highly capable models that can run locally without any problem. Some developers are even looking to build apps and libraries that take advantage of browser-based AI capabilities. Over time, this means better models that can run on the same hardware as their predecessors.

Even today, these new, small models with superpowers represent the full spectrum of capabilities and tool use – NLP, machine vision, general language models, and more. We expect that diversity to grow as fine-tuned versions of small models continue to emerge on HuggingFace (and are pre-packaged on Docker Model Runner).

All of this being said, there are plenty of use cases where local development on an MVM is only the first step and access to bigger models and more powerful GPUs or AI training or inference clusters are essential. Remocal + MVM delivers the best of both worlds: fast, cost-effective local inference for everyday tasks combined with frictionless access to powerful cloud models when you hit complexity limits. This hybrid approach means you can prototype and iterate rapidly on local hardware, then seamlessly scale to frontier models for demanding workloads—all within the same development environment. You’re not locked into either local-only constraints or cloud-only costs; instead, you get intelligent resource allocation that automatically uses the right model size for each task, optimizing both performance and economics across your entire AI pipeline.

Rubrics for Local Models vs API Giants

All of this being said, Remocal + MVM may not work for certain situations. It’s important to run a full product requirement spec to clarify use cases and verify that MVM is a viable approach for what you are planning to build.

Stick with API Models When:

You need broad world knowledge or current events

Complex, multi-step reasoning across diverse domains is required

You’re building general-purpose conversational AI

You have fewer than 1,000 requests per month

Accuracy improvements of 2-5% justify 100x higher costs

Use Right-Sized Models When:

Your task is well-defined (classification, code completion, document processing)

You need consistent, low-latency responses

Cost per inference matters for your business model

Data privacy or compliance is a concern

You want developer independence from API rate limits

The classic 80/20 Power Law applies in Remocal + MVM. Most production AI applications fall into well-defined categories where right-sized models can achieve near-equivalents of large model performance at a small fraction of the cost, with higher velocity, greater flexibility and better security.

Conclusion: The Dawn of Practical AI

The era of “bigger is always better” in AI is giving way to a more nuanced understanding: the right model for the right job and a “Unix” mindset of “smaller tools for more specific jobs”. With Microsoft’s Phi-4 achieving GPT-4o-mini level performance in a 14B parameter package, and Gemini Nano running sophisticated AI directly in your browser, we’re witnessing the democratization of AI capabilities. That means any developer anywhere with a decent laptop can build sophisticated AI applications.

The Remocal + Minimum Viable Models approach to AI goes beyond cost savings. It also solves issues around control, flexibility, pace of iteration, and developer experience that formerly vexed Platform and MLOps teams. This approach also will allow a thousand AI apps to bloom, and make it far simpler to build to spec and modify on a dime. As a starting point, too, local AI development means better security, better compliance and minimized risk. This is particularly important for the vast majority of developers who are not experienced in AI security and compliance.

Whether you’re building a customer service chatbot, a code completion tool, or a document analyzer, there’s likely a small, efficient model that can handle your use case without the complexity, cost, and privacy concerns of cloud APIs. Then, when the time is right and the application requires it, an organization can burst their AI workload to more powerful GPU clusters in the cloud for training and inference. They can switch to a larger, more powerful model, on demand, as needed. Local vs cloud for AI development is a 100% false choice. Most organizations, in fact, are better off having both, giving their developers the tools to be fast, nimble and autonomous with small local models but the capacity to burst into big cloud GPUs and state-of-the-art model APIs as needed if an application or use case requires it.

The future belongs to organizations that can strategically mix local efficiency with cloud scale, using the minimum viable model that gets the job done. Start local, prove value, then scale strategically.

Quelle: https://blog.docker.com/feed/
Build a Recipe AI Agent with Koog and Docker

Hi, I’m Philippe Charriere, a Principal Solutions Architect at Docker. I like to test new tools and see how they fit into real-world workflows. Recently, I set out to see if JetBrains’ Koog framework could run with Docker Model Runner, and what started as a quick test turned into something a lot more interesting than I expected. In this new blog post, we’ll explore how to create a small Koog agent specializing in ratatouille recipes using popular Docker AI tools (disclaimer: I’m French). We’ll be using:

Koog: a framework for building AI Agents in Kotlin

Docker Model Runner: a Docker feature that allows deploying AI models locally, based on Llama.cpp

Agentic Compose: a Docker Compose feature to easily integrate AI models into your applications

Docker MCP Gateway: a gateway to access MCP (Model Context Protocol) servers from the Docker MCP Catalog 

Prerequisites: Kotlin project initialization

I use IntelliJ IDEA Community Edition to initialize the Kotlin project.

I use OpenJDK 23 and Gradle Kotlin DSL for project configuration.

Step 1: Gradle Configuration

Here’s my build configuration: build.gradle.kts

plugins {
kotlin("jvm") version "2.1.21"
application
}

group = "kitchen.ratatouille"
version = "1.0-SNAPSHOT"

repositories {
mavenCentral()
}

dependencies {
testImplementation(kotlin("test"))
implementation("ai.koog:koog-agents:0.3.0")
implementation("org.slf4j:slf4j-simple:2.0.9")

}

application {
mainClass.set("kitchen.ratatouille.MainKt")
}

tasks.test {
useJUnitPlatform()
}

tasks.jar {
duplicatesStrategy = DuplicatesStrategy.EXCLUDE
manifest {
attributes("Main-Class" to "kitchen.ratatouille.MainKt")
}
from(configurations.runtimeClasspath.get().map { if (it.isDirectory) it else zipTree(it) })
}

kotlin {
jvmToolchain(23)
}

Step 2: Docker Compose Project Configuration

The new “agentic” feature of Docker Compose allows defining the models to be used by Docker Compose services.

With the content below, I define that I will use the hf.co/menlo/lucy-128k-gguf:q4_k_m model from Hugging Face for my “Koog agent”.

models:
app_model:
model: hf.co/menlo/lucy-128k-gguf:q4_k_m

And I make the “link” between the koog-app service and the app_model model and the Koog agent as follows at the service level:

models:
app_model:
endpoint_var: MODEL_RUNNER_BASE_URL
model_var: MODEL_RUNNER_CHAT_MODEL

Docker Compose will automatically inject the MODEL_RUNNER_BASE_URL and MODEL_RUNNER_CHAT_MODEL environment variables into the koog-app service, which allows the Koog agent to connect to the model.

If you entered interactive mode in the koog-app container, you could verify that the environment variables are properly defined with the command:

env | grep '^MODEL_RUNNER'

And you would get something like:

MODEL_RUNNER_BASE_URL=http://model-runner.docker.internal/engines/v1/
MODEL_RUNNER_CHAT_MODEL=hf.co/menlo/lucy-128k-gguf:q4_k_m

It’s entirely possible to define multiple models.

The complete compose.yaml file looks like this:

services:

koog-app:
build:
context: .
dockerfile: Dockerfile
environment:
SYSTEM_PROMPT: You are a helpful cooking assistant.
AGENT_INPUT: How to cook a ratatouille?
models:
app_model:
endpoint_var: MODEL_RUNNER_BASE_URL
model_var: MODEL_RUNNER_CHAT_MODEL

models:
app_model:
model: hf.co/menlo/lucy-128k-gguf:q4_k_m

Step 3: Dockerfile

Next, we’ll need a Dockerfile to build the Docker image of our Koog application. The Dockerfile uses multi-stage build to optimize the final image size, so it’s divided into two parts/stages: one for building the application (build) and one for execution (runtime). Here’s the content of the Dockerfile:

# Stage 1: Build
FROM eclipse-temurin:23-jdk-noble AS build

WORKDIR /app

COPY gradlew .
COPY gradle/ gradle/
COPY build.gradle.kts .
COPY settings.gradle.kts .

RUN chmod +x ./gradlew

COPY src/ src/

# Build
RUN ./gradlew clean build

# Stage 2: Runtime
FROM eclipse-temurin:23-jre-noble AS runtime

WORKDIR /app

COPY –from=build /app/build/libs/ratatouille-1.0-SNAPSHOT.jar app.jar
CMD ["java", "-jar", "app.jar"]

Step 4: Kotlin side:

Connecting to Docker Model Runner

Now, here’s the source code of our application, in the src/main/kotlin/Main.kt file to be able to use Docker Model Runner. The API exposed by Docker Model Runner is compatible with the OpenAI API, so we’ll use Koog’s OpenAI client to interact with our model:

package kitchen.ratatouille

import ai.koog.prompt.executor.clients.openai.OpenAIClientSettings
import ai.koog.prompt.executor.clients.openai.OpenAILLMClient

suspend fun main() {

val apiKey = "nothing"
val customEndpoint = System.getenv("MODEL_RUNNER_BASE_URL").removeSuffix("/")
val model = System.getenv("MODEL_RUNNER_CHAT_MODEL")

val client = OpenAILLMClient(
apiKey=apiKey,
settings = OpenAIClientSettings(customEndpoint)
)
}

First Koog Agent

Creating an agent with Koog is relatively simple as you can see in the code below. We’ll need:

a SingleLLMPromptExecutor that will use the OpenAI client we created previously to execute requests to the model.

an LLModel that will define the model we’re going to use.

an AIAgent that will encapsulate the model and the prompt executor to execute requests.

Regarding the prompt, I use the SYSTEM_PROMPT environment variable to define the agent’s system prompt, and AGENT_INPUT to define the agent’s input (the “user message”). These variables were defined in the compose.yaml file previously:

environment:
SYSTEM_PROMPT: You are a helpful cooking assistant.
AGENT_INPUT: How to cook a ratatouille?

And here’s the complete code of the Koog agent in the src/main/kotlin/Main.kt file:

package kitchen.ratatouille

import ai.koog.agents.core.agent.AIAgent
import ai.koog.prompt.executor.clients.openai.OpenAIClientSettings
import ai.koog.prompt.executor.clients.openai.OpenAILLMClient
import ai.koog.prompt.executor.llms.SingleLLMPromptExecutor
import ai.koog.prompt.llm.LLMCapability
import ai.koog.prompt.llm.LLMProvider
import ai.koog.prompt.llm.LLModel

suspend fun main() {

val apiKey = "nothing"
val customEndpoint = System.getenv("MODEL_RUNNER_BASE_URL").removeSuffix("/")
val model = System.getenv("MODEL_RUNNER_CHAT_MODEL")

val client = OpenAILLMClient(
apiKey=apiKey,
settings = OpenAIClientSettings(customEndpoint)
)

val promptExecutor = SingleLLMPromptExecutor(client)

val llmModel = LLModel(
provider = LLMProvider.OpenAI,
id = model,
capabilities = listOf(LLMCapability.Completion)
)

val agent = AIAgent(
executor = promptExecutor,
systemPrompt = System.getenv("SYSTEM_PROMPT"),
llmModel = llmModel,
temperature = 0.0
)

val recipe = agent.run(System.getenv("AGENT_INPUT"))

println("Recipe:n $recipe")

}

Running the project

All that’s left is to launch the project with the following command:

docker compose up –build –no-log-prefix

Then wait a moment, depending on your machine, the build and completion times will be more or less long. I nevertheless chose Lucy 128k because it can run on small configurations, even without a GPU. This model also has the advantage of being quite good at “function calling” detection despite its small size (however, it doesn’t support parallel tool calls). And you should finally get something like this in the console:

Recipe:
Sure! Here's a step-by-step guide to cooking a classic ratatouille:

—

### **Ingredients**
– 2 boneless chicken thighs or 1-2 lbs rabbit (chicken is common, but rabbit is traditional)
– 1 small onion (diced)
– 2 garlic cloves (minced)
– 1 cup tomatoes (diced)
– 1 zucchini (sliced)
– 1 yellow squash or eggplant (sliced)
– 1 bell pepper (sliced)
– 2 medium potatoes (chopped)
– 1 red onion (minced)
– 2 tbsp olive oil
– 1 tbsp thyme (or rosemary)
– Salt and pepper (to taste)
– Optional: 1/4 cup wine (white or red) to deglaze the pan

—

### **Steps**
1. **Prep the Ingredients**
– Dice the onion, garlic, tomatoes, zucchini, squash, bell pepper, potatoes.
– Sauté the chicken in olive oil until browned (about 10–15 minutes).
– Add the onion and garlic, sauté for 2–3 minutes.

2. **Add Vegetables & Flavor**
– Pour in the tomatoes, zucchini, squash, bell pepper, red onion, and potatoes.
– Add thyme, salt, pepper, and wine (if using). Stir to combine.
– Add about 1 cup water or stock to fill the pot, if needed.

3. **Slow Cook**
– Place the pot in a large pot of simmering water (or use a Dutch oven) and cook on low heat (around 200°F/90°C) for about 30–40 minutes, or until the chicken is tender.
– Alternatively, use a stovetop pot with a lid to cook the meat and vegetables together, simmering until the meat is cooked through.

4. **Finish & Serve**
– Remove the pot from heat and let it rest for 10–15 minutes to allow flavors to meld.
– Stir in fresh herbs (like rosemary or parsley) if desired.
– Serve warm with crusty bread or on the plate as is.

—

### **Tips**
– **Meat Variations**: Use duck or other meats if you don't have chicken.
– **Vegetables**: Feel free to swap out any vegetables (e.g., mushrooms, leeks).
– **Liquid**: If the mixture is too dry, add a splash of water or stock.
– **Serving**: Ratatouille is often eaten with bread, so enjoy it with a side of crusty bread or a simple salad.

Enjoy your meal!

As you can see, it’s quite simple to create an agent with Koog and Docker Model Runner! 

But we have a problem, I told you I was French and the ratatouille recipe proposed by Lucy 128k doesn’t really suit me: there’s no rabbit, chicken, or duck in a ratatouille!!!. But let’s see how to fix that.

Let’s add superpowers to our Koog agent with the Docker MCP Gateway

What I’d like to do now is have my application first search for information about ratatouille ingredients, and then have the Koog agent use this information to improve the recipe. For this, I’d like to use the DuckDuckGo MCP server that’s available on the Docker MCP Hub. And to make my life easier, I’m going to use the Docker MCP Gateway to access this MCP server.

Configuring the Docker MCP Gateway in Docker Compose

To use the Docker MCP Gateway, I’ll first modify the compose.yml file to add the gateway configuration.

Configuring the gateway in the compose.yaml file

Here’s the configuration I added for the gateway in the compose.yaml file:

mcp-gateway:
image: docker/mcp-gateway:latest
command:
– –port=8811
– –transport=sse
– –servers=duckduckgo
– –verbose
volumes:
– /var/run/docker.sock:/var/run/docker.sock

This configuration will create an mcp-gateway service that will listen on port 8811 and use the sse (Server-Sent Events) transport to communicate with MCP servers.

Important:

with –servers=duckduckgo I can filter the available MCP servers to only use the DuckDuckGo server.

the MCP Gateway will automatically pull the available MCP servers from the Docker MCP Hub.

The MCP Gateway is an open-source project that you can find here: 

Next, I’ll modify the koog-app service so it can communicate with the gateway by adding the MCP_HOST environment variable that will point to the gateway URL, as well as the dependency on the mcp-gateway service:

environment:
MCP_HOST: http://mcp-gateway:8811/sse
depends_on:
– mcp-gateway

I’ll also modify the system prompt and user message:

environment:
SYSTEM_PROMPT: |
You are a helpful cooking assistant.
Your job is to understand the user prompt and decide if you need to use tools to run external commands.
AGENT_INPUT: |
Search for the ingredients to cook a ratatouille, max result 1
Then, from these found ingredients, generate a yummy ratatouille recipe
Do it only once

So here’s the complete compose.yml file with the MCP Gateway configuration and the modifications made to the koog-app service:

services:

koog-app:
build:
context: .
dockerfile: Dockerfile
environment:
SYSTEM_PROMPT: |
You are a helpful cooking assistant.
Your job is to understand the user prompt and decide if you need to use tools to run external commands.
AGENT_INPUT: |
Search for the ingredients to cook a ratatouille, max result 1
Then, from these found ingredients, generate a yummy ratatouille recipe
Do it only once
MCP_HOST: http://mcp-gateway:8811/sse
depends_on:
– mcp-gateway
models:
app_model:
# NOTE: populate the environment variables with the model runner endpoint and model name
endpoint_var: MODEL_RUNNER_BASE_URL
model_var: MODEL_RUNNER_CHAT_MODEL

mcp-gateway:
image: docker/mcp-gateway:latest
command:
– –port=8811
– –transport=sse
– –servers=duckduckgo
– –verbose
volumes:
– /var/run/docker.sock:/var/run/docker.sock

models:
app_model:
model: hf.co/menlo/lucy-128k-gguf:q4_k_m

Now, let’s modify the Kotlin code to use the MCP Gateway and search for ratatouille ingredients.

Modifying the Kotlin code to use the MCP Gateway

The modification is extremely simple; you just need to:

define the MCP transport (SseClientTransport) with the gateway URL: val transport = McpToolRegistryProvider.defaultSseTransport(System.getenv(“MCP_HOST”))

create the MCP tools registry with the gateway: val toolRegistry = McpToolRegistryProvider.fromTransport(transport = transport, name = “sse-client”, version = “1.0.0”)

and finally, add the tools registry to the Koog agent constructor: toolRegistry = toolRegistry

Extremely important: I added capabilities = listOf(LLMCapability.Completion, LLMCapability.Tools) for the LLM model, because we’re going to use its “function calling” capabilities (the tools are defined and provided by the MCP server).

Here’s the complete code of the Koog agent modified to use the MCP Gateway in the src/main/kotlin/Main.kt file:

package kitchen.ratatouille

import ai.koog.agents.core.agent.AIAgent
import ai.koog.agents.mcp.McpToolRegistryProvider
import ai.koog.prompt.executor.clients.openai.OpenAIClientSettings
import ai.koog.prompt.executor.clients.openai.OpenAILLMClient
import ai.koog.prompt.executor.llms.SingleLLMPromptExecutor
import ai.koog.prompt.llm.LLMCapability
import ai.koog.prompt.llm.LLMProvider
import ai.koog.prompt.llm.LLModel

suspend fun main() {

val transport = McpToolRegistryProvider.defaultSseTransport(System.getenv("MCP_HOST"))
// Create a tool registry with tools from the MCP server
val toolRegistry = McpToolRegistryProvider.fromTransport(
transport = transport,
name = "sse-client",
version = "1.0.0"
)
println(toolRegistry.tools)

val apiKey = "nothing"
val customEndpoint = System.getenv("MODEL_RUNNER_BASE_URL").removeSuffix("/")
val model = System.getenv("MODEL_RUNNER_CHAT_MODEL")

val client = OpenAILLMClient(
apiKey=apiKey,
settings = OpenAIClientSettings(customEndpoint)
)

val promptExecutor = SingleLLMPromptExecutor(client)

val llmModel = LLModel(
provider = LLMProvider.OpenAI,
id = model,
capabilities = listOf(LLMCapability.Completion, LLMCapability.Tools)
)

val agent = AIAgent(
executor = promptExecutor,
systemPrompt = System.getenv("SYSTEM_PROMPT"),
llmModel = llmModel,
temperature = 0.0,
toolRegistry = toolRegistry
)

val recipe = agent.run(System.getenv("AGENT_INPUT"))

println("Recipe:n $recipe")

}

Launching the project with the MCP Gateway

Let’s launch the project again with the command:

docker compose up –build –no-log-prefix

And after a while, you should get a new ratatouille recipe, but the LLM will have relied on the search results performed by the DuckDuckGo MCP server (via the MCP Gateway) to improve the recipe. The response time will be a bit longer because the LLM will first query the MCP server to get the ratatouille ingredients, then it will generate the recipe. And the DuckDuckGo MCP server will search for links and then retrieve the content of those links (indeed, the DuckDuckGo MCP server exposes 2 tools: search and fetch_content).

Here’s an example of what you might get with an improved and more “authentic” ratatouille recipe:

Recipe:
Here's a **complete and easy-to-follow version** of **Ratatouille**, based on the recipe you provided, with tips and variations to suit your preferences:

—

### **What Is Ratatouille?**
A classic French vegetable stew, traditionally made with eggplant, tomatoes, zucchini, bell peppers, onions, and mushrooms. It's often seasoned with herbs like parsley, thyme, or basil and paired with crusty bread or a light sauce.

—

### **Ingredients** (for 4 servings):
– **1/2 cup olive oil** (divided)
– **2 tbsp olive oil** (for the skillet)
– **3 cloves garlic**, minced
– **1 eggplant**, cubed
– **2 zucchinis**, sliced
– **2 large tomatoes**, chopped
– **2 cups fresh mushrooms**, sliced
– **1 large onion**, sliced
– **1 green or red bell pepper**, sliced
– **1/2 tsp dried parsley**
– **Salt to taste**
– **1/2 cup grated Parmesan cheese** (or pecorino, as you mentioned)

—

### **How to Make Ratatouille**
**Preheat oven** to 350°F (175°C).

1. **Prepare the dish**: Coat a 1½-quart casserole dish with 1 tbsp olive oil.
2. **Cook the base**: In a skillet, sauté garlic until fragrant (about 1–2 minutes). Add eggplant, parsley, and salt; cook for 10 minutes until tender.
3. **Layer the vegetables**: Spread the eggplant mixture in the dish, then add zucchini, tomatoes, mushrooms, onion, and bell pepper. Top with Parmesan.
4. **Bake**: Cover and bake for 45 minutes. Check for tenderness; adjust time if needed.

**Cook's Note**:
– Add mushrooms (optional) or omit for a traditional flavor.
– Use fresh herbs like thyme or basil if preferred.
– Substitute zucchini with yellow squash or yellow bell pepper for color.

—

### **How to Serve**
– **Main dish**: Serve with crusty French bread or rice.
– **Side**: Pair with grilled chicken or fish.
– **Guilt-free twist**: Add black olives or a sprinkle of basil/others for a lighter version.

—

Conclusion

This blog post perfectly illustrates the modern containerized AI ecosystem that Docker is building. By combining Docker Model Runner, Agentic Compose, Docker MCP Gateway, and the Koog framework (but we could of course use other frameworks), we were able to create an “intelligent” agent quite simply.

Docker Model Runner allowed us to use an AI model locally.

Agentic Compose simplified the integration of the model into our application by automatically injecting the necessary environment variables.

The Docker MCP Gateway transformed our little agent into a system capable of interacting with the outside world.

The Koog framework allowed us to orchestrate these components in Kotlin.

Soon, I’ll go deeper into the MCP Gateway and how to use it with your own MCP servers, and not just with Koog. And I continue my explorations with Koog and Docker Model Runner. Check out the entire source code of this project is available here 

Learn more

If you need more GPUs to experiment with different models, sign up for Docker Offload beta program and get 300 minutes for free. 

Discover hundreds of curated MCP servers on the Docker MCP Catalog

Learn more about Docker MCP Toolkit

Explore Docker MCP Gateway on GitHub

Get started with Docker Model Runner

Get more practical agent examples from Agentic Compose repos

Quelle: https://blog.docker.com/feed/
MCP Horror Stories: The Supply Chain Attack

This is Part 2 of our MCP Horror Stories series, an in-depth look at real-world security incidents exposing the vulnerabilities in AI infrastructure, and how the Docker MCP Toolkit delivers enterprise-grade protection.

The Model Context Protocol (MCP) promised to be the “USB-C for AI applications” – a universal standard enabling AI agents like ChatGPT, Claude, and GitHub Copilot to safely connect to any tool or service. From reading emails and updating databases to managing Kubernetes clusters and sending Slack messages, MCP creates a standardized bridge between AI applications and the real world.

But as we discovered in Part 1 of this series, that promise has become a security nightmare. For Part 2, we’re covering a critical OAuth vulnerability in mcp-remote that led to credential compromise and remote code execution across AI development environments.

Today’s Horror Story: The Supply Chain Attack That Compromised 437,000 Environments

In this issue, we dive deep into CVE-2025-6514 – a critical vulnerability that turned mcp-remote, a trusted OAuth proxy used by nearly half a million developers, into a remote code execution nightmare. This supply chain attack represents the first documented case of full system compromise achieved through the MCP infrastructure, affecting AI development environments at organizations using Cloudflare, Hugging Face, Auth0, and countless others.

You’ll learn:

How a simple OAuth configuration became a system-wide security breach

The specific attack techniques that bypass traditional security controls

Why containerized MCP servers prevent entire classes of these attacks

Practical steps to secure your AI development environment today

Why This Series Matters

Each “Horror Story” in this series examines a real-world security incident that transforms laboratory findings into production disasters. These aren’t hypothetical attacks – they’re documented cases where the MCP security issues and vulnerabilities we identified in Part 1 have been successfully exploited against actual organizations and developers.

Our goal is to show the human impact behind the statistics, demonstrate how these attacks unfold in practice, and provide concrete guidance on protecting your AI development infrastructure through Docker’s security-first approach to MCP deployment.

The story begins with something every developer has done: configuring their AI client to connect to a new tool…

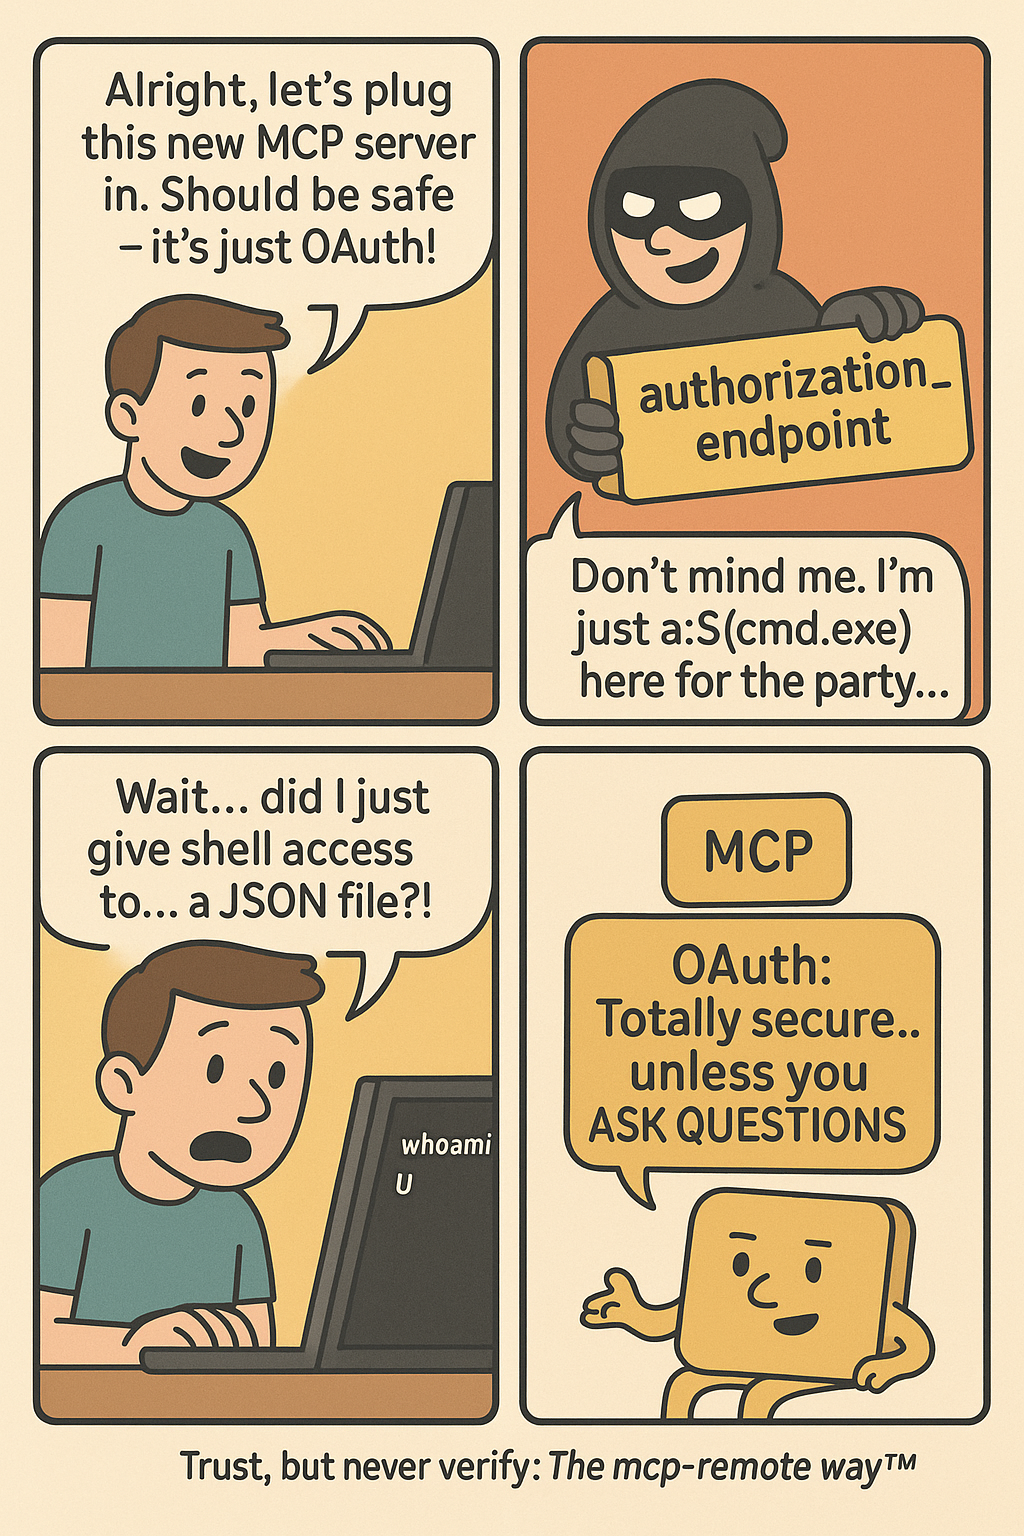
Caption: comic depicting OAuth vulnerability in mcp-remote horror story ~ a remote code execution nightmare

The Problem

In July 2025, JFrog Security Research discovered CVE-2025-6514. CVE-2025-6514 is a critical vulnerability in mcp-remote that affects how AI tools like Claude Desktop, VS Code, and Cursor connect to external services. With a devastating CVSS score of 9.6 out of 10, this vulnerability represents the first documented case of full remote code execution achieved against an MCP client in a real-world scenario.

The Scale of the Problem

The impact is staggering. The mcp-remote package has been downloaded more than 437,000 times, making this vulnerability a supply chain attack affecting hundreds of thousands of AI development environments. mcp-remote has been featured in integration guides from major platforms, including Cloudflare, Hugging Face, and Auth0, demonstrating its widespread enterprise adoption.

How the Attack Works

Here’s what happened: mcp-remote, a widely-used OAuth proxy for AI applications, trusts server-provided OAuth endpoints without validation. An attacker crafted a malicious authorization URL that gets executed directly by your system’s shell. When you configure your AI client to use a new tool, you’re essentially trusting that tool’s server to behave properly. CVE-2025-6514 shows what happens when that trust is misplaced.

To understand how CVE-2025-6514 became possible, we need to examine the Model Context Protocol’s architecture and identify the specific design decisions that created this attack vector. MCP consists of several interconnected components, each representing a potential point of failure in the security model.

MCP Client represents AI applications like Claude Desktop, VS Code, or Cursor that receive user prompts and coordinate API calls. In CVE-2025-6514, the client becomes an unwitting enabler, faithfully executing what it believes are legitimate OAuth flows without validating endpoint security.

mcp-remote (Third-Party OAuth Proxy) serves as the critical vulnerability point—a community-built bridge that emerged to address OAuth limitations while the MCP specification continues evolving its authentication support. This proxy handles OAuth discovery, processes server-provided metadata, and integrates with system URL handlers. However, this third-party solution’s blind trust in server-provided OAuth endpoints creates the direct pathway from malicious JSON to system compromise.

Caption: diagram showing the authentication workflow and attack surface

Communication Protocol carries JSON-RPC messages between clients and servers, including the malicious OAuth metadata that triggers CVE-2025-6514. The protocol lacks built-in validation mechanisms to detect command injection attempts in OAuth endpoints.

System Integration connects mcp-remote to operating system services through URL handlers and shell execution. When mcp-remote processes malicious OAuth endpoints, it passes them directly to system handlers—PowerShell on Windows, shell commands on Unix—enabling arbitrary code execution.

The vulnerability happens in step 4. mcp-remote receives OAuth metadata from the server and passes authorization endpoints directly to the system without validation.

Technical Breakdown: The Attack

Here’s how a developer’s machine and data get compromised:

1. Legitimate Setup

When users want to configure their LLM host, such as Claude Desktop, to connect to a remote MCP server, they follow standard procedures by editing Claude’s configuration file to add an mcp-remote command with only the remote MCP server’s URL:

{
"mcpServers": {
"remote-mcp-server-example": {
"command": "npx",
"args": [
"mcp-remote",
"http://remote.server.example.com/mcp"
]
}
}
}

2. OAuth Discovery Request

When the developer restarts Claude Desktop, mcp-remote makes a request to http://remote.server.example.com/.well-known/oauth-authorization-server to get OAuth metadata.

3. Malicious Response

Instead of legitimate OAuth config, the compromised server returns:

{
"authorization_endpoint": "a:$(cmd.exe /c whoami > c:temppwned.txt)",
"registration_endpoint": "https://remote.server.example.com/register",
"code_challenge_methods_supported": ["S256"]
}

Note: The a: protocol prefix exploits the fact that non-existing URI schemes don’t get URL-encoded, allowing the $() PowerShell subexpression to execute. This specific technique was discovered by JFrog Security Research as the most reliable way to achieve full command execution.

4. Code Execution

mcp-remote processes this like any OAuth endpoint and attempts to open it in a browser:

// Vulnerable code pattern in mcp-remote (from auth.ts)
const authUrl = oauthConfig.authorization_endpoint;
// No validation of URL format or protocol
await open(authUrl.toString()); // Uses 'open' npm package

The open() function on Windows executes:

powershell -NoProfile -NonInteractive -ExecutionPolicy Bypass -EncodedCommand '…'

Which decodes and runs:

Start "a:$(cmd.exe /c whoami > c:temppwned.txt)"

The a: protocol triggers Windows’ protocol handler, and the $() PowerShell subexpression operator executes the embedded cmd.exe command with your user privileges.

The Impact

Within seconds, the attacker now has:

Your development machine compromised

Ability to execute arbitrary commands

Access to environment variables and credentials

Potential access to your company’s internal repositories

How Docker MCP Toolkit Eliminates This Attack Vector

The current MCP ecosystem forces developers into a dangerous trade-off between convenience and security. Every time you run npx -y @untrusted/mcp-server or uvx some-mcp-tool, you’re executing arbitrary code directly on your host system with full access to:

Your entire file system

All network connections

Environment variables and secrets

System resources

This is exactly how CVE-2025-6514 achieves system compromise—through trusted execution paths that become attack vectors. When mcp-remote processes malicious OAuth endpoints, it passes them directly to your system’s shell, enabling arbitrary code execution with your user privileges.

Docker’s Security-First Architecture

Docker MCP Catalog and Toolkit represent a fundamental shift toward making security the path of least resistance. Rather than patching individual vulnerabilities, Docker built an entirely new distribution and execution model that eliminates entire classes of attacks by design. The explosive adoption of Docker’s MCP Catalog – surpassing 5 million pulls in just a few weeks – demonstrates that developers are hungry for a secure way to run MCP servers. 

Docker MCP Catalog and Toolkit fundamentally solves CVE-2025-6514 by eliminating the vulnerable architecture entirely. Unlike npm packages that can be hijacked or compromised, Docker MCP Catalog and Toolkit include:

Cryptographic verification ensuring images haven’t been tampered with

Transparent build processes for Docker-built servers

Continuous security scanning for known vulnerabilities

Immutable distribution through Docker Hub’s secure infrastructure

Eliminating Vulnerable Proxy Patterns

1. Native OAuth Integration

Instead of relying on mcp-remote, Docker Desktop handles OAuth directly:

# No vulnerable mcp-remote needed
docker mcp oauth ls
github | not authorized
gdrive | not authorized

# Secure OAuth through Docker Desktop
docker mcp oauth authorize github
# Opens browser securely via Docker's OAuth flow

docker mcp oauth ls
github | authorized
gdrive | not authorized

2. No More mcp-remote Proxy

Instead of using vulnerable proxy tools, Docker provides containerized MCP servers:

# Traditional vulnerable approach:
{
"mcpServers": {
"remote-server": {
"command": "npx",
"args": ["mcp-remote", "http://remote.server.example.com/mcp"]
}
}
}

# Docker MCP Toolkit approach:
docker mcp server enable github-official
docker mcp server enable grafana

No proxy = No proxy vulnerabilities.

3. Container Isolation with Security Controls

While containerization doesn’t prevent CVE-2025-6514 (since that vulnerability occurs in the host-based proxy), Docker MCP provides defense-in-depth through container isolation for other attack vectors:

# Maximum security configuration
docker mcp gateway run
–verify-signatures
–block-network
–block-secrets
–cpus 1
–memory 1Gb

This protects against tool-based attacks, command injection in MCP servers, and other container-breakout attempts.

4. Secure Secret Management

Instead of environment variables, Docker MCP uses Docker Desktop’s secure secret store:

# Secure secret management
docker mcp secret set GITHUB_TOKEN=ghp_your_token
docker mcp secret ls
# Secrets are never exposed as environment variables

5. Network Security Controls

Prevent unauthorized outbound connections:

# Zero-trust networking
docker mcp gateway run –block-network
# Only allows pre-approved destinations like api.github.com:443

6. Real-Time Threat Protection

Active monitoring and prevention:

# Block secret exfiltration
docker mcp gateway run –block-secrets
# Scans tool responses for leaked credentials

# Resource limits prevent crypto miners
docker mcp gateway run –cpus 1 –memory 512Mb

7. Attack Prevention in Practice

The same attack that works against traditional MCP fails against Docker:

# Traditional MCP (vulnerable to CVE-2025-6514)
npx mcp-remote http://malicious-server.com/mcp
# → OAuth endpoint executed on host → PowerShell RCE → System compromised

# Docker MCP (attack contained)
docker mcp server enable untrusted-server
# → Runs in container → L7 proxy controls network → Secrets protected → Host safe

8. Practical Security Improvements

Here’s what you get with Docker MCP Toolkit:

Security Aspect

Traditional MCP

Docker MCP Toolkit

Execution Model

Direct host execution via npx/mcp-remote

Containerized isolation

OAuth Handling

Vulnerable proxy with shell execution

No proxy needed, secure gateway

Secret Management

Environment variables

Docker Desktop secure store

Network Access

Unrestricted host networking

L7 proxy with allowlisted destinations

Resource Controls

None

CPU/memory limits, container isolation

Monitoring

No visibility

Comprehensive logging with –log-calls

Best Practices for Secure MCP Deployment

Start with Docker-built servers – Choose the gold standard when available

Migrate from mcp-remote – Use containerized MCP servers instead

Enable security controls – Use –block-network and –block-secrets

Verify images – Use –verify-signatures for supply chain security

Set resource limits – Prevent resource exhaustion attacks

Monitor tool calls – Enable logging with –log-calls for audit trails

Regular security updates – Keep Docker MCP Toolkit updated

Take Action: Secure Your AI Development Today

The path to secure MCP development starts with a single step. Here’s how you can join the movement away from vulnerable MCP practices:

Browse the Docker MCP Catalog to find containerized, verified MCP servers that replace risky npm packages with enterprise-grade security.

Install Docker Desktop and run MCP servers safely in isolated containers with help with Docker MCP Toolkit. Compatible with all major AI clients including Claude Desktop, Cursor, VS Code, and more—without the security risks.

Have an MCP server? Help build the secure ecosystem by submitting it to the Docker catalog. Choose Docker-built for maximum security or community-built for container isolation benefits.

Conclusion

CVE-2025-6514 demonstrates why the current MCP ecosystem needs fundamental security improvements. By containerizing MCP servers and eliminating vulnerable proxy patterns, Docker MCP Toolkit doesn’t just patch this specific vulnerability—it prevents entire classes of host-based attacks.

Coming up in our series: MCP Horror Stories issue 3 will explore how GitHub’s official MCP integration became a vector for private repository data theft through prompt injection attacks.

Learn more

Explore the MCP Catalog: Visit the MCP Catalog to discover MCP servers that solve your specific needs securely.

Use and test hundreds of MCP Servers: Download Docker Desktop to download and use any MCP server in our catalog with your favorite clients: Gordon, Claude, Cursor, VSCode, etc

Submit your server: Join the movement toward secure AI tool distribution. Check our submission guidelines for more.

Follow our progress: Star our repository and watch for updates on the MCP Gateway release and remote server capabilities.

Read issue #1 of this MCP Horror Stories series

Quelle: https://blog.docker.com/feed/
The Next Evolution of Docker Hardened Images: Customizable, FedRAMP Ready, AI Migration Agent, and Deeper Integrations

We launched Docker Hardened Images (DHI) in May, and in just two and a half months, adoption has accelerated rapidly across industries. From nimble startups to global enterprises, organizations are turning to DHI to achieve near-zero CVEs, shrink their attack surface, and harden their software supply chain, all without slowing down developers.

In a short time, DHI has become the trusted foundation for production workloads: minimal, signed, continuously patched, and built from the ground up to deliver security at scale. Platform and security teams alike are moving faster and more securely than ever before.

That momentum is why we’re doubling down. We’re expanding Docker Hardened Images with powerful new capabilities: a broader image catalog, flexible customization options, AI migration agent, FedRAMP-ready variants, and tighter integrations with the tools teams already use every day. Many of these enhancements will be in action at Black Hat 2025.

Secure Images for End-to-End Workloads

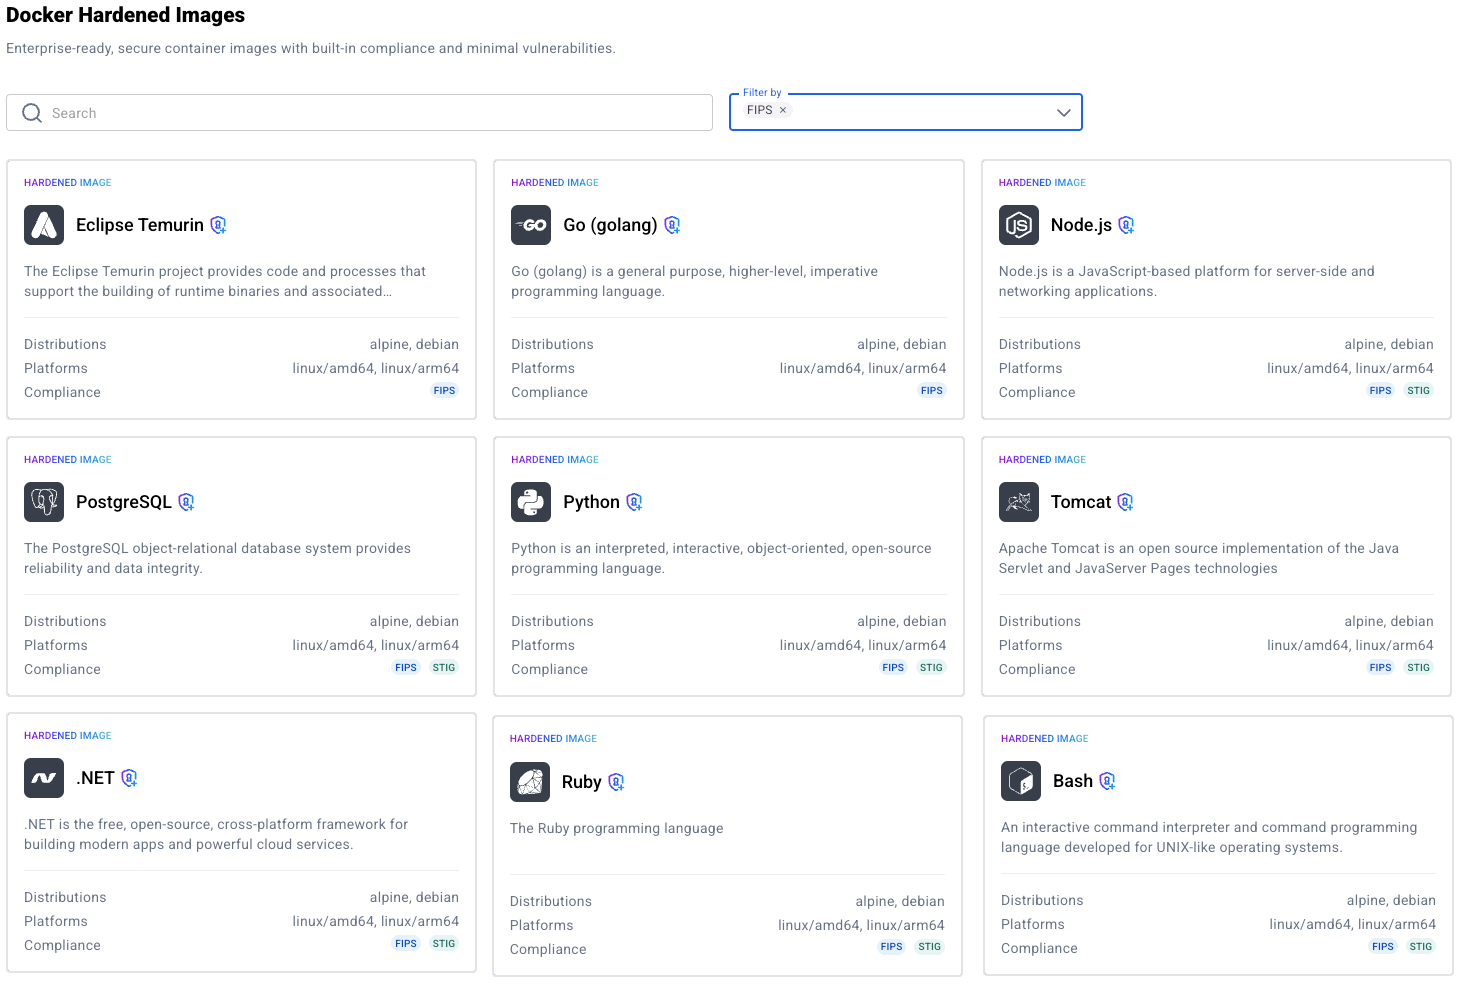
One of the most consistent things we hear from customers, especially those in security-conscious environments, is that they’re not just running a few basic containers. They’re deploying full-stack systems that span everything from message queues like RabbitMQ and Redis, to web servers like Tomcat and NGINX, databases and storage tools such as PostgreSQL and Prometheus, and developer tools like Azure Functions and Grafana. They also rely on networking components like Envoy, monitoring and observability stacks like Grafana, Loki, and Netdata, and even ML and AI infrastructure like Kubeflow. 

To support these real-world workloads, the Docker Hardened Images (DHI) catalog now includes trusted, production-ready images across all these categories. Every image is SLSA-compliant, signed, and continuously maintained, giving security teams confidence that they’re using secure, verifiable containers without slowing down developers or complicating compliance.

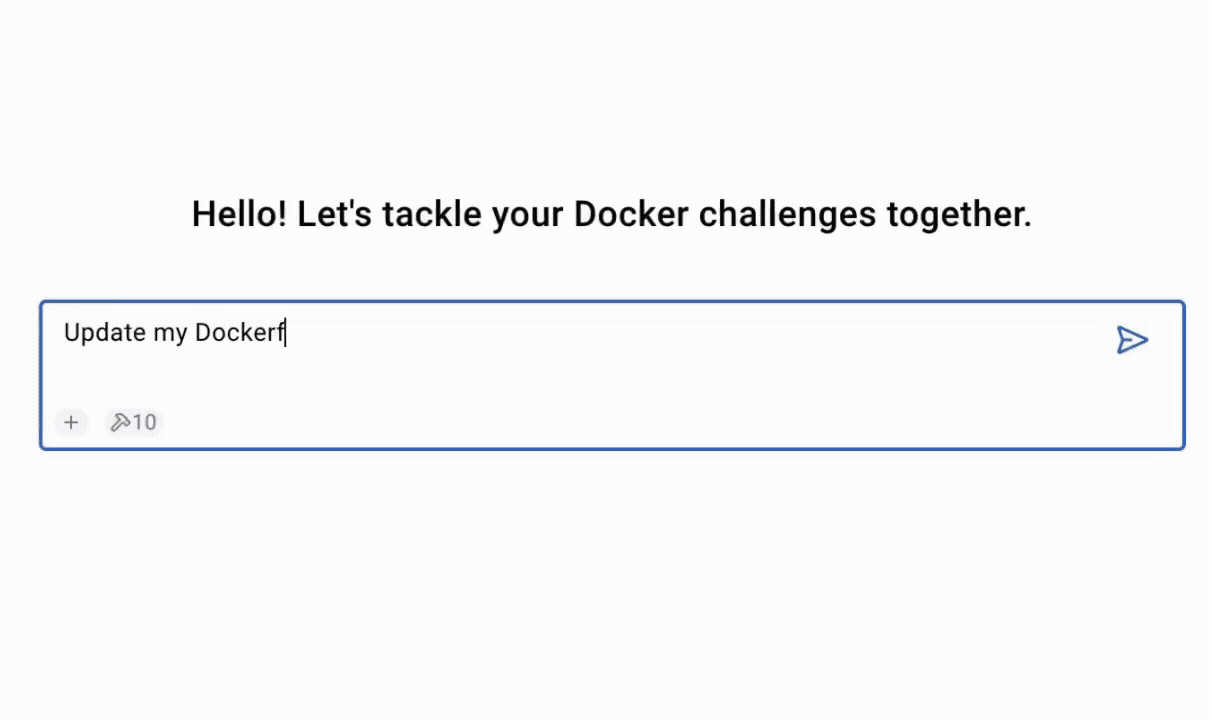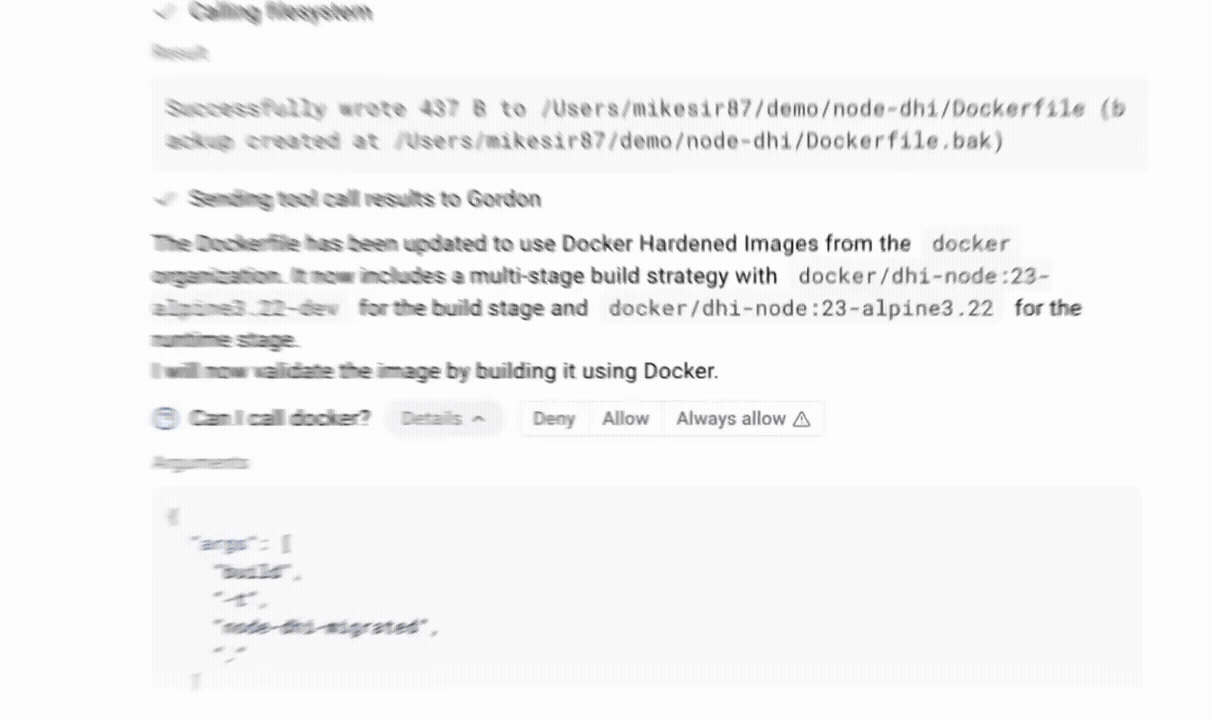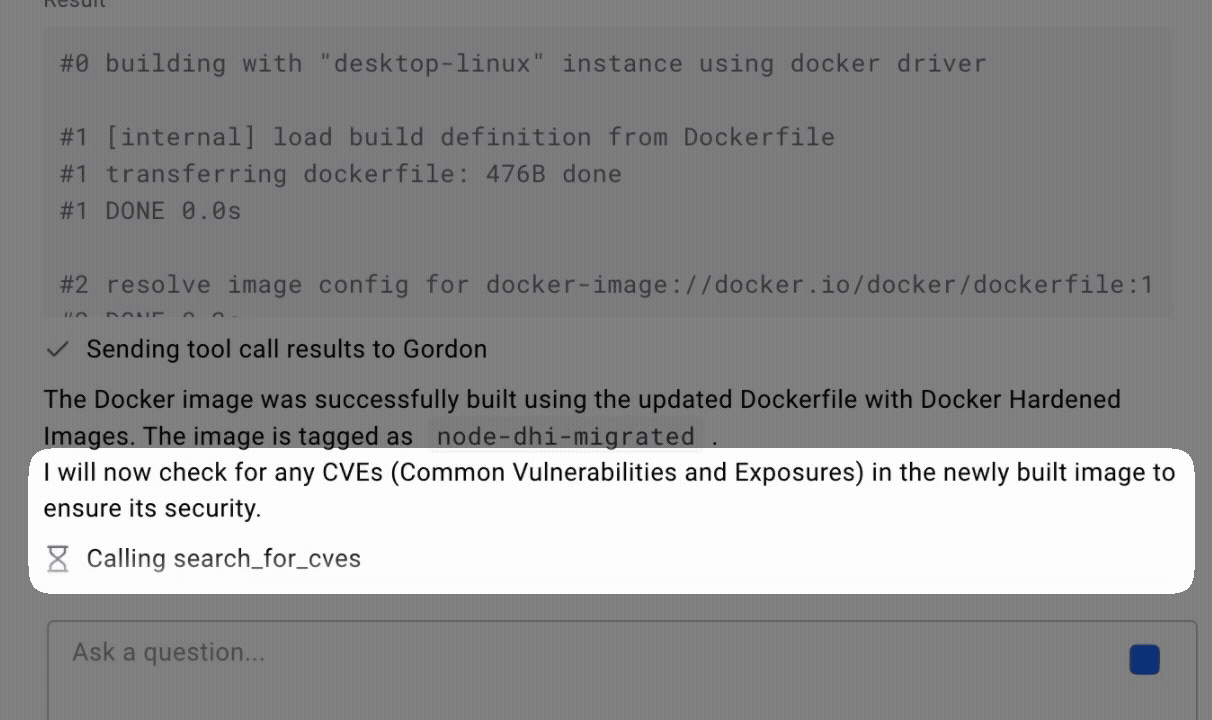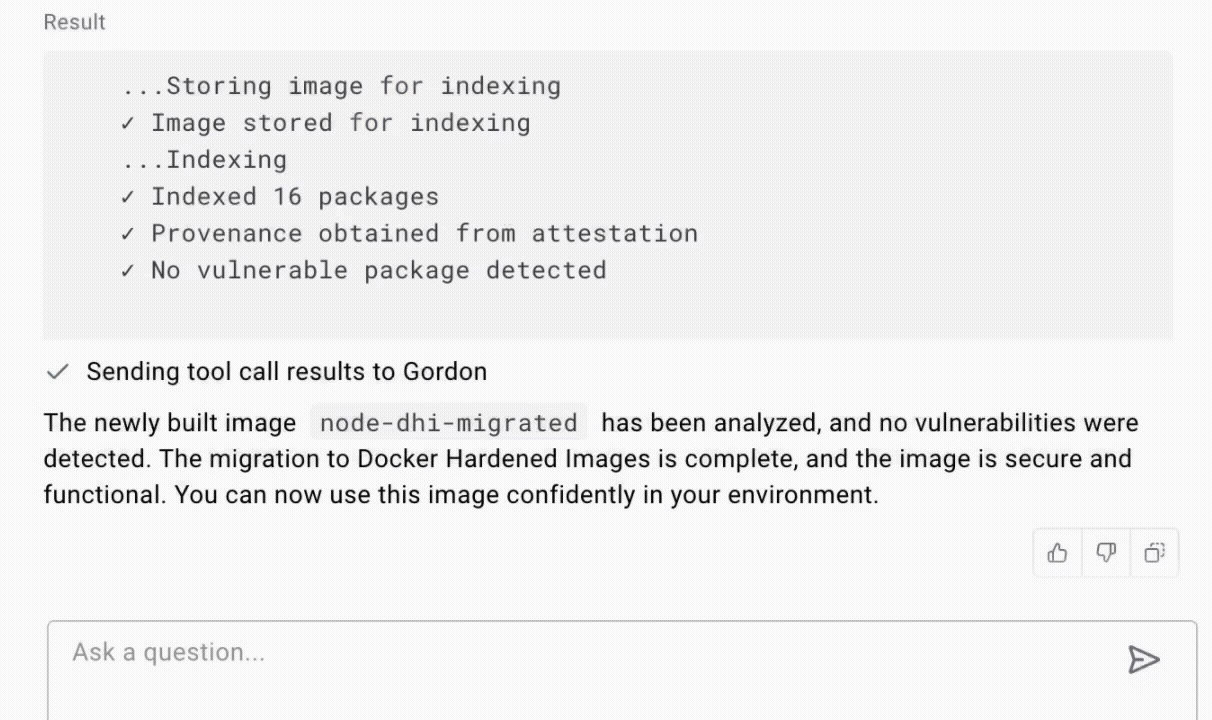
And now, getting started with DHI is even easier. Docker’s AI assistant can automatically analyze your existing containers and recommend or apply equivalent hardened images, streamlining your move from community or internal images. Watch it in action below.

DHI Customization: Flexibility without the risk

Another piece of feedback we’ve heard from customers is how much they appreciate the flexibility of DHI. DHI meets teams where they are, allowing them to customize based on their unique needs rather than forcing them to adapt to rigid constraints. The ability to tailor images while still relying on a hardened, security-first foundation has been a clear win. And now, we’ve taken that experience even further.

With our new self-serve UI, customizing DHI is faster and simpler than ever. You can inject internal certificates, install trusted packages, tweak runtime settings, and define user policies, all without forking base images or wrangling complex workarounds.

Need to configure runtimes, install essential tools like curl, git, or debugging utilities? Want to add custom CA certificates for internal trust chains, set environment variables, or define custom users and groups? With DHI, you can do it all in just a few clicks.

Best of all, your custom images stay secure automatically. Customizations are packaged as OCI artifacts: secure, versioned layers that cleanly separate your logic from the base image. Docker handles the final image build, signs it while maintaining a SLSA Build Level 3 standard, and ensures the image is always up to date.

When the base image receives a security patch or your own artifacts are updated, Docker automatically rebuilds your customized images in the background. No manual work. No surprise drift. Just continuous compliance and protection by default. Customers can create as many customizations as they need for each repository, without any additional cost. 

This is a huge win for platform and security teams. There’s no need to fork base images, write custom CI rebuild scripts, or maintain parallel image pipelines just to meet security or policy requirements. You get the flexibility you need without the operational overhead.

FedRAMP-Ready: Built for compliance from the start

If you’re chasing FedRAMP authorization, meeting strict security standards like FIPS and STIG isn’t optional, it’s mission-critical. But hardening container images manually? That’s wasted time, human error, and endless maintenance.

Docker Hardened Images now ship with FedRAMP-ready variants, engineered to align out of the box with U.S. federal security requirements. These images are FIPS-enabled for strong, validated cryptographic enforcement, STIG-ready with secure defaults baked in, and delivered with signed SBOMs and attestations for full auditability.

All of this is built and maintained by Docker so your team doesn’t have to be in the business of compliance engineering. Just plug these images into your pipeline and go. Under the hood, Docker’s FIPS-enabled images leverage validated cryptographic modules such as OpenSSL, Bouncy Castle, and Go. Each image includes signed attestations linked to NIST certifications and test results, ensuring transparency and traceability across the software supply chain.

Every STIG-ready image is scanned via OpenSCAP during secure builds and comes with signed results, including compliance scores and full scan outputs (HTML and XCCDF). Each result is clearly mapped to NIST 800-53 controls, making it easier for security teams and auditors to assess and track compliance. As you customize these images, Docker helps you track compliance over time, making it easier for security teams and auditors alike.

Learn how Docker is simplifying FedRAMP readiness in this deep-dive blog post

Docker + Wiz: Smarter Vulnerability Management

Docker Hardened Images integrate seamlessly into your existing developer and security workflows, working out of the box with popular tools like GitLab, Sonatype, CloudSmith, Docker Hub, Docker Desktop, GitHub Actions, Jenkins, and more.

Now, we’re taking it a step further: Docker Hardened Images integrate with Wiz, empowering security teams with deeper, context-rich visibility into real risk based on what’s running in production, what’s exposed to the internet, and what interacts with sensitive data.

“Docker’s Hardened Images offer an exceptionally secure foundation with significantly smaller surface areas and near-zero CVEs”, said Oron Noah, VP of Product, Extensibility & Partnerships at Wiz. “The integration between Docker and Wiz empowers DevSecOps teams to operationalize these trusted foundations with complete visibility into container image technologies and precise vulnerability reporting. Rich OpenVEX documents and OSV advisories provided by Docker add context to vulnerabilities reported in Wiz, enabling teams to prioritize the vulnerabilities that matter and remediate faster without slowing down innovation. This integration gives platform and security teams both a secure foundation and a platform to monitor and manage the full container security lifecycle from code to runtime.”

Putting DHI to the Test: Independent Security Assessment

To validate the security posture of Docker Hardened Images, we partnered with Security Research Labs (SRLabs), a leading cybersecurity firm, to conduct an independent assessment. Their review included threat modeling, architectural analysis, and grey-box testing using publicly available artifacts, simulating realistic attack scenarios.

The results reaffirmed our approach. SRLabs verified that all sampled Docker Hardened Images are cryptographically signed, rootless by default, and ship with both SBOM and VEX metadata, a critical combination for modern software supply chain security. 

Importantly, no root escapes or high-severity breakouts were found during the assessment period. SRLabs also validated Docker’s claim of removing common shells and package managers, significantly reducing the attack surface up to 95% smaller than standard images. 7-day patch SLA and build-to-sign pipeline were identified as a strength compared to typical community images. The review also acknowledged areas for improvement such as key revocation and build determinism which are already being actively addressed.

Read more about the SRLabs report here. 

The Future of Hardened Containers Starts Here

Docker Hardened Images are becoming the trusted foundation for building and running secure apps at scale. With a broad catalog, easy customization, FedRAMP-ready variants, and integrations like Wiz, DHI meets teams where they are. Best of all, customization, FIPS, and STIGs are included at no extra cost, simplifying compliance without compromise.

If you’re attending Black Hat 2025, we’d love to connect. Please come visit Docker at Booth #5315 to explore how we’re redefining software supply chain security. And don’t miss our session, “Achieving End-to-End Software Supply Chain Security”, happening on Wednesday, August 6 from 12:05 to 1:30 PM in Lagoon CD, Level 2. We’ll be diving deep into real-world strategies for implementing hardened, traceable, and continuously compliant software delivery pipelines.
Quelle: https://blog.docker.com/feed/
Accelerating FedRAMP Compliance with Docker Hardened Images

Federal Risk and Authorization Management Program (FedRAMP) compliance costs typically range from $450,000 to over $2 million and take 12 to 18 months to achieve, time your competitors are using to capture government contracts. While you’re spending months configuring FIPS cryptography, hardening security baselines, and navigating 400+ security controls, your competitors are already shipping to federal agencies. Companies that want to sell cloud products and services to the US government must meet the rigorous requirements of FedRAMP, which mandates they implement the expansive security controls described in NIST Special Publication 800-53. As more companies go through this process, they’re looking for ways to accelerate the process (faster time-to-market) and reduce the cost of maintaining FedRAMP compliance.

Shift from months of manual compliance work to automated, auditable security. In May, we announced Docker Hardened Images (DHI) – a curated catalog of minimalist images, kept continuously up to date by Docker to ensure near-zero known CVEs. Today, we are announcing support for FIPS 140-compliant and STIG hardened images – two FedRAMP hurdles that companies have found particularly challenging. Below, we will dive into these new features in more detail and give an overview of all the ways DHI addresses pain points associated with FedRAMP.

FIPS-enabled Docker Hardened Images

FIPS Validated Cryptography Made Simple

FIPS 140 is a US government standard that defines security and testing requirements for cryptographic modules that protect sensitive information. FedRAMP requires that companies use cryptographic modules that have been validated by the NIST Cryptographic Module Validation Program (CMVP). 

Although swapping out a cryptographic library for a FIPS-validated one in a base image might seem simple, it can become increasingly difficult as some software must be specifically configured or built from source to use the FIPS-validated module, and even the selection of cryptographic algorithms may need to change. And it’s not just a one-time effort. As you update your software over time, you must be able to prove that your image is still compliant and you haven’t accidentally introduced non-validated cryptographic software.

FIPS-compliant Docker images do all the hard work for you. They are pre-configured to use FIPS-validated software and tested during our secure build process to confirm correct function. But you don’t have to take our word for it. Every FIPS-compliant image comes with signed attestations that list the FIPS-validated software in use, complete with links to its CMVP certification and the test results proving it. We support all major open source cryptographic modules, including OpenSSL, Bouncy Castle, and Go.

{
"certification": "CMVP #4985",
"certificationUrl": "https://csrc.nist.gov/projects/cryptographic-module-validation-program/certificate/4985",
"name": "OpenSSL FIPS Provider",
"package": "pkg:dhi/openssl-provider-fips@3.1.2",
"standard": "FIPS 140-3",
"status": "active",
"sunsetDate": "2030-03-10",
"version": "3.1.2"
}

STIG Hardened Images without the Headache

Security Technical Implementation Guides (STIGs) are the FedRAMP preferred baselines for secure configuration. STIGs are application-specific versions of the more general Security Requirements Guides (SRGs) and are designed to be run programmatically using Security Content Automation Protocol (SCAP) compatible software. Both STIGs and SRGs are published by the US Defense Information Systems Agency (DISA).

Currently, there are no government-published, container-specific STIGs or SRGs. However, per Department of Defence guidance, if there is no related STIG, the most relevant SRG can be used to determine compliance. For containers, that is the General Purpose Operating System (GPOS) SRG. Docker has created a custom STIG that checks for all the container-relevant content from the GPOS SRG. We’re also aligned with industry efforts to create government-published, container-specific STIGs, which we can leverage in the future.

STIG-hardened Docker images are scanned during our secure build process using OpenSCAP and our custom container STIG, and we deliver the results as signed attestations. The STIG compliance score (% of checks passing) is easily visible inside the attestation and from the Docker Hub UI, making it simple to gauge compliance. Not only do we run this scan when we build the initial image, but also anytime we rebuild it using DHI’s new customization features so that you can easily see if you’ve added customizations that would affect your compliance.

STIG-Hardened Docker Images Scoring

In addition to the scan score, we also provide the full HTML and Extensible Configuration Checklist Description Format (XCCDF) output of OpenSCAP so that you can inspect the results yourself. 

The HTML output is convenient for taking a quick look, while XCCDF is great for loading into the SCAP-compliant tool of your (or your auditor’s) choice for rich visualization. For example, Heimdall will helpfully map the checks to the underlying NIST 800-53 controls for you. For those wanting to manually map our checks back to the GPOS SRG, we’ve used consistent numbering of check IDs between the two for easy cross-referencing.

{
"name": "Docker Hardened Image – Debian 12 GPOS STIG Profile",
"output": [
{
"content": "…",
"format": "html",
"mediaType": "text/html"
},
{
"content": "…",
"format": "xccdf",
"mediaType": "application/xml"
}
],
"profile": "xccdf_dhi-debian_profile_.check",
"publisher": "Docker, Inc.",
"result": "passed",
"status": "active",
"summary": {
"defaultScore": 100,
"failedChecks": 0,
"maxDefaultScore": 100,
"notApplicableChecks": 107,
"passedChecks": 91,
"totalChecks": 198
},
"tool": "openscap",
"type": "Vendor published STIG-ready content, SRG aligned",
"version": "0.1"
}

Continuous Compliance at Scale 

Vulnerability Reduction

Docker Hardened Images start with a dramatically reduced attack surface, up to 95% smaller by package count, to limit exposure from the outset, and are kept continuously up to date to ensure near-zero known CVEs. Images are also scanned for viruses and secrets with corresponding attestations that can serve as evidence during audits.

Vulnerability Detection & Remediation

FedRAMP requires that companies monitor and scan for vulnerabilities and remediate them within a defined timeframe (30/90/180 days for high/moderate/low risk). Docker continually monitors various CVE sources to detect applicable vulnerabilities in our hardened images. CVE counts are reported in the Docker Hub UI and as attestations and Docker Scout can be configured to notify you of new vulnerabilities affecting previously pulled images. DHI has a remediation SLA of 7 days for critical/high vulnerabilities and 30 days for medium/low ones (from availability of an upstream fix), ensuring that you can comfortably meet the FedRAMP remediation timelines.

Docker also provides Vulnerability Exploitability eXchange (VEX) attestations that identify vulnerabilities that do not apply to the image (and explains why) so that scanners that support the VEX standard can automatically filter these results, allowing you to look past the noise and focus on exploitability.

Integrity and Supply Chain Transparency

Doctor Hardened Images are built using an SLSA Build Level 3 secure build pipeline that ensures verifiability and prevents tampering during and after the build. Build provenance is provided via signed attestations, and Software Bills of Materials (SBOMs) are generated in multiple popular formats to help satisfy FedRAMP’s asset management and software inventory reporting requirements.

Audit Evidence

You’ve heard attestations mentioned multiple times in this post. There’s a good reason for that. Evidence is everything when demonstrating compliance with FedRAMP or other regulatory frameworks. DHI attestations serve as secure evidence of all aspects of DHI security, from provenance to asset management to vulnerability and other security scanning to FIPS compliance. Attestations follow the in-toto attestation standard, a project of the Cloud Native Computing Foundation (CNCF), ensuring compatibility across a wide range of software vendors.

Government Grade Security for Every Environment

While there are definitely parts of the FedRAMP process specific to the federal government, the NIST 800-53 controls on which it is based are intended to be common-sense security best practices. So whether or not your company is currently subject to FedRAMP, aligning your security practices with the underlying controls makes good sense. We see this with initiatives like GovRAMP that define FedRAMP-aligned security controls for companies selling to state and local governments. 

Ready to accelerate your FedRAMP journey?

Docker Hardened Images are designed both to help you ship software with confidence and to make FedRAMP compliance easier and less costly. Let Developers stay focused on building while giving Compliance teams and Auditors the evidence they need.

We’re here to help. Get in touch with us and let’s harden your software supply chain, together.

Quelle: https://blog.docker.com/feed/
Everyone’s a Snowflake: Designing Hardened Image Processes for the Real World

Hardened container images and distroless software are the new hotness as startups and incumbents alike pile into the fast-growing market. In theory, hardened images provide not only a smaller attack surface but operational simplicity. In practice, there remains a fundamental – and often painful – tension between the promised security perfection of hardened images and the reality of building software atop those images and running them in production. This causes real challenges for platform engineering teams trying to hit the Golden Mean between usability and security.

Why? Everyone’s a snowflake. 

No two software stacks, CI/CD pipeline set ups and security profiles are exactly the same. In software, small differences can cause big headaches. When a developer can no longer access their preferred debugging tools, or cannot add the services they are used to pairing in a container, that causes friction and frustration. Naturally, devs who must ship figure out workarounds or other methods to achieve desired functionality. This snowflake reality can have a snowball affect of driving modifications underground, moving them outside of the hardened image process, or causing backlogs at hardened image vendors who designed their products for rigid security, not reality. In the worst case, they simplify ditch distroless and stymie adoption.

The counterintuitive truth? Rigid container solutions can have the opposite effect, making organizations less secure. This is why the process of designing and applying hardened images is most effective when developer and DevOps needs are taken into account and flexibility is baked into the process. At the same time, too much choice is chaos and chaos generates excessive risk. This is a delicate balance and the ultimate challenge for platform ops today.

The Snowflake Problem: Why Every Environment is Unique

The Snowflake Challenge in container security is pervasive. Walk into any engineering team and you’ll find them standardized not only on an OS distro and changes to that distro will likely cause unforeseen disruptions. They’ve got applications that need to connect to internal services with self-signed certificates, but hardened images often lack the CA bundles or the ability to easily add custom ones. They need to debug production issues with standard system tools, but hardened images leave them out. They’re running containers with multiple processes because splitting legacy applications into separate containers would break existing functionality and require months of rewriting. And they rely on package managers to install operational tools that security teams never planned for.

Distribution, tool and package loyalty isn’t just preference. It’s years of institutional knowledge baked into deployment scripts, monitoring configurations, and troubleshooting runbooks. Teams that have mastered a specific toolchain don’t want to retrain their entire organization just to get security benefits they can’t immediately see. Platform teams know this and will bias towards hardened image solutions that do not layer on cognitive load.

The reality is this. Real-world deployment patterns rarely match the security team’s slideshow. Multi-service containers are everywhere because deadlines matter more than architectural purity. These environments work, they’re tested, and they’re supporting actual users. Asking teams to rebuild their entire stack for theoretical security improvements feels like asking them to fix something that isn’t obviously broken. And they will find a way not to. So platform’s job is to find a hardened image solution that recognizes these types of realities and adjusts for them rather than forces behavioral change.

Familiarity as a Security Strategy

The most secure system in the world is worthless if your development teams route around it or ignore it. Flexibility and recognition that at least giving teams what they are used to having can make security nearly invisible and quite palatable.

In this light, multi-distro options from a hardened image vendor  isn’t a luxury feature. It’s an adoption requirement and critical way to mitigate the Snowflake Challenge. A hardened image solution that supports multiple major distros removes the biggest barrier to getting started – the fear of having to adopt an unfamiliar operating system. Once they recognize that their operating system in the hardened images will be familiar, platform teams can confidently begin hardening their existing stacks without worrying about retraining their entire engineering organization on a new base distribution or rewriting their deployment tooling.

Self-service customization turns potential friction into adoption drivers. When developers can add their required CA certificates easily and through self-service instead of filing support tickets, they actually use the tool. When they can merge their existing images with hardened bases through automated workflows, the migration path becomes clear. The goal isn’t to eliminate necessary customization but to make it just another simple step that is no big deal. No big deal modifications leads to smooth adoption paths and developer satisfaction.

The adoption math is straightforward. DDifficulty correlates inversely with security coverage. A perfectly hardened image that only 20% of teams can use provides less overall organizational security than a reasonably hardened image that 80% of teams adopt. Meeting developers where they are beats forcing architectural changes every time.

Migration Friction and Community Trust

The gap between current state and hardened images can feel daunting to many teams. Their existing Dockerfiles might be single-stage builds with years of accumulated dependencies. Their CI/CD pipelines assume certain tools will be available. Their developers assume packages they are comfortable with will be supported.

Modern tooling for hardened images can bridge this gap through progressive assistance. AI-powered converters can help translate existing Dockerfiles into multi-stage builds compatible with hardened bases. Converting legacy applications to hardened images through guided automation removes much of the technical friction. The tools handle the mechanical aspects of separating build dependencies from runtime dependencies while preserving application functionality. Teams can retain their existing development flows with less disruption and toil. Security adoption will be greater, while down-sizing the attack surface.

Hardened image adoption can depend on trust as much as technical merit. Organizations trust hardened image providers who demonstrate knowledge of the open source projects they’re securing. Docker has maintained close relationships with each open source project of the more than 70 official images listed on Docker Hub, That signals long-term commitment beyond just security theater. The reality is, the best hardened image design processes are dialogues that include project stakeholders and benefit from project insights and experience.The upshot? Platform teams need to talk to their developer and DevOps customers to understand what software is critical and to talk to their hardened image provider to understand their ties and active interactions with the upstream communities. A successful hardened image rollout must navigates these realities and acknowledge all the invested parties. 

The Happy Medium: Secure Defaults, Controlled Flexibility, Community Cred

Effective container security resembles building with Lego blocks rather than erecting security monoliths. The beloved Lego kits not only have a base-level design but are also easy to modify while maintaining structural integrity. Monoliths make appear more solid and substantial but modifying them is challenging and their strong opinionated view of the world is destined to cramp someone’s style.

Auditable customization paths maintain security posture while accommodating reality. When developers can add packages through controlled processes that log changes and validate security implications, both security and productivity goals get met. The secret lies in making the secure path the easy path rather than trying to eliminate all alternatives. At the foundational level, this requires solutions that integrate with existing practices rather than replacing them wholesale. 

Success metrics need to include coverage and adoption alongside traditional hardening measurements. A hardened image strategy that achieves 95% team adoption with 80% attack surface reduction delivers better organizational security than one that achieves 99% hardening but only gets used by 30% of applications. Platform teams that understand this math are far more likely to succeed in hardened image adoption and embrace.

Beyond the Binary: A New Security Paradigm

The bottom line? Really good security deployed everywhere beats perfect security deployed sporadically because security is a system property, not a component property. The weakest link determines overall posture. An organization with consistent, reasonable security practices across all applications faces lower aggregate risk than one with perfect security on some applications and no security on others.

The path forward involves designing hardened image processes that acknowledge developer reality and involves community in order to improve security outcomes. That comes through broad adoption and minimal disruption.. This means creating migration paths that feel achievable rather than overwhelming, providing automation to smooth the path, and delivering self-service options rather than more Jira-ticket Bingo. Every organization may be a snowflake, but that doesn’t make security impossible. It just means hardened image solutions need to be as adaptable as the environments they’re protecting.

Quelle: https://blog.docker.com/feed/
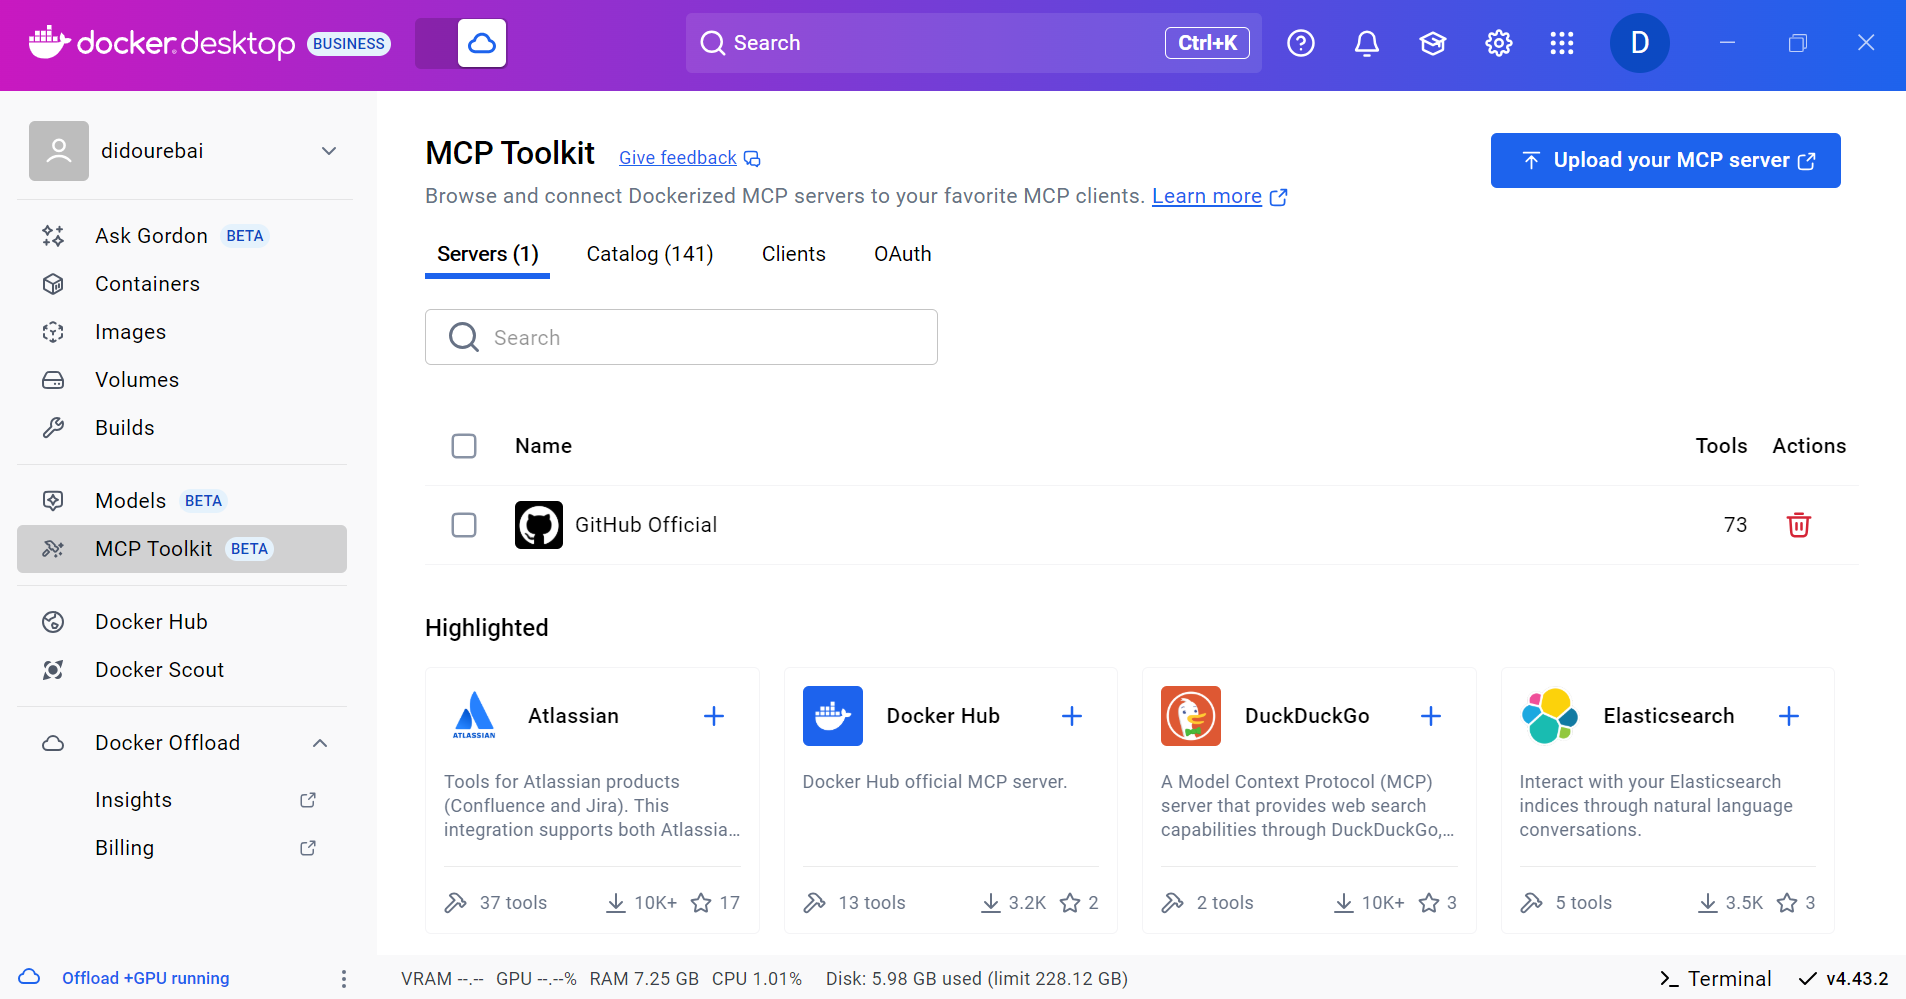
Hard Questions: What You Should Really Be Asking Your Hardened Image Provider Before You Press the Buy Button

When evaluating hardened image providers, don’t just look for buzzwords like “zero-CVE” or “minimal.” True security in a dynamic environment demands a nuanced understanding of their process, their commitment, and their flexibility. For platform, DevOps, and SecOps teams, these are the critical questions that reveal whether a provider offers genuine security that enhances your workflow, or one that will ultimately create more problems than it solves.

1. Update and Patch Management: The Reality of “Continuously Secure”

How quickly can you update the images in response to newly disclosed critical and high-severity CVEs? What are your Service Level Agreements (SLAs) for this?

Why it matters: This directly impacts your exposure window. A slow patching process, regardless of how “hardened” the image initially is, leaves you vulnerable.

What does your rebuild process look like (not just emergency patches)?

Why it matters: Each release of software you go through costs money, toil and introduces risk. So if you receive a nightly update and deploy every day for no reason then your increasing cost and risk. Instead, you want an intelligent approach to rebuilds. Your vendor should catalog all packages, monitor for CVES and fixes, and only when necessary. The rebuild should utilize an intelligent, event-driven systematic approach.

What is your process for notifying us of updates and changes? How can we consume these updates (e.g., through an API, a registry feed, direct notifications)?

Why it matters: You need an efficient way to integrate updates into your automated pipelines, not manual checks. 

2. The Modification Process: Unpacking “Flexibility”

This section dives deep into how the provider handles the “snowflake” reality. It’s not enough to say “we’re flexible”; you need to understand the mechanics and implications.

What is the precise technical process for us to modify your hardened images (e.g., through a Dockerfile, a proprietary tool, specific build arguments)? Describe the steps involved.

Why it matters: Understand the actual workflow. Is it standard and open, or does it require learning a new, potentially restrictive ecosystem? Does it support multi-stage builds effectively for final image reduction?

How do you ensure that our modifications don’t inadvertently compromise the underlying hardening? What automated checks or gates are in place to validate these changes?

Why it matters: The value of the base image is lost if adding one package nullifies its security. Look for integrated security scanning, policy enforcement, and best practice checks (e.g., non-root user enforcement, no hardcoded secrets) after your modifications.

What mechanisms do you provide to verify that our specific modifications work as intended and haven’t introduced functional regressions? (e.g., integration with our testing frameworks, pre-configured health checks)?

Why it matters: Security should not break functionality. How does the provider’s ecosystem facilitate confidence in modified images before deployment? Are there test suites or validation tools available?

What is your typical turnaround time for a custom modification request or for applying a patch to a custom-modified image (if you handle the modifications)?

Why it matters: If you’re relying on the vendor to perform modifications, their speed directly impacts your agility. Slow turnaround can negate the benefits of automation.

For large organizations requiring many unique modifications across a diverse application portfolio, how do you manage and scale the modification process?

Why it matters: Is their system built for enterprise complexity? How do they handle versioning, conflict resolution, and consistent application of patches across potentially hundreds or thousands of modified images? Do they offer centralized management or just point solutions?

Do your modifications allow for easy SBOM generation and vulnerability scanning of the final modified image, including our additions?

Why it matters: Full transparency is crucial for your compliance and incident response. The SBOM should reflect everything in the image.

3. Supply Chain Security and Transparency: Trust, But Verify

What is the full provenance of your images? Can you provide verifiable Software Bill of Materials (SBOMs) that include all dependencies, including transitive ones?

Why it matters: You need to know exactly what’s inside the image and where it came from, from source to binary, at every layer.

What standards do you adhere to for supply chain security (e.g., SLSA, reproducible builds)? How can you demonstrate this?

Why it matters: Beyond just CVEs, how secure is the process by which the image is built and delivered?

How do you handle third-party components and open-source licenses within your images?

Why it matters: Compliance isn’t just about security; it’s about legal adherence.

What is your process for handling non-exploitable vulnerabilities and using VEX to clarify what vulnerabilities are reachable? Do you provide this information transparently?

Why it matters: You don’t want to chase every reported CVE if it’s not actually exploitable in the image’s context.

4. Support, Integration, and Ecosystem Compatibility: Beyond the Image Itself

How do your hardened images integrate with popular DevOps tools and CI/CD platforms (e.g., Kubernetes, Jenkins, GitLab CI, Argo CD)?

Why it matters: A secure image that doesn’t fit your existing toolchain creates friction and resistance.

What level of support do you provide for issues related to the hardened image itself versus issues related to our application running on it?

Why it matters: Clear lines of responsibility for troubleshooting can save significant time during incidents.

Do you offer dedicated support channels or expertise for security teams?

Why it matters: Security teams have specific needs and often require direct access to security experts.

What is your pricing model? Does it scale effectively with our usage and organizational growth, considering potential customization costs?

Why it matters: Understand the total cost of ownership beyond the sticker price, factoring in the complexity of managing many modified images.

By asking these hard questions, platform, DevOps, and SecOps teams can move beyond marketing claims and evaluate hardened image providers based on the real-world demands of secure, agile software delivery.

Quelle: https://blog.docker.com/feed/
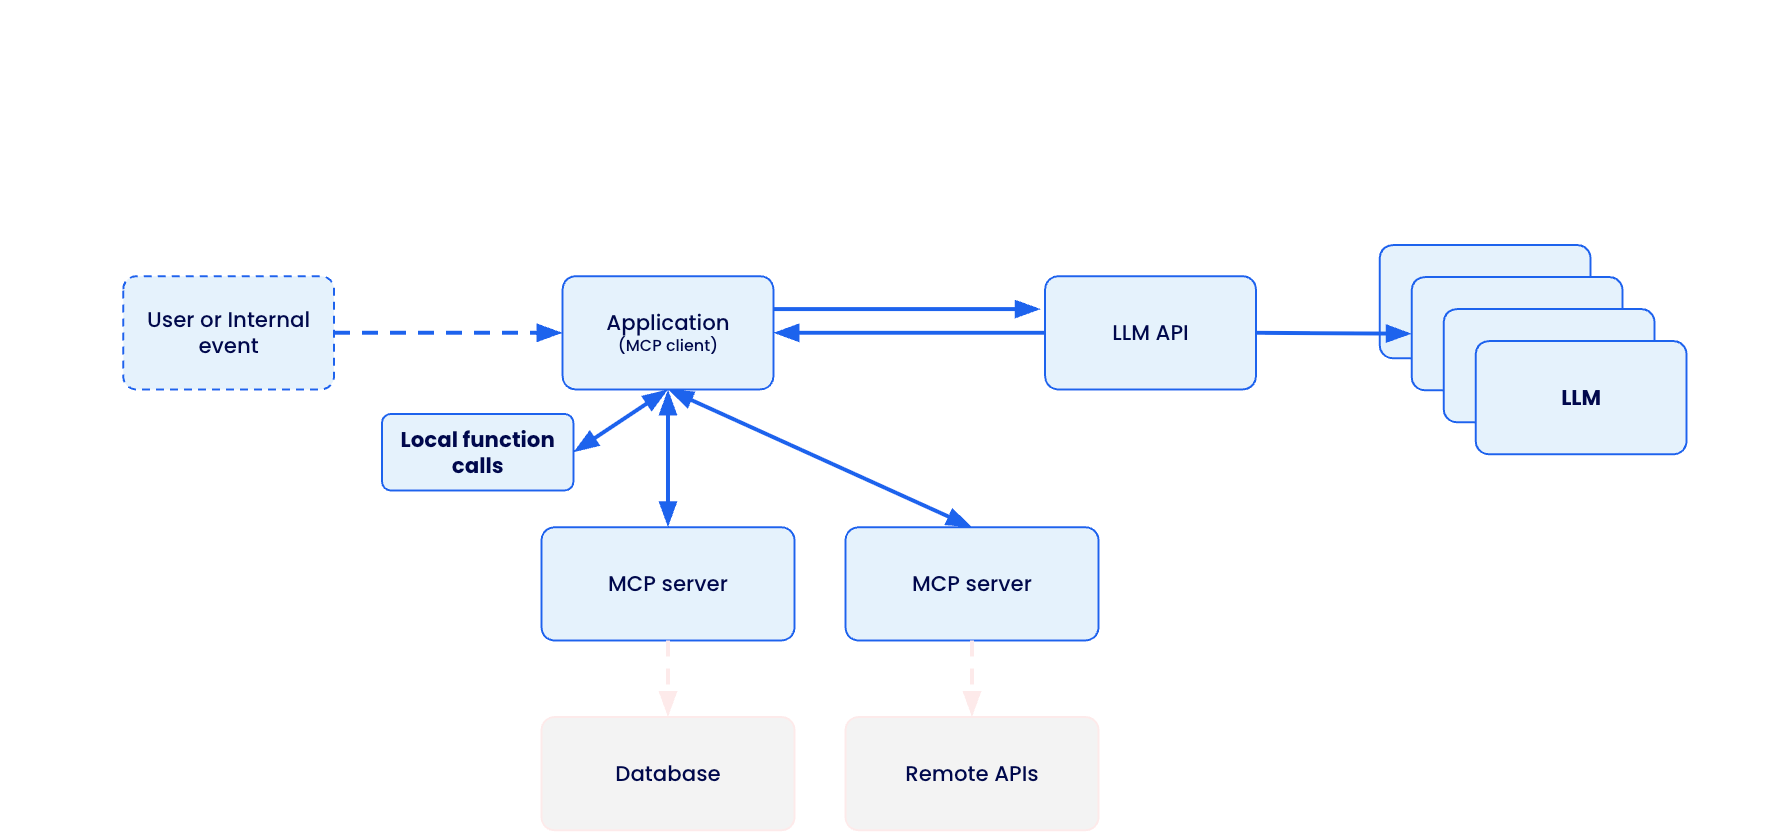
How Docker MCP Toolkit Works with VS Code Copilot Agent Mode

In the rapidly evolving landscape of software development, integrating modern AI tools is essential to boosting productivity and enhancing the developer experience. One such advancement is the integration of Docker’s Model Context Protocol (MCP) Toolkit with Visual Studio Code’s GitHub Copilot Agent Mode.

This powerful combination transforms how developers interact with containerized applications, enabling autonomous coding workflows that seamlessly manage Docker environments with enhanced security, improved discoverability, and increased automation.As a Docker Captain, I’ve worked extensively with containerized development workflows. In this article, we’ll guide you through setting up and using the Docker MCP Toolkit with Copilot Agent Mode in VS Code, providing practical steps and examples.

What Is the Docker MCP Toolkit?

The Docker MCP Toolkit enables hosting and managing MCP servers—modular tool endpoints that run inside Docker containers. These servers expose APIs for specific development tasks, such as retrieving GitHub issue data or automating continuous integration (CI) workflows.

These tools are designed with the following goals:

Security: Run in isolated containers with strict access controls.

Reusability: Modular components can be reused across multiple projects.

Discoverability: Automatically discoverable by tools like GitHub Copilot.

Each MCP server adheres to a standard request-response specification, ensuring predictable and safe interactions with AI agents.

Prerequisites

Make sure you have the following before you begin:

Docker Desktop v4.43 (latest recommended)

Visual Studio Code

GitHub Copilot extension for VS Code

GitHub Copilot with Chat and Agent Mode enabled

GitHub Personal Access Token (optional, for GitHub-related tools)

Step-by-Step Integration Guide

1. Enable the MCP Toolkit in Docker Desktop

MCP Toolkit is now integrated with Docker Desktop. Open Docker Desktop and find it by navigating to the MCP Toolkit tab.

Figure 1: MCP Toolkit is now integrated with Docker Desktop  

2. Start an MCP Server

You can launch an MCP server either from Docker Desktop’s UI or using the CLI. One common choice is the GitHub Official MCP server, which exposes tools for interacting with GitHub repositories. We will open Docker Desktop and start it from the user interface. 

Open Docker Desktop > MCP Toolkit.

Select GitHub Official from the list.

Configure it with your GitHub token and start the server.

Figure 2: Docker Desktop showing the configuration of the GitHub Official MCP server

3. Start the MCP Gateway

Open Docker Desktop > MCP Toolkit (BETA).

Within the MCP Toolkit, locate the Clients tab.

Scroll to Other MCP Clients and copy the suggested command:

docker mcp gateway run

Figure 4: Docker Desktop showing how to enable MCP Gateway

This command initializes the gateway and makes your MCP server tools discoverable to clients like VS Code.

4. Connect MCP to Visual Studio Code

In VS Code, open the Command Palette and press Ctrl + Shift + P (or Cmd + Shift + P on macOS)

Select “Add MCP Server” and paste the gateway command.

Figure 5: VS Code command displaying how to add an MCP Server

Paste the previously copied docker mcp gateway run command when prompted.

Figure 6: VS Code displaying the Docker MCP gateway run command

This establishes a connection between your VS Code Copilot Agent Mode and the Docker MCP Toolkit (running through Docker Desktop). Once applied to your workspace, Copilot will register approximately 30 MCP tools, all running in containers.

5. Configure and Use Copilot Agent Mode

To configure Copilot Agent Mode, we have two options available:

Option 1: Enable via Copilot Chat Panel (GUI)

Ensure GitHub Copilot is installed and signed in.

Open the Copilot Chat panel, either through Copilot Labs or GitHub Copilot Chat.

Enable Agent Mode:

Use the dropdown or toggle in the chat panel to activate Agent Mode.

This mode allows Copilot to access external tools like those provided by the MCP Toolkit and intelligently reason over them.

Figure 7: GitHub Copilot activating Agent mode

Option 2: Enable via mcp CLI Commands (Manual Setup)

You can also configure Agent Mode by running mcp CLI commands directly in a terminal. This is useful for scripting, headless environments, or if you prefer a command-line setup.

Run the following command to start the gateway manually:

docker mcp gateway run

This procedure will facilitate the exposure of the gateway, thereby allowing Copilot in Visual Studio Code to establish a connection.

In Visual Studio Code, access the mcp.json configuration file to add the running gateway or confirm it is set to use the same endpoint. Restart Visual Studio Code or refresh the Copilot Agent connection to apply the changes.

6. Explore and Test

Try prompts like:

– “List open issues in this GitHub repo”

– “Trigger the CI pipeline for the latest commit”

Copilot routes these tasks to the correct containerized tool and returns results automatically.

Conclusion

Integrating the Docker MCP Toolkit with Copilot Agent Mode in Visual Studio Code offers developers a scalable, modular, and secure method for automating development tasks using containerized AI tools. This workflow represents a significant advancement in creating intelligent, context-aware development environments that simplify repetitive tasks and enhance efficiency.

Learn more

Review the official Docker MCP Toolkit Documentation

Review the capabilities and setup for GitHub Copilot in VS Code

Quelle: https://blog.docker.com/feed/

MCP Horror Stories: The Security Issues Threatening AI Infrastructure

This is issue 1 of a new series – MCP Horror Stories – where we will examine critical security issues and vulnerabilities in the Model Context Protocol (MCP) ecosystem and how Docker MCP Toolkit provides enterprise-grade protection against these threats.

What is MCP?

The Model Context Protocol (MCP) is a standardized interface that enables AI agents to interact with external tools, databases, and services. Launched by Anthropic in November 2024, MCP has achieved remarkable adoption, with thousands of MCP server repositories emerging on GitHub. Major technology giants, including Microsoft, OpenAI, Google, and Amazon, have officially integrated MCP support into their platforms, with development tools companies like Block, Replit, Sourcegraph, and Zed also adopting the protocol. 

Think of MCP as the plumbing that allows ChatGPT, Claude, or any AI agent to read your emails, update databases, manage files, or interact with APIs. Instead of building custom integrations for every tool, developers can use one protocol to connect everything. 

How does MCP work?

MCP creates a standardized bridge between AI applications and external services through a client-server architecture. 

The Model Context Protocol (MCP) creates a standardized bridge between AI applications and external services through a client-server architecture. 

When a user submits a prompt to their AI assistant (like Claude Desktop, VS Code, or Cursor), the MCP client actually sends the tool descriptions to the LLM, which does analysis and determines which, if any, tools should be called. The MCP host executes these decisions by routing calls to the appropriate MCP servers – whether that’s querying a database for customer information or calling remote APIs for real-time data. Each MCP server acts as a standardized gateway to its respective data source, translating between the universal MCP protocol and the specific APIs or database formats underneath. 

Caption: Model Context Protocol client-server architecture enabling standardized AI integration across databases, APIs, and local functions

The overall MCP architecture enables powerful AI workflows where a single conversation can seamlessly integrate multiple services – for example, an AI agent could analyze data from a database, create a GitHub repository with the results, send a Slack notification to the team, and deploy the solution to Kubernetes, all through standardized MCP interactions. However, this connectivity also introduces significant security risks, as malicious MCP servers could potentially compromise AI clients, steal credentials, or manipulate AI agents into performing unauthorized actions.

The Model Context Protocol (MCP) was supposed to be the “USB-C for AI applications” – a universal standard that would let AI agents safely connect to any tool or service. Instead, it’s become a security nightmare that’s putting organizations at risk of data breaches, system compromises, and supply chain attacks.

The promise is compelling: Write once, connect everywhere. The reality is terrifying: A protocol designed for convenience, not security.

Caption: comic depicting MCP convenience and potential security risk

MCP Security Issues by the Numbers

The scale of security issues with MCP isn’t speculation – it’s backed by a comprehensive analysis of thousands of MCP servers revealing systematic flaws across six critical attack vectors:

OAuth Discovery Vulnerabilities

Command Injection and Code Execution

Unrestricted Network Access

File System Exposure

Tool Poisoning Attacks

Secret Exposure and Credential Theft

1. OAuth Discovery Vulnerabilities

What it is: Malicious servers can inject arbitrary commands through OAuth authorisation endpoints, turning legitimate authentication flows into remote code execution vectors.

The numbers: Security researchers analyzing the MCP ecosystem found that OAuth-related vulnerability represent the most severe attack class, with command injection flaws affecting 43% of analyzed servers. The mcp-remote package alone has been downloaded over 558,846 times, making OAuth vulnerabilities a supply chain attack affecting hundreds of thousands of developer environments.

The horror story: CVE-2025-6514 demonstrates exactly how devastating this vulnerability class can be – turning a trusted OAuth proxy into a remote code execution nightmare that compromises nearly half a million developer environments.

Strategy for mitigation: Watch out for MCP servers that use third-party OAuth tools like mcp-remote, have non-https endpoints, or need complex shell commands. Instead, pick servers with built-in OAuth support and never run OAuth proxies that execute shell commands.

2. Command Injection and Code Execution

What it is: MCP servers can execute arbitrary system commands on host machines through inadequate input validation and unsafe command construction.

The numbers: Backslash Security’s analysis of thousands of publicly available MCP servers uncovered “dozens of instances” where servers allow arbitrary command execution. Independent assessments confirm 43% of servers suffer from command injection flaws – the exact vulnerability enabling remote code execution.

The horror story: These laboratory findings translate directly to real-world exploitation, as demonstrated in our upcoming coverage of container breakout attacks targeting AI development environments.

Strategy for mitigation: Avoid MCP servers that don’t validate user input, build shell commands from user data, or use eval() and exec() functions. Always read the server code before installing and running MCP servers in containers.

3. Unrestricted Network Access

What it is: MCP servers with unrestricted internet connectivity can exfiltrate sensitive data, download malicious payloads, or communicate with command-and-control infrastructure.

The numbers: Academic research published on arXiv found that 33% of analyzed MCP servers allow unrestricted URL fetches, creating direct pathways for data theft and external communication. This represents hundreds of thousands of potentially compromised AI integrations with uncontrolled network access.

The horror story: The Network Exfiltration Campaign shows how this seemingly innocent capability becomes a highway for stealing corporate data and intellectual property.

Strategy for mitigation: Skip MCP servers that don’t explain their network needs or want broad internet access without reason. Use MCP tools with network allow-lists and monitor what connections your servers make.

4. File System Exposure

What it is: Inadequate path validation allows MCP servers to access files outside their intended directories, potentially exposing sensitive documents, credentials, and system configurations.

The numbers: The same arXiv security study found that 22% of servers exhibit file leakage vulnerabilities that allow access to files outside intended directories. Combined with the 66% of servers showing poor MCP security practices, this creates a massive attack surface for data theft.

The horror story: The GitHub MCP Data Heist analysis reveals how these file access vulnerabilities enable unauthorized access to private repositories and sensitive development assets.

Strategy for mitigation: Avoid MCP servers that want access beyond their work folder. Don’t use tools that skip file path checks or lack protection against directory attacks. Stay away from servers running with too many privileges. Stay secure by using containerized MCP servers with limited file access. Set up monitoring for file access.

5. Tool Poisoning Attack

What it is: Malicious MCP servers can manipulate AI agents by providing false tool descriptions or poisoned responses that trick AI systems into performing unauthorized actions.

The numbers: Academic research identified 5.5% of servers exhibiting MCP-specific tool poisoning attacks, representing a new class of AI-targeted vulnerabilities not seen in traditional software security.

The horror story:  The Tenable Website Attack demonstrates how tool poisoning, combined with localhost exploitation, turns users’ own development tools against them.

Strategy for mitigation: Carefully review the MCP server documentation and tool descriptions before installation. Monitor AI agent behavior for unexpected actions. Use MCP implementations with comprehensive logging to detect suspicious tool responses.

6. Secret Exposure and Credential Theft

What it is: MCP deployments often expose API keys, passwords, and sensitive credentials through environment variables, process lists, and inadequate secret management.

The numbers: Traditional MCP deployments systematically leak credentials, with plaintext secrets visible in process lists and logs across thousands of installations. The comprehensive security analysis found 66% of servers exhibiting code smells, indicating poor MCP security practices, compounding this credential exposure problem.

The horror story: The Secret Harvesting Operation reveals how attackers systematically collect API keys and credentials from compromised MCP environments, enabling widespread account takeovers.

Strategy for mitigation: Avoid MCP servers that need credentials as environment variables. Don’t use tools that log or show sensitive info. Stay away from servers without secure credential storage. Be careful if docs mention storing credentials as plain text. Protect your credentials by using secure secret management systems.

How Docker MCP Tools Address MCP Security Issues

While identifying vulnerabilities is important, the real solution lies in choosing secure-by-design MCP implementations. Docker MCP Catalog, Toolkit and Gateway represent a fundamental shift toward making security the default path for MCP development.

Security-first Architecture

MCP Gateway serves as the secure communication layer between AI clients and MCP servers. Acting as an intelligent proxy, the MCP Gateway intercepts all tool calls, applies security policies, and provides comprehensive monitoring. This centralized security enforcement point enables features like network filtering, secret scanning, resource limits, and real-time threat detection without requiring changes to individual MCP servers.

Secure Distribution through Docker MCP Catalog provides cryptographically signed, immutable images that eliminate supply chain attacks targeting package managers like npm.

Container Isolation ensures every MCP server runs in an isolated container, preventing host system compromise even if the server is malicious. Unlike npm-based MCP servers that execute directly on your machine, Docker MCP servers can’t access your filesystem or network without explicit permission.

Network Controls with built-in allowlisting ensure MCP servers only communicate with approved destinations, preventing data exfiltration and unauthorized communication.

Secret Management via Docker Desktop’s secure secret store replaces vulnerable environment variable patterns, keeping credentials encrypted and never exposed to MCP servers directly.

Systematic Vulnerability Elimination

Docker MCP Toolkit systematically eliminates each vulnerability class through architectural design.

OAuth Vulnerabilities -> Native OAuth Integration

OAuth vulnerabilities disappear entirely through native OAuth handling in Docker Desktop, eliminating vulnerable proxy patterns without requiring additional tools. 

# No vulnerable mcp-remote needed
docker mcp oauth ls
github | not authorized
gdrive | not authorized

# Secure OAuth through Docker Desktop
docker mcp oauth authorize github
# Opens browser securely via Docker's OAuth flow

docker mcp oauth ls
github | authorized
gdrive | not authorized

Command Injection -> Container Isolation

Command injection attacks are contained within container boundaries through isolation, preventing any host system access even when servers are compromised. 

# Every MCP server runs with security controls
docker mcp gateway run
# Containers launched with: –security-opt no-new-privileges –cpus 1 –memory 2Gb

Network Attacks -> Zero-Trust Networking

Network attacks are blocked through zero-trust networking with –block-network flags and real-time monitoring that detects suspicious patterns. 

# Maximum security configuration
docker mcp gateway run
–verify-signatures
–block-network
–cpus 1
–memory 1Gb

Tool Poisoning -> Comprehensive Logging

Tool poisoning becomes visible through complete interaction logging with –log-calls, enabling automatic blocking of suspicious responses. 

# Enable comprehensive tool monitoring
docker mcp gateway run –log-calls –verbose
# Logs all tool calls, responses, and detects suspicious patterns

Secret Exposure -> Secure Secret Management

Secret exposure is eliminated through secure secret management combined with active scanning via –block-secrets that prevents credential leakage.

# Secure secret storage
docker mcp secret set GITHUB_TOKEN=ghp_your_token
docker mcp secret ls
# Secrets never exposed as environment variables

# Block secret exfiltration
docker mcp gateway run –block-secrets
# Scans tool responses for leaked credentials

Enterprise-grade Protection

For production environments, Docker MCP Gateway provides a maximum security configuration that combines all protection mechanisms:

# Production hardened setup
docker mcp gateway run
–verify-signatures # Cryptographic image verification
–block-network # Zero-trust networking
–block-secrets # Secret scanning protection
–cpus 1 # Resource limits
–memory 1Gb # Memory constraints
–log-calls # Comprehensive logging
–verbose # Full audit trail

This configuration provides:

Supply Chain Security: –verify-signatures ensures only cryptographically verified images run

Network Isolation: –block-network creates L7 proxies allowing only approved destinations

Secret Protection: –block-secrets scans all tool responses for credential leakage

Resource Controls: CPU and memory limits prevent resource exhaustion attacks

Full Observability: Complete logging and monitoring of all tool interactions

Security Aspect

Traditional MCP

Docker MCP Toolkit

Execution Model

Direct host execution via npx/mcp-remote

Containerized isolation

OAuth Handling

Vulnerable proxy with shell execution

Native OAuth in Docker Desktop

Secret Management

Environment variables

Docker Desktop secure store

Network Access

Unrestricted host networking

L7 proxy with allowlisted destinations

Resource Controls

None

CPU/memory limits, container isolation

Supply Chain

npm packages (can be hijacked)

Cryptographically signed Docker images

Monitoring

No visibility

Comprehensive logging with –log-calls

Threat Detection

None

Real-time secret scanning, anomaly detection

The result is a security-first MCP ecosystem where developers can safely explore AI integrations without compromising their development environments. Organizations can deploy AI tools confidently, knowing that enterprise-grade security is the default, not an afterthought.

Stay tuned for upcoming issues in this series:

1. OAuth Discovery Vulnerabilities → JFrog Supply Chain Attack

Malicious authorization endpoints enable remote code execution

Affects 437,000+ downloads of mcp-remote through CVE-2025-6514

2. Prompt Injection Attacks → GitHub MCP Data Heist

AI agents manipulated into accessing unauthorized repositories

Official GitHub MCP Server (14,000+ stars) weaponized against private repos

3. Drive-by Localhost Exploitation → Tenable Website Attack

Malicious websites compromise local development environments

MCP Inspector (38,000+ weekly downloads) becomes attack vector

4. Tool Poisoning + Container Escape → AI Agent Container Breakout

Containerized MCP environments breached through combined attacks

Isolation failures in AI development environments

5. Unrestricted Network Access → Network Exfiltration Campaign

33% of MCP tools allow unrestricted URL fetches

Creates pathways for data theft and external communication

6. Exposed Environment Variables → Secret Harvesting Operation

Plaintext credentials visible in process lists and logs

Traditional MCP deployments leak API keys and passwords

In the next issue of this series, we will dive deep into CVE-2025-6514 – the supply chain attack that turned a trusted OAuth proxy into a remote code execution nightmare, compromising nearly half a million developer environments. 

Learn more

Explore the MCP Catalog: Visit the MCP Catalog to discover MCP servers that solve your specific needs securely.

Use and test hundreds of MCP Servers: Download Docker Desktop to download and use any MCP server in our catalog with your favorite clients: Gordon, Claude, Cursor, VSCode, etc

Submit your server: Join the movement toward secure AI tool distribution. Check our submission guidelines for more.

Follow our progress: Star our repository and watch for updates on the MCP Gateway release and remote server capabilities.

Quelle: https://blog.docker.com/feed/





