MCP Security: A Developer’s Guide

Since its release by Anthropic in November 2024, Model Context Protocol (MCP) has gained massive adoption and is quickly becoming the connective tissue between AI agents and the tools, APIs, and data they act on. 

With just a few lines of configuration, an agent can search code, open tickets, query SaaS systems, or even deploy infrastructure. That kind of flexibility is powerful but it also introduces new security challenges. In fact, security researchers analyzing the MCP ecosystem found command injection flaws affecting 43% of analyzed servers. A single misconfigured or malicious server can exfiltrate secrets, trigger unsafe actions, or quietly change how an agent behaves. 

This guide is for developers and platform teams building with agents. We’ll unpack what makes MCP workflows uniquely risky for AI infrastructure, highlight common missteps like prompt injection or shadow tooling, and show how secure defaults, like containerized MCP servers and policy-based gateways, can help you govern every tool call without slowing your AI roadmap.

What is MCP security?

Model Context Protocol is a standardized interface that enables AI agents to interact with external tools, databases, and services. MCP security refers to the controls and risks that govern how agents discover, connect to, and execute MCP servers. These security risks span across the entire development lifecycle and involve:

Supply chain: how servers are packaged, signed, versioned, and approved.

Runtime isolation: how they’re executed on the host vs. in containers, with CPU/memory/network limits.

Brokered access: how calls are mediated, logged, blocked, or transformed in real time.

Client trust: which tools a given IDE/agent is allowed to see and use.

Why does MCP security matter?

Securing MCP workflows has become more important than ever because AI agents blur the line between “code” and “runtime.” A prompt or tool description can change what your system is capable of without a code release. 

This means that security practices have to move up a layer, from static analysis to policy over agent‑tool interactions. Docker codifies that policy in a gateway and makes secure defaults practical for everyday developers.

Docker’s approach is to make MCP both easy and safe through containerized execution, a policy‑enforcing MCP Gateway, and a curated MCP Catalog & Toolkit that helps teams standardize what agents can do. If you’re building with agents, this guide will help you understand the risks, why traditional tools fall short, and how Docker reduces blast radius without slowing your AI roadmap.

Understanding MCP security risks

While MCP risks can show up in various ways across the dev lifecycle, there are specific categories they typically fall into. The section below highlights how these risks surface in real workflows, their impact, and practical guardrails that mitigate without slowing teams down. 

Misconfigurations & weak defaults

Running servers directly on the host with broad privileges or a persistent state.

Unrestricted network egress from tools to the public internet.

Unvetted catalogs/registries in client configs, exposing agents to unknown tools.

No audit trail for tool calls-hard to investigate or respond.

Impact: Lateral movement, data exfiltration, and irreproducible behavior.

Mitigation: Always follow MCP server best practices such as leveraging containerization, applying resource and network limits, maintaining an allowlist of approved tools, and capturing call logs centrally.

Malicious or compromised servers (supply chain)

Typosquatting/poisoned images or unsigned builds.

Hidden side effects or altered tool metadata that nudges agents into risky actions.

Impact: Covert behavior change, credential theft, persistent access.

Mitigation: Require signature verification, pin versions/digests, and pull from curated sources such as the MCP Catalog & Toolkit.

Secret management failures

Plaintext credentials in environment variables, prompts, or tool arguments.

Leakage via tool outputs or model completions.

Impact: Account takeover, data loss.

Mitigation: Use managed secrets, minimize prompt exposure, and redact or block sensitive values at the broker.

Prompt injection & tool poisoning

Prompt injection: hostile content instructs the model to exfiltrate data or call dangerous tools.

Tool poisoning/shadowing: misleading tool descriptions or unexpected defaults that steer the agent.

Impact: Agents do the wrong thing, confidently.

Mitigation: Strict tool allowlists, pre/post‑call interceptors, and output filtering at the gateway. Docker’s MCP Gateway provides active security capabilities (signature checks, call logging, secret and network controls, interceptors).

What makes MCP security challenging?

Dynamic & non‑deterministic behavior: the same prompt may lead to different tool calls.

Instruction vs. data ambiguity: LLMs can treat content (including tool docs) as instructions.

Growing, shifting attack surface: every new tool expands what the agent can do instantly.

Traditional AppSec gaps: Static analysis tools don’t see agentic tool calls or MCP semantics; you need mediation between agents and tools, not just better prompts.

Implication for developers: You need a guardrail that lives at the agent–tool boundary, verifying what runs, brokering what’s allowed, and recording what happened.

How to prevent and mitigate MCP server security concerns

Use this practitioner checklist to raise the floor:

Containerize every MCP serverRun servers in containers (not on the host) with CPU/memory caps and a read‑only filesystem where possible. Treat each server as untrusted code with the least privilege necessary.Why it helps: limits blast radius and makes behavior reproducible.

Centralize enforcement at a gateway (broker)Place a policy‑enforcing gateway between clients (IDE/agent) and servers. Use it to:

Verify signatures before running servers.

Maintain a tool allowlist (only approved servers are discoverable).

Apply network egress controls and secret redaction.

Log requests/responses for audit and incident response.

Govern secrets end‑to‑endStore secrets in a managed system; avoid .env files. Prefer short‑lived tokens. Sanitize prompts and tool outputs to reduce exposure.

Defend the prompt layerUse pre‑call interceptors (argument/type checks, safety classifiers) and post‑call interceptors (redaction, PII scrub). Combine with strict tool scoping to reduce prompt‑injection blast radius.

Harden the supply chainPull servers from curated sources (e.g., MCP Catalog & Toolkit), require signatures, and pin to immutable versions.

Monitor and rehearseAlert on anomalous tool sequences (e.g., sudden credential access), and run tabletop exercises to rotate tokens and revoke access.

How Docker makes MCP security practical

Turning MCP security from theory into practice means putting guardrails where agents meet tools and making trusted servers easy to adopt for agentic workflows. Docker’s MCP stack does both: Docker Gateway enforces policy and observability on every call, while the Docker MCP Catalog & Toolkit curates, verifies, and versions the servers your team can safely use.

Docker MCP Gateway: Your enforcement point

The gateway sits between clients and servers to provide verification, policy, and observability for every tool call. It supports active security measures like signature verification, call logging, secret and network controls, and pre/post-interceptors so you can block or transform risky actions before they reach your systems. 

Learn more in Docker MCP Gateway: Unified, Secure Infrastructure for Agentic AI and the Gateway Active Security documentation.

Docker MCP Catalog & Toolkit: Curation and convenience

Use the MCP Catalog & Toolkit to standardize the servers your organization trusts. The catalog helps reduce supply‑chain risk (publisher verification, versioning, provenance) and makes it straightforward for developers to pull approved tools into their workflow. With a growing selection of 150+ curated MCP servers, MCP Catalog is a safe and easy way to get started with MCP.

Looking for a broader view of how Docker helps with AI development? Check out Docker for AI.

Putting it all Together: A practical flow

Choose servers from the Catalog and pin them by digest.

Register servers with the Gateway so clients only see approved tooling.

Enable active security: verify signatures, log all calls, redact/deny secrets, and restrict egress.

Add pre/post interceptors: validate arguments (before), redact/normalize outputs (after).

Monitor and tune: review call logs, alert on anomalies, rotate secrets, and update allowlists as new tools are introduced.

Conclusion

MCP unlocks powerful agentic workflows but also introduces new classes of risk, from prompt injection to tool poisoning and supply‑chain tampering. MCP security isn’t just better prompts; it’s secure packaging, verified distribution, and a brokered runtime with policy.

Key takeaways

Treat MCP as a governed toolchain, not just an SDK.

Put a policy gateway between agents and tools to verify, mediate, and observe.

Pull servers from the MCP Catalog & Toolkit and pin versions/digests.

Use active security features such as signature checks, interceptors, logging, and secret/network controls to reduce blast radius.

Learn more

Browse the MCP Catalog: Discover 200+ containerized, security-hardened MCP servers

Download the MCP Toolkit in Docker Desktop: Get immediate access to secure credential management and container isolation

Submit Your Server: Help build the secure, containerized MCP ecosystem. Check our submission guidelines for more.

Follow Our Progress: Star our repository for the latest security updates and threat intelligence
Quelle: https://blog.docker.com/feed/
The Nine Rules of AI PoC Success: How to Build Demos That Actually Ship

That study claiming “95% of AI POCs fail” has been making the rounds. It’s clickbait nonsense, and frankly, it’s not helping anyone. The real number? Nobody knows, because nobody’s tracking it properly. But here’s what I do know after years of watching teams build AI systems: the study masks a much more important problem.

Teams are confused about how to design POCs that survive beyond the demo stage. There is no playbook.

Most AI POCs die because they were designed to die. They’re built as disposable demos, optimized for executive presentations rather than production reality. They burn through cloud credits, rely on perfect conditions and perfectly structured data, and quickly collapse when real users start to touch them. If they don’t collapse then, often under scale they collapse when the design problems emerge under strain, leading to more serious failure.

But it doesn’t have to be this way. 

After watching hundreds of AI projects at Docker and beyond, I’ve seen the patterns that separate the 5% that make it from the 95% that don’t. Here’s the playbook I wish every platform and MLOps team had from day one.

The New Foundation: Remocal Workflows

Before we dive into the rules, let’s talk about the biggest shift in how successful teams approach AI development: remocal workflows (remote + local).

Running AI locally isn’t just about saving money—though it absolutely does that. It’s about maintaining developer velocity and avoiding the demo theater trap. Here’s how the best teams structure their work:

Test locally on laptops for fast iteration. No waiting for cloud resources, no surprise bills, no network latency killing your flow. The nature of building with AI should be making the process feel very interactive.

Burst to remote resources for scale testing, production-like validation, or when you actually need those H100s. It should feel easy to move AI workloads around.

Keep costs transparent from day one. You know exactly what each experiment costs because you’re only paying for remote compute when you choose to.

POCs that incorporate this pattern from day zero avoid both runaway bills and the classic “it worked in the demo” disaster. They’re grounded in reality because they’re built with production constraints baked in.

The Nine Rules of POC Survival

1. Start Small, Stay Small

Your first instinct is wrong. You don’t need the biggest model, the complete dataset, or every possible feature. Bite-sized everything: models that fit on a laptop, datasets you can actually inspect, and scope narrow enough that you can explain the value in one sentence.

Early wins compound trust. A small thing that works beats a big thing that might work.

2. Design for Production from Day Zero

Logging, monitoring, versioning, and guardrails aren’t “nice to haves” you add later. They’re the foundation that determines whether your POC can grow up to be a real system.

If your POC doesn’t have structured logging and basic metrics – observability –  from the first commit, you’re building a disposable demo, not a prototype of a production system.

3. Optimize for Repeatability and Model Improvement, Not Novelty

Infrastructure should be templated. Prompt testing should be in CI/CD. Model comparisons should be apples-to-apples benchmarks, not “it felt better this time.” What’s more, POC designs can and should assume existing model families will continue to rapidly improve. That includes larger context windows, greater accuracy, lower latency and smaller resource consumption.

The sexiest part of AI isn’t the novel algorithm—it’s how we’re learning to frame problems in ways  that make AI more reliable at scale.

4. Think in Feedback Loops

This is the big one that separates amateur hour from production-ready systems. Separate your non-deterministic AI components from your deterministic business logic. Build in layers of control and validation. Domain knowledge is still your magic ingredient.

In a remocal setup, this becomes natural: your agent loops can run locally for fast iteration, while tool execution and heavy compute burst to remote resources only when needed. You get reliability from layered control, not from hoping your model has a good day.

5. Solve Pain, Not Impress

Anchor everything to measurable business pain. Real users with real problems they’re willing to pay to solve. If your POC’s main value proposition is “look how cool this is,” you’re building the wrong thing.

Kill the vanity demos that only look good in slideware. Build the boring solutions that save people actual time and money.

6. Embed Cost and Risk Awareness Early

Track unit economics from day one. What does each request cost? Each user? Each workflow?

Benchmark small vs. large models. Cloud vs. local execution. Know your trade-offs with real numbers, not hand-waving about “cloud scale.”

7. Make Ownership Clear

Who owns this thing when it breaks at 2 AM? What are the SLAs? Who’s responsible for retraining the model? Who pays for the compute?

Don’t let POCs drift in the organizational void between research labs and operations teams. Assign owners, responsibilities, and lifecycle management from day one.

8. Control Costs Upfront

Transparent cost per request, user, and workflow. Hard budget caps and kill switches. No surprises in the monthly cloud bill.

Remocal workflows make this natural: you default to local execution and only burst remote when you consciously choose to spend money. Your costs are predictable because they’re intentional.

9. Involve Users From Day Zero

Co-design with real users, not executives who saw a ChatGPT demo and want “AI for everything.” Measure adoption and time saved, not just accuracy scores.

The best AI POCs feel like natural extensions of existing workflows because they were built with the people who actually do the work.

Why This Actually Matters

Most failed AI POCs never had a chance. They were too big, too expensive, too disconnected from real problems, and too optimized for demo day rather than daily use.

By flipping the script—starting small, designing for production, involving real users, and building on remocal workflows—you dramatically increase your odds of building something that ships and scales.

The difference between a successful AI POC and a failed one isn’t the sophistication of the model. It’s the boring engineering decisions you make on day zero.

Stop treating AI POCs as disposable demos. Treat them as the first draft of a production system.

Jim Clark is Principal Engineer for AI at Docker, where he helps teams build AI systems that actually make it to production. He’s spent the last decade watching the gap between AI demos and AI products, and occasionally bridging it.

Quelle: https://blog.docker.com/feed/
From Hallucinations to Prompt Injection: Securing AI Workflows at Runtime

How developers are embedding runtime security to safely build with AI agents

Introduction: When AI Workflows Become Attack Surfaces

The AI tools we use today are powerful, but also unpredictable and exploitable.

You prompt an LLM and it generates a Dockerfile. It looks correct. A shell script? Reasonable. You run it in dev. Then something breaks: a volume is deleted. A credential leaks into a log. An outbound request hits a production API. Nothing in your CI pipeline flagged it, because the risk only became real at runtime.

This is the new reality of AI-native development: fast-moving code, uncertain behavior, and an expanding attack surface.

Hallucinations in LLM output are only part of the story. As developers build increasingly autonomous agentic tools, they’re also exposed to prompt injection, jailbreaks, and deliberate misuse of model outputs by adversaries. A malicious user, through a cleverly crafted input, can hijack an AI agent and cause it to modify files, exfiltrate secrets, or run unauthorized commands.

In one recent case, a developer ran an LLM-generated script that silently deleted a production database, an issue that went undetected until customer data was already lost. In another, an internal AI assistant was prompted to upload sensitive internal documents to an external file-sharing site, triggered entirely through user input.

These failures weren’t caught in static analysis, code review, or CI. They surfaced only when the code ran.

In this post, we’ll explore how developers are addressing both accidental failures and intentional threats by shifting runtime security into the development loop, embedding observability, policy enforcement, and threat detection directly into their workflows using Docker.

The Hidden Risks of AI-Generated Code

LLMs and AI agents are great at generating text, but they don’t always know what they’re doing. Whether you’re using GitHub Copilot, LangChain, or building with OpenAI APIs, your generated outputs might include:

Shell scripts that escalate privileges or misconfigure file systems

Dockerfiles that expose unnecessary ports or install outdated packages

Infra-as-code templates that connect to production services by default

Hardcoded credentials or tokens hidden deep in the output

Command sequences that behave differently depending on the context

The problem is compounded when teams start running autonomous agents, AI tools designed to take actions, not just suggest code. These agents can:

Execute file writes and deletions

Make outbound API calls

Spin up or destroy containers

Alter configuration state mid-execution

Execute dangerous database queries

These risks only surface at runtime, after your build has passed and your pipeline has shipped. And that’s a problem developers are increasingly solving inside the dev loop.

Why Runtime Security Belongs in the Developer Workflow

Traditional security tooling focuses on build-time checks, SAST, SCA, linters, compliance scanners. These are essential, but they don’t protect you from what AI-generated agents do at execution time.

Developers need runtime security that fits their workflow, not a blocker added later.

What runtime security enables:

Live detection of dangerous system calls or file access

Policy enforcement when an agent attempts unauthorized actions

Observability into AI-generated code behavior in real environments

Isolation of high-risk executions in containerized sandboxes

Why it matters:

Faster feedback loops: See issues before your CI/CD fails

Reduced incident risk: Catch privilege escalation, data exposure, or network calls early

Higher confidence: Ship LLM-generated code without guesswork

Secure experimentation: Enable safe iteration without slowing down teams

Developer ROI: Catching a misconfigured agent in dev avoids hours of triage and mitigates production risk and reputation risk; saving time, cost, and compliance exposure.

Building Safer AI Workflows with Docker

Docker provides the building blocks to develop, test, and secure modern agentic applications:

Docker Desktop gives you an isolated, local runtime for testing unsafe code

Docker Hardened Images. Secure, minimal, production-ready images

Docker Scout scans container images for vulnerabilities and misconfigurations

Runtime policy enforcement (with upcoming MCP Defender integration) provides live detection and guardrails while code executes

Step-by-Step: Safely Test AI-Generated Scripts

1. Run your agent or script in a hardened container

docker run –rm -it
–security-opt seccomp=default.json
–cap-drop=ALL
-v $(pwd):/workspace
python:3.11-slim

Applies syscall restrictions and drops unnecessary capabilities

Runs with no persistent volume changes

Enables safe, repeatable testing of LLM output

2. Scan the container with Docker Scout

docker scout cves my-agent:latest

Surfaces known CVEs and outdated dependencies

Detects unsafe base images or misconfigured package installs

Available both locally and inside CI/CD workflows

3. Add runtime policy (beta) to block unsafe behavior

scout policy add deny-external-network
–rule "deny outbound to *"

This would catch an AI agent that unknowingly makes an outbound request to an internal system, third-party API, or external data store.

Note: Runtime policy enforcement in Docker Scout is currently in development. CLI and behavior may change upon release.

Best Practices for Securing AI Agent Containers

Practice

Why it matters

Use slim, verified base images

Minimizes attack surface and dependency drift

Avoid downloading from unverified sources

Prevents LLMs from introducing shadow dependencies

Use .dockerignore and secrets management

Keeps secrets out of containers

Run containers with dropped capabilities

Limits impact of unexpected commands

Apply runtime seccomp profiles

Enforces syscall-level sandboxing

Log agent behavior for analysis

Builds observability into experimentation

Integrating Into Your Cloud-Native Workflow

Runtime security for AI tools isn’t just for local testing, it fits cleanly into cloud-native and CI/CD workflows too.

GitHub Actions Integration Example:

jobs:
security-scan:
runs-on: ubuntu-latest
steps:
– uses: actions/checkout@v3
– name: Build container
run: docker build -t my-agent:latest .
– name: Scan for CVEs
run: docker scout cves my-agent:latest

Works across environments:

Local dev via Docker Desktop

Remote CI/CD via GitHub Actions, GitLab, Jenkins

Kubernetes staging environments with policy enforcement and agent isolation

Cloud Development Environments (CDEs) with Docker + secure agent sandboxes

Dev teams using ephemeral workspaces and Docker containers in cloud IDEs or CDEs can now enforce the same policies across local and cloud environments.

Real-World Example: AI-Generated Infra Gone Wrong

A platform team uses an LLM agent to auto-generate Kubernetes deployment templates. A developer reviews the YAML and merges it. The agent-generated config opens an internal-only service to the internet via LoadBalancer. The CI pipeline passes. The deploy works. But a customer database is now exposed.

Had the developer run this template inside a containerized sandbox with outbound policy rules, the attempt to expose the service would have triggered an alert, and the policy would have prevented escalation.

Lesson: You can’t rely on static review alone. You need to see what AI-generated code does, not just what it looks like.

Why This Matters: Secure-by-Default for AI-Native Dev Teams

As LLM-powered tools evolve from suggestion to action, runtime safety becomes a baseline requirement, not an optional add-on.

The future of secure AI development starts in the inner loop, with runtime policies, observability, and smart defaults that don’t slow you down.

Docker’s platform gives you:

Developer-first workflows with built-in security

Runtime enforcement to catch AI mistakes early

Toolchain integration across build, test, deploy

Cloud-native flexibility across local dev, CI/CD, and CDEs

Whether you’re building AI-powered automations, agent-based platforms, or tools that generate infrastructure, you need a runtime layer that sees what AI can’t, and blocks what it shouldn’t do.

What’s Next

Runtime protection is moving left, into your dev environment. With Docker, developers can:

Run LLM-generated code in secure, ephemeral containers

Observe runtime behavior before pushing to CI

Enforce policies that prevent high-risk actions

Reduce the risk of silent security failures in AI-powered apps

Docker is working to bring MCP Defender into our platform to provide this protection out-of-the-box, so hallucinations don’t turn into incidents.

Ready to Secure Your AI Workflow?

Sign up for early access to Docker’s runtime security capabilities

Watch our Tech Talk on “Building Safe AI Agents with Docker”

Explore Docker Scout for real-time vulnerability insights

Join the community conversation on Docker Community Slack or GitHub Discussions

Let’s build fast, and safely.

Quelle: https://blog.docker.com/feed/

Docker Acquisition of MCP Defender Helps Meet Challenges of Securing the Agentic Future

Docker, Inc.®, a provider of cloud-native and AI-native development tools, infrastructure, and services, today announced the acquisition of MCP Defender, a company founded to secure AI applications.

The rapid evolution of AI-from simple generative models to powerful agentic tools-has transformed software development in extraordinary ways. But as with all powerful technologies, new capabilities bring new security challenges. We recently highlighted critical MCP security issues on the Docker blog, emphasizing how essential it is to secure our emerging AI infrastructure. Building on that discussion, we want to offer our perspective on the current state of AI security, outline its trajectory, consider what this means for organizations developing AI agents and tools, and explore Docker’s vision for securely empowering these new AI workloads.

Today’s AI security landscape mirrors the early days of container adoption: rapid innovation, widespread enthusiasm, but significant uncertainty around risks. AI agents now routinely execute critical tasks – from automated code generation and system administration to customer interaction – often interfacing directly with sensitive data and critical infrastructure. The security stakes have never been higher.

Looking ahead, securing AI infrastructure will require a significant shift towards runtime monitoring, real-time threat detection, and continuous security evaluation. Organizations will increasingly adopt tools designed specifically to detect and respond dynamically to threats occurring at runtime. Instead of relying solely on preventative measures, security strategies will embrace active monitoring and intelligent automation.

For companies developing AI agents and MCP tools, these security shifts are profound. Security can no longer be a late-stage consideration-it must be embedded from the earliest design phase. These solutions must transparently enforce policies, providing clear guardrails that reduce the cognitive load on development teams. Security for AI agents should be frictionless – built seamlessly into the workflows developers already use every day.

Docker’s mission has always been to simplify application development while ensuring security and portability. Extending that mission to agentic AI means integrating security deeply into the infrastructure itself. Docker’s vision is clear: secure-by-default AI infrastructure where every interaction is automatically verified, every threat proactively detected, and every policy transparently enforced. Docker’s commitment to security extends beyond AI, with products such as Docker Scout and Docker Hardened Images.

Quelle: https://blog.docker.com/feed/

Hybrid AI Isn’t the Future — It’s Here (and It Runs in Docker)

Running large AI models in the cloud gives access to immense capabilities, but it doesn’t come for free. The bigger the models, the bigger the bills, and with them, the risk of unexpected costs.

Local models flip the equation. They safeguard privacy and keep costs predictable, but their smaller size often limits what you can achieve. 

For many GenAI applications, like analyzing long documents or running workflows that need a large context, developers face a tradeoff between quality and cost. But there might be a smarter way forward: a hybrid approach that combines the strengths of remote intelligence with local efficiency. 

This idea is well illustrated by the Minions protocol, which coordinates lightweight local “minions” with a stronger remote model to achieve both cost reduction and accuracy preservation. By letting local agents handle routine tasks while deferring complex reasoning to a central intelligence, Minions demonstrates how organizations can cut costs without sacrificing quality.

With Docker and Docker Compose, the setup becomes simple, portable, and secure. 

In this post, we’ll show how to use Docker Compose, Model Runner, and the MinionS protocol to deploy hybrid models and break down the results and trade-offs.  

What’s Hybrid AI

Hybrid AI combines the strengths of powerful cloud models with efficient local models, creating a balance between performance, cost, and privacy. Instead of choosing between quality and affordability, Hybrid AI workflows let developers get the best of both worlds.

Next, let’s see an example of how this can be implemented in practice.

The Hybrid Model: Supervisors and Minions

Think of it as a teamwork model:

Remote Model (Supervisor): Smarter, more capable, but expensive. It doesn’t do all the heavy lifting, it directs the workflow.

Local Models (Minions): Lightweight and inexpensive. They handle the bulk of the work in parallel, following the supervisor’s instructions.

Here’s how it plays out in practice in our new Dockerized Minions integration:

Spin up the Minions application server with docker compose up

A request is sent to the remote model. Instead of processing all the data directly, it generates executable code that defines how to split the task into smaller jobs.

Execute that orchestration code inside the Minions application server, which runs in a Docker container and provides sandboxed isolation.

Local models run those subtasks, analyzing chunks of a large document, summarizing sections, or performing classification in parallel.

The results are sent back to the remote model, which aggregates them into a coherent answer.

The remote model acts like a supervisor, while the local models are the team members doing the work. The result is a division of labor that’s efficient, scalable, and cost-effective.

Why Hybrid?

Cost Reduction: Local models handle most of the tokens and context, thereby reducing cloud model usage.

Scalability: By splitting large jobs into smaller ones, workloads scale horizontally across local models.

Security: The application server runs in a Docker container, and orchestration code is executed there in a sandboxed environment.

Quality: Hybrid protocols pair the cost savings of local execution with the coherence and higher-level reasoning of remote models, delivering better results than local-only setups.

Developer Simplicity: Docker Compose ties everything together into a single configuration file, with no messy environment setup.

Research Benchmarks: Validating the Hybrid Approach

The ideas behind this hybrid architecture aren’t just theoretical, they’re backed by research. In this recent research paper Minions: Cost-efficient Collaboration Between On-device and Cloud Language Models, the authors evaluated different ways of combining smaller local models with larger remote models.

The results demonstrate the value of the hybrid design where a local and remote model collaborate on a task:

Minion Protocol: A local model interacts directly with the remote model, which reduces cloud usage significantly. This setup achieves a 30.4× reduction in remote inference costs, while maintaining about 87% of the performance of relying solely on the remote model.

MinionS Protocol: A local model executes parallel subtasks defined by code generated by the remote model. This structured decomposition achieves a 5.7× cost reduction while preserving ~97.9% of the remote model’s performance.

This is an important validation: hybrid AI architectures can deliver nearly the same quality as high-end proprietary APIs, but at a fraction of the cost.

For developers, this means you don’t need to choose between quality and cost, you can have both. Using Docker Compose as the orchestration layer, the hybrid MinionS protocol becomes straightforward to implement in a real-world developer workflow.

Compose-Driven Developer Experience

What makes this approach especially attractive for developers is how little configuration it actually requires. 

With Docker Compose, setting up a local AI model doesn’t involve wrestling with dependencies, library versions, or GPU quirks. Instead, the model can be declared as a service in a few simple lines of YAML, making the setup both transparent and reproducible.

models:

  worker:

    model: ai/llama3.2

    context_size: 10000

This short block is all it takes to bring up a worker running a local Llama 3.2 model with a 10k context window. Under the hood, Docker ensures that this configuration is portable across environments, so every developer runs the same setup, without ever needing to install or manage the model manually. 

Please note that, depending on the environment you are running in, Docker Model Runner might run as a host process (Docker Desktop) instead of in a container (Docker CE) to ensure optimal inference performance.

Beyond convenience, containerization adds something essential: security. 

In a hybrid system like this, the remote model generates code to orchestrate local execution. By running that code inside a Docker container, it’s safely sandboxed from the host machine. This makes it possible to take full advantage of dynamic orchestration without opening up security risks.

The result is a workflow that feels effortless: declare the model in Compose, start it with a single command, and trust that Docker takes care of both reproducibility and isolation. Hybrid AI becomes not just powerful and cost-efficient, but also safe and developer-friendly.

You can find a complete example ready to use here. In practice, using ai/qwen3 as a local model can cut cloud usage significantly. For a typical workload, only ~15,000 remote tokens are needed, about half the amount required if everything ran on the remote model. 

This reduction comes with a tradeoff: because tasks are split, orchestrated, and processed locally before aggregation, responses may take longer to generate (up to ~10× slower). For many scenarios, the savings in cost and control over data can outweigh the added latency.

Conclusion

Hybrid AI is no longer just an interesting idea, it is a practical path forward for developers who want the power of advanced models while keeping costs low. 

The research behind Minions shows that this approach can preserve nearly all the quality of large remote models while reducing cloud usage dramatically. Docker, in turn, makes the architecture simple to run, easy to reproduce, and secure by design.

By combining remote intelligence with local efficiency, and wrapping it all in a developer-friendly Compose setup, we can better control the tradeoff between capability and cost. What emerges is an AI workflow that is smarter, more sustainable, and accessible to any developer, not just those with deep infrastructure expertise.

This shows a realistic direction for GenAI: not always chasing bigger models, but finding smarter, safer, and more efficient ways to use them. By combining Docker and MinionS, developers already have the tools to experiment with this hybrid approach and start building cost-effective, reproducible AI workflows today. Try it yourself today by visiting the project GitHub repo! 

Learn more 

Read our quickstart guide to Docker Model Runner.

Visit our Model Runner GitHub repo! Docker Model Runner is open-source, and we welcome collaboration and contributions from the community!

Discover other AI solutions from Docker 

Learn how Compose makes building AI apps and agents easier

Quelle: https://blog.docker.com/feed/

You are Doing MCP Wrong: 3 Big Misconceptions

MCP is not an API. Tools are not agents. MCP is more than tools. Here’s what this means in practice.

Most developers misread the Model Context Protocol because they map it onto familiar API mental models. That mistake breaks agent designs, observability, and the “last mile” where non-deterministic reasoning must meet deterministic execution. This piece corrects three common misconceptions and offers concrete patterns that actually work.

1) Misconception #1: “MCP is just another API”

Claim people make: Treat an MCP call like calling REST or gRPC.Reality: MCP is a model-facing protocol designed for LLM tool use, intent mediation, and context exchange. It does not replace RPC. It often uses APIs and RPC under the hood, but its purpose is to make those safely and effectively usable by non-deterministic agents.

Why the confusion happens

Teams default to API thinking because it is familiar and testable.

Most demos show “call tool, get result,” which looks like HTTP.

What MCP actually gives you

Tool interfaces for models that carry intent and affordances, not just endpoints.

Context surfaces beyond request/response: prompts, elicitations, and resources that shape model behavior.

A seam between non-deterministic planning and deterministic execution so the last mile can be reliable.

Design patterns that work

API behind MCP: Keep your stable business APIs. Wrap them with MCP tool definitions that express preconditions, success criteria, and affordances the model can reason about.

Deterministic “last mile”: Treat tool execution as deterministic and idempotent where possible. Validate inputs derived from model planning. Fail closed.

Anti-patterns to avoid

Treating MCP tools as business APIs with complex state changes and no guardrails.

Expecting strict schema obedience without model-aware validation and retries.

Mini-checklist

Define tool preconditions and postconditions.

Return machine-checkable outcomes the agent can evaluate.

Log plan → tool → result so you can replay and audit.

2) Misconception #2: “Tools are agents”

Claim people make: A tool with input and output is an agent.Reality: Tools execute. Agents plan, re-plan, and evaluate. Agents loop until goals are satisfied. Tools do not.

Why the confusion happens

Unix mental model: “compose tools and you get intelligence.”

Modern LLM demos blur the line when a single call seems to “do everything.”

What separates agents from tools

Agency: goal tracking, re-planning, and error recovery.

Evaluation: fitness functions and success criteria, not just status codes.

Memory and context: prompts and resources evolve across steps.

Design patterns that work

Control loop outside the tool: Keep the agent loop responsible for deciding which tool to run next and why.

Explicit success metrics: Give the agent measurable checks to know if it should stop, retry, or escalate to a human.

Human elicitation via MCP: When confidence is low or ambiguity is high, use MCP prompts to ask the user for disambiguation.

Anti-patterns to avoid

Cramming planning into a single tool invocation.

Measuring “agent performance” only with tool latency.

Mini-checklist

Write the agent’s goal, constraints, and stop conditions.

Add retries with backoff and tool-specific error handling.

Capture traces for each loop iteration.

3) Misconception #3: “MCP is just tools”

Claim people make: MCP equals tool definitions with JSON in and out.Reality: MCP includes resources, prompts, and elicitations in addition to tools. These are first-class for context-rich work.

Why the confusion happens

Early adopters only wired tools and ignored the rest of the spec.

Many examples look like “natural language over an API.”

What you miss if you ignore the rest

Resources: structured artifacts the agent can read, write, and reference across steps.

Prompts: reusable, versioned instruction sets the system can attach, test, and audit.

Elicitations: structured human-in-the-loop requests when only a user can resolve ambiguity.

Design patterns that work

Resource adapters: Map knowledge bases, files, and tickets into MCP resources with permissions and lifecycle.

Prompt registries: Treat prompts like code. Version, test, and roll back.

Human checkpoints: Define when to elicit user input and how to resume the loop afterward.

Anti-patterns to avoid

Using MCP as a “voice layer” over existing services without resources or prompts.

Hard-coding long prompts inside the application rather than managing them via MCP.

Mini-checklist

Expose at least one resource type the agent can read and one it can write.

Register prompts with IDs and versions.

Define user elicitation flows for low-confidence branches.

Putting it together: The architecture seam that makes AI reliable

Non-deterministic layer: model planning, tool choice, re-planning, evaluation.

Deterministic layer: tool execution, input validation, idempotency, side-effect control.

MCP as the seam: tools, resources, prompts, and elicitations connect the two layers with observable traces and policies.

Observability and governance

Trace plan → prompt → tool → resource updates.

Version prompts and tool specs.

Enforce access, rate limits, and approvals at the MCP boundary.

Conclusion

If you keep thinking “API,” you will ship brittle, one-shot demos. Treat tools as deterministic executors, treat agents as planners and evaluators, and use all of MCP — tools, resources, prompts, and elicitations — as the seam where intelligent behavior meets reliable systems.

Implementation guide 

Inventory APIs and wrap them with MCP tools that declare pre/postconditions.

Define agent goals and fitness functions. Encode stop criteria.

Model resources the agent needs. Add read/write guards and retention.

Stand up a prompt registry with testing and rollback.

Add human elicitations for low-confidence paths.

Instrument traces and create replayable sessions for audits.

Run chaos drills where tools fail and confirm the agent recovers or escalates.

Common pitfalls and how to avoid them

Treating MCP like REST: Add success checks and evaluation, not just status codes.

One-shot agent calls: Build loops with retries and human checkpoints.

No resource model: The agent thrashes without durable context.

Prompt sprawl: Version prompts and run A/B tests.

Opaque operations: Without traces you cannot debug or trust outcomes.

Quelle: https://blog.docker.com/feed/

Broadcom’s New Bitnami Restrictions? Migrate Easily with Docker

For years, Bitnami has played a vital role in the open source and cloud-native community, making it easier for developers and operators to deploy popular applications with reliable, prebuilt container images and Helm charts. Countless teams have benefited from their work standardizing installation and updates for everything from WordPress to PostgreSQL. We want to acknowledge and thank Bitnami’s contributors for that important contribution.

Recently, however, Bitnami announced significant changes to how their images are distributed. Starting this month, access to most versioned images will move behind a paid subscription under Bitnami Secure Images (BSI), with only the :latest tags remaining free. Older images are being shifted into a Bitnami Legacy archive that will no longer receive updates. For many teams, this raises real challenges around cost, stability, and compliance.

Docker remains committed to being a trusted partner for developers and enterprises alike. Docker Official Images (DOI) are one of the two most widely used catalogs of open source container images in the world, and by far the most adopted. While Bitnami has been valuable to the community, Docker Official Images see billions of pulls every month and are trusted by developers, maintainers, and enterprises globally. This is the standard foundation teams already rely on.

For production environments that require added security and compliance, Docker Hardened Images (DHI) are a seamless drop-in replacement for DOI. They combine the familiarity and compatibility of DOI with enterprise-ready features: minimal builds, non-root by default, signed provenance, and near-zero-CVE baselines. Unlike Bitnami’s new paid model, DHI is designed to be affordable and transparent, giving organizations the confidence they need without unpredictable costs.

Bitnami’s Access Changes Are Already Underway

On July 16, Broadcom’s Bitnami team announced changes to their container image distribution model, effective September 29. Here’s what’s changing:

Freely built and available images and Helm charts are going away. The bitnami organization will be deleted.

New Bitnami Secure Images offering. Users that want to use Bitnami images will need to get a paid subscription to a new Binami Secure Images offering, hosted on the Bitnami registry. This provides access to stable tags, version history,

Free tier of Bitnami Secure Images. The bitnamisecure org has been created to provide a set of hardened, more secure images. Only the :latest tags will be available and the images are intended for development purposes only.

Unsupported legacy fallback. Older images are moved to a “Bitnami Legacy Registry”, available on Docker Hub in the bitnamilegacy org. These images are unsupported, will no longer receive updates or patches, and are intended to be used while making plans for alternatives.

Image and Helm chart source still available. While the built artifacts won’t be published, organizations will still be able to access the source code for Debian-based images and Helm charts. They can build and publish these on their own.

The timeline is tight too. Brownouts have already begun, and the public catalog deletion is set for September 29, 2025.

What Bitnami Users Need to Know

For many teams, this means Helm charts, CI/CD pipelines, and Kubernetes clusters relying on Bitnami will soon face broken pulls, compliance risks, or steep new costs.

The community reaction has been strong. Developers and operators voice concerns around:

Trust and stability concerns. Many see this as a “bait and switch,” with long-standing free infrastructure suddenly paywalled.

Increased operational risk. Losing version pinning or relying on :latest tags introduces deployment chaos, security blind spots, and audit failures.

Cost and budget pressure. Early pricing reports suggest that for organizations running hundreds of workloads, Bitnami’s new model could mean six-figure annual costs.

In short: teams depending on Bitnami for reliable, stable images and Helm charts now face an urgent decision.

Your Fastest Path Forward: Docker

At Docker, we believe developers and enterprises deserve choice, stability, and stability. That’s why we continue to offer two strong paths forward:

Docker Official Images – Free and Widely Available

Docker is committed to building and maintaining its Docker Official Image catalog. This catalog:

Fully supported with a dedicated team. This team reviews, publishes, and maintains the Docker Official Images.

Focused on collaboration. The team works with upstream software maintainers, security experts, and the broader Docker community to ensure images work, are patched, and support the needs of the Docker community.

Trusted by millions of developers worldwide. The Docker Official Images are pulled billions of times per month for development, learning, and production.

Docker Hardened Images – Secure, Minimal, Production-Ready

Docker Hardened Images are secure, production-ready container images designed for enterprise use.

Smaller near-zero known CVEs. Start with images that are up to 95% smaller, fewer packages, and a much-reduced attack surface.

Fast, SLA-backed remediation. Critical and High severity CVEs are patched within 7 days, faster than typical industry response times, and backed by an enterprise-grade SLA.

Multi-distro support. Use the distros you’re familiar with, including trusted Linux distros like Alpine and Debian

Signed provenance, SBOMs, and VEX data – for compliance confidence.

SLSA Level 3 builds, non-root by default, distroless options – following secure-by-default practices.

Self-service customization. Add certificates, packages, environment variables, and other configuration right into the build pipelines without forking or secondary patching.

Fully integrated into Docker Hub for a familiar developer workflow.

Start Your Move Today

If your organization is affected by the Bitnami changes,we are here to help. Docker offers you a fast path forward:

Audit your Bitnami dependencies. Identify which images you’re pulling.

Choose your path. Explore the Docker Official Images catalog or learn more about Docker Hardened Images. Many of the Bitnami images can be easily swapped with images from either catalog.

Need help?Contact our sales team to learn how Docker Hardened Images can provide secure, production-ready images at scale.

Quelle: https://blog.docker.com/feed/

Boost Your Copilot with SonarQube via Docker MCP Toolkit and Gateway

In the era of AI copilots and code generation tools productivity is skyrocketing, but so is the risk of insecure, untested, or messy code slipping into production. How do you ensure it doesn’t introduce vulnerabilities, bugs, or bad practices? 

A widely adopted tool to help address these concerns is SonarQube. It provides a rich set of rules and quality gates to analyze code for bugs, test coverage, code smells, and security issues. But there’s a common pain point: the feedback loop. You often need to switch between your IDE and SonarQube’s results, breaking focus and slowing iteration.

What if your AI agent could see code quality issues the moment they appear, right in your IDE, without you switching tabs or breaking your flow? In this post, we’ll focus on enhancing your development workflow by integrating SonarQube analysis directly into your IDE using the Sonar MCP server and Docker MCP Toolkit.

Getting Started with Sonar MCP from the Docker MCP Toolkit

The solution is here: Sonar MCP Server – a Model Context Protocol (MCP) server that integrates with SonarQube (Cloud or Server) and allows AI agents (like GitHub Copilot) to access code quality metrics and insights directly from your IDE.

To enable Sonar MCP easily and securely, we’ll use the Docker MCP Toolkit. It provides a catalog of over 150 MCP servers – including SonarQube.

We won’t dive deep into how MCP servers and the MCP Toolkit work, (check out the links below for that), but instead we’ll walk through a hands-on example of using Docker MCP Toolkit with Sonar MCP in a Java project.

Further reading about MCP Catalog and Toolkit:

How Docker MCP Toolkit Works with VS Code Copilot Agent Mode

Introducing Docker MCP Catalog and Toolkit

Demo Project: Java Local Development with Testcontainers

For our demo, we’ll use the Java Local Development Testcontainers Workshop project, a Spring Boot-based microservice for managing a product catalog, complete with APIs and Testcontainers-based tests.

GitHub repo: GannaChernyshova/java-testcontainers-local-development

Before diving into MCP integration, ensure your Java project is already set up for SonarQube analysis. In this demo project, that includes:

Using the JaCoCo plugin to collect test coverage data

Adding the SonarQube Maven plugin for code scanning

We also created a corresponding project in SonarQube Cloud and linked it to the GitHub repository. The details of SonarQube setup are outside the scope of this post, but if you need guidance, check out the official SonarQube documentation.

Step 1: Start the Sonar MCP Server via Docker Desktop

The Docker MCP Toolkit, available in Docker Desktop, makes it quick and secure to spin up MCP servers from a pre‑curated catalog without worrying about manual setup or complex dependencies. 

To get started:

Open Docker Desktop and navigate to the MCP Toolkit tab.

Browse the Catalog to find SonarQube.

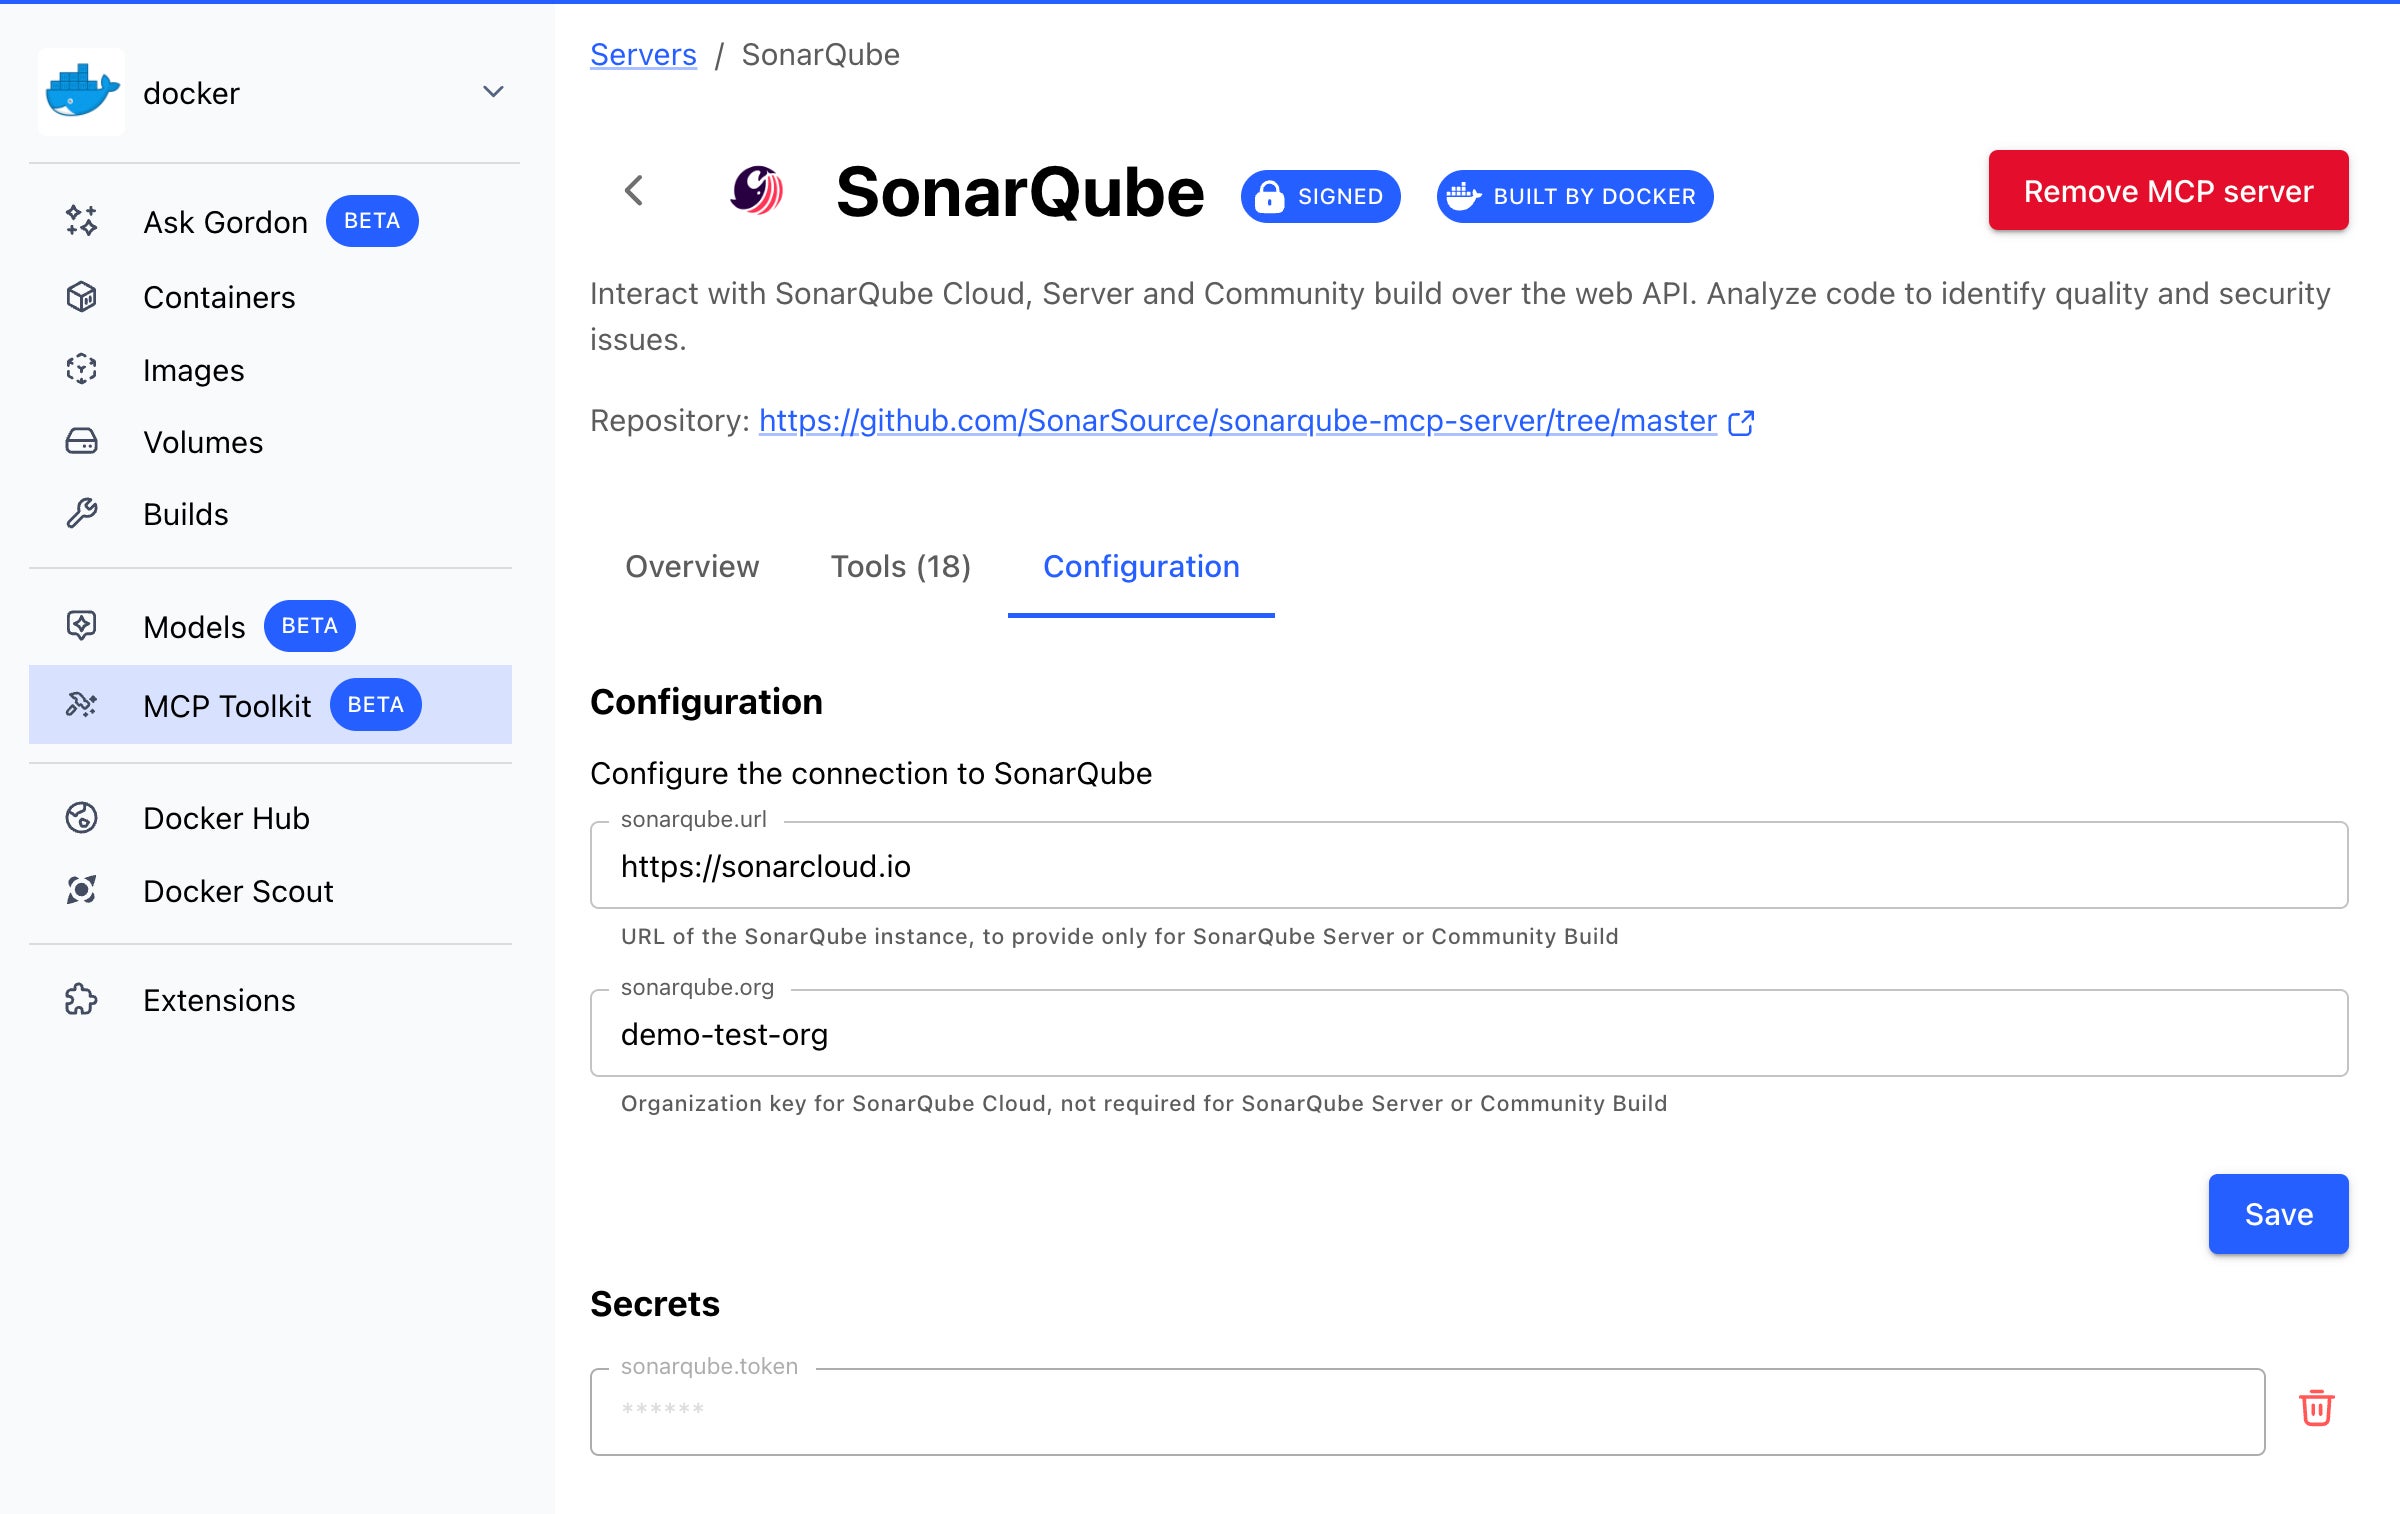
Configure it with your SonarQube URL, organization, and access token.

Hit Start to launch the MCP server.

Figure 1: SonarQube MCP settings in the Docker Desktop MCP Toolkit

Your MCP server should now be up and running.

Step 2: Connect Sonar MCP to GitHub Copilot (IntelliJ)

We’ll use GitHub Copilot in IntelliJ, which now supports Agent Mode and MCP integration.  Here is the detailed instruction from GitHub: how to use the Model Context Protocol (MCP) to extend Copilot Chat.

Open Copilot Settings.

Edit or create the mcp.json file with:

{
"servers": {
"MCP_DOCKER": {
"command": "docker",
"args": [
"mcp",
"gateway",
"run"
],
"type": "stdio"
}
}
}

With this configuration you enable the Docker MCP Gateway, a secure enforcement point between agents and external tools, that would connect the MCP servers from the MCP Toolkit to your clients or agents.  

Now when you switch to Agent Mode in Copilot Chat, you’ll see a list of tools available from the connected MCP server – in this case, the Sonar MCP tools.

Figure 2: Tools that SonarQube MCP server provides

Step 3: Analyze and Improve Your Code

Let’s scan the project:

mvn clean verify sonar:sonar

In our case, the default quality gate passed. However, 4 security issues, few maintainability and 72.1% test coverage were flagged, leaving room for improvement.

Figure 3: Initial SonarQube scanning overview

Time to bring in Copilot + Sonar MCP!

We can now ask Copilot Chat to list the issues, suggest fixes, help with adding missing tests, and iterate faster – all within IntelliJ, without switching context.

Through several iterations, the agent successfully:

Detected open issues, suggested and applied fixes:

Figure 4: GitHub Copilot Agent detects and fixes issues reported by SonarQube 

Improved test coverage based on the sonar report of uncovered code lines: 

Figure 5: GitHub Copilot Agent writes tests for uncovered code detected in SonarQube report 

Resolved security problems and improved code maintainability:

Figure 6: GitHub Copilot Agent implements fixes based on the SonarQube open security and maintainability issues

As a result, the final SonarQube scan showed an A rating in every analysis category, and test coverage increased by over 15%, reaching 91.1%.

Figure 7: SonarQube scanning results after the fixes made with the help of Copilot

Conclusion

With the rapid rise of generative AI tools, developers can move faster than ever. But that speed comes with responsibility. The combination of Sonar MCP + Docker MCP Toolkit turns AI copilots into security- and quality-aware coding partners. It’s not just about writing code faster, it’s about writing better code first. 

Learn More

Discover hundreds of curated MCP servers on the Docker MCP Catalog

Learn more about Docker MCP Toolkit

Explore Docker MCP Gateway on GitHub

Quelle: https://blog.docker.com/feed/

Secure by Design: A Shift-Left Approach with Testcontainers, Docker Scout, and Hardened Images

In today’s fast-paced world of software development, product teams are expected to move quickly: building features, shipping updates, and reacting to user needs in real-time. But moving fast should never mean compromising on quality or security.

Thanks to modern tooling, developers can now maintain high standards while accelerating delivery. In a previous article, we explored how Testcontainers supports shift-left testing by enabling fast and reliable integration tests within the inner dev loop. In this post, we’ll look at the security side of this shift-left approach and how Docker can help move security earlier in the development lifecycle, using practical examples.

A Shift-Left Approach: Testing a Movie Catalog API

We’ll use a simple demo project to walk through our workflow. This is a Node.js + TypeScript API backed by PostgreSQL and tested with Testcontainers.

Movie API Endpoints:

Method

Endpoint

Description

POST

/movies

Add a new movie to the catalog

GET

/movies

Retrieve all movies, sorted by title

GET

/movies/search?q=…

Search movies by title or description (fuzzy match)

Before deploying this app to production, we want to make sure it functions correctly and is free from critical vulnerabilities.

Shift-Left Testing with Testcontainers: Recap

We verify the application against a real PostgreSQL instance by using Testcontainers to spin up containers for both the database and the application. A key advantage of Testcontainers is that it creates these containers dynamically during test execution. Another feature of the Testcontainers libraries is the ability to start containers directly from a Dockerfile. This allows us to run the containerized application along with any required services, such as databases, effectively reproducing the local environment needed to test the application at the API or end-to-end (E2E) level. This approach provides an additional layer of quality assurance and brings even more testing into the inner development loop.

For a more detailed explanation of how Testcontainers enables a shift-left testing approach into the developer inner loop, refer to the introductory blog post.

Here’s a beforeAll setup that prepares our test environment, including PostgreSQL and the application under development, started from the Dockerfile :

beforeAll(async () => {
const network = await new Network().start();
// 1. Start Postgres
db = await new PostgreSqlContainer("postgres:17.4")
.withNetwork(network)
.withNetworkAliases("postgres")
.withDatabase("catalog")
.withUsername("postgres")
.withPassword("postgres")
.withCopyFilesToContainer([
{
source: path.join(__dirname, "../dev/db/1-create-schema.sql"),
target: "/docker-entrypoint-initdb.d/1-create-schema.sql"
},
])
.start();
// 2. Build movie catalog API container from the Dockerfile
const container = await GenericContainer
.fromDockerfile("../movie-catalog")
.withTarget("final")
.withBuildkit()
.build();
// 3. Start movie catalog API container with environment variables for DB connection
app = await container
.withNetwork(network)
.withExposedPorts(3000)
.withEnvironment({
PGHOST: "postgres",
PGPORT: "5432",
PGDATABASE: "catalog",
PGUSER: "postgres",
PGPASSWORD: "postgres",
})
.withWaitStrategy(Wait.forListeningPorts())
.start();
}, 120000);

We can now test the movie catalog API:

it("should create and retrieve a movie", async () => {
const baseUrl = `http://${app.getHost()}:${app.getMappedPort(3000)}`;
const payload = {
title: "Interstellar",
director: "Christopher Nolan",
genres: ["sci-fi"],
releaseYear: 2014,
description: "Space and time exploration"
};

const response = await axios.post(`${baseUrl}/movies`, payload);
expect(response.status).toBe(201);
expect(response.data.title).toBe("Interstellar");
}, 120000);

This approach allows us to validate that:

The application is properly containerized and starts successfully.

The API behaves correctly in a containerized environment with a real database.

However, that’s just one part of the quality story. Now, let’s turn our attention to the security aspects of the application under development.

Introducing Docker Scout and Docker Hardened Images 

To follow modern best practices, we want to containerize the app and eventually deploy it to production. Before doing so, we must ensure the image is secure by using Docker Scout.

Our Dockerfile takes a multi-stage build approach and is based on the node:22-slim image.

###########################################################
# Stage: base
# This stage serves as the base for all of the other stages.
# By using this stage, it provides a consistent base for both
# the dev and prod versions of the image.
###########################################################
FROM node:22-slim AS base
WORKDIR /usr/local/app
RUN useradd -m appuser && chown -R appuser /usr/local/app
USER appuser
COPY –chown=appuser:appuser package.json package-lock.json ./

###########################################################
# Stage: dev
# This stage is used to run the application in a development
# environment. It installs all app dependencies and will
# start the app in a dev mode that will watch for file changes
# and automatically restart the app.
###########################################################
FROM base AS dev
ENV NODE_ENV=development
RUN npm ci –ignore-scripts
COPY –chown=appuser:appuser ./src ./src
EXPOSE 3000
CMD ["npx", "nodemon", "src/app.js"]

###########################################################
# Stage: final
# This stage serves as the final image for production. It
# installs only the production dependencies.
###########################################################
# Deps: install only prod deps
FROM base AS prod-deps
ENV NODE_ENV=production
RUN npm ci –production –ignore-scripts && npm cache clean –force
# Final: clean prod image
FROM base AS final
WORKDIR /usr/local/app
COPY –from=prod-deps /usr/local/app/node_modules ./node_modules
COPY ./src ./src
EXPOSE 3000
CMD [ "node", "src/app.js" ]

Let’s build our image with SBOM and provenance metadata. First, make sure that the containerd image store is enabled in Docker Desktop. We’ll also use the buildx command ( a Docker CLI plugin that extends the docker build) with the –provenance=true  and –sbom=true flags. These options attach build attestations to the image, which Docker Scout uses to provide more detailed and accurate security analysis.

docker buildx build –provenance=true –sbom=true -t movie-catalog-service:v1 .

Then set up a Docker organization with security policies and scan the image with Docker Scout: 

docker scout config organization demonstrationorg
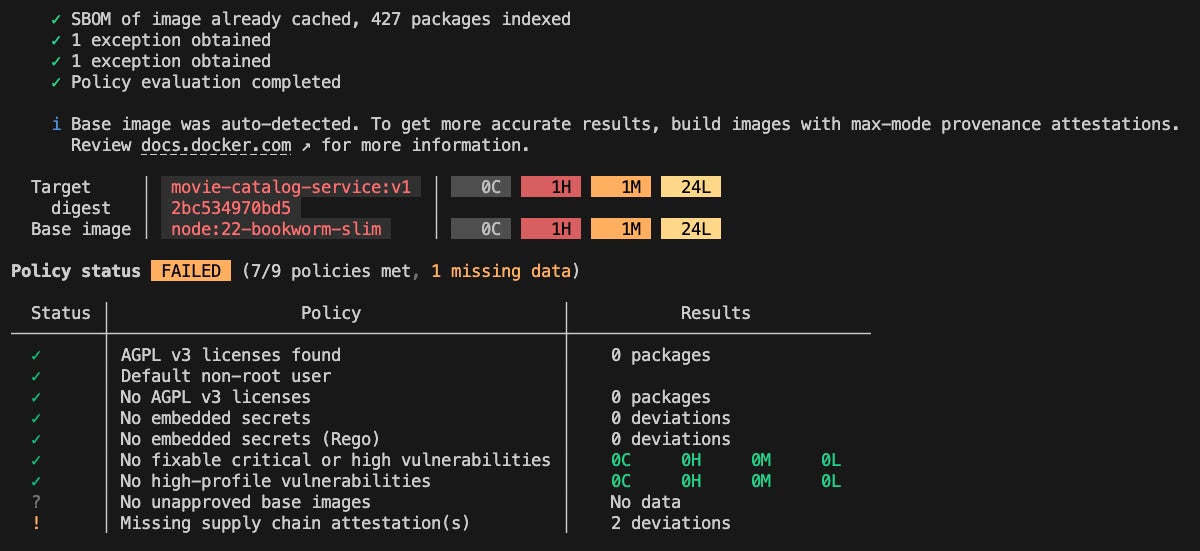
docker scout quickview movie-catalog-service:v1

Figure 1: Docker Scout cli quickview output for node:22 based movie-catalog-service image

Docker Scout also offers a visual analysis via Docker Desktop.

Figure 2: Image layers and CVEs view in Docker Desktop for node:22 based movie-catalog-service image

In this example, no vulnerabilities were found in the application layer. However, several CVEs were introduced by the base node:22-slim image, including a high-severity CVE-2025-6020, a vulnerability present in Debian 12. This means that any Node.js image based on Debian 12 inherits this vulnerability. A common way to address this is by switching to an Alpine-based Node image, which does not include this CVE. However, Alpine uses musl libc instead of glibc, which can lead to compatibility issues depending on your application’s runtime requirements and deployment environment.

So, what’s a more secure and compatible alternative?

That’s where Docker Hardened Images (DHI) come in. These images follow a distroless philosophy, removing unnecessary components to significantly reduce the attack surface. The result? Smaller images that pull faster, run leaner, and provide a secure-by-default foundation for production workloads:

Near-zero exploitable CVEs: Continuously updated, vulnerability-scanned, and published with signed attestations to minimize patch fatigue and eliminate false positives.

Seamless migration: Drop-in replacements for popular base images, with -dev variants available for multi-stage builds.

Up to 95% smaller attack surface: Unlike traditional base images that include full OS stacks with shells and package managers, distroless images retain only the essentials needed to run your app.

Built-in supply chain security: Each image includes signed SBOMs, VEX documents, and SLSA provenance for audit-ready pipelines.

For developers, DHI means fewer CVE-related disruptions, faster CI/CD pipelines, and trusted images you can use with confidence.

Making the Switch to Docker Hardened Images

Switching to a Docker Hardened Image is straightforward. All we need to do is replace the base image node:22-slim with a DHI equivalent.

Docker Hardened Images come in two variants:

Dev variant (demonstrationorg/dhi-node:22-dev) – includes a shell and package managers, making it suitable for building and testing.

Runtime variant (demonstrationorg/dhi-node:22) – stripped down to only the essentials, providing a minimal and secure footprint for production.

This makes them perfect for use in multi-stage Dockerfiles. We can build the app in the dev image, then copy the built application into the runtime image, which will serve as the base for production.

Here’s what the updated Dockerfile would look like:

###########################################################
# Stage: base
# This stage serves as the base for all of the other stages.
# By using this stage, it provides a consistent base for both
# the dev and prod versions of the image.
###########################################################
# Changed node:22 to dhi-node:22-dev
FROM demonstrationorg/dhi-node:22-dev AS base
WORKDIR /usr/local/app
# DHI comes with nonroot user built-in.
COPY –chown=nonroot package.json package-lock.json ./

###########################################################
# Stage: dev
# This stage is used to run the application in a development
# environment. It installs all app dependencies and will
# start the app in a dev mode that will watch for file changes
# and automatically restart the app.
###########################################################
FROM base AS dev
ENV NODE_ENV=development
RUN npm ci –ignore-scripts
# DHI comes with nonroot user built-in.
COPY –chown=nonroot ./src ./src
EXPOSE 3000
CMD ["npx", "nodemon", "src/app.js"]

###########################################################
# Stage: final
# This stage serves as the final image for production. It
# installs only the production dependencies.
###########################################################
# Deps: install only prod deps
FROM base AS prod-deps
ENV NODE_ENV=production
RUN npm ci –production –ignore-scripts && npm cache clean –force
# Final: clean prod image
# Changed base to dhi-node:22
FROM demonstrationorg/dhi-node:22 AS final
WORKDIR /usr/local/app
COPY –from=prod-deps /usr/local/app/node_modules ./node_modules
COPY ./src ./src
EXPOSE 3000
CMD [ "node", "src/app.js" ]

Let’s rebuild and scan the new image:

docker buildx build –provenance=true –sbom=true -t movie-catalog-service-dhi:v1 .
docker scout quickview movie-catalog-service-dhi:v1

Figure 3: Docker Scout cli quickview output for dhi-node:22 based movie-catalog-service image

As you can see, all critical and high CVEs are gone, thanks to the clean and minimal footprint of the Docker Hardened Image.

One of the key benefits of using DHI is the security SLA it provides. If a new CVE is discovered, the DHI team commits to resolving:

Critical and high vulnerabilities within 7 days of a patch becoming available,

Medium and low vulnerabilities within 30 days.

This means you can significantly reduce your CVE remediation burden and give developers more time to focus on innovation and feature development instead of chasing vulnerabilities.

Comparing images with Docker Scout

Let’s also look at the image size and package count advantages of using distroless Hardened Images.

Docker Scout offers a helpful command docker scout compare , that allows you to analyze and compare two images. We’ll use it to evaluate the difference in size and package footprint between node:22-slim and dhi-node:22 based images.

docker scout compare local://movie-catalog-service:v1 –to local://movie-catalog-service-dhi:v1

Figure 4: Comparison of the node:22 and dhi-node:22 based movie-catalog-service images

As you can see, the original node:22-slim based image was 80 MB in size and included 427 packages, while the dhi-node:22 based image is just 41 MB with only 123 packages. 

By switching to a Docker Hardened Image, we reduced the image size by nearly 50 percent and cut down the number of packages by more than three times, significantly reducing the attack surface.

Final Step: Validate with local API tests

Last but not least, after migrating to a DHI base image, we should verify that the application still functions as expected.

Since we’ve already implemented Testcontainers-based tests, we can easily ensure that the API remains accessible and behaves correctly.

Let’s run the tests using the npm test command. 

Figure 5: Local API test execution results

As you can see, the container was built and started successfully. In less than 20 seconds, we were able to verify that the application functions correctly and integrates properly with Postgres.

At this point, we can push the changes to the remote repository, confident that the application is both secure and fully functional, and move on to the next task. 

Further integration with external security tools

In addition to providing a minimal and secure base image, Docker Hardened Images include a comprehensive set of attestations. These include a Software Bill of Materials (SBOM), which details all components, libraries, and dependencies used during the build process, as well as Vulnerability Exploitability eXchange (VEX). VEX offers contextual insights into vulnerabilities, specifying whether they are actually exploitable in a given environment, helping teams prioritize remediation.

Let’s say you’ve committed your code changes, built the application, and pushed a container image. Now you want to verify the security posture using an external scanning tool you already use, such as Grype or Trivy. That requires vulnerability information in a compatible format, which Docker Scout can generate for you.

First, you can view the list of available attestations using the docker scout attest command:

docker scout attest list demonstrationorg/movie-catalog-service-dhi:v1 –platform linux/arm64

This command returns a detailed list of attestations bundled with the image. For example, you might see two OpenVEX files: one for the DHI base image and another for any custom exceptions (like no-dsa) specific to your image.

Then, to integrate this information with external tools, you can export the VEX data into a vex.json file. Starting Docker Scout v1.18.3 you can use the docker scout vex get command to get the merged VEX document from all VEX attestations:

docker scout vex get demonstrationorg/movie-catalog-service-dhi:v1 –output vex.json

This generates a vex.json file containing all VEX statements for the specified image. Tools that support VEX can then use this file to suppress known non-exploitable CVEs.

To use the VEX information with Grype or Trivy, pass the –vex flag during scanning:

trivy image demonstrationorg/movie-catalog-service-dhi:v1 –vex vex.json

This ensures your security scanning results are consistent across tools, leveraging the same set of vulnerability contexts provided by Docker Scout.

Conclusion

Shifting left is about more than just early testing. It’s a proactive mindset for building secure, production-ready software from the beginning.

This shift-left approach combines:

Real infrastructure testing using Testcontainers

End-to-end supply chain visibility and actionable insights with Docker Scout

Trusted, minimal base images through Docker Hardened Images

Together, these tools help catch issues early, improve compliance, and reduce security risks in the software supply chain.

Learn more and request access to Docker Hardened Images!
Quelle: https://blog.docker.com/feed/

Docker Desktop Accelerates Innovation with Faster Release Cadence

We’re excited to announce a major evolution in how we deliver Docker Desktop updates to you. Starting with Docker Desktop release 4.45.0 on 28 August we’re moving to releases every two weeks, with the goal of reaching weekly releases by the end of 2025.

Why We’re Making This Change

You’ve told us you want faster access to new features, bug fixes, and security updates. By moving from a monthly to a two-week cadence, you get:

Earlier access to new features and improvements

Reduced wait times for critical updates

Faster bug fixes and security patches

Built on Proven Quality Processes

Our accelerated releases are backed by the same robust quality assurance that enterprise customers depend on:

Comprehensive automated testing across platforms and configurations

Docker Captains Community continues as our valued early adopter program, providing crucial feedback through beta channels

Real-time reliability monitoring to catch issues early

Feature flags for controlled rollout of major changes

Canary deployments reaching a small percentage of users first

Coming Soon

Along with faster releases, we’re completely redesigning how updates work. The following changes are going to be rolled out very soon:

Smarter Component Updates

Independent tools like Scout, Compose, Ask Gordon, and Model Runner update silently in the background

No workflow interruption – the component updates happen when you’re not actively developing

GUI updates (Docker Desktop dashboard) happen automatically when you close and reopen Docker Desktop

Clearer Update Information

Simplified update flow

In-app release highlights showcasing key improvements

Enterprise Control Maintained

We know enterprises need precise control over updates. The new model maintains the ability to disable in-app updates for local users or set defaults via the cloud admin console.

Getting Started

The new release cadence and update experience are rolling out in phases to all Docker Desktop users starting with version 4.45.0. Enterprise customers can access governance features through existing Docker Business subscriptions.

We’re excited to get improvements into your hands faster while maintaining the enterprise-grade reliability you expect from Docker Desktop.Download Docker Desktop here or update in-app!

Quelle: https://blog.docker.com/feed/