State of Agentic AI Report: Key Findings

Based on Docker’s State of Agentic AI report, a global survey of more than 800 developers, platform engineers, and technology decision-makers, this blog summarizes key findings of what’s really happening as agentic AI scales within organizations. Drawing on insights from decision-makers and purchase influencers worldwide, we’ll give you a preview on not only where teams are seeing early wins but also what’s still missing to move from experimentation to enterprise-grade adoption.

Rapid adoption, early maturity

60% of organizations already have AI agents in production, and 94% view building agents as a strategic priority, but most deployments remain internal and focused on productivity and operational efficiency.

Security and complexity are the top barriers

40% of respondents cite security as the #1 challenge in scaling agentic AI, with 45% struggling to ensure tools are secure and enterprise-ready. Technical complexity compounds the challenge. One in three organizations (33%) report orchestration difficulties as multi-model and multi-cloud environments proliferate (79% of organizations run agents across two or more environments).

MCP shows promise but isn’t enterprise-ready

85% of teams are familiar with the Model Context Protocol (MCP), yet most report significant security, configuration, and manageability issues that prevent production-scale deployment.

Want the full picture? Download the latest State of Agentic AI report to explore deeper insights and practical recommendations for scaling agentic AI in your organization.

Fear of vendor lock-in is real

Enterprises worry about dependencies in core agent and agentic infrastructure layers such as model hosting, LLM providers, and even cloud platforms. Seventy-six percent of global  respondents report active concerns about vendor lock-in, rising to 88% in France, 83%in Japan, and 82% in the UK. 

Containerization remains foundational

94% use containers for agent development or production, and 98% follow the same cloud-native workflows as traditional software, establishing containers as the proven substrate for agentic AI infrastructure.

Long-term outlook

Rather than a “year of the agents,” the data points to a decade-long transformation. Organizations are laying the governance and trust foundations now for scalable, enterprise-grade agent ecosystems.

The path forward

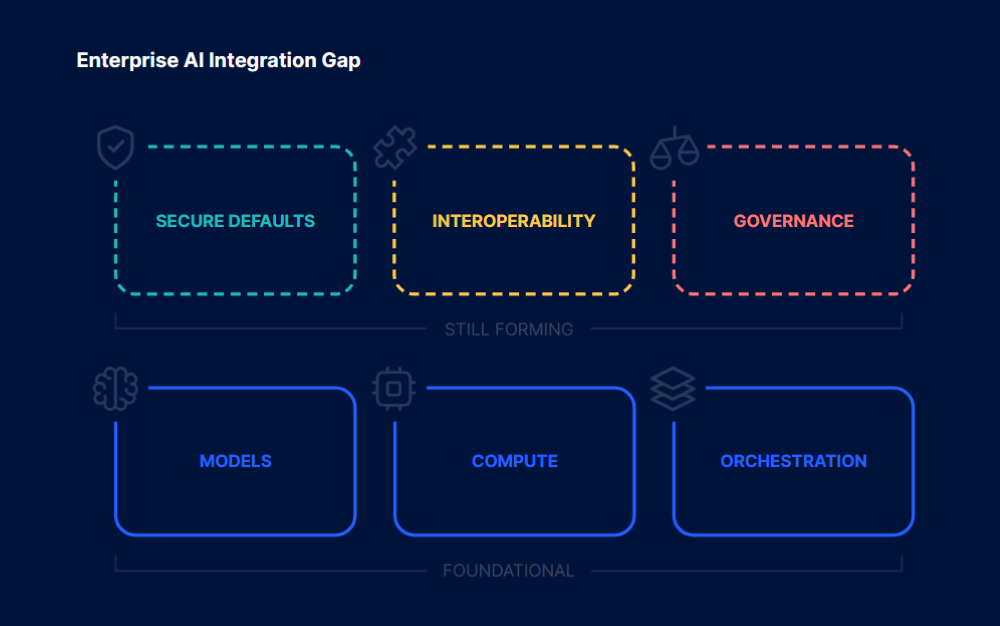
The path forward doesn’t require reinvention so much as consolidation around a trust layer: access to trusted content and components that can be safely discovered and reused; secure-by-default runtimes; standardized orchestration and policy; and portable, auditable packaging.

Agentic AI’s near-term value is already real in internal workflows; unlocking the next wave depends on standardizing how we secure, orchestrate, and ship agents. Teams that invest now in this trust layer, on top of the container foundations they already know, will be first to scale agents from local productivity to durable, enterprise-wide outcomes.

Download the full Agentic AI report for more insights and recommendations on how to scale agents for enterprise.  

Learn more:

Get your copy of the latest State of Agentic AI report! 

Learn more about Docker’s AI solutions

Subscribe to our Developer Newsletter to get the latest news

Quelle: https://blog.docker.com/feed/

How Medplum Secured Their Healthcare Platform with Docker Hardened Images (DHI)

Special thanks to Cody Ebberson and the Medplum team for their open-source contribution and for sharing their migration experience with the community. A real-world example of migrating a HIPAA-compliant EHR platform to DHI with minimal code changes.

Healthcare software runs on trust. When patient data is at stake, security isn’t just a feature but a fundamental requirement. For healthcare platform providers, proving that trust to enterprise customers is an ongoing challenge that requires continuous investment in security posture, compliance certifications, and vulnerability management.

That’s why we’re excited to share how Medplum, an open-source healthcare platform serving over 20 million patients, recently migrated to Docker Hardened Images (DHI). This migration demonstrates exactly what we designed DHI to deliver: enterprise-grade security with minimal friction. Medplum’s team made the switch with just 54 lines of changes across 5 files – a near net-zero code change that dramatically improved their security posture.

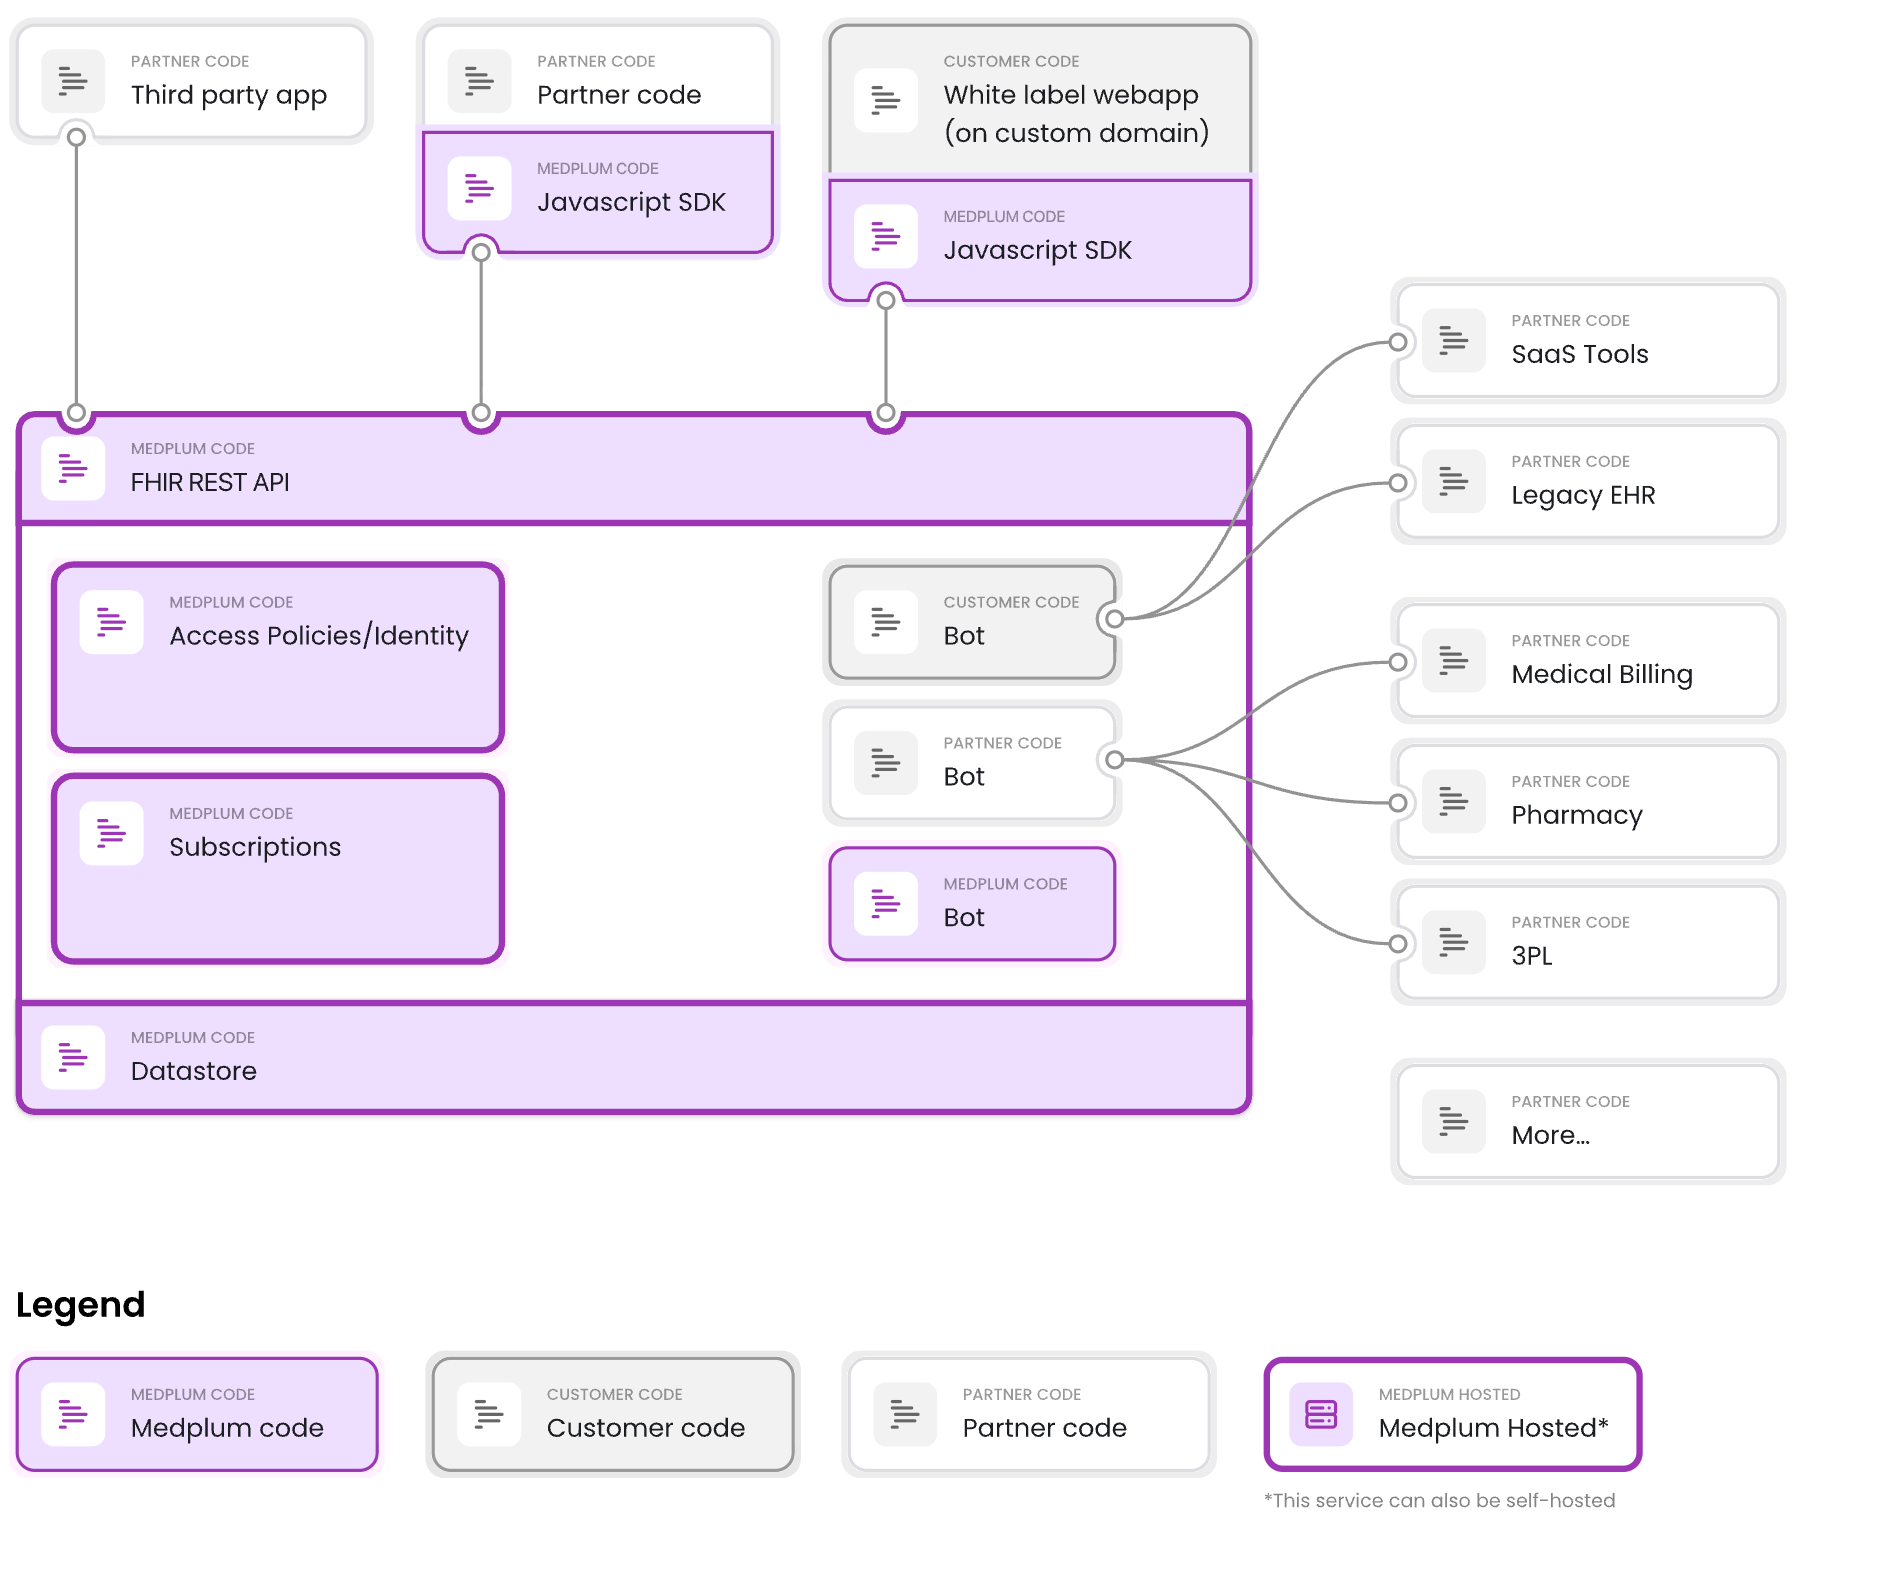
Medplum is a headless EHR; the platform handles patient data, clinical workflows, and compliance so developers can focus on building healthcare apps. Built by and for healthcare developers, the platform provides:

HIPAA and SOC2 compliance out of the box

FHIR R4 API for healthcare data interoperability

Self-hosted or managed deployment options

Support for 20+ million patients across hundreds of practices

With over 500,000 pulls on Docker Hub for their medplum-server image, Medplum has become a trusted foundation for healthcare developers worldwide. As an open-source project licensed under Apache 2.0, their entire codebase, including Docker configurations, is publicly available onGitHub. This transparency made their DHI migration a perfect case study for the community.

Caption: Medplum is a headless EHR; the platform handles patient data, clinical workflows, and compliance so developers can focus on building healthcare apps.

Medplum is developer-first. It’s not a plug-and-play low-code tool, it’s designed for engineering teams that want a strong FHIR-based foundation with full control over the codebase.

The Challenge: Vulnerability Noise and Security Toil

Healthcare software development comes with unique challenges. Integration with existing EHR systems, compliance with regulations like HIPAA, and the need for robust security all add complexity and cost to development cycles.

“The Medplum team found themselves facing a challenge common to many high-growth platforms: “Vulnerability Noise.” Even with lean base images, standard distributions often include non-essential packages that trigger security flags during enterprise audits. For a company helping others achieve HIPAA compliance, every “Low” or “Medium” CVE (Common Vulnerability and Exposure) requires investigation and documentation, creating significant “security toil” for their engineering team.”

Reshma Khilnani
CEO, Medplum

Medplum addresses this by providing a compliant foundation. But even with that foundation, their team found themselves facing another challenge common to high-growth platforms: “Vulnerability Noise.”

Healthcare is one of the most security-conscious industries. Medplum’s enterprise customers, including Series C and D funded digital health companies, don’t just ask about security; they actively verify it. These customers routinely scan Medplum’s Docker images as part of their security due diligence.

Even with lean base images, standard distributions often include non-essential packages that trigger security flags during enterprise audits. For a company helping others achieve HIPAA compliance, every “Low” or “Medium” CVE requires investigation and documentation. This creates significant “security toil” for their engineering team.

The First Attempt: Distroless

This wasn’t Medplum’s first attempt at solving the problem. Back in November 2024, the team investigated Google’s distroless images as a potential solution.

The motivations were similar to what DHI would later deliver:

Less surface area in production images, and therefore less CVE noise

Smaller images for faster deployments

Simpler build process without manual hardening scripts

The idea was sound. Distroless images strip away everything except the application runtime: no shell, no package manager, minimal attack surface. On paper, it was exactly what Medplum needed.

But the results were mixed. Image sizes actually increased. Build times went up. There were concerns about multi-architecture support for native dependencies. The PR was closed without merging.

The core problem remained: many CVEs in standard images simply aren’t actionable. Often there isn’t a fix available, so all you can do is document and explain why it doesn’t apply to your use case. And often the vulnerability is in a corner of the image you’re not even using, like Perl, which comes preinstalled on Debian but serves no purpose in a Node.js application.

Fully removing these unused components is the only real answer. The team knew they needed hardened images. They just hadn’t found the right solution yet.

The Solution: Docker Hardened Images

When Docker made Hardened Images freely available under Apache 2.0, Medplum’s team saw an opportunity to simplify their security posture while maintaining compatibility with their existing workflows.

By switching to Docker Hardened Images, Medplum was able to offload the repetitive work of OS-level hardening – like configuring non-root users and stripping out unnecessary binaries – to Docker. This allowed them to provide their users with a “Secure-by-Default” image that meets enterprise requirements without adding complexity to their open-source codebase.

This shift is particularly significant for an open-source project. Rather than maintaining custom hardening scripts that contributors need to understand and maintain, Medplum can now rely on Docker’s expertise and continuous maintenance. The security posture improves automatically with each DHI update, without requiring changes to Medplum’s Dockerfiles.

“By switching to Docker Hardened Images, Medplum was able to offload the repetitive work of OS-level hardening—like configuring non-root users and stripping out unnecessary binaries—to Docker. This allowed their users to provide their users with a “Secure-by-Default” image that meets enterprise requirements without adding complexity to their open-source codebase.”

Cody Ebberson
CTO, Medplum

The Migration: Real Code Changes

The migration was remarkably clean. Previously, Medplum’s Dockerfile required manual steps to ensure security best practices. By moving to DHI, they could simplify their configuration significantly.

Let’s look at what actually changed. Here’s the complete server Dockerfile after the migration:

# Medplum production Dockerfile
# Uses Docker "Hardened Images":
# https://hub.docker.com/hardened-images/catalog/dhi/node/guides

# Supported architectures: linux/amd64, linux/arm64

# Stage 1: Build the application and install production dependencies
FROM dhi.io/node:24-dev AS build-stage
ENV NODE_ENV=production
WORKDIR /usr/src/medplum
ADD ./medplum-server-metadata.tar.gz ./
RUN npm ci –omit=dev &&
rm package-lock.json

# Stage 2: Create the runtime image
FROM dhi.io/node:24 AS runtime-stage
ENV NODE_ENV=production
WORKDIR /usr/src/medplum
COPY –from=build-stage /usr/src/medplum/ ./
ADD ./medplum-server-runtime.tar.gz ./

EXPOSE 5000 8103

ENTRYPOINT [ "node", "–require", "./packages/server/dist/otel/instrumentation.js", "packages/server/dist/index.js" ]

Notice what’s not there:

No groupadd or useradd commands: DHI runs as non-root by default

No chown commands: permissions are already correct

No USER directive: the default user is already non-privileged

Before vs. After: Server Dockerfile

Before (node:24-slim):

FROM node:24-slim
ENV NODE_ENV=production
WORKDIR /usr/src/medplum

ADD ./medplum-server.tar.gz ./

# Install dependencies, create non-root user, and set permissions
RUN npm ci &&
rm package-lock.json &&
groupadd -r medplum &&
useradd -r -g medplum medplum &&
chown -R medplum:medplum /usr/src/medplum

EXPOSE 5000 8103

# Switch to the non-root user
USER medplum

ENTRYPOINT [ "node", "–require", "./packages/server/dist/otel/instrumentation.js", "packages/server/dist/index.js" ]

After (dhi.io/node:24):

FROM dhi.io/node:24-dev AS build-stage
ENV NODE_ENV=production
WORKDIR /usr/src/medplum
ADD ./medplum-server-metadata.tar.gz ./
RUN npm ci –omit=dev && rm package-lock.json

FROM dhi.io/node:24 AS runtime-stage
ENV NODE_ENV=production
WORKDIR /usr/src/medplum
COPY –from=build-stage /usr/src/medplum/ ./
ADD ./medplum-server-runtime.tar.gz ./

EXPOSE 5000 8103

ENTRYPOINT [ "node", "–require", "./packages/server/dist/otel/instrumentation.js", "packages/server/dist/index.js" ]

The migration also introduced a cleaner multi-stage build pattern, separating metadata (package.json files) from runtime artifacts.

Before vs. After: App Dockerfile (Nginx)

The web app migration was even more dramatic:

Before (nginx-unprivileged:alpine):

FROM nginxinc/nginx-unprivileged:alpine

# Start as root for permissions
USER root

COPY <<EOF /etc/nginx/conf.d/default.conf
# … nginx config …
EOF

ADD ./medplum-app.tar.gz /usr/share/nginx/html
COPY ./docker-entrypoint.sh /docker-entrypoint.sh

# Manual permission setup
RUN chown -R 101:101 /usr/share/nginx/html &&
chown 101:101 /docker-entrypoint.sh &&
chmod +x /docker-entrypoint.sh

EXPOSE 3000

# Switch back to non-root
USER 101

ENTRYPOINT ["/docker-entrypoint.sh"]

After (dhi.io/nginx:1):

FROM dhi.io/nginx:1

COPY <<EOF /etc/nginx/nginx.conf
# … nginx config …
EOF

ADD ./medplum-app.tar.gz /usr/share/nginx/html
COPY ./docker-entrypoint.sh /docker-entrypoint.sh

EXPOSE 3000

ENTRYPOINT ["/docker-entrypoint.sh"]

Results: Improved Security Posture

After merging the changes, Medplum’s team shared their improved security scan results. The migration to DHI resulted in:

Dramatically reduced CVE count – DHI’s minimal base means fewer packages to patch

Non-root by default – No manual user configuration required

No shell access in production – Reduced attack surface for container escape attempts

Continuous patching – All DHI images are rebuilt when upstream security updates are available

For organizations that require stronger guarantees, Docker Hardened Images Enterprise adds SLA-backed remediation timelines, image customizations, and FIPS/STIG variants.

Most importantly, all of this was achieved with zero functional changes to the application. The same tests passed, the same workflows worked, and the same deployment process applied.

CI/CD Integration

Medplum also updated their GitHub Actions workflow to authenticate with the DHI registry:

– name: Login to Docker Hub
uses: docker/login-action@v2.2.0
with:
username: ${{ secrets.DOCKERHUB_USERNAME }}
password: ${{ secrets.DOCKERHUB_TOKEN }}

– name: Login to Docker Hub Hardened Images
uses: docker/login-action@v2.2.0
with:
registry: dhi.io
username: ${{ secrets.DOCKERHUB_USERNAME }}
password: ${{ secrets.DOCKERHUB_TOKEN }}

This allows their CI/CD pipeline to pull hardened base images during builds. The same Docker Hub credentials work for both standard and hardened image registries.

The Multi-Stage Pattern for DHI

One pattern worth highlighting from Medplum’s migration is the use of multi-stage builds with DHI variants:

Build stage: Use dhi.io/node:24-dev which includes npm/yarn for installing dependencies

Runtime stage: Use dhi.io/node:24 which is minimal and doesn’t include package managers

This pattern ensures that build tools never make it into the production image, further reducing the attack surface. It’s a best practice for any containerized Node.js application, and DHI makes it straightforward by providing purpose-built variants for each stage.

Medplum’s Production Architecture

Medplum’s hosted offering runs on AWS using containerized workloads. Their medplum/medplum-server image, built on DHI base images, now deploys to production.

Here’s how the build-to-deploy flow works:

Build time: GitHub Actions pulls dhi.io/node:24-dev and dhi.io/node:24 as base images

Push: The resulting hardened image is pushed to medplum/medplum-server on Docker Hub

Deploy: AWS Fargate pulls medplum/medplum-server:latest and runs the hardened container

The deployed containers inherit all DHI security properties (non-root execution, minimal attack surface, no shell) because they’re built on DHI base images. This demonstrates that DHI works seamlessly with production-grade infrastructure including:

AWS Fargate/ECS for container orchestration

Elastic Load Balancing for high availability

Aurora PostgreSQL for managed database

ElastiCache for Redis caching

CloudFront for CDN and static assets

No infrastructure changes were required. The same deployment pipeline, the same Fargate configuration, just a more secure base image.

Why This Matters for Healthcare

For healthcare organizations evaluating container security, Medplum’s migration offers several lessons:

1. Eliminating “Vulnerability Noise”

The biggest win from DHI isn’t just security, it’s reducing the operational burden of security. Fewer packages means fewer CVEs to investigate, document, and explain to customers. For teams without dedicated security staff, this reclaimed time is invaluable.

2. Compliance-Friendly Defaults

HIPAA requires covered entities to implement technical safeguards including access controls and audit controls. DHI’s non-root default and minimal attack surface align with these requirements out of the box. For companies pursuing SOC 2 Type 2 certification, which Medplum implemented from Day 1, or HITRUST certification, DHI provides a stronger foundation for the technical controls auditors evaluate.

3. Reduced Audit Surface

When security teams audit container configurations, DHI provides a cleaner story. Instead of explaining custom hardening scripts or why certain CVEs don’t apply, teams can point to Docker’s documented hardening methodology, SLSA Level 3 provenance, and independent security validation by SRLabs. This is particularly valuable during enterprise sales cycles where customers scan vendor images as part of due diligence.

4. Practicing What You Preach

For platforms like Medplum that help customers achieve compliance, using hardened images isn’t just good security, it’s good business. When you’re helping healthcare organizations meet regulatory requirements, your own infrastructure needs to set the example.

5. Faster Security Response

With DHI Enterprise, critical CVEs are patched within 7 days. For healthcare organizations where security incidents can have regulatory implications, this SLA provides meaningful risk reduction and a concrete commitment to share with customers.

Conclusion

Medplum’s migration to Docker Hardened Images demonstrates that improving container security doesn’t have to be painful. With minimal code changes (54 additions and 52 deletions) they achieved:

Secure-by-Default images that meet enterprise requirements

Automatic non-root execution

Dramatically reduced CVE surface

Simplified Dockerfiles with no manual hardening scripts

Less “security toil” for their engineering team

A stronger compliance story for enterprise customers

By offloading OS-level hardening to Docker, Medplum can focus on what they do best: building healthcare infrastructure while their security posture improves automatically with each DHI update.

For a platform with 500,000+ Docker Hub pulls serving healthcare organizations worldwide, this migration shows that DHI is ready for production workloads at scale. More importantly, it shows that security improvements can actually reduce operational burden rather than add to it.

For platforms helping others achieve compliance, practicing what you preach matters. With Docker Hardened Images, that just got a lot easier.

Ready to harden your containers? Explore the Docker Hardened Images documentation or browse the free DHI catalog to find hardened versions of your favorite base images.

Resources

Medplum DHI Pull Request

Medplum GitHub Repository

Docker Hardened Images Documentation

DHI Free Announcement

DHI Node.js Guide

Quelle: https://blog.docker.com/feed/
The Multi-Model Database for AI Agents: Deploy SurrealDB with Docker Extension

When it comes to building dynamic and real-work solutions, developers need to stitch multiple databases (relational, document, graph, vector, time-series, search) together and build complex API layers to integrate them. This generates significant complexity, cost, and operational risk, and reduces speed of innovation. More often than not, developers end up focusing on building glue code and managing infrastructure rather than building application logic. For AI use cases, using multiple databases means AI Agents have fragmented data, context and memory, producing bad outputs at high latency.

Enter SurrealDB.

SurrealDB is a multi-model database built in Rust that unifies document, graph, relational, time-series, geospatial, key-value, and vector data into a single engine. Its SQL-like query language, SurrealQL, lets you traverse graphs, perform vector search, and query structured data – all in one statement.

Designed for data-intensive workloads like AI agent memory, knowledge graphs, real-time applications, and edge deployments, SurrealDB runs as a single binary anywhere: embedded in your app, in the browser via WebAssembly, at the edge, or as a distributed cluster.

What problem does SurrealDB solve?

Modern AI systems place very different demands on data infrastructure than traditional applications. SurrealDB addresses these pressures directly:

Single runtime for multiple data models – AI systems frequently combine vector search, graph traversal, document storage, real-time state, and relational data in the same request path. SurrealDB supports these models natively in one engine, avoiding brittle cross-database APIs, ETL pipelines, and consistency gaps.

Low-latency access to changing context – Voice agents, interactive assistants, and stateful agents are sensitive to both latency and data freshness. SurrealDB’s query model and real-time features serve up-to-date context without polling or background sync jobs.

Reduced system complexity – Replacing multiple specialized databases with a single multi-model store reduces services, APIs, and failure modes. This simplifies deployment, debugging, and long-term maintenance.

Faster iteration on data-heavy features – Opt in schemas definitions and expressive queries let teams evolve data models alongside AI features without large migrations. This is particularly useful when experimenting with embeddings, relationships, or agent memory structures.

Built-in primitives for common AI patterns – Native support for vectors, graphs, and transactional consistency enables RAG, graph-augmented retrieval, recommendation pipelines, and agent state management – without external systems or custom glue code.

In this article, you’ll see how to build a WhatsApp RAG chatbot using SurrealDB Docker Extension. You’ll learn how SurrealDB Docker Extension powers an intelligent WhatsApp chatbot that turns your chat history into searchable, AI-enhanced conversations with vector embeddings and precise source citations.

Understanding SurrealDB Architecture

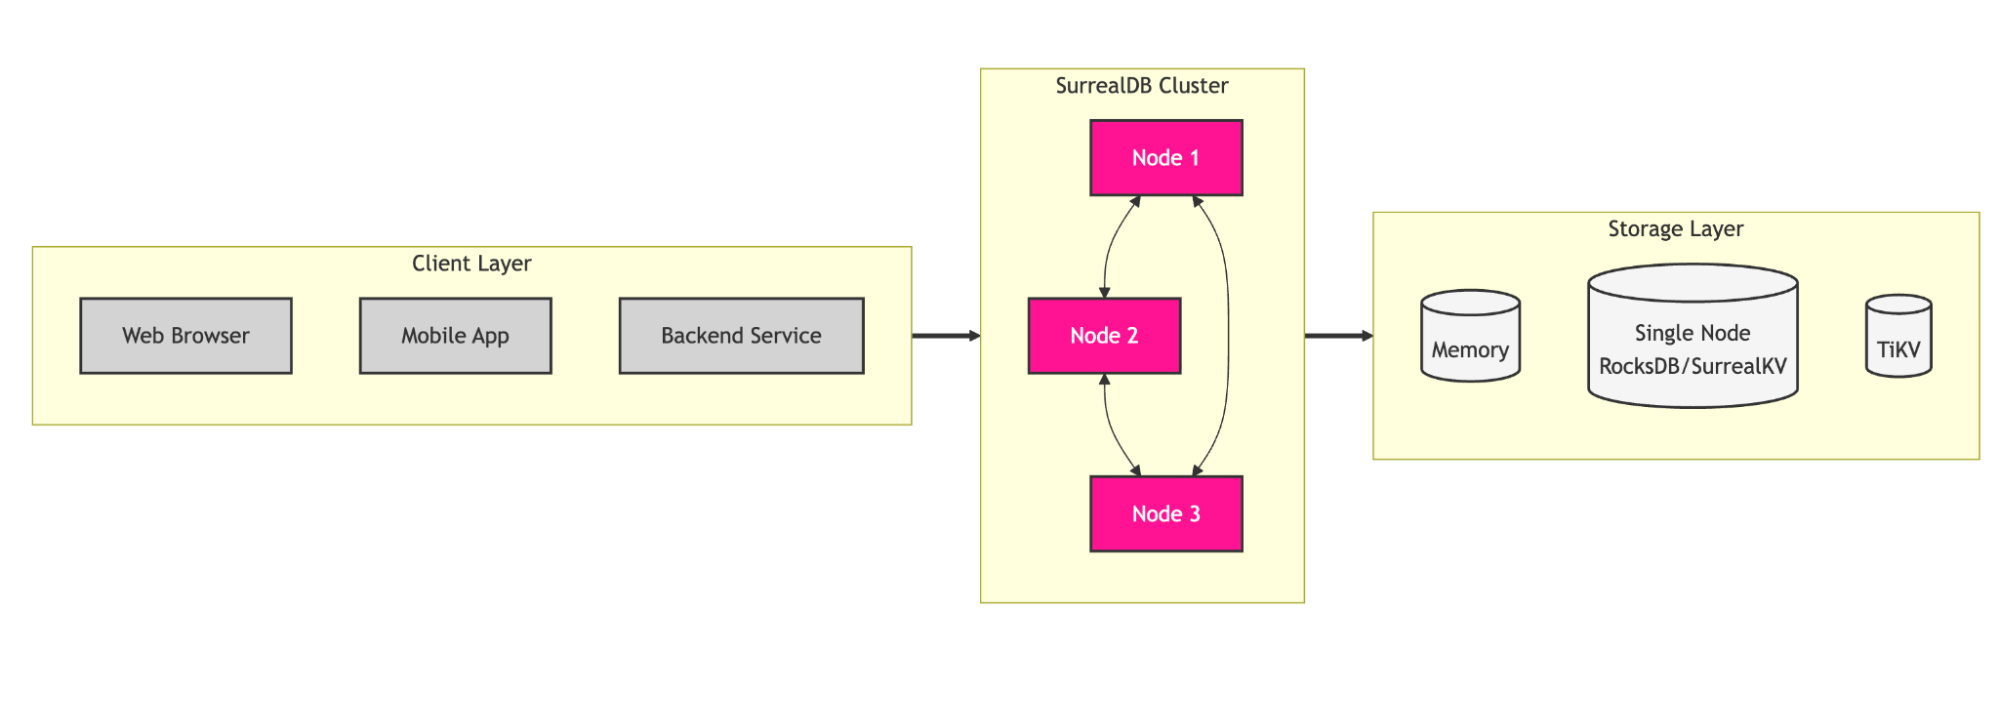
SurrealDB’s architecture unifies multiple data models within a single database engine, eliminating the need for separate systems and synchronization logic (figure below).

Caption: SurrealDB Architecture diagram

Caption: Architecture diagram of SurrealDB showing a unified multi-model database with real-time capabilities. (more information at https://surrealdb.com/docs/surrealdb/introduction/architecture)

With SurrealDB, you can:

Model complex relationships using graph traversal syntax (e.g., ->bought_together->product)

Store flexible documents alongside structured relational tables

Subscribe to real-time changes with LIVE SELECT queries that push updates instantly

Ensure data consistency with ACID-compliant transactions across all models

Learn more about SurrealDB’s architecture and key features on the official documentation.

How does Surreal work?

SurrealDB separates storage from compute, enabling you to scale these independently without the need to manually shard your data.

The query layer (otherwise known as the compute layer) handles queries from the client, analyzing which records need to be selected, created, updated, or deleted.

The storage layer handles the storage of the data for the query layer. By scaling storage nodes, you are able to increase the amount of supported data for each deployment.

SurrealDB supports all the way from single-node to highly scalable fault-tolerant deployments with large amounts of data.

For more information, see https://surrealdb.com/docs/surrealdb/introduction/architecture. 

Why should you run SurrealDB as a Docker Extension

For developers already using Docker Desktop, running SurrealDB as an extension eliminates friction. There’s no separate installation, no dependency management, no configuration files – just a single click from the Extensions Marketplace.

Docker provides the ideal environment to bundle and run SurrealDB in a lightweight, isolated container. This encapsulation ensures consistent behavior across macOS, Windows, and Linux, so what works on your laptop works identically in staging.

The Docker Desktop Extension includes:

Visual query editor with SurrealQL syntax highlighting

Real-time data explorer showing live updates as records change

Schema visualization for tables and relationships

Connection management to switch between local and remote instances

Built-in backup/restore for easy data export and import

With Docker Desktop as the only prerequisite, you can go from zero to a running SurrealDB instance in under a minute.

Getting Started

To begin, download and install Docker Desktop on your machine. Then follow these steps:

Open Docker Desktop and select Extensions in the left sidebar

Switch to the Browse tab

In the Filters dropdown, select the Database category

Find SurrealDB and click Install

Caption: Installing the SurrealDB Extension from Docker Desktop’s Extensions Marketplace.

Real-World Example

Smart Team Communication Assistant

Imagine searching through months of team WhatsApp conversations to answer the question: “What did we decide about the marketing campaign budget?”

Traditional keyword search fails, but RAG with SurrealDB and LangChain solves this by combining semantic vector search with relationship graphs.

This architecture analyzes group chats (WhatsApp, Instagram, Slack) by storing conversations as vector embeddings while simultaneously building a knowledge graph linking conversations through extracted keywords like “budget,” “marketing,” and “decision.” When queried, the system retrieves relevant context using both similarity matching and graph traversal, delivering accurate answers about past discussions, decisions, and action items even when phrased differently than the original conversation.

This project is inspired by Multi-model RAG with LangChain | GitHub Example

1. Clone the repository:

git clone https://github.com/Raveendiran-RR/surrealdb-rag-demo

2. Enable Docker Model Runner by visiting  Docker Desktop  > Settings > AI

Caption: Enable Docker Model Runner in Docker Desktop > settings > AI

3. Pull llama3.2 model from Docker Hub

Search for llama 3.2 under Models > Docker Hub and pull the right model.

Caption:  Pull the Docker model llama3.2

4. Download the embeddinggemma model from Docker Hub

Caption: Click on Models > Search for embeddinggemma > download the model

5. Run this command to connect to the persistent surrealDB container

Browse to the directory where you have cloned the repository

Create directory “mydata”

mkdir -p mydata

6. Run this command:

docker run -d –name demo_data
-p 8002:8000
-v "$(pwd)/mydata:/mydata"
surrealdb/surrealdb:latest
start –log debug –user root –pass root
rocksdb://mydata

Note: use the path based on the operating system. 

For windows , use rocksdb://mydata

For linux and macOS, use rocksdb:/mydata

7. Open SurrealDB Docker Extension and connect with SurrealDB.

Caption: Connecting to SurrealDB through Docker Desktop Extension

Connection name: RAGBot

Remote address: http://localhost:8002

Username: root | password: root

Click on Create Connection

8. Run the setup instructions 

9. Upload the whatsapp chat

Start the UI for the RAG bot (http://localhost:8080)

Caption: Create connection to the SurrealDB Docker container

10. Start chatting with the RAG bot and have fun 

11. We can verify the correctness data in SurrealDB list 

Ensure that you connect to the right namespace (whatsapp) and database (chats)

python3 load_whatsapp.py
python3 rag_chat_ui.py

Caption: connect to the “whatsapp” namespace and “chats” database

Caption: Data stored as vectors in SurrealDB

Caption: Interact with the RAG bot UI where it gives you the answer and exact reference for it 

Using this chat bot, now you can get information about the chat.txt file that was ingested. You can also verify the information in the query editor as shown below when you can run custom queries to validate the results from the chat bot. You can ingest new messages through the load_whatsapp.py file, please ensure that the message format is same as in the sample whatsChatExport.txt file.

Learn more about SurrealQL here.

Caption: SurrealDB Query editor in the Docker Desktop Extension

Conclusion

The SurrealDB Docker Extension offers an accessible and powerful solution for developers building data-intensive applications – especially those working with AI agents, knowledge graphs, and real-time systems. Its multi-model architecture eliminates the need to stitch together separate databases, letting you store documents, traverse graphs, query vectors, and subscribe to live updates from a single engine.

With Docker Desktop integration, getting started takes seconds rather than hours. No configuration files, no dependency management – just install the extension and start building. The visual query editor and real-time data explorer make it easy to prototype schemas, test queries, and inspect data as it changes.

Whether you’re building agent memory systems, real-time recommendation engines, or simply looking to consolidate a sprawling database stack, SurrealDB’s Docker Extension provides an intuitive path forward. Install it today and see how a unified data layer can simplify your architecture.

If you have questions or want to connect with other SurrealDB users, join the SurrealDB community on Discord.

Learn More

Install the SurrealDB Docker Extension

Get the latest release of Docker Desktop

SurrealDB documentation

Vote on what’s next! Check out our public roadmap

Have questions? The Docker community is here to help

New to Docker? Get started

Quelle: https://blog.docker.com/feed/
Running NanoClaw in a Docker Shell Sandbox

Ever wanted to run a personal AI assistant that monitors your WhatsApp messages 24/7, but worried about giving it access to your entire system? Docker Sandboxes’ new shell sandbox type is the perfect solution. In this post, I’ll show you how to run NanoClaw, a lightweight Claude-powered WhatsApp assistant, inside a secure, isolated Docker sandbox.

What is the Shell Sandbox?

Docker Sandboxes provides pre-configured environments for running AI coding agents like Claude Code, Gemini CLI, and others. But what if you want to run a different agent or tool that isn’t built-in?That’s where the shell sandbox comes in. It’s a minimal sandbox that drops you into an interactive bash shell inside an isolated microVM. No pre-installed agent, no opinions — just a clean Ubuntu environment with Node.js, Python, git, and common dev tools. You install whatever you need.

Why Run NanoClaw in a Sandbox?

NanoClaw already runs its agents in containers, so it’s security-conscious by design. But running the entire NanoClaw process inside a Docker sandbox adds another layer:

Filesystem isolation – NanoClaw can only see the workspace directory you mount, not your home directory

Credential management – API keys are injected via Docker’s proxy, never stored inside the sandbox

Clean environment – No conflicts with your host’s Node.js version or global packages

Disposability – Nuke it and start fresh anytime with docker sandbox rm

Prerequisites

Docker Desktop installed and running

Docker Sandboxes CLI (docker sandbox command available) (v.0.12.0 available in the nightly build as of Feb 13)

An Anthropic API key in an env variable

Setting It Up

Create the sandbox

Pick a directory on your host that will be mounted as the workspace inside the sandbox. This is the only part of your filesystem the sandbox can see:

mkdir -p ~/nanoclaw-workspace
docker sandbox create –name nanoclaw shell ~/nanoclaw-workspace

Connect to it

docker sandbox run nanoclaw

You’re now inside the sandbox – an Ubuntu shell running in an isolated VM. Everything from here on happens inside the sandbox.

Install Claude Code

The shell sandbox comes with Node.js 20 pre-installed, so we can install Claude Code directly via npm:

npm install -g @anthropic-ai/claude-code

Configure the API key

This is the one extra step needed in a shell sandbox. The built-in claude sandbox type does this automatically, but since we’re in a plain shell, we need to tell Claude Code to get its API key from Docker’s credential proxy:

mkdir -p ~/.claude && cat > ~/.claude/settings.json << 'EOF'
{
"apiKeyHelper": "echo proxy-managed",
"defaultMode": "bypassPermissions",
"bypassPermissionsModeAccepted": true
}
EOF

What this does: apiKeyHelper tells Claude Code to run echo proxy-managed to get its API key. The sandbox’s network proxy intercepts outgoing API calls and swaps this sentinel value for your real Anthropic key, so the actual key never exists inside the sandbox.

Clone NanoClaw and install dependencies

cd ~/workspace
git clone https://github.com/†/nanoclaw.git
cd nanoclaw
npm install

Run Claude and set up NanoClaw

NanoClaw uses Claude Code for its initial setup – configuring WhatsApp authentication, the database, and the container runtime:

claude

Once Claude starts, run /setup and follow the prompts. Claude will walk you through scanning a WhatsApp QR code and configuring everything else.

Start NanoClaw

After setup completes, start the assistant:

npm start

NanoClaw is now running and listening for WhatsApp messages inside the sandbox.

Managing the Sandbox

# List all sandboxes
docker sandbox ls

# Stop the sandbox (stops NanoClaw too)
docker sandbox stop nanoclaw

# Start it again
docker sandbox start nanoclaw

# Remove it entirely
docker sandbox rm nanoclaw

What Else Could You Run?

The shell sandbox isn’t specific to NanoClaw. Anything that runs on Linux and talks to AI APIs is a good fit:

Custom agents built with the Claude Agent SDK or any other AI agent: Claude code, Codex, Github Copilot, OpenCode, Kiro, and more. 

AI-powered bots and automation scripts

Experimental tools you don’t want running on your host

The pattern is always the same: create a sandbox, install what you need, configure credentials via the proxy, and run it.

docker sandbox create –name my-shell shell ~/my-workspace
docker sandbox run my-shell

Quelle: https://blog.docker.com/feed/
How to solve the context size issues with context packing with Docker Model Runner and Agentic Compose

If you’ve worked with local language models, you’ve probably run into the context window limit, especially when using smaller models on less powerful machines. While it’s an unavoidable constraint, techniques like context packing make it surprisingly manageable.

Hello, I’m Philippe, and I am a Principal Solutions Architect helping customers with their usage of Docker.  In my previous blog post, I wrote about how to make a very small model useful by using RAG. I had limited the message history to 2 to keep the context length short.

But in some cases, you’ll need to keep more messages in your history. For example, a long conversation to generate code:

– generate an http server server in golang
– add a human structure and a list of humans
– add a handler to add a human to the list
– add a handler to list all humans
– add a handler to get a human by id
– etc…

Let’s imagine we have a conversation for which we want to keep 10 messages in the history. Moreover, we’re using a very verbose model (which a lot of tokens), so we’ll quickly encounter this type of error:

error: {
code: 400,
message: 'request (8860 tokens) exceeds the available context size (8192 tokens), try increasing it',
type: 'exceed_context_size_error',
n_prompt_tokens: 8860,
n_ctx: 8192
},
code: 400,
param: undefined,
type: 'exceed_context_size_error'
}

What happened?

Understanding context windows and their limits in local LLMs

Our LLM has a context window, which has a limited size. This means that if the conversation becomes too long… It will bug out.

This window is the total number of tokens the model can process at once, like a short-term working memory.  Read this IBM article for a deep dive on context window

In our example in the code snippet above, this size was set to 8192 tokens for LLM engines that power local LLM, like Docker Model Runner, Ollama, Llamacpp, …

This window includes everything: system prompt, user message, history, injected documents, and the generated response. Refer to this Redis post for more info. 

Example: if the model has 32k context, the sum (input + history + generated output) must remain ≤ 32k tokens. Learn more here.  

It’s possible to change the default context size (up or down) in the compose.yml file:

models:
chat-model:
model: hf.co/qwen/qwen2.5-coder-3b-instruct-gguf:q4_k_m
# Increased context size for better handling of larger inputs
context_size: 16384

You can also do this with Docker with the following command: docker model configure –context-size 8192 ai/qwen2.5-coder `

And so we solve the problem, but only part of the problem. Indeed, it’s not guaranteed that your model supports a larger context size (like 16384), and even if it does, it can very quickly degrade the model’s performance.

Thus, with hf.co/qwen/qwen2.5-coder-3b-instruct-gguf:q4_k_m, when the number of tokens in the context approaches 16384 tokens, generation can become (much) slower (at least on my machine). Again, this will depend on the model’s capacity (read its documentation). And remember, the smaller the model, the harder it will be to handle a large context and stay focused.

Tips: always provide an option (a /clear command for example) in your application to empty the message list, or to reduce it. Automatic or manual. Keep the initial system instructions though.

So we’re at an impasse. How can we go further with our small models?

Well, there is still a solution, which is called context packing.

Using context packing to fit more information into limited context windows

We can’t indefinitely increase the context size. To still manage to fit more information in the context, we can use a technique called “context packing”, which consists of having the model itself summarize previous messages (or entrust the task to another model), and replace the history with this summary and thus free up space in the context.So we decide that from a certain token limit, we’ll have the history of previous messages summarized, and replace this history with the generated summary.I’ve therefore modified my example to add a context packing step. For the exercise, I decided to use another model to do the summarization.

Modification of the compose.yml file

I added a new model in the compose.yml file: ai/qwen2.5:1.5B-F16

models:
chat-model:
model: hf.co/qwen/qwen2.5-coder-3b-instruct-gguf:q4_k_m

embedding-model:
model: ai/embeddinggemma:latest

context-packing-model:
model: ai/qwen2.5:1.5B-F16

Then:

I added the model in the models section of the service that runs our program.

I increased the number of messages in the history to 10 (instead of 2 previously).

I set a token limit at 5120 before triggering context compression.

And finally, I defined instructions for the “context packing” model, asking it to summarize previous messages.

excerpt from the service:

golang-expert-v3:
build:
context: .
dockerfile: Dockerfile
environment:

HISTORY_MESSAGES: 10
TOKEN_LIMIT: 5120
# …

configs:
– source: system.instructions.md
target: /app/system.instructions.md
– source: context-packing.instructions.md
target: /app/context-packing.instructions.md

models:
chat-model:
endpoint_var: MODEL_RUNNER_BASE_URL
model_var: MODEL_RUNNER_LLM_CHAT

context-packing-model:
endpoint_var: MODEL_RUNNER_BASE_URL
model_var: MODEL_RUNNER_LLM_CONTEXT_PACKING

embedding-model:
endpoint_var: MODEL_RUNNER_BASE_URL
model_var: MODEL_RUNNER_LLM_EMBEDDING

You’ll find the complete version of the file here: compose.yml

System instructions for the context packing model

Still in the compose.yml file, I added a new system instruction for the “context packing” model, in a context-packing.instructions.md file:

context-packing.instructions.md:
content: |
You are a context packing assistant.
Your task is to condense and summarize provided content to fit within token limits while preserving essential information.
Always:
– Retain key facts, figures, and concepts
– Remove redundant or less important details
– Ensure clarity and coherence in the condensed output
– Aim to reduce the token count significantly without losing critical information

The goal is to help fit more relevant information into a limited context window for downstream processing.

All that’s left is to implement the context packing logic in the assistant’s code.

 Applying context packing to the assistant’s code

First, I define the connection with the context packing model in the Setup part of my assistant:

const contextPackingModel = new ChatOpenAI({
model: process.env.MODEL_RUNNER_LLM_CONTEXT_PACKING || `ai/qwen2.5:1.5B-F16`,
apiKey: "",
configuration: {
baseURL: process.env.MODEL_RUNNER_BASE_URL || "http://localhost:12434/engines/llama.cpp/v1/",
},
temperature: 0.0,
top_p: 0.9,
presencePenalty: 2.2,
});

I also retrieve the system instructions I defined for this model, as well as the token limit:

let contextPackingInstructions = fs.readFileSync('/app/context-packing.instructions.md', 'utf8');

let tokenLimit = parseInt(process.env.TOKEN_LIMIT) || 7168

Once in the conversation loop, I’ll estimate the number of tokens consumed by previous messages, and if this number exceeds the defined limit, I’ll call the context packing model to summarize the history of previous messages and replace this history with the generated summary (the assistant-type message: [“assistant”, summary]). Then I continue generating the response using the main model.

excerpt from the conversation loop:

let estimatedTokenCount = messages.reduce((acc, [role, content]) => acc + Math.ceil(content.length / 4), 0);
console.log(` Estimated token count for messages: ${estimatedTokenCount} tokens`);

if (estimatedTokenCount >= tokenLimit) {
console.log(` Warning: Estimated token count (${estimatedTokenCount}) exceeds the model's context limit (${tokenLimit}). Compressing conversation history…`);

// Calculate original history size
const originalHistorySize = history.reduce((acc, [role, content]) => acc + Math.ceil(content.length / 4), 0);

// Prepare messages for context packing
const contextPackingMessages = [
["system", contextPackingInstructions],
…history,
["user", "Please summarize the above conversation history to reduce its size while retaining important information."]
];

// Generate summary using context packing model
console.log(" Generating summary with context packing model…");
let summary = '';
const summaryStream = await contextPackingModel.stream(contextPackingMessages);
for await (const chunk of summaryStream) {
summary += chunk.content;
process.stdout.write('x1b[32m' + chunk.content + 'x1b[0m');
}
console.log();

// Calculate compressed size
const compressedSize = Math.ceil(summary.length / 4);
const reductionPercentage = ((originalHistorySize – compressedSize) / originalHistorySize * 100).toFixed(2);

console.log(` History compressed: ${originalHistorySize} tokens → ${compressedSize} tokens (${reductionPercentage}% reduction)`);

// Replace all history with the summary
conversationMemory.set("default-session-id", [["assistant", summary]]);

estimatedTokenCount = compressedSize

// Rebuild messages with compressed history
messages = [
["assistant", summary],
["system", systemInstructions],
["system", knowledgeBase],
["user", userMessage]
];
}

You’ll find the complete version of the code here: index.js

All that’s left is to test our assistant and have it hold a long conversation, to see context packing in action.

docker compose up –build -d
docker compose exec golang-expert-v3 node index.js

And after a while in the conversation, you should see the warning message about the token limit, followed by the summary generated by the context packing model, and finally, the reduction in the number of tokens in the history:

Estimated token count for messages: 5984 tokens
Warning: Estimated token count (5984) exceeds the model's context limit (5120). Compressing conversation history…
Generating summary with context packing model…
Sure, here's a summary of the conversation:

1. The user asked for an example in Go of creating an HTTP server.
2. The assistant provided a simple example in Go that creates an HTTP server and handles GET requests to display "Hello, World!".
3. The user requested an equivalent example in Java.
4. The assistant presented a Java implementation that uses the `java.net.http` package to create an HTTP server and handle incoming requests.

The conversation focused on providing examples of creating HTTP servers in both Go and Java, with the goal of reducing the token count while retaining essential information.
History compressed: 4886 tokens → 153 tokens (96.87% reduction)

This way, we ensure that our assistant can handle a long conversation while maintaining good generation performance.

Summary

The context window is an unavoidable constraint when working with local language models, particularly with small models and on machines with limited resources. However, by using techniques like context packing, you can easily work around this limitation. Using Docker Model Runner and Agentic Compose, you can implement this pattern to support long, verbose conversations without overwhelming your model.

All the source code is available on Codeberg: context-packing. Give it a try! 
Quelle: https://blog.docker.com/feed/
Hardened Images Are Free. Now What?

Docker Hardened Images are now free, covering Alpine, Debian, and over 1,000 images including databases, runtimes, and message buses. For security teams, this changes the economics of container vulnerability management.

DHI includes security fixes from Docker’s security team, which simplifies security response. Platform teams can pull the patched base image and redeploy quickly. But free hardened images raise a question: how should this change your security practice? Here’s how our thinking is evolving at Docker.

What Changes (and What Doesn’t)

DHI gives you a security “waterline.” Below the waterline, Docker owns vulnerability management. Above it, you do. When a scanner flags something in a DHI layer, it’s not actionable by your team. Everything above the DHI boundary remains yours.

The scope depends on which DHI images you use. A hardened Python image covers the OS and runtime, shrinking your surface to application code and direct dependencies. A hardened base image with your own runtime on top sets the boundary lower. The goal is to push your waterline as high as possible.

Vulnerabilities don’t disappear. Below the waterline, you need to pull patched DHI images promptly. Above it, you still own application code, dependencies, and anything you’ve layered on top.

Supply Chain Isolation

DHI provides supply chain isolation beyond CVE remediation.

Community images like python:3.11 carry implicit trust assumptions: no compromised maintainer credentials, no malicious layer injection via tag overwrite, no tampering since your last pull. The Shai Hulud campaign(s) demonstrated the consequences when attackers exploit stolen PATs and tag mutability to propagate through the ecosystem.

DHI images come from a controlled namespace where Docker rebuilds from source with review processes and cooldown periods. Supply chain attacks that burn through community images stop at the DHI boundary. You’re not immune to all supply chain risk, but you’ve eliminated exposure to attacks that exploit community image trust models.

This is a different value proposition than CVE reduction. It’s isolation from an entire class of increasingly sophisticated attacks.

The Container Image as the Unit of Assessment

Security scanning is fragmented. Dependency scanning, SAST, and SCA all run in different contexts, and none has full visibility into how everything fits together at deployment time.

The container image is where all of this converges. It’s the actual deployment artifact, which makes it the checkpoint where you can guarantee uniform enforcement from developer workstation to production. The same evaluation criteria you run locally after docker build can be identical to what runs in CI and what gates production deployments.

This doesn’t need to replace earlier pipeline scanning altogether. It means the image is where you enforce policy consistency and build a coherent audit trail that maps directly to what you’re deploying.

Policy-Driven Automation

Every enterprise has a vulnerability management policy. The gap is usually between policy (PDFs and wikis) and practice (spreadsheets and Jira tickets).

DHI makes that gap easier to close by dramatically reducing the volume of findings that require policy decisions in the first place. When your scanner returns 50 CVEs instead of 500, even basic severity filtering becomes a workable triage system rather than an overwhelming backlog.

A simple, achievable policy might include the following:

High and critical severity vulnerabilities require remediation or documented exception

Medium and lower severity issues are accepted with periodic review

CISA KEV vulnerabilities are always in scope

Most scanning platforms support this level of filtering natively, including Grype, Trivy, Snyk, Wiz, Prisma Cloud, Aqua, and Docker Scout. You define your severity thresholds, apply them automatically, and surface only what requires human judgment.

For teams wanting tighter integration with DHI coverage data, Docker Scout evaluates policies against DHI status directly. Third-party scanners can achieve similar results through pipeline scripting or by exporting DHI coverage information for comparison.

The goal isn’t perfect automation but rather reducing noise enough that your existing policy becomes enforceable without burning out your engineers.

VEX: What You Can Do Today

Docker Hardened Images ship with VEX attestations that suppress CVEs Docker has assessed as not exploitable in context. The natural extension is for your teams to add their own VEX statements for application-layer findings.

Here’s what your security team can do today:

Consume DHI VEX data. Grype (v0.65+), Trivy, Wiz, and Docker Scout all ingest DHI VEX attestations automatically or via flags. Scanners without VEX support can still use extracted attestations to inform manual triage.

Write your own VEX statements. OpenVEX provides the JSON format. Use vexctl to generate and sign statements.

Attach VEX to images. Docker recommends docker scout attestation add for attaching VEX to images already in a registry:

docker scout attestation add
–file ./cve-2024-1234.vex.json
–predicate-type https://openvex.dev/ns/v0.2.0
<image>

Alternatively, COPY VEX documents into the image filesystem at build time, though this prevents updates without rebuilding.

Configure scanner VEX ingestion. The workflow: scan, identify investigated findings, document as VEX, feed back into scanner config. Future scans automatically suppress assessed vulnerabilities.

Compliance: What DHI Actually Provides

Compliance frameworks such as ISO 27001, SOC 2, and the EU Cyber Resilience Act require systematic, auditable vulnerability management. DHI addresses specific control requirements:

Vulnerability management documentation (ISO 27001  A.8.8. , SOC 2 CC7.1). The waterline model provides a defensible answer to “how do you handle base image vulnerabilities?” Point to DHI, explain the attestation model, show policy for everything above the waterline.

Continuous monitoring evidence. DHI images rebuild and re-scan on a defined cadence. New digests mean current assessments. Combined with your scanner’s continuous monitoring, you demonstrate ongoing evaluation rather than point-in-time checks.

Remediation traceability. VEX attestations create machine-readable records of how each CVE was handled. When auditors ask about specific CVEs in specific deployments, you have answers tied to image digests and timestamps.

CRA alignment. The Cyber Resilience Act requires “due diligence” vulnerability handling and SBOMs. DHI images include SBOM attestations, and VEX aligns with CRA expectations for exploitability documentation.

This won’t satisfy every audit question, but it provides the foundation most organizations lack.

What to Do After You Read This Post

Identify high-volume base images. Check Docker Hub’s Hardened Images catalog (My Hub → Hardened Images → Catalog) for coverage of your most-used images (Python, Node, Go, Alpine, Debian).

Swap one image. Pick a non-critical service, change the FROM line to DHI equivalent, rebuild, scan, compare results.

Configure policy-based filtering. Set up your scanner to distinguish DHI-covered vulnerabilities from application-layer findings. Use Docker Scout or Wiz for native VEX integration, or configure Grype/Trivy ignore policies based on extracted VEX data.

Document your waterline. Write down what DHI covers and what remains your responsibility. This becomes your policy reference and audit documentation.

Start a VEX practice. Convert one informally-documented vulnerability assessment into a VEX statement and attach it to the relevant image.

DHI solves specific, expensive problems around base image vulnerabilities and supply chain trust. The opportunity is building a practice around it that scales.

The Bigger Picture

DHI coverage is expanding. Today it might cover your OS layer, tomorrow it extends through runtimes and into hardened libraries. Build your framework to be agnostic to where the boundary sits. The question is always the same, though, namely —  what has Docker attested to, and what remains yours to assess?

The methodology Docker uses for DHI (policy-driven assessment, VEX attestations, auditable decisions) extends into your application layer. We can’t own your custom code, but we can provide the framework for consistent practices above the waterline. Whether you use Scout, Wiz, Grype, Trivy, or another scanner, the pattern is the same. You can let DHI handle what it covers, automate policy for what remains, and document decisions in formats that travel with artifacts.

At Docker, we’re using DHI internally to build this vulnerability management model. The framework stays constant regardless of how much of our stack is hardened today versus a year from now. Only the boundary moves.

The hardened images are free. The VEX attestations are included. What’s left is integrating these pieces into a coherent security practice where the container is the unit of truth, policy drives automation, and every vulnerability decision is documented by default.

For organizations that require stronger guarantees, FIPS-enabled and STIG-ready images, and customizations, DHI Enterprise is tailor made for those use cases. Get in touch with the Docker team if you would like a demo. If you’re still exploring, take a look at the catalog (no-signup needed) or take DHI Enterprise for a spin with a free trial.

Quelle: https://blog.docker.com/feed/
Reduce Vulnerability Noise with VEX: Wiz + Docker Hardened Images

Open source components power most modern applications. A new generation of hardened container images can establish a more secure foundation, but even with hardened images, vulnerability scanners often return dozens or hundreds of CVEs with little prioritization. This noise slows teams down and complicates security triage. The VEX (Vulnerability Exploitability eXchange) standard addresses the problem by providing information on whether a specific vulnerability actually impacts an organization’s application stack and infrastructure.

A new integration between Docker Hardened Images (DHI) and Wiz CLI now gives security and platform teams accurate reachability insights by analyzing VEX data. Wiz worked with Docker to tune its scanners to properly ingest and parse the VEX statements included with every one of the more than 1,000 DHI images in the catalog. The integration helps users cut through vulnerability noise with scan results that deliver clear, actionable insights.

When the Wiz scanner detects a Docker Hardened Image, it pulls from the image’s VEX documents and OSV advisories to filter out false positives. For organizations already using Wiz, this means a simpler path to adopting hardened images across their container fleet. Finally, for organizations pursuing FedRAMP or other compliance certifications that specify VEX coverage, the ability of Wiz to read DHI VEX statements can accelerate compliance, reducing time to deployment and consequently time to revenue.

TL;DR

Integrate Docker with Wiz to:

Minimize false positives using VEX and OSV data

Identify base images and software components more accurately

Provide security teams with clear visibility into software bills of materials (SBOMs)

Reduce manual validation efforts by integrating detailed issue summaries into your remediation workflows

Better image quality assurance with up-to-date package metadata and SPDX snippets

Migrate to Docker Hardened Images with greater confidence

Why VEX?

VEX (Vulnerability Exploitability eXchange) is a machine-readable way for software suppliers to state whether a known vulnerability actually affects a specific product. Instead of inferring risk from dependency lists alone, VEX explicitly declares whether a vulnerability is not affected, affected, fixed, or under investigation. This matters because many scanner findings are not exploitable in real products, leading to false positives, wasted effort, and obscured real risk.VEX  enables transparent, auditable vulnerability status that security tools and customers can independently verify, unlike proprietary advisory feeds that obscure context and historical risk.

Before you begin

Ensure you have access to both your Docker and Wiz organizations;

Confirm your are using a Docker Hardened Image

Ensure you have SBOM export and scan visibility enabled in Wiz.

Identifying Docker Hardened Images via the Integration on Wiz

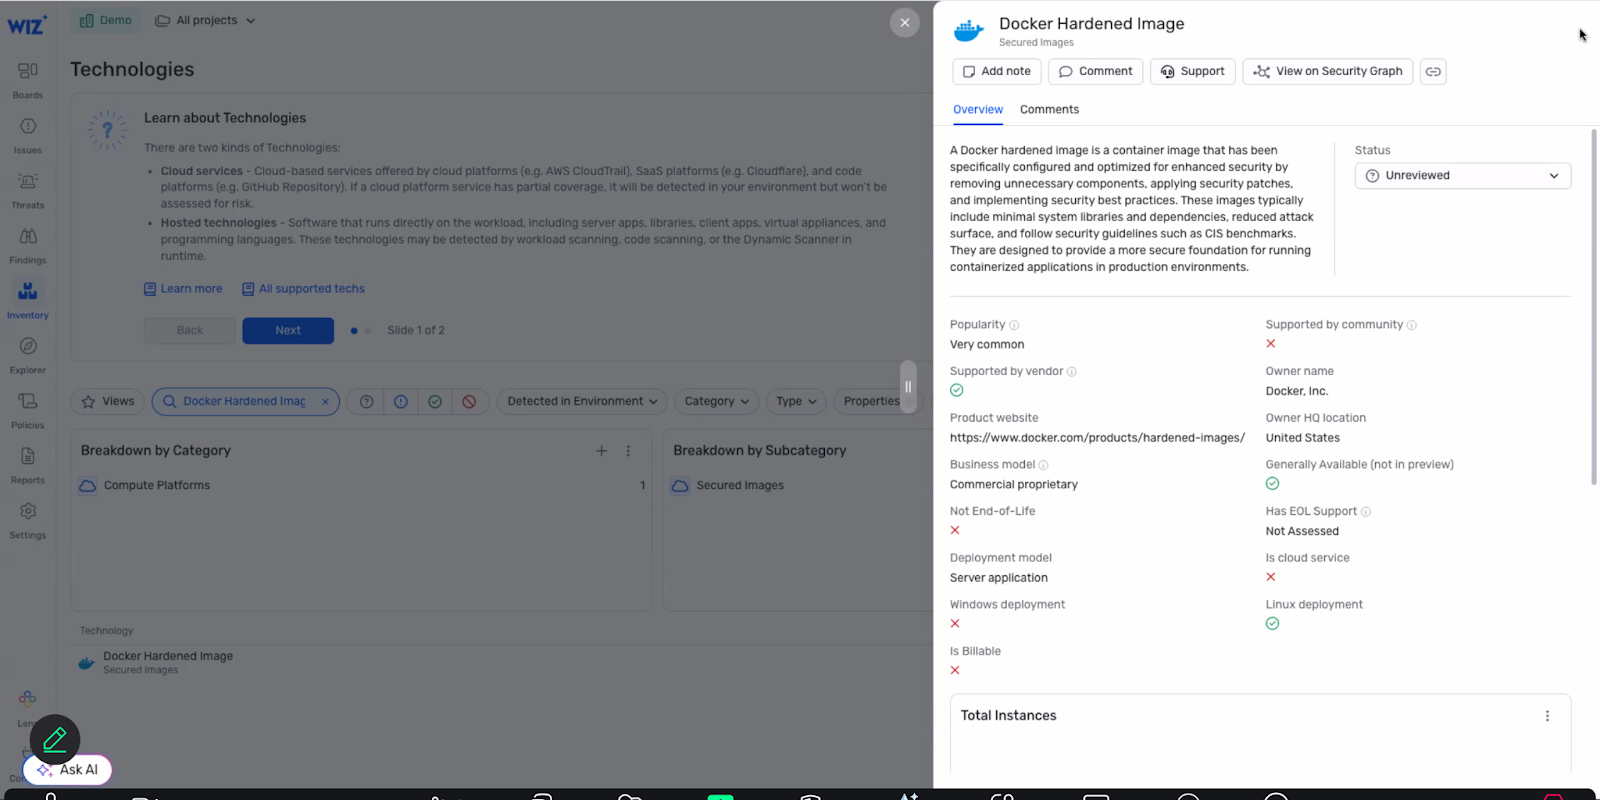
With the integration, Wiz automatically detects Docker Hardened Images. The integration consists of two main functionalities on the Wiz dashboard. First, we will verify how many resources and organizations are using Docker Hardened Images by following these steps: 

Navigate to the Wiz Docker integration page and click connect

You’ll be prompted to log in to your Wiz dashboard

Once logged in, navigate to the “Inventory” section on the left side bar of your dashboard

You’ll be redirected to the “Technology” dashboard, where Wiz detects all technologies running on customer environments. Now, look for “Docker Hardened Images” on the search bar

Wiz automatically detects the specific operating systems running on each container mounts and flags them as hardened images

Checking for vulnerabilities on the Wiz dashboard:

Once you’ve validated that Wiz can identify Docker Hardened Images, you will be able to check for vulnerabilities using Wiz’s security graph and Docker’s container metadata. In order to do that, follow these steps from the technologies tab:

Go to inventory/technologies page and filter by operating systems or search for specific technology

Click on the OS/technology to view metadata and resource count

Click to access the security graph view showing all resources running that technology

Add a condition to filter for CVEs detected on those resources. 

View all resources with their associated vulnerabilities in table or graph format

Final Check

After setup, the vulnerabilities will appear according to your pre-set policies. You’ll be able to get a detailed overview on each CVE listed, including graph visualizations for dependency relationships, severity distribution, and potential exploit paths. These insights will help you prioritize remediation efforts, track resolution progress, and ensure compliance with your organization’s security standards.

Integrating Docker Hardened Images for better software supply chain visibility

The Docker-Wiz integration is more than just a checkbox in your security checklist. It provides:

Clarity: VEX documents and accurate base image identification eliminate guesswork, providing clear, contextual vulnerability data.

Confidence: Minimized false positives through OSV advisories and Docker-provided metadata ensures security teams can trust what they see.

Control: Enhanced visibility into SBOMs and technology usage empowers teams to prioritize and manage remediation effectively.

Coverage: Full-stack integration with Wiz surfaces vulnerabilities across all Docker environments, including hardened images and source-built components.This partnership helps DevSecOps teams move fast and remain proactive against container vulnerabilities, an essential capability for modern, lean teams managing fast-paced releases, open source risk, and complex cloud-native environments.

Ready to Get Started?

If you’re already using Docker Hardened Images and Wiz, you’re just a few clicks away from reducing false positives, improving SBOM visibility, and making vulnerability data more actionable.

Check the Docker + Wiz solutions brief

Visit the Docker + Wiz integration page

Read more about VEX in our documentation

Quelle: https://blog.docker.com/feed/

Get Started with the Atlassian Rovo MCP Server Using Docker

We’re excited to announce that the remote Atlassian Rovo MCP server is now available in Docker’s MCP Catalog and Toolkit, making it easier than ever to connect AI assistants to Jira and Confluence. With just a few clicks, technical teams can use their favorite AI agents to create and update Jira issues, epics, and Confluence pages without complex setup or manual integrations.

In this post, we’ll show you how to get started with the Atlassian remote MCP server in minutes and how to use it to automate everyday workflows for product and engineering teams.

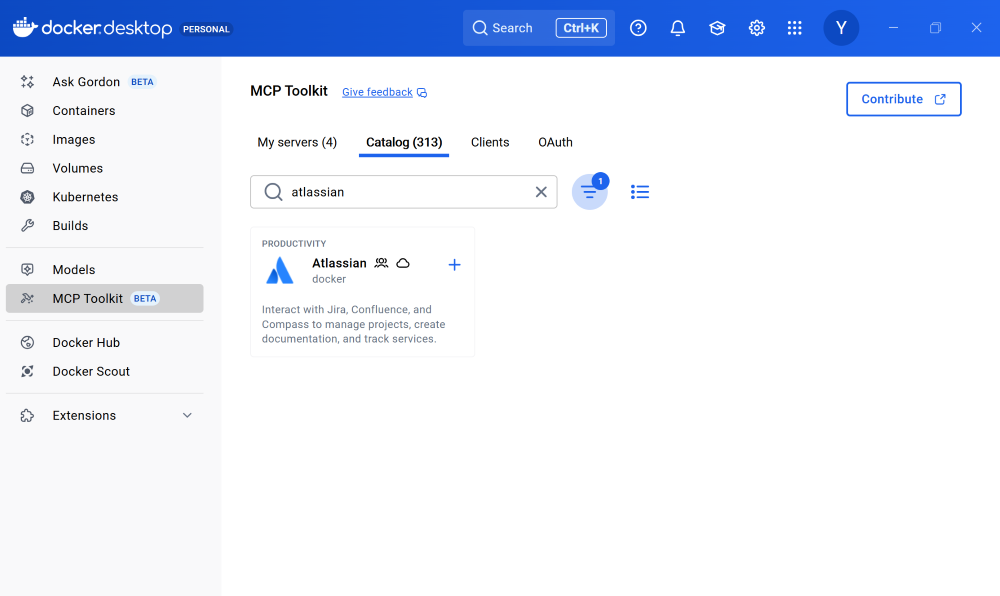
Figure 1: Discover over 300+ MCP servers including the remote Atlassian MCP server in Docker MCP Catalog.

What is the Atlassian Rovo MCP Server?

Like many teams, we rely heavily on Atlassian tools, especially Jira to plan, track, and ship product and engineering work. The Atlassian Rovo MCP server enables AI assistants and agents to interact directly with Jira and Confluence, closing the gap between where work happens and how teams want to use AI.

With the Atlassian Rovo MCP server, you can:

Create and update Jira issues and epics

Generate and edit Confluence pages

Use your preferred AI assistant or agent to automate everyday workflows

Traditionally, setting up and configuring MCP servers can be time-consuming and complex. Docker removes that friction, making it easy to get up and running securely in minutes.

Enable the Atlassian Rovo MCP Server with One Click

Docker’s MCP Catalog is a curated collection of 300+ MCP servers, including both local and remote options. It provides a reliable starting point for developers building with MCP so you don’t have to wire everything together yourself.

Prerequisites

Before you begin, make sure you have:

A machine with 8GB RAM minimum, ideally 16GB

Install Docker Desktop

To get started with the Atlassian remote MCP server:

Open Docker Desktop and click on the MCP Toolkit tab. 

Navigate to Docker MCP Catalog

Search for the Atlassian Rovo MCP server. 

Select the remote version with cloud icon

Enable it with a single click

That’s it. No manual installs. No dependency wrangling.

Why use the Atlassian Rovo MCP server with Docker

Demo by Cecilia Liu: Set up the Atlassian Rovo MCP server with Docker with just a few clicks and use it to generate Jira epics with Claude Desktop

Seamless Authentication with Built-in OAuth

The Atlassian Rovo MCP server uses Docker’s built-in OAuth, so authorization is seamless. Docker securely manages your credentials and allows you to reuse them across multiple MCP clients. You authenticate once, and you’re good to go.

Behind the scenes, this frictionless experience is powered by the MCP Toolkit, which handles environment setup and dependency management for you.

Works with Your Favorite AI Agent

Once the Atlassian Rovo MCP server is enabled, you can connect it to any MCP-compatible client.

For popular clients like Claude Desktop, Claude Code, Codex, or Gemini CLI, connecting is just one click. Just click Connect, restart Claude Desktop, and now we’re ready to go.

From there, we can ask Claude to:

Write a short PRD about MCP

Turn that PRD into Jira epics and stories

Review the generated epics and confirm they’re correct

And just like that, Jira is updated.

One Setup, Any MCP Client

Sometimes AI assistants have hiccups. Maybe you hit a daily usage limit in one tool. That’s not a blocker here.

Because the Atlassian Rovo MCP server is connected through the Docker MCP Toolkit, the setup is completely client-agnostic. Switching to another assistant like Gemini CLI or Cursor is as simple as clicking Connect. No need for reconfiguration or additional setup!

Now we can ask any connected AI assistant such as Gemini CLI to, for example, check all new unassigned Jira tickets. It just works.

Coming Soon: Share Atlassian-Based Workflows Across Teams

We’re working on new enhancements that will make Atlassian-powered workflows even more powerful and easy to share. Soon, you’ll be able to package complete workflows that combine MCP servers, clients, and configurations. Imagine a workflow that turns customer feedback into Jira tickets using Atlassian and Confluence, then shares that entire setup instantly with your team or across projects. That’s where we’re headed.

Frequently Asked Questions (FAQ)

What is the Atlassian Rovo MCP server?

The Atlassian MCP Rovo server enables AI assistants and agents to securely interact with Jira and Confluence. It allows AI tools to create and update Jira issues and epics, generate and edit Confluence pages, and automate everyday workflows for product and engineering teams.

How do I use the Atlassian Rovo MCP server with Docker? 

You can enable the Atlassian Rovo MCP server directly from Docker Desktop or CLI. Simply open the MCP Toolkit tab, search for the Atlassian MCP server, select the remote version, and enable it with one click. Connect to any MCP-compatible client. For popular tools like Claude Code, Codex, and Gemini, setup is even easier with one-click integration. 

Why use Docker to run the Atlassian Rovo MCP server?

Using Docker to run the Atlassian Rovo MCP server removes the complexity of setup, authentication, and client integration. Docker provides one-click enablement through the MCP Catalog, built-in OAuth for secure credential management, and a client-agnostic MCP Toolkit that lets teams connect any AI assistant or agent without reconfiguration so you can focus on automating Jira and Confluence workflows instead of managing infrastructure.

Less Setup. Less Context Switching. More Work Shipped.

That’s how easy it is to set up and use the Atlassian Rovo MCP server with Docker. By combining the MCP Catalog and Toolkit, Docker removes the friction from connecting AI agents to the tools teams already rely on.

Learn more

Get started with MCP Catalog and Toolkit

Explore the Docker MCP Catalog: Discover containerized, security-hardened MCP servers

Read more about the Docker MCP Toolkit: Official Documentation

Quelle: https://blog.docker.com/feed/

The 3Cs: A Framework for AI Agent Security

Every time execution models change, security frameworks need to change with them. Agents force the next shift.

The Unattended Laptop Problem

No developer would leave their laptop unattended and unlocked. The risk is obvious. A developer laptop has root-level access to production systems, repositories, databases, credentials, and APIs. If someone sat down and started using it, they could review pull requests, modify files, commit code, and access anything the developer can access.

Yet this is how many teams are deploying agents today. Autonomous systems are given credentials, tools, and live access to sensitive environments with minimal structure. Work executes in parallel and continuously, at a pace no human could follow. Code is generated faster than developers can realistically review, and they cannot monitor everything operating on their behalf.

Once execution is parallel and continuous, the potential for mistakes or cascading failures scales quickly. Teams will continue to adopt agents because the gains are real. What remains unresolved is how to make this model safe enough to operate without requiring manual approval for every action. Manual approval slows execution back down to human speed and eliminates the value of agents entirely. And consent fatigue is real.

Why AI Agents Break Existing Governance

Traditional security controls were designed around a human operator. A person sits at the keyboard, initiates actions deliberately, and operates within organizational and social constraints. Reviews worked because there was time between intent and execution. Perimeter security protected the network boundary, while automated systems operated within narrow execution limits.

But traditional security assumes something deeper: that a human is operating the machine.  Firewalls trust the laptop because an employee is using it. VPNs trust the connection because an engineer authenticated. Secrets managers grant access because a person requested it. The model depends on someone who can be held accountable and who operates at human speed.

Agents break this assumption. They act directly, reading repositories, calling APIs, modifying files, using credentials. They have root-level privileges and execute actions at machine speed.  

Legacy controls were never intended for this. The default response has been more visibility and approvals, adding alerts, prompts, and confirmations for every action. This does not scale and generates “consent fatigue”, annoying developers and undermining the very security it seeks to enforce. When agents execute hundreds of actions in parallel, humans cannot review them meaningfully. Warnings become noise.

AI Governance and the Execution Layer: The Three Cs Framework

Each major shift in computing has moved security closer to execution. Agents follow the same trajectory. If agents execute, security must operate at the agentic execution layer.

That shift maps governance to three structural requirements: the 3Cs.

Contain: Bound the Blast Radius

Every execution model relies on isolation. Processes required memory protection. Virtual machines required hypervisors. Containers required namespaces. Agents require an equivalent boundary. Containment limits failure so mistakes made by an agent don’t have permanent consequences for your data, workflows, and business. Unlocking full agent autonomy requires the confidence that experimentation won’t be reckless. . Without it, autonomous execution fails.

Curate: Define the Agent’s Environment

What an agent can do is determined by what exists in its environment. The tools it can invoke, the code it can see, the credentials it can use, the context it operates within. All of this shapes execution before the agent acts.

Curation isn’t approval. It is construction. You are not reviewing what the agent wants to do. You are defining the world it operates in. Agents do not reason about your entire system. They act within the environment they are given. If that environment is deliberate, execution becomes predictable. If it is not, you have autonomy without structure, which is just risk.

Control: Enforce Boundaries in Real Time

Governance that exists only on paper has no effect on autonomous systems. Rules must apply as actions occur. File access, network calls, tool invocation, and credential use require runtime enforcement. This is where alert-based security breaks down. Logging and warnings explain what happened or ask permission after execution is already underway. 

Control determines what can happen, when, where, and who has the privilege to make it happen. Properly executed control does not remove autonomy. It defines its limits and removes the need for humans to approve every action under pressure. If this sounds like a policy engine, you aren’t wrong. But this must be dynamic and adaptable, able to keep pace with an agentic workforce.

Putting the 3Cs Into Practice

The three Cs reinforce one another. Containment limits the cost of failure. Curation narrows what agents can attempt and makes them more useful to developers by applying semantic knowledge to craft tools and context to suit the specific environment and task. Control at the runtime layer replaces reactive approval with structural enforcement.

In practice, this work falls to platform teams. It means standardized execution environments with isolation by default, curated tool and credential surfaces aligned to specific use cases, and policy enforcement that operates before actions complete rather than notifying humans afterward. Teams that build with these principles can use agents effectively without burning out developers or drowning them in alerts. Teams that do not will discover that human attention is not a scalable control plane.
Quelle: https://blog.docker.com/feed/

Docker Sandboxes: Run Claude Code and Other Coding Agents Unsupervised (but Safely)

We introduced Docker Sandboxes in experimental preview a few months ago. Today, we’re launching the next evolution with microVM isolation, available now for macOS and Windows. 

We started Docker Sandboxes to answer the question:

How do I run Claude Code or Gemini CLI safely?

Sandboxes provide disposable, isolated environments purpose-built for coding agents. Each agent runs in an isolated version of your development environment, so when it installs packages, modifies configurations, deletes files, or runs Docker containers, your host machine remains untouched.

This isolation lets you run agents like Claude Code, Codex CLI, Copilot CLI, Gemini CLI, and Kiro with autonomy. Since they can’t harm your computer, let them run free.

Since our first preview, Docker Sandboxes have evolved. They’re now more secure, easier to use, and more powerful.

Level 4 Coding Agent Autonomy

Claude Code and other coding agents fundamentally change how developers write and maintain code. But a practical question remains: how do you let an agent run unattended (without constant permission prompts), while still protecting your machine and data? 

Most developers quickly run into the same set of problems trying to solve this:

OS-level sandboxing interrupts workflows and isn’t consistent across platforms

Containers seem like the obvious answer, until the agent needs to run Docker itself

Full VMs work, but are slow, manual, and hard to reuse across projects

We started building Docker Sandboxes specifically to fill this gap.

Docker Sandboxes: MicroVM-Based Isolation for Coding Agents

Defense-in-depth, isolation by default

Each agent runs inside a dedicated microVM

Only your project workspace is mounted into the sandbox

Hypervisor-based isolation significantly reduces host risk

A real development environment

Agents can install system packages, run services, and modify files

Workflows run unattended, without constant permission approvals

Safe Docker access for coding agents

Coding agents can build and run Docker containers inside the MicroVM

They have no access to the host Docker daemon

One sandbox, many coding agents

Use the same sandbox experience with Claude Code, Copilot CLI, Codex CLI, Gemini CLI, and Kiro

More to come (and we’re taking requests!)

Fast reset, no cleanup

If an agent goes off the rails, delete the sandbox and spin up a fresh one in seconds

What’s New Since the Preview and What’s Next

The experimental preview validated the core idea: coding agents need an execution environment with clear isolation boundaries, not a stream of permission prompts. The early focus was developer experience, making it easy to spin up an environment that felt natural and productive for real workflows.

As Matt Pocock put it, “Docker Sandboxes have the best DX of any local AI coding sandbox I’ve tried.”

With this release, we’re making Sandboxes more powerful and secure with no compromise on developer experience.

What’s New

MicroVM-based isolation Sandboxes now run on dedicated microVMs, adding a hard security boundary.

Network isolation with allow and deny listsControl over coding agent network access.

Secure Docker execution for agentsDocker Sandboxes are the only sandboxing solution we’re aware of that allows coding agents to build and run Docker containers while remaining isolated from the host system.

What’s Next

We’re continuing to expand Docker Sandboxes based on developer feedback:

Linux support

MCP Gateway support

Ability to expose ports to the host device and access host-exposed services

Support for additional coding agents

Docker Sandboxes were made for developers who want to run coding agents unattended, experiment freely, and recover instantly when something goes wrong. They extend the usability of containers’ isolation principles but with hard boundaries.

If you’ve been holding back on using agents because of permission prompts, system risk, or Docker-in-Docker limitations, Docker Sandboxes are built to remove those constraints.

We’re iterating quickly, and feedback from real-world usage will directly shape what comes next.

Quelle: https://blog.docker.com/feed/



