Summary
This post is for technical decision makers evaluating where to run production PostgreSQL workloads. It compares two valid operating models—self-managed PostgreSQL and a managed database service—through business and operational outcomes: control, engineering capacity, resilience, security, cost predictability, risk tolerance, and access to specialist expertise. The right choice depends on which responsibilities the organization needs to retain and which it is prepared to transfer to a service provider.
Why organizations choose PostgreSQL
PostgreSQL is a powerful, versatile open-source relational database used for workloads ranging from small applications to enterprise systems. It is a natural choice for teams that need a standards-based database with a broad ecosystem and extensive extensibility.
Managed vs. self-hosted PostgreSQL: Understanding the trade-offs
Once an organization chooses PostgreSQL, it must decide where and how to operate it: on its own infrastructure, in a virtual machine, or through a managed cloud service. Each model offers a different balance of control, responsibility, cost, and operational effort. Self-hosting provides direct control over the operating system (OS), PostgreSQL installation, and supporting infrastructure, but it also leaves the organization responsible for operating the complete platform. Managed PostgreSQL services, like Azure Database for PostgreSQL and Azure HorizonDB, can reduce selected infrastructure and platform responsibilities and help teams devote more engineering capacity to applications, data, and performance.
Discover migration services in Azure Database for PostgreSQL
Operational challenges emerge at scale
Self-hosting creates an ongoing ‘operational tax’: the time, expertise, and resources required to provision, secure, monitor, maintain, and recover the database platform. These activities are essential, but they do not usually differentiate the application or service the organization is building.
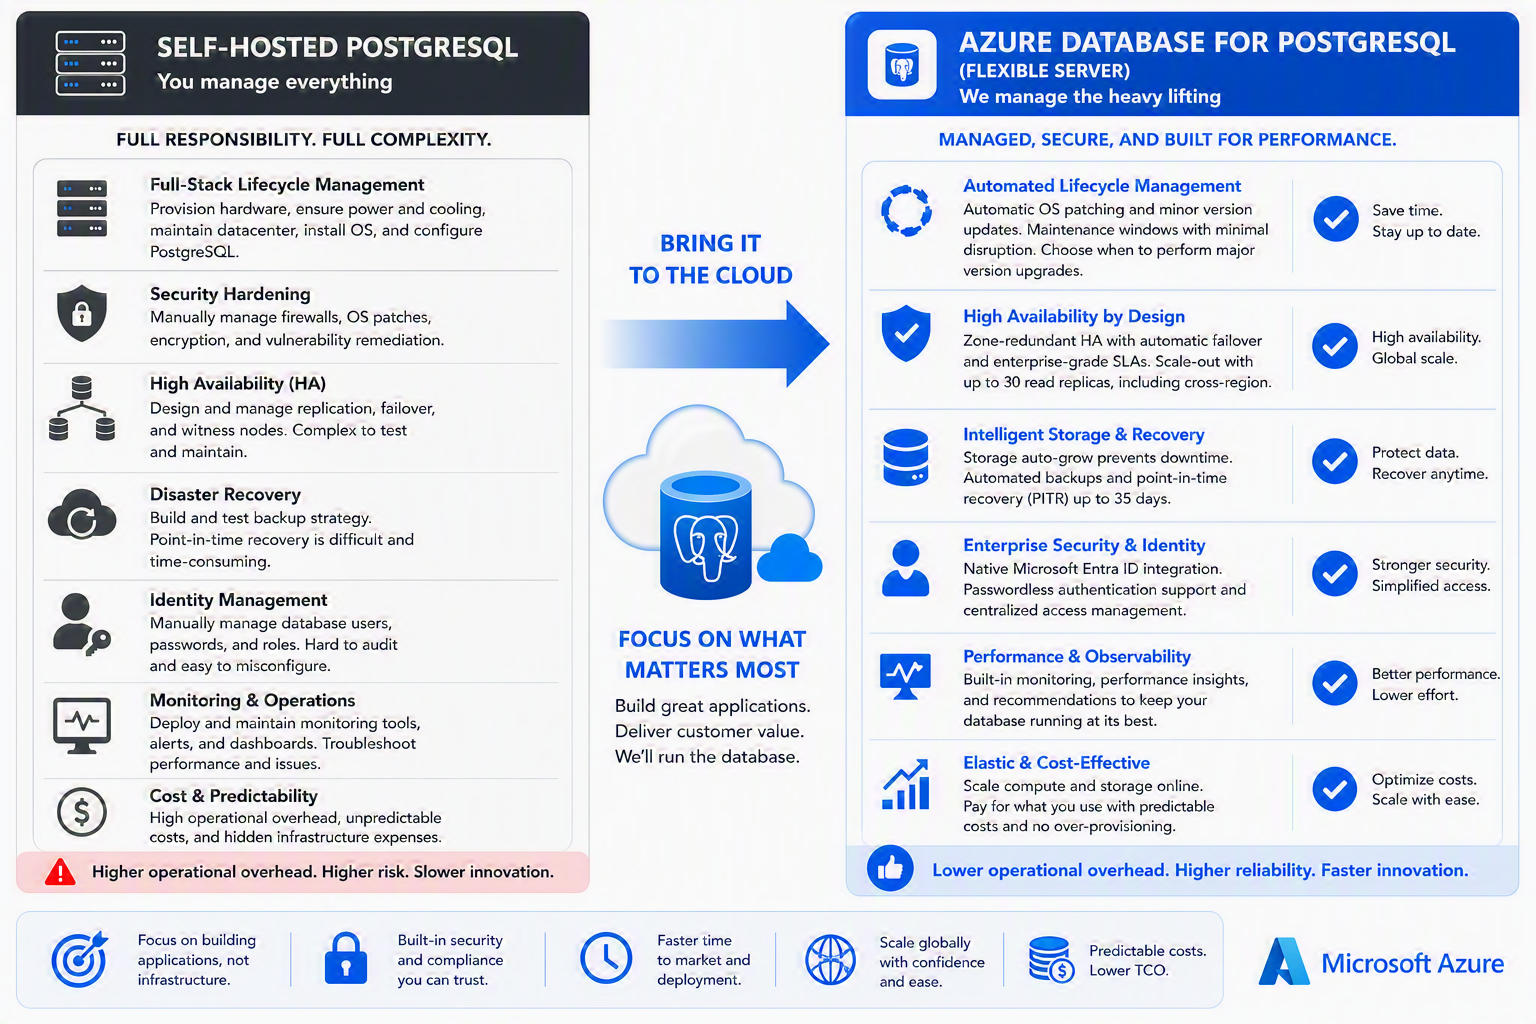
In a self-hosted scenario (e.g., running Postgres on a virtual machine (VM) or an on-premises server), the company’s engineering team is responsible for the entire stack:
Full-stack lifecycle management: Provisioning hardware, ensuring adequate power and cooling, maintaining datacenter infrastructure, installing the OS, and correctly configuring PostgreSQL.
Security hardening: Manually managing firewalls, OS-level security patches, and encryption at rest and in transit.
High Availability (HA): Setting up complex replication and failover mechanisms (like Patroni or Pacemaker), which are notoriously difficult to test and maintain.
Disaster recovery: Designing, automating, monitoring, and testing backups and recovery procedures, including point-in-time recovery. Achieving dependable recovery objectives requires sustained engineering effort and operational discipline.
Identity management: Manually managing database users and passwords, creating silos of credentials that are difficult to audit.
Operational tax consumes time that could be spent improving applications, delivering features, refining data models, or tuning the database’s performance.
When a managed PostgreSQL service may make sense
Managed database services change the operating model by transferring defined infrastructure and platform responsibilities to the cloud provider. This reduces the undifferentiated work required to keep the database platform available, secure, patched, and recoverable.
A managed PostgreSQL service is designed to reduce the operational tax associated with infrastructure and platform administration. The provider typically manages the underlying infrastructure, operating-system maintenance, service patching, and physical datacenter security. Customers remain responsible for their data, database configuration, access policies, application design, and workload performance.
Try Azure Database for PostgreSQL
When self-managed PostgreSQL may be the right fit
Self-management can be the preferred operating model when an organization requires operating-system access, specialized infrastructure, unsupported extensions, customized deployment patterns, or direct control over patching and change schedules. It may also fit organizations with mature PostgreSQL platform engineering, reliable automation, tested recovery practices, and sufficient on-call capacity. In these cases, the additional responsibility is an intentional trade-off for control and flexibility rather than avoidable burden.
Managed services and the shared responsibility model
A useful way to evaluate managed PostgreSQL services is through the lens of the cloud shared responsibility model. As organizations move from self-hosted environments to infrastructure-as-a-service (IaaS) and platform-as-a-service (PaaS) offerings, an increasing portion of the infrastructure and platform stack is operated by the cloud provider. In an IaaS deployment, organizations still manage virtual machines, operating systems, database software, and many operational processes. In a PaaS deployment, responsibility for operating systems and much of the underlying platform is transferred to the provider, reducing the operational effort required to keep the service secure, available, and up to date.
This shift does not eliminate responsibility. Organizations continue to own their data, identities, configurations, access management, compliance requirements, and application behavior regardless of the deployment model. However, by reducing responsibility for operating-system management, physical infrastructure, platform maintenance, and portions of the security stack, managed PostgreSQL services can significantly reduce the operational tax associated with running database platforms at scale.
For example, Azure Database for PostgreSQL is a PostgreSQL PaaS offering that transfers responsibility for infrastructure management, operating-system maintenance, patching orchestration, and platform operations to Microsoft while allowing organizations to retain control over their data, database configuration, access policies, and workload design. This balance enables teams to focus more effort on application delivery, data architecture, and performance optimization rather than routine platform administration. This follows the same shared-responsibility principles that apply across cloud PaaS services.
How managed PostgreSQL services can help
Managed PostgreSQL services replace selected manual infrastructure and platform tasks with managed capabilities and configurable automation. The comparisons below show how responsibilities associated with self-hosting can be simplified or transferred to the service, reducing the Operational Tax on engineering teams.
1. Automated lifecycle management
Self-hosted: Teams must monitor for security alerts, manually download patches, and plan downtime for both the OS and the database.
Managed service: The provider typically manages operating-system maintenance and service updates, including minor PostgreSQL version updates. Customers can often configure preferred maintenance windows for planned maintenance, while major-version upgrades may remain customer-initiated so compatibility can be validated and the schedule controlled.
2. High availability and resilience by design
Self-hosted: Manual HA requires managing multiple VMs, replication lag, and witness nodes. Failover is rarely 100% reliable without constant testing.
Managed service: High availability is commonly available as a service configuration, with the provider maintaining standby capacity and orchestrating failover under the service commitment. Read replicas are a separate capability for scaling read-intensive workloads and should be evaluated independently from the high-availability design.
3. Intelligent storage and recovery
Self-hosted: Exhausted disk capacity can cause a high-severity incident. Teams must provision and monitor storage, maintain backup automation, validate backup targets, and plan capacity increases or disk replacement.
Managed service: Storage growth, automated backups, and point-in-time restore are commonly built into the platform. Retention periods, storage limits, redundancy options, and scaling behaviour vary by provider, region, service tier, and configuration.
4. Enterprise security and identity
Identity and access management comparison
FeatureSelf-hostedManaged serviceAuthenticationManual password rotation and managing separate, siloed credential stores.Native Microsoft Entra ID integration for centralized identity management.Security postureHigher risk of credential leaks due to manual handling and static passwords.Passwordless authentication support, significantly reducing the attack surface.AdministrationDBAs must manually sync organizational users with database roles.Use Microsoft Entra identities and groups to centralize access management and align database access with organizational identity processes. Database permissions still require administration.
Evaluation checklist
Use these questions to evaluate the two operating models:
Do we have the infrastructure and PostgreSQL expertise to operate the platform reliably?
Which responsibilities must remain under direct organizational control?
What availability, recovery, security, and compliance outcomes are required?
How much operational variation and incident risk can the organization absorb?
Can the platform scale to support new workloads?
Which work should database specialists own, and which responsibilities can be transferred to a managed service?
How important are predictable operating costs, standardized controls, and faster deployment?
The choice: Strategic allocation of resources
Choosing between self-managed PostgreSQL and a managed service is a strategic allocation of control, engineering capacity, and operational risk. Self-management can be appropriate when direct infrastructure access, specialized capabilities, or deep customization outweigh the cost of owning the complete platform. A managed service can be appropriate when standardized operations, resilience, security integration, and faster delivery outweigh the need for low-level control.
Technical decision makers should select the model that aligns with business priorities, risk tolerance, regulatory obligations, and the organization’s ability to operate PostgreSQL reliably at the required scale. For teams that choose a managed model on Azure, Azure Database for PostgreSQL provides a fully managed PostgreSQL service with configurable high availability, maintenance, backup, scaling, and security capabilities. Azure HorizonDB provides a cloud-native PostgreSQL option for mission-critical workloads that benefit from independently scalable compute and storage, rapid read scale-out, and built-in zone resilience.
Ready to evaluate the next step?
First validate required extensions, operating-system access, availability and recovery objectives, security controls, regional availability, performance needs, and internal support capacity. If a managed service on Azure fits those requirements, the following resources can help you evaluate Azure Database for PostgreSQL and plan a migration.
Recommended starting point: Migration Service in Azure Database for PostgreSQL flexible server – Azure Database for PostgreSQL
Hands-on training: Migrate to Azure Database for PostgreSQL flexible server – Training
Cloud shared responsibility model: Shared responsibility in the cloud
Online migration tutorial: Migrate Online, from an Azure VM or an On-Premises PostgreSQL to Azure Database for PostgreSQL flexible server, Using the Migration Service in Azure – Azure Database for PostgreSQL
Offline migration tutorial: Migrate Offline, from an Azure VM or an On-Premises PostgreSQL to Azure Database for PostgreSQL flexible server, Using the Migration Service in Azure – Azure Database for PostgreSQL
Simplify Your PostgreSQL Migration
Learn how the migration service in Azure Database for PostgreSQL helps move databases to flexible server with minimal complexity and downtime.
Start Your Migration
The post Managed PostgreSQL vs. self-hosted PostgreSQL: Key benefits and trade-offs appeared first on Microsoft Azure Blog.
Quelle: Azure